a5b51a11e5
* Chore CI by adding checks for links and references
* Potential fix for code scanning alert no. 6: Workflow does not contain permissions
* Fix markdown image formatting in metrics documentation
* Update all `docs` links to use absolute URLs and fix broken references in documentation and workflows.
* Fix broken `albumentations` links in dataset processing documentation
* lycheeVersion: v0.22.0
* Refactor CI link check workflow to use lychee config file for cleaner argument management
* add TODOs for future file type support
* Fix header formatting for example plots across metric files

---------

Co-authored-by: Copilot Autofix powered by AI <62310815+github-advanced-security[bot]@users.noreply.github.com>
Co-authored-by: Copilot <175728472+Copilot@users.noreply.github.com>
9.9 KiB
comments
| comments |
|---|
| true |
Detect Small Objects
This guide shows how to detect small objects
with the Inference,
Ultralytics or
Transformers packages using
InferenceSlicer.
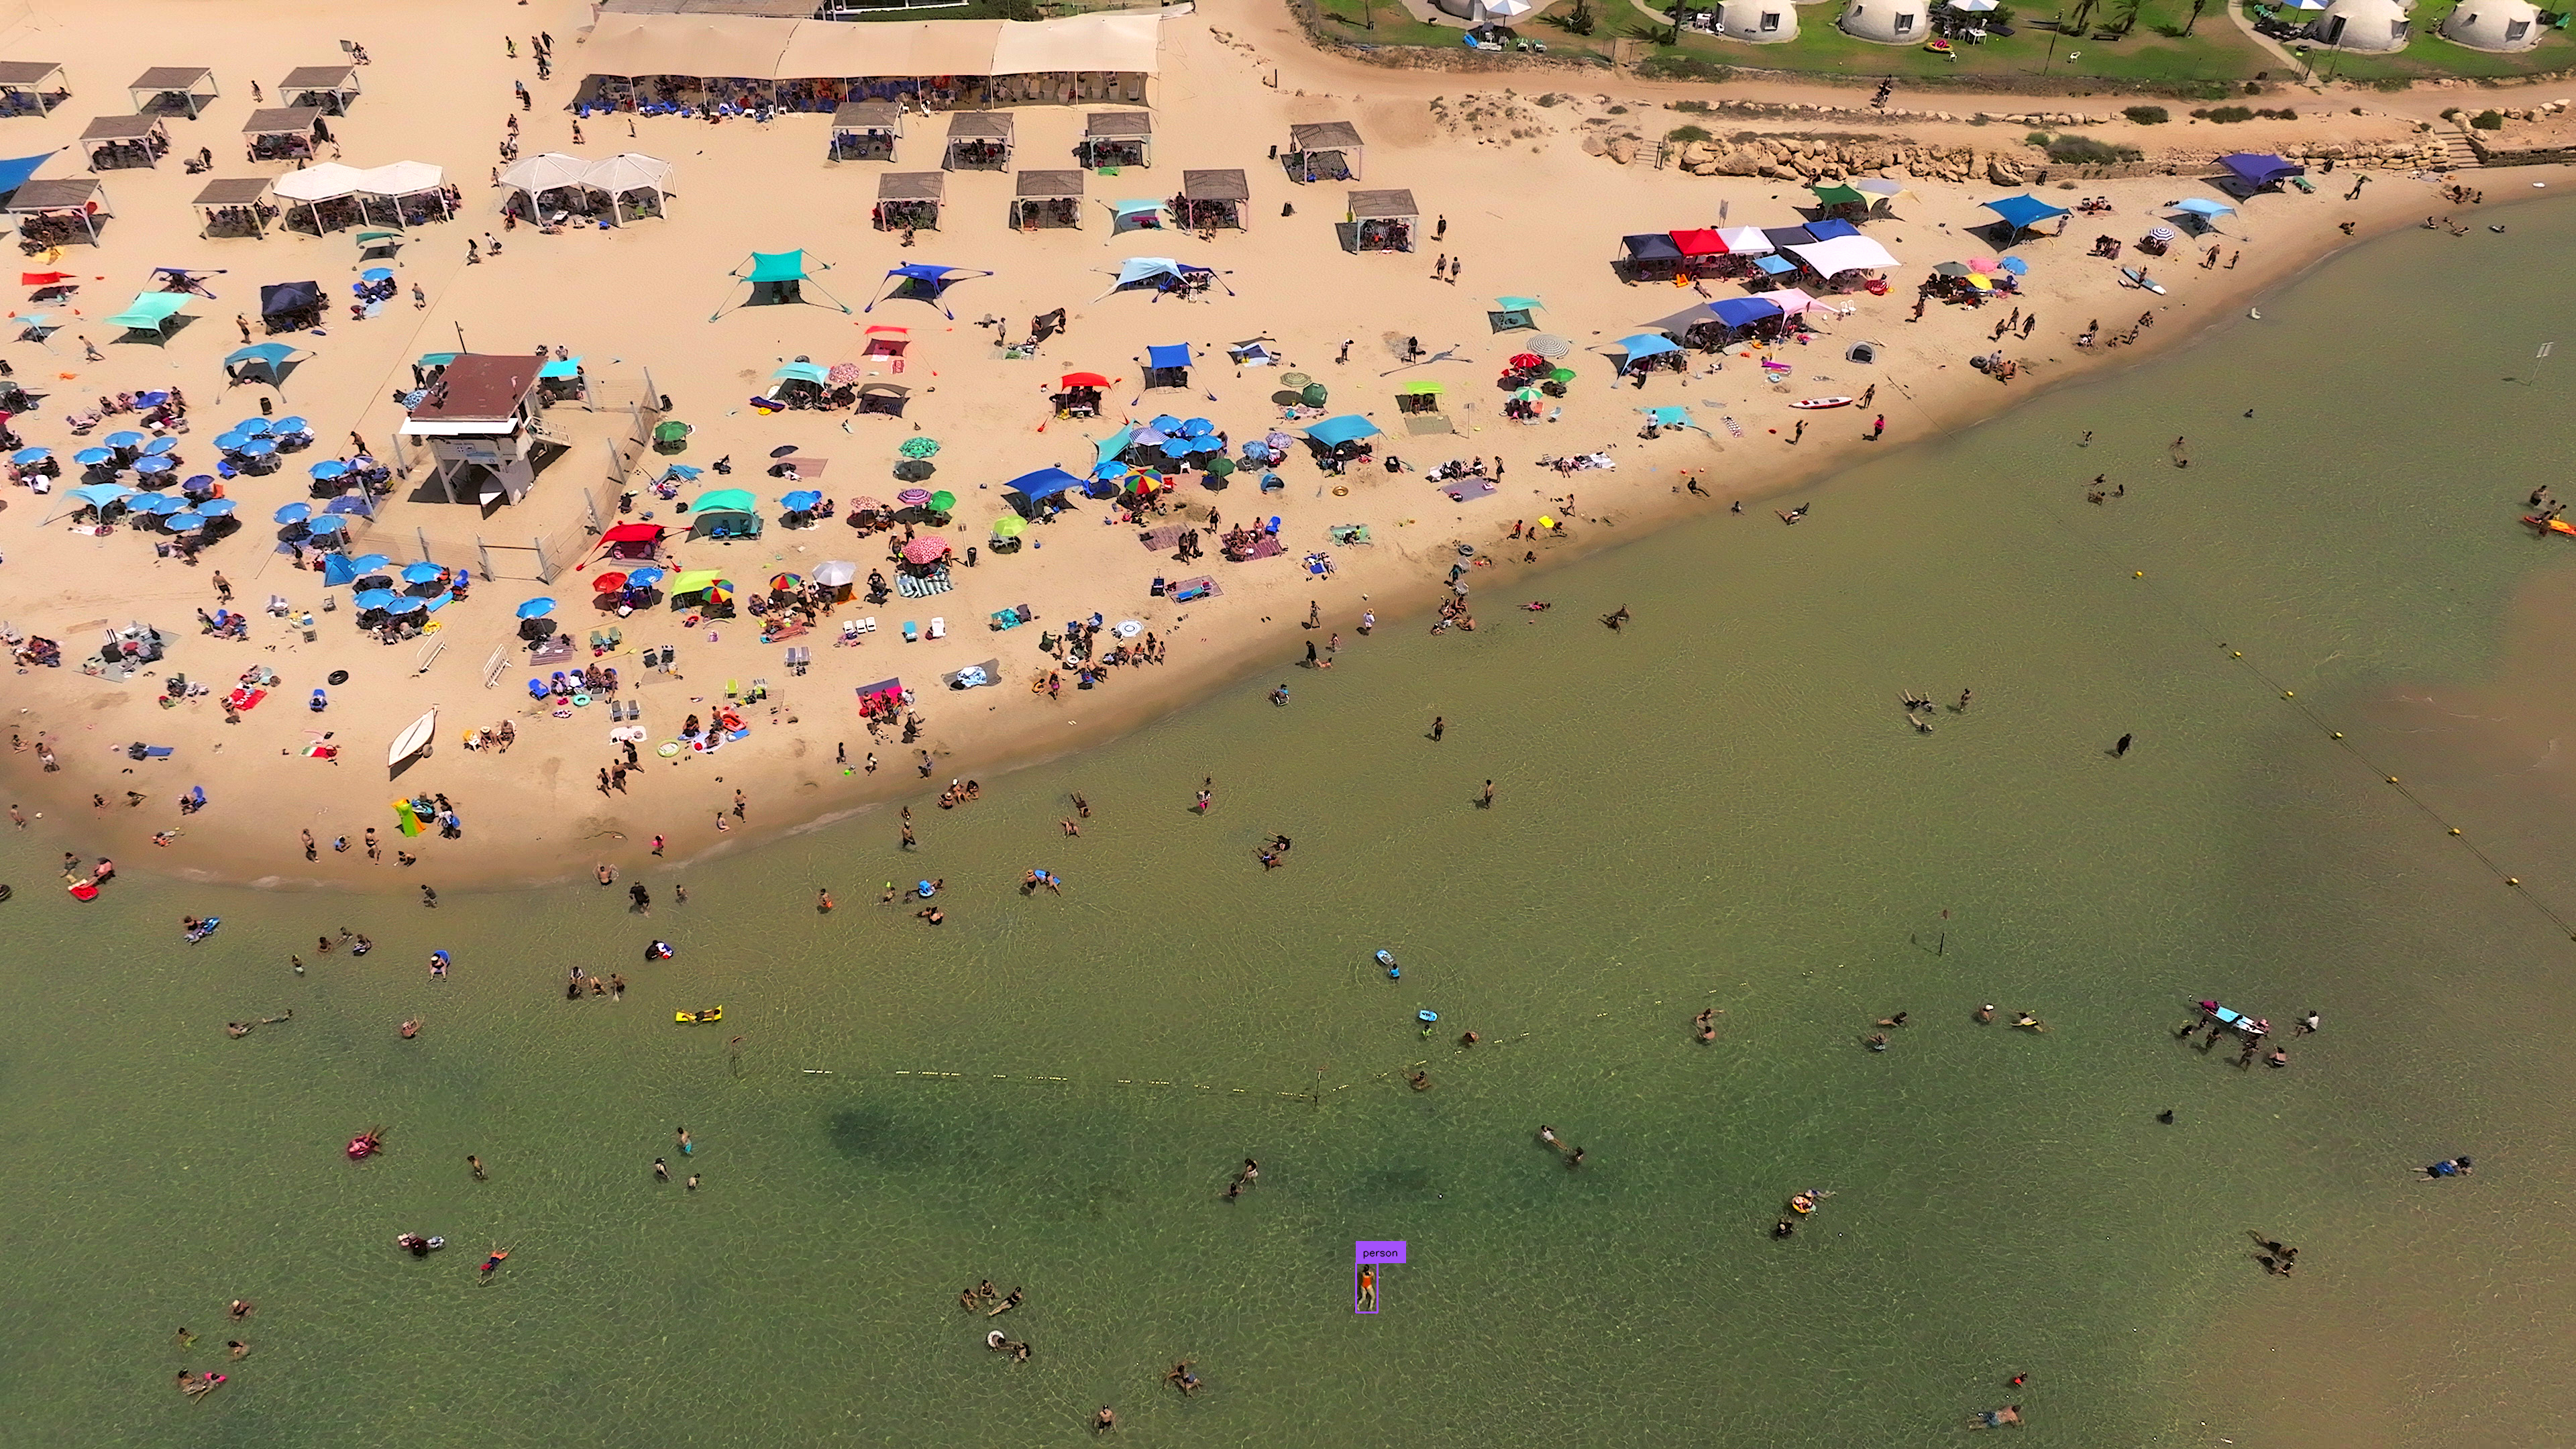
Baseline Detection
Small object detection in high-resolution images presents challenges due to the objects' size relative to the image resolution.
=== "Inference" ```python import cv2 import supervision as sv from inference import get_model
model = get_model(model_id="yolov8x-640")
image = cv2.imread(<SOURCE_IMAGE_PATH>)
results = model.infer(image)[0]
detections = sv.Detections.from_inference(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Ultralytics" ```python import cv2 import supervision as sv from ultralytics import YOLO
model = YOLO("yolov8x.pt")
image = cv2.imread(<SOURCE_IMAGE_PATH>)
results = model(image)[0]
detections = sv.Detections.from_ultralytics(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Transformers" ```python import torch import supervision as sv from PIL import Image from transformers import DetrImageProcessor, DetrForSegmentation
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50")

image = Image.open(<SOURCE_IMAGE_PATH>)
inputs = processor(images=image, return_tensors="pt")

with torch.no_grad():
    outputs = model(**inputs)

width, height = image_slice.size
target_size = torch.tensor([[width, height]])
results = processor.post_process_object_detection(
    outputs=outputs, target_sizes=target_size)[0]
detections = sv.Detections.from_transformers(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

labels = [
    model.config.id2label[class_id]
    for class_id
    in detections.class_id
]

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections, labels=labels)
```
Input Resolution
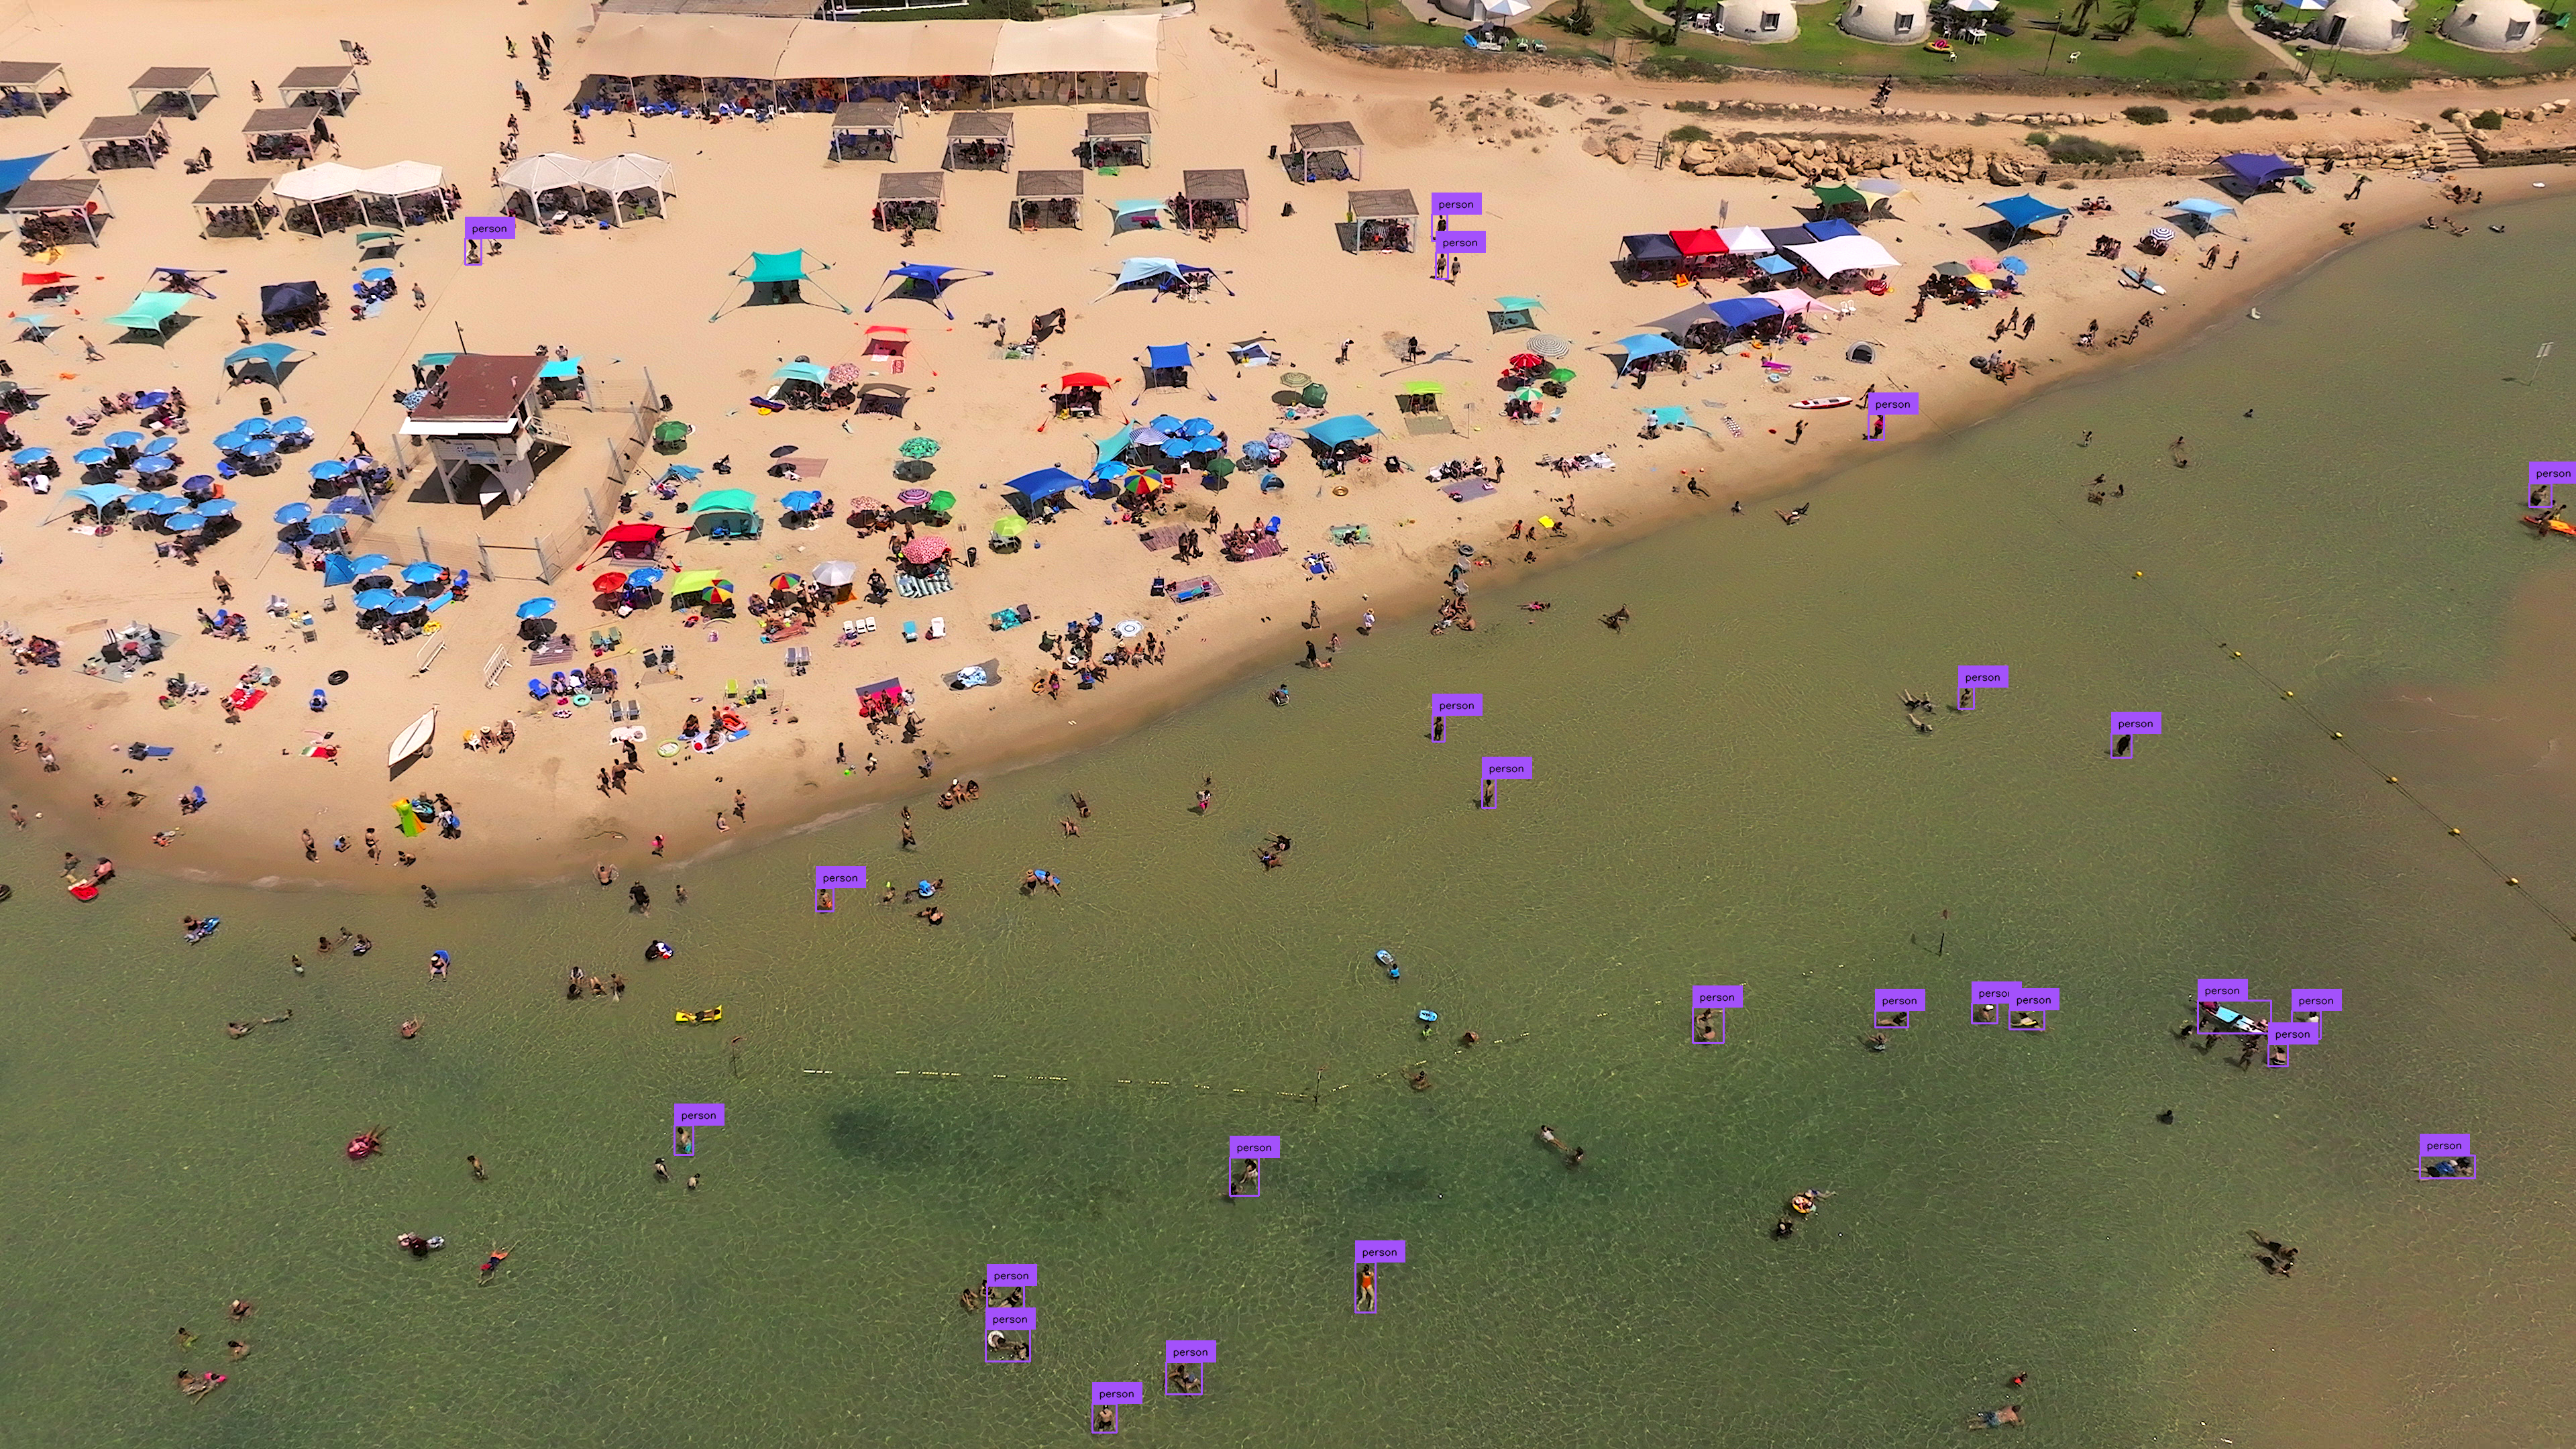
Modifying the input resolution of images before detection can enhance small object identification at the cost of processing speed and increased memory usage. This method is less effective for ultra-high-resolution images (4K and above).
=== "Inference" ```{ .py hl_lines="5" } import cv2 import supervision as sv from inference import get_model
model = get_model(model_id="yolov8x-1280")
image = cv2.imread(<SOURCE_IMAGE_PATH>)
results = model.infer(image)[0]
detections = sv.Detections.from_inference(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Ultralytics" ```{ .py hl_lines="7" } import cv2 import supervision as sv from ultralytics import YOLO
model = YOLO("yolov8x.pt")
image = cv2.imread(<SOURCE_IMAGE_PATH>)
results = model(image, imgsz=1280)[0]
detections = sv.Detections.from_ultralytics(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
Inference Slicer
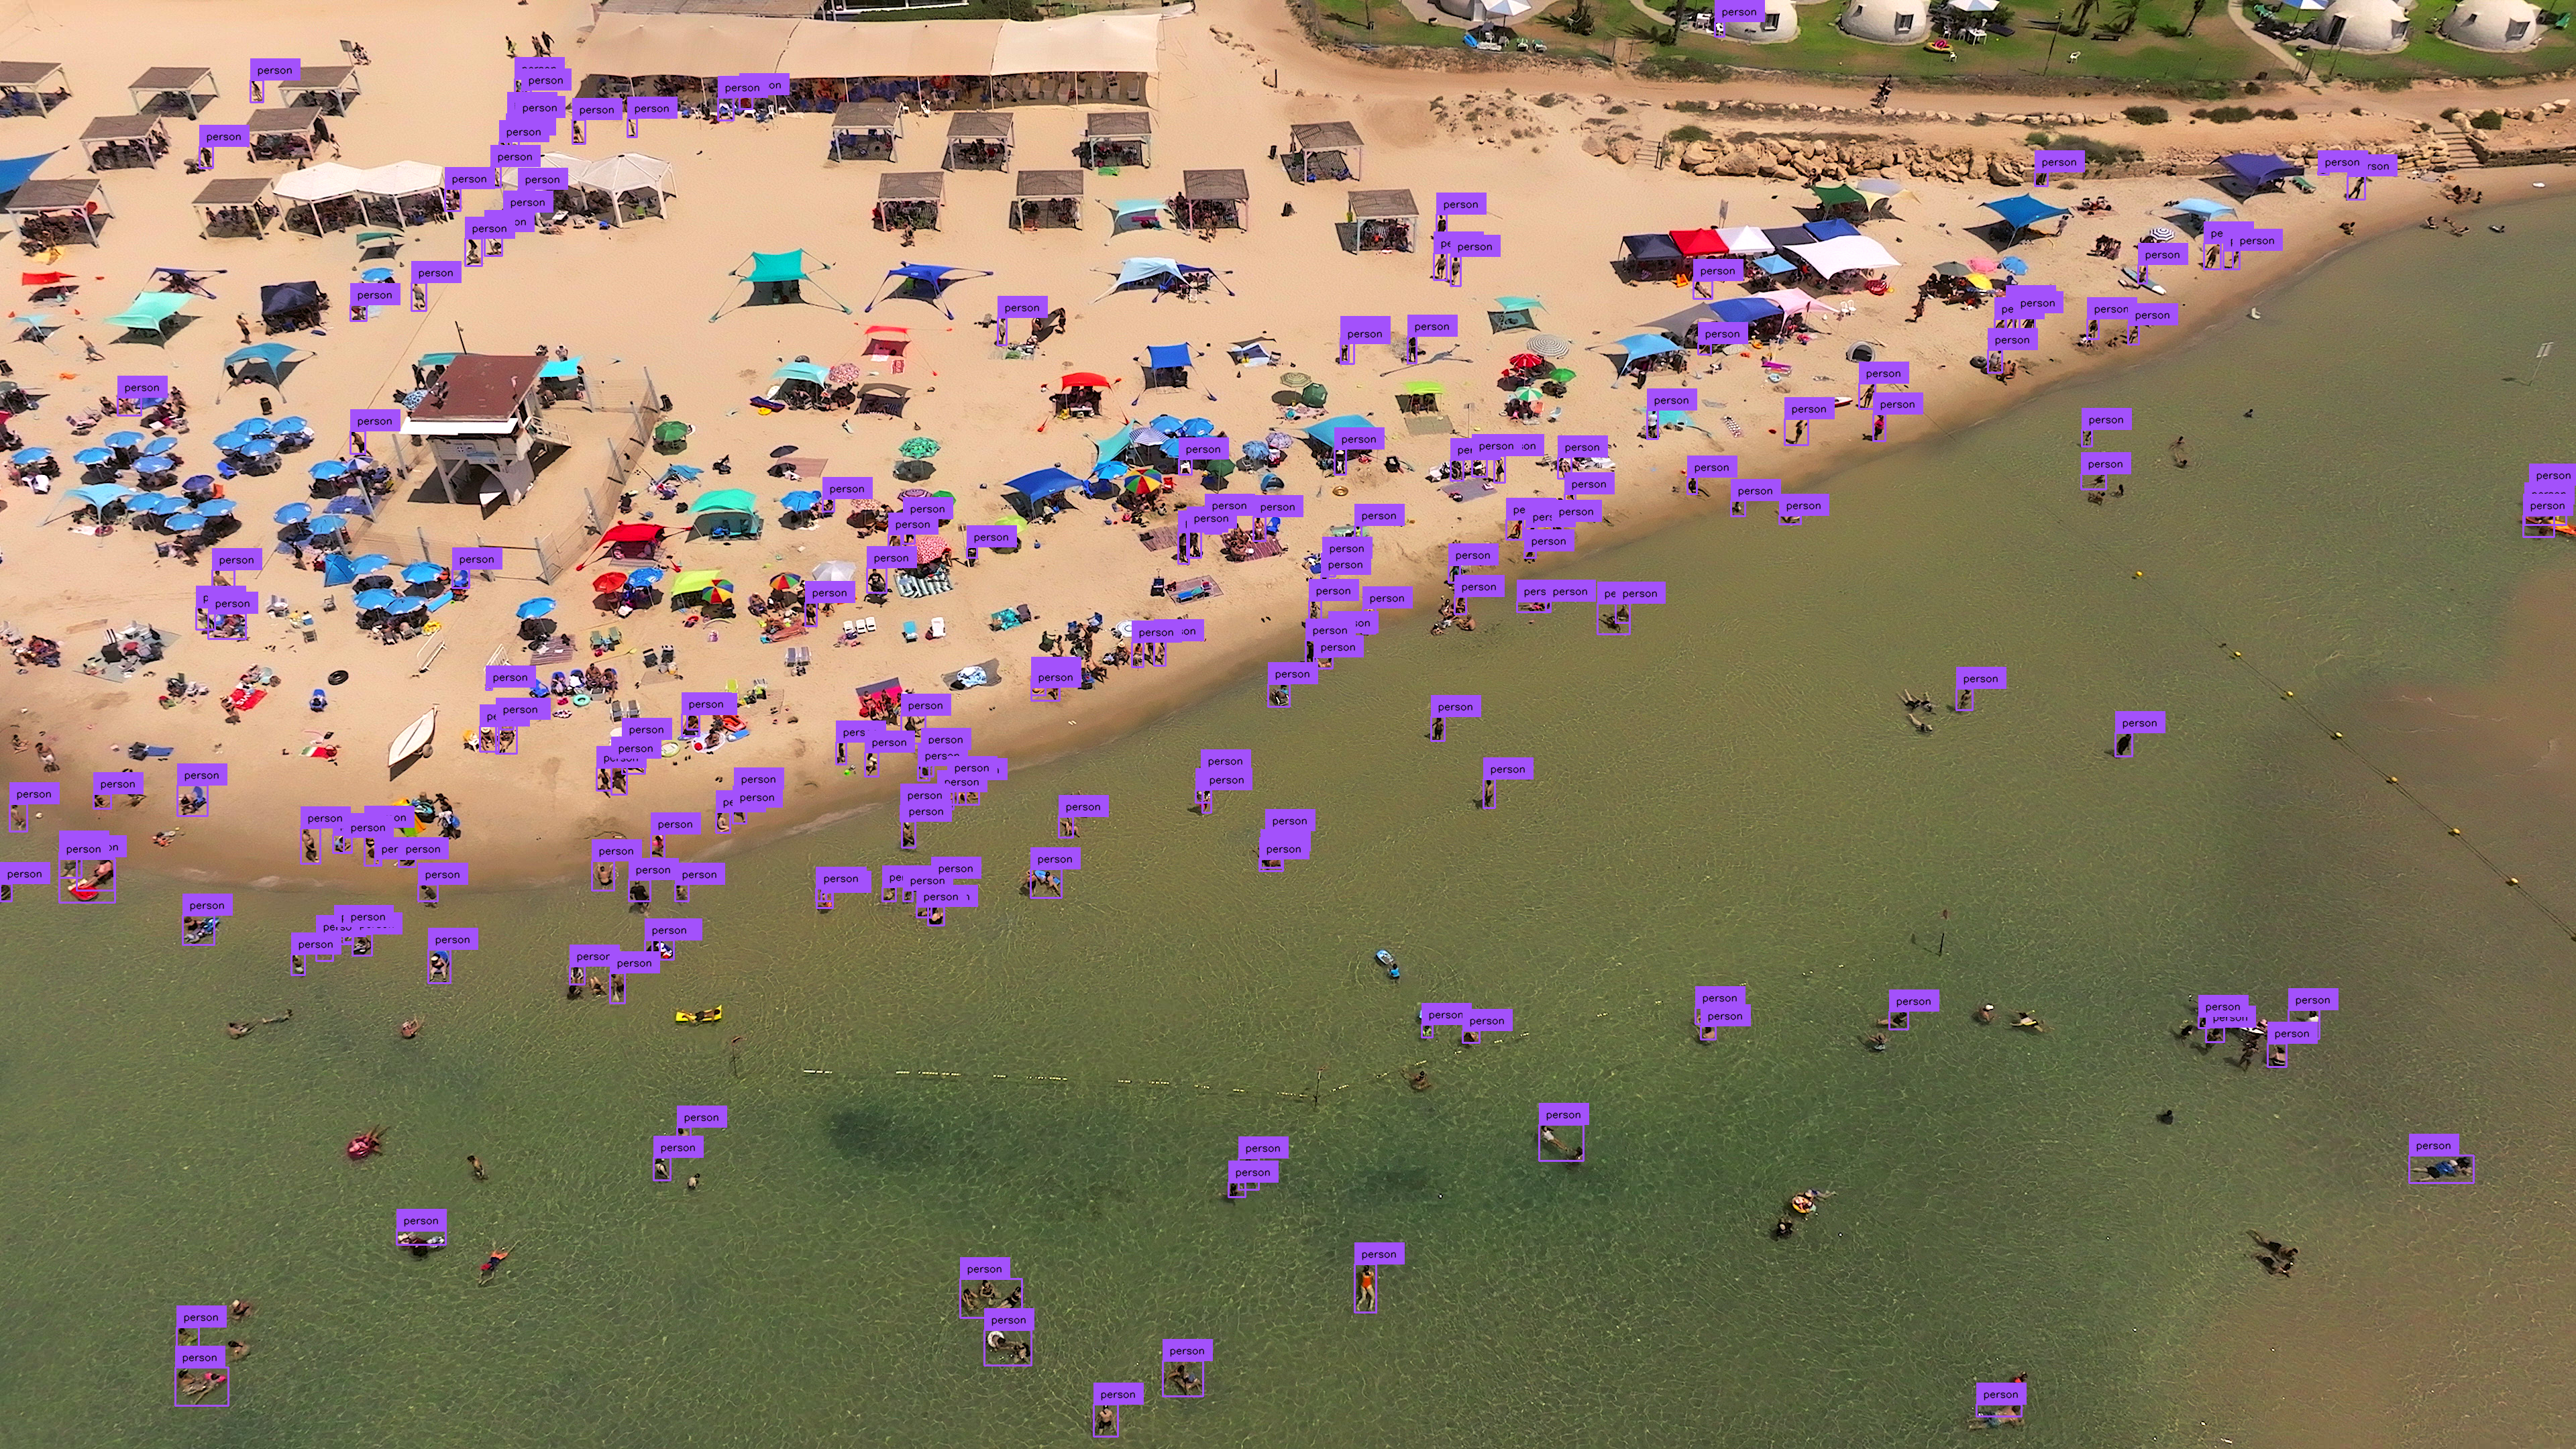
InferenceSlicer
processes high-resolution images by dividing them into smaller segments, detecting
objects within each, and aggregating the results.
=== "Inference" ```{ .py hl_lines="9-14" } import cv2 import numpy as np import supervision as sv from inference import get_model
model = get_model(model_id="yolov8x-640")
image = cv2.imread(<SOURCE_IMAGE_PATH>)

def callback(image_slice: np.ndarray) -> sv.Detections:
    results = model.infer(image_slice)[0]
    return sv.Detections.from_inference(results)

slicer = sv.InferenceSlicer(callback = callback)
detections = slicer(image)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Ultralytics" ```{ .py hl_lines="9-14" } import cv2 import numpy as np import supervision as sv from ultralytics import YOLO
model = YOLO("yolov8x.pt")
image = cv2.imread(<SOURCE_IMAGE_PATH>)

def callback(image_slice: np.ndarray) -> sv.Detections:
    result = model(image_slice)[0]
    return sv.Detections.from_ultralytics(result)

slicer = sv.InferenceSlicer(callback = callback)
detections = slicer(image)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Transformers" ```{ .py hl_lines="13-28" } import cv2 import torch import numpy as np import supervision as sv from PIL import Image from transformers import DetrImageProcessor, DetrForObjectDetection
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")

image = cv2.imread(<SOURCE_IMAGE_PATH>)

def callback(image_slice: np.ndarray) -> sv.Detections:
    image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
    image_slice = Image.fromarray(image_slice)
    inputs = processor(images=image_slice, return_tensors="pt")

    with torch.no_grad():
        outputs = model(**inputs)

    width, height = image_slice.size
    target_size = torch.tensor([[width, height]])
    results = processor.post_process_object_detection(
        outputs=outputs, target_sizes=target_size)[0]
    return sv.Detections.from_transformers(results)

slicer = sv.InferenceSlicer(callback = callback)
detections = slicer(image)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

labels = [
    model.config.id2label[class_id]
    for class_id
    in detections.class_id
]

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections, labels=labels)
```
Small Object Segmentation
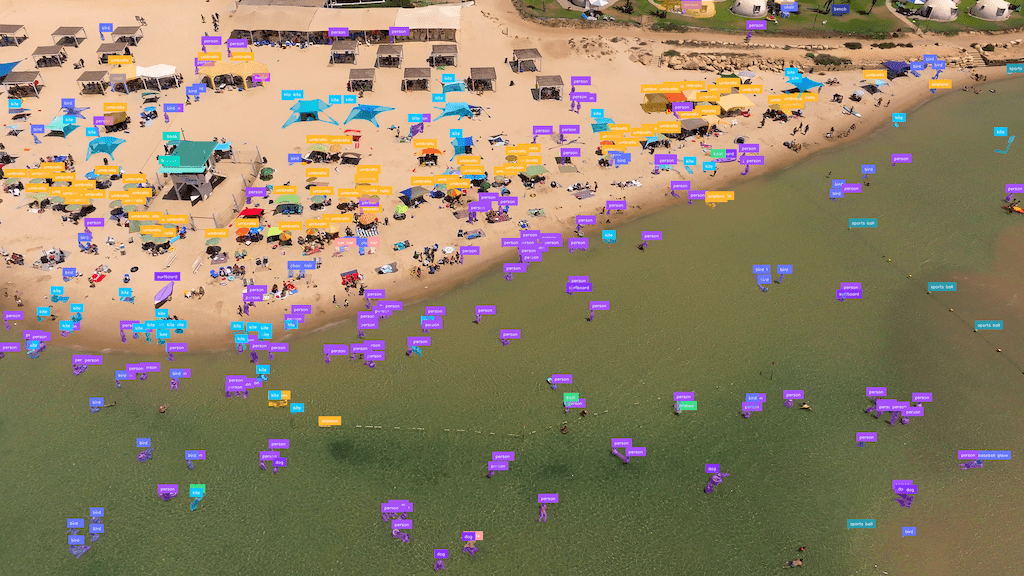
InferenceSlicer can perform segmentation tasks too.
=== "Inference" ```{ .py hl_lines="6 16 19-20" } import cv2 import numpy as np import supervision as sv from inference import get_model
model = get_model(model_id="yolov8x-seg-640")
image = cv2.imread(<SOURCE_IMAGE_PATH>)

def callback(image_slice: np.ndarray) -> sv.Detections:
    results = model.infer(image_slice)[0]
    return sv.Detections.from_inference(results)

slicer = sv.InferenceSlicer(callback = callback)
detections = slicer(image)

mask_annotator = sv.MaskAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = mask_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```
=== "Ultralytics" ```{ .py hl_lines="6 16 19-20" } import cv2 import numpy as np import supervision as sv from ultralytics import YOLO
model = YOLO("yolov8x-seg.pt")
image = cv2.imread(<SOURCE_IMAGE_PATH>)

def callback(image_slice: np.ndarray) -> sv.Detections:
    result = model(image_slice)[0]
    return sv.Detections.from_ultralytics(result)

slicer = sv.InferenceSlicer(callback = callback)
detections = slicer(image)

mask_annotator = sv.MaskAnnotator()
label_annotator = sv.LabelAnnotator()

annotated_image = mask_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections)
```