Merge remote-tracking branch 'upstream/develop' into add_nmm_to_detections
This commit is contained in:
 LinasKo committed
commit
2eb0c7c242
17 files changed
+778
-108
No files matched your search
@@ -45,7 +45,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.4.2
|
||||
rev: v0.4.4
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
@@ -65,8 +65,26 @@ status: new
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.move_masks">move_masks</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_masks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.clip_boxes">clip_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.clip_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.pad_boxes">pad_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
@@ -6,7 +6,7 @@ status: new
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
@@ -68,10 +68,10 @@ size relative to the image resolution.
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
@@ -79,8 +79,8 @@ size relative to the image resolution.
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
@@ -175,7 +175,7 @@ objects within each, and aggregating the results.
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
@@ -239,8 +239,8 @@ objects within each, and aggregating the results.
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
@@ -264,3 +264,63 @@ objects within each, and aggregating the results.
|
||||
```
|
||||
|
||||
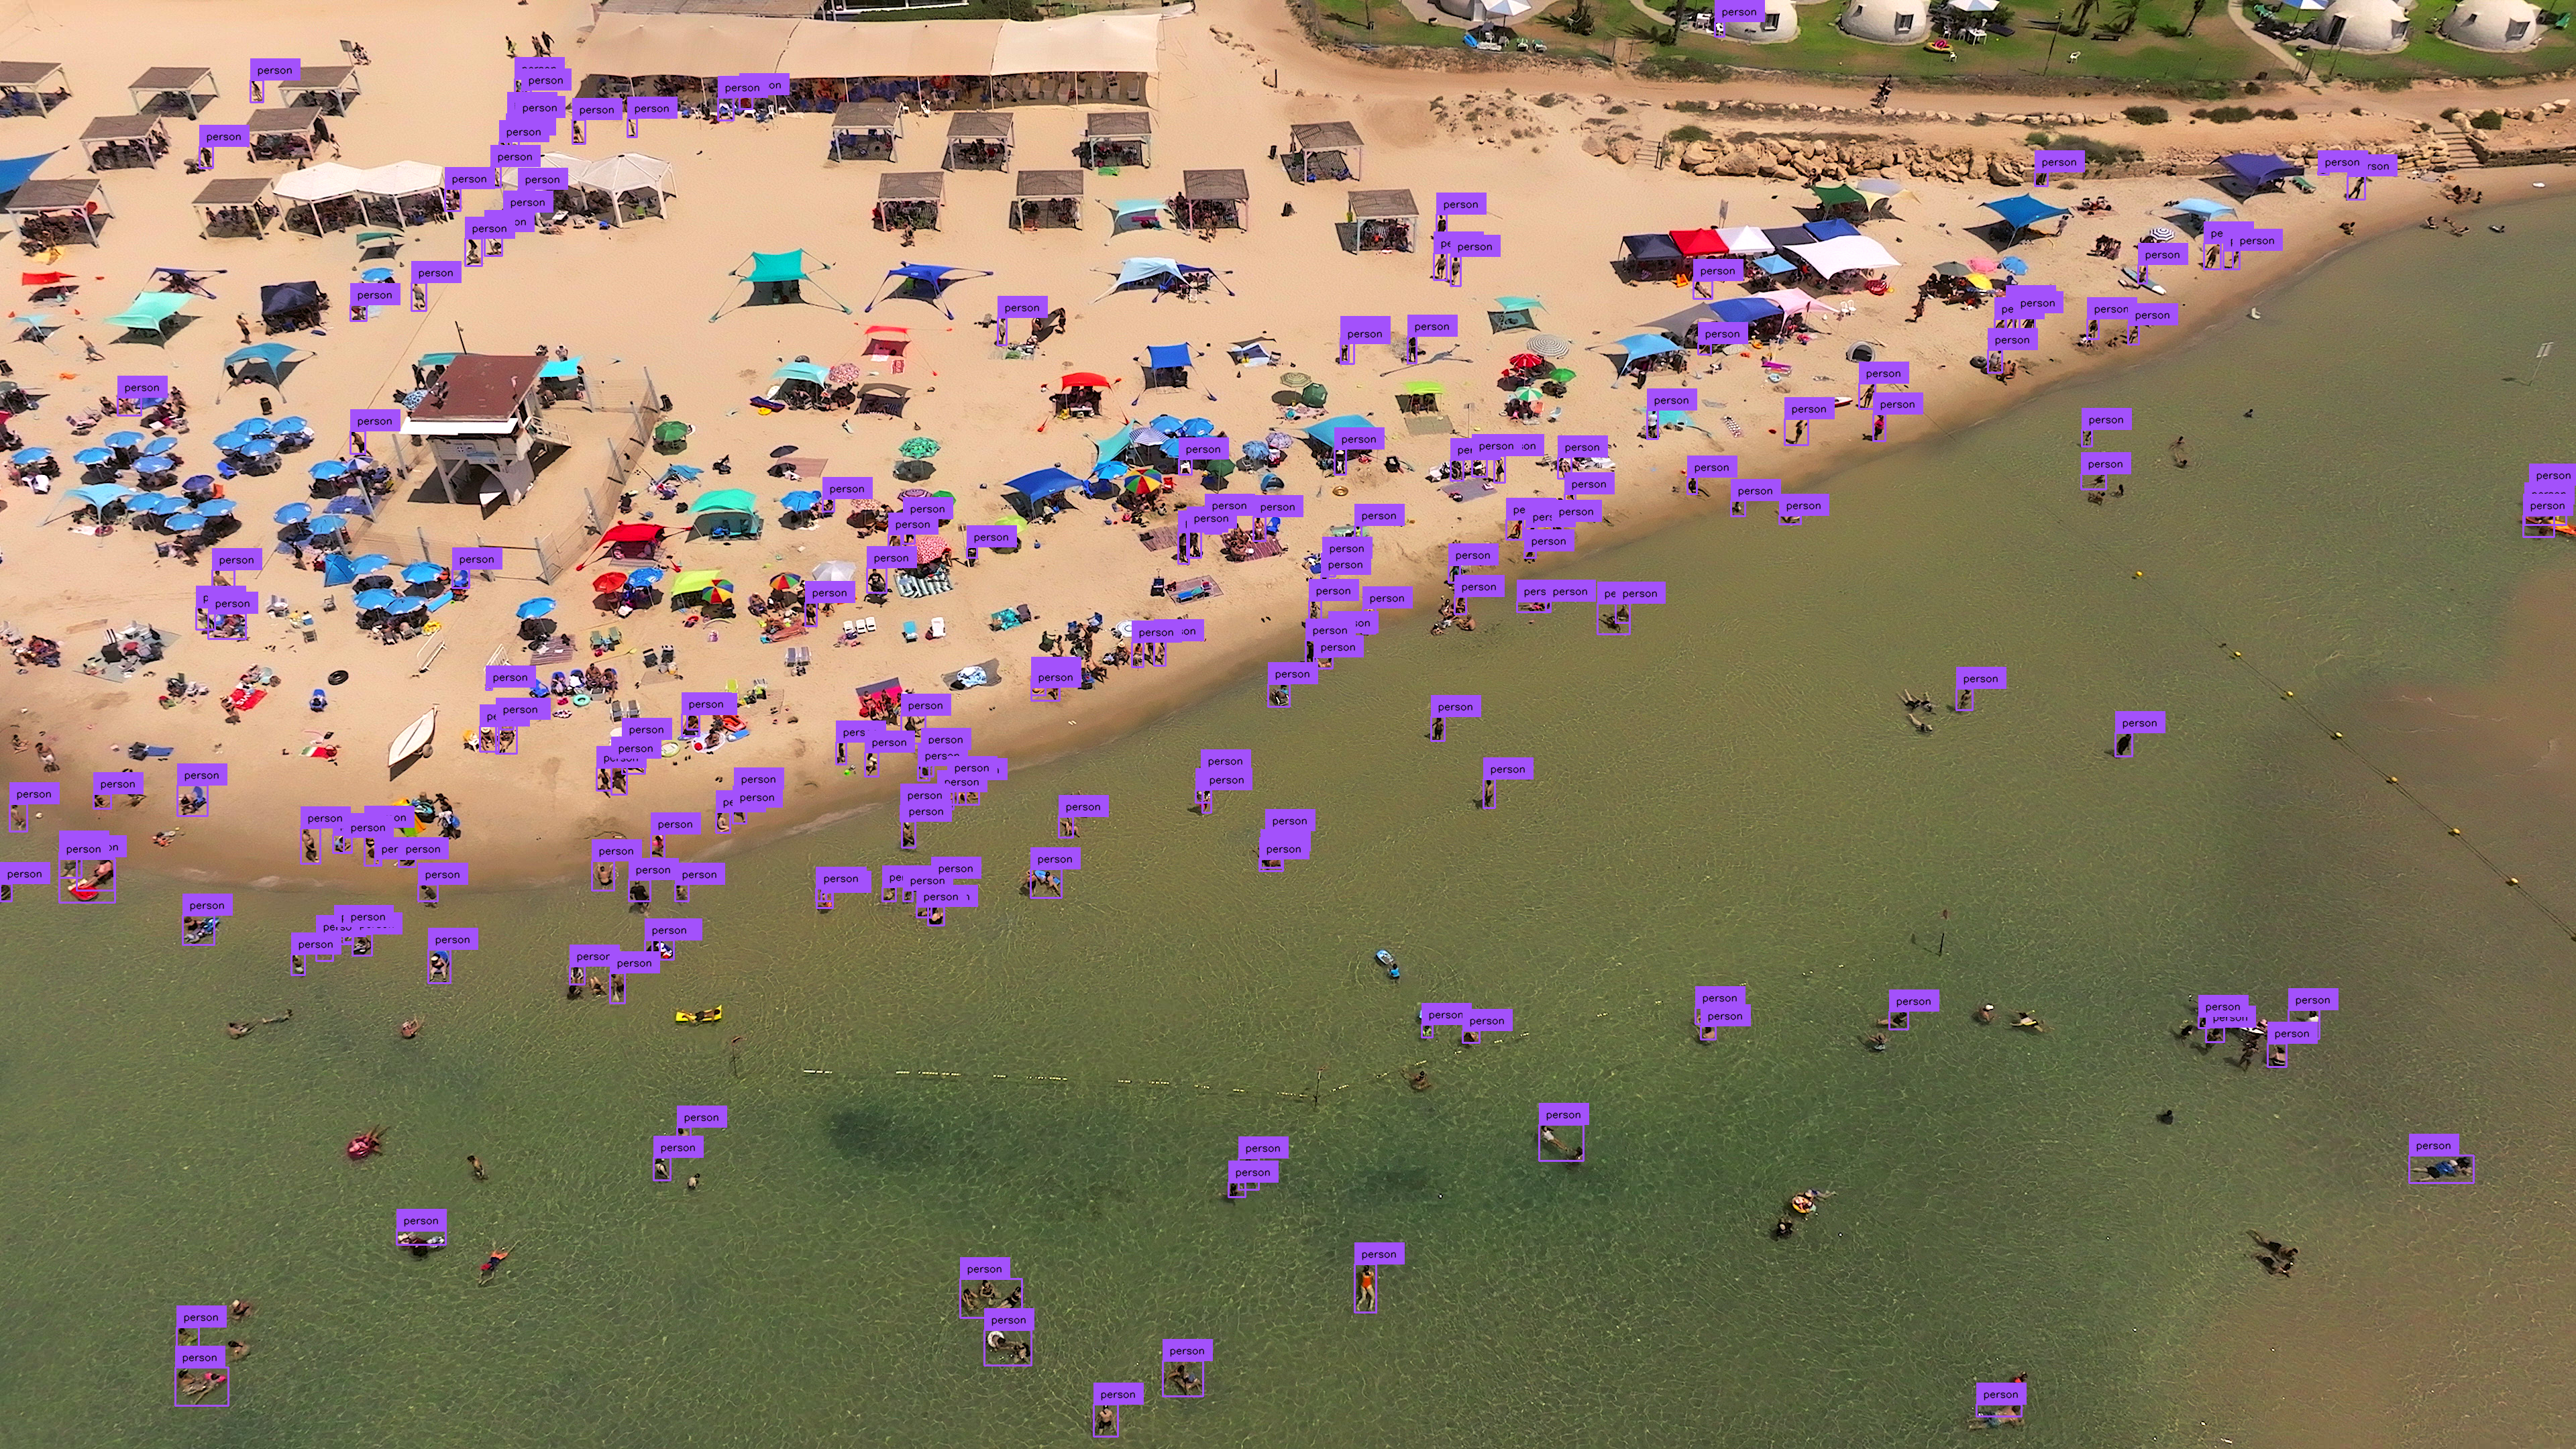
|
||||
|
||||
## Small Object Segmentation
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can perform segmentation tasks too.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
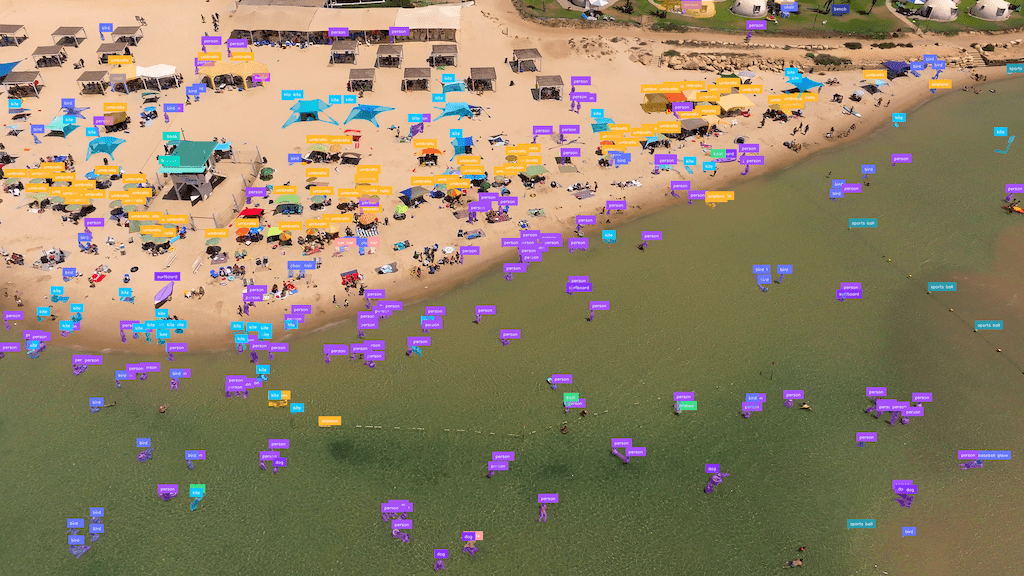
|
||||
@@ -13,7 +13,10 @@ status: new
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
vertex_annotator = sv.VertexAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
radius=10
|
||||
)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
@@ -34,7 +37,10 @@ status: new
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
@@ -47,6 +53,31 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "VertexLabelAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
text_color=sv.Color.BLACK,
|
||||
border_radius=5
|
||||
)
|
||||
annotated_frame = vertex_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
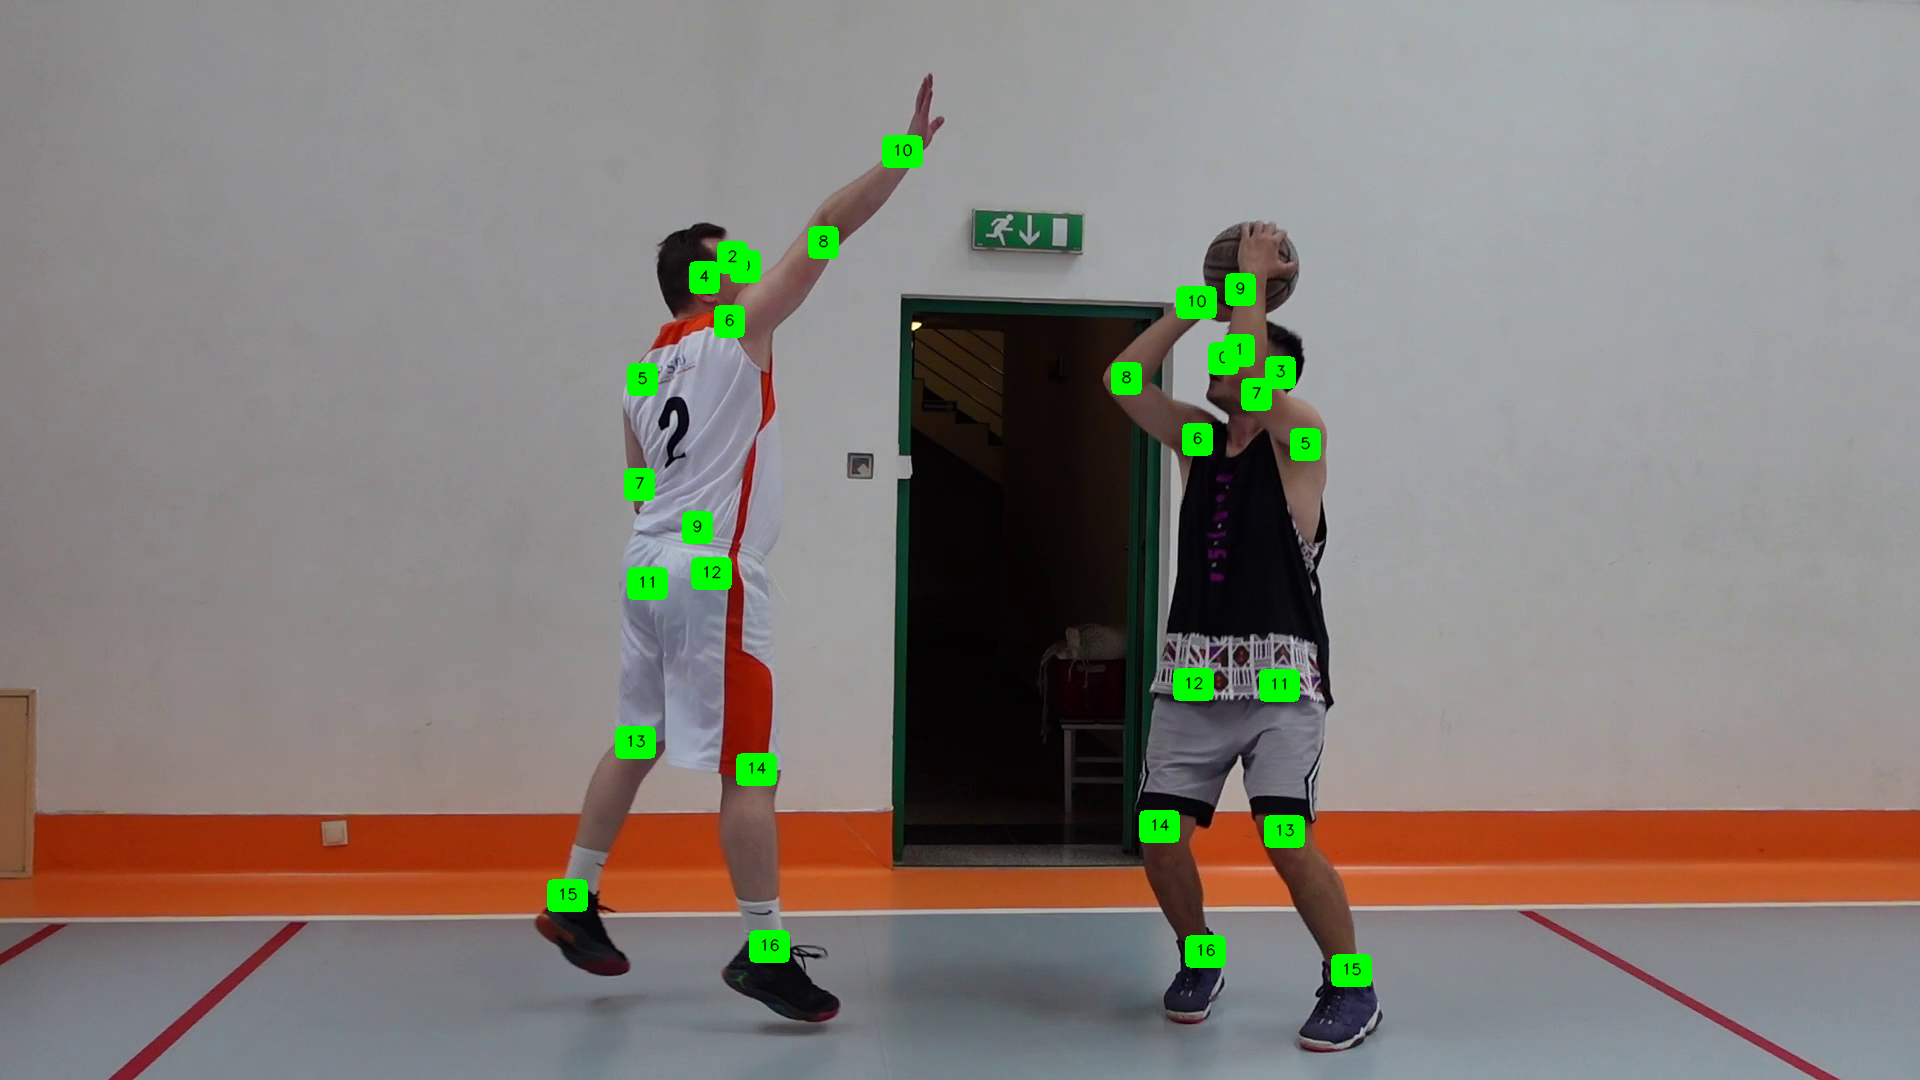{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -58,3 +89,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexLabelAnnotator">VertexLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexLabelAnnotator
|
||||
@@ -103,7 +103,7 @@ python scripts/draw_zones.py \
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/traffic/video.mp4" \
|
||||
--zone_configuration_path "data/traffic/custom_config.json"
|
||||
--zone_configuration_path "data/traffic/config.json"
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac
|
||||
@@ -157,7 +157,7 @@ Script to run object detection on a video stream using the Roboflow Inference mo
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python inference_stream_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
@@ -167,7 +167,7 @@ python inference_file_example.py \
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python inference_stream_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
@@ -192,7 +192,7 @@ Script to run object detection on a video file using the Ultralytics YOLOv8 mode
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python ultralytics_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
@@ -203,7 +203,7 @@ python inference_file_example.py \
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python ultralytics_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
@@ -226,7 +226,7 @@ Script to run object detection on a video stream using the Ultralytics YOLOv8 mo
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python ultralytics_stream_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
@@ -237,7 +237,7 @@ python inference_file_example.py \
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
python ultralytics_stream_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
|
||||
Generated
+24
-24
@@ -1340,13 +1340,13 @@ trio = ["async_generator", "trio"]
|
||||
|
||||
[[package]]
|
||||
name = "jinja2"
|
||||
version = "3.1.3"
|
||||
version = "3.1.4"
|
||||
description = "A very fast and expressive template engine."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "Jinja2-3.1.3-py3-none-any.whl", hash = "sha256:7d6d50dd97d52cbc355597bd845fabfbac3f551e1f99619e39a35ce8c370b5fa"},
|
||||
{file = "Jinja2-3.1.3.tar.gz", hash = "sha256:ac8bd6544d4bb2c9792bf3a159e80bba8fda7f07e81bc3aed565432d5925ba90"},
|
||||
{file = "jinja2-3.1.4-py3-none-any.whl", hash = "sha256:bc5dd2abb727a5319567b7a813e6a2e7318c39f4f487cfe6c89c6f9c7d25197d"},
|
||||
{file = "jinja2-3.1.4.tar.gz", hash = "sha256:4a3aee7acbbe7303aede8e9648d13b8bf88a429282aa6122a993f0ac800cb369"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2198,13 +2198,13 @@ pygments = ">2.12.0"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.21"
|
||||
version = "9.5.22"
|
||||
description = "Documentation that simply works"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_material-9.5.21-py3-none-any.whl", hash = "sha256:210e1f179682cd4be17d5c641b2f4559574b9dea2f589c3f0e7c17c5bd1959bc"},
|
||||
{file = "mkdocs_material-9.5.21.tar.gz", hash = "sha256:049f82770f40559d3c2aa2259c562ea7257dbb4aaa9624323b5ef27b2d95a450"},
|
||||
{file = "mkdocs_material-9.5.22-py3-none-any.whl", hash = "sha256:8c7a377d323567934e6cd46915e64dc209efceaec0dec1cf2202184f5649862c"},
|
||||
{file = "mkdocs_material-9.5.22.tar.gz", hash = "sha256:22a853a456ae8c581c4628159574d6fc7c71b2c7569dc9c3a82cc70432219599"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -3661,28 +3661,28 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.4.3"
|
||||
version = "0.4.4"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.4.3-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:b70800c290f14ae6fcbb41bbe201cf62dfca024d124a1f373e76371a007454ce"},
|
||||
{file = "ruff-0.4.3-py3-none-macosx_11_0_arm64.whl", hash = "sha256:08a0d6a22918ab2552ace96adeaca308833873a4d7d1d587bb1d37bae8728eb3"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:eba1f14df3c758dd7de5b55fbae7e1c8af238597961e5fb628f3de446c3c40c5"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:819fb06d535cc76dfddbfe8d3068ff602ddeb40e3eacbc90e0d1272bb8d97113"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:0bfc9e955e6dc6359eb6f82ea150c4f4e82b660e5b58d9a20a0e42ec3bb6342b"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:510a67d232d2ebe983fddea324dbf9d69b71c4d2dfeb8a862f4a127536dd4cfb"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:dc9ff11cd9a092ee7680a56d21f302bdda14327772cd870d806610a3503d001f"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:29efff25bf9ee685c2c8390563a5b5c006a3fee5230d28ea39f4f75f9d0b6f2f"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:18b00e0bcccf0fc8d7186ed21e311dffd19761cb632241a6e4fe4477cc80ef6e"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:262f5635e2c74d80b7507fbc2fac28fe0d4fef26373bbc62039526f7722bca1b"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:7363691198719c26459e08cc17c6a3dac6f592e9ea3d2fa772f4e561b5fe82a3"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_i686.whl", hash = "sha256:eeb039f8428fcb6725bb63cbae92ad67b0559e68b5d80f840f11914afd8ddf7f"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:927b11c1e4d0727ce1a729eace61cee88a334623ec424c0b1c8fe3e5f9d3c865"},
|
||||
{file = "ruff-0.4.3-py3-none-win32.whl", hash = "sha256:25cacda2155778beb0d064e0ec5a3944dcca9c12715f7c4634fd9d93ac33fd30"},
|
||||
{file = "ruff-0.4.3-py3-none-win_amd64.whl", hash = "sha256:7a1c3a450bc6539ef00da6c819fb1b76b6b065dec585f91456e7c0d6a0bbc725"},
|
||||
{file = "ruff-0.4.3-py3-none-win_arm64.whl", hash = "sha256:71ca5f8ccf1121b95a59649482470c5601c60a416bf189d553955b0338e34614"},
|
||||
{file = "ruff-0.4.3.tar.gz", hash = "sha256:ff0a3ef2e3c4b6d133fbedcf9586abfbe38d076041f2dc18ffb2c7e0485d5a07"},
|
||||
{file = "ruff-0.4.4-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:29d44ef5bb6a08e235c8249294fa8d431adc1426bfda99ed493119e6f9ea1bf6"},
|
||||
{file = "ruff-0.4.4-py3-none-macosx_11_0_arm64.whl", hash = "sha256:c4efe62b5bbb24178c950732ddd40712b878a9b96b1d02b0ff0b08a090cbd891"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4c8e2f1e8fc12d07ab521a9005d68a969e167b589cbcaee354cb61e9d9de9c15"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:60ed88b636a463214905c002fa3eaab19795679ed55529f91e488db3fe8976ab"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:b90fc5e170fc71c712cc4d9ab0e24ea505c6a9e4ebf346787a67e691dfb72e85"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:8e7e6ebc10ef16dcdc77fd5557ee60647512b400e4a60bdc4849468f076f6eef"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:b9ddb2c494fb79fc208cd15ffe08f32b7682519e067413dbaf5f4b01a6087bcd"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:c51c928a14f9f0a871082603e25a1588059b7e08a920f2f9fa7157b5bf08cfe9"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:b5eb0a4bfd6400b7d07c09a7725e1a98c3b838be557fee229ac0f84d9aa49c36"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:b1867ee9bf3acc21778dcb293db504692eda5f7a11a6e6cc40890182a9f9e595"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:1aecced1269481ef2894cc495647392a34b0bf3e28ff53ed95a385b13aa45768"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_i686.whl", hash = "sha256:9da73eb616b3241a307b837f32756dc20a0b07e2bcb694fec73699c93d04a69e"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:958b4ea5589706a81065e2a776237de2ecc3e763342e5cc8e02a4a4d8a5e6f95"},
|
||||
{file = "ruff-0.4.4-py3-none-win32.whl", hash = "sha256:cb53473849f011bca6e754f2cdf47cafc9c4f4ff4570003a0dad0b9b6890e876"},
|
||||
{file = "ruff-0.4.4-py3-none-win_amd64.whl", hash = "sha256:424e5b72597482543b684c11def82669cc6b395aa8cc69acc1858b5ef3e5daae"},
|
||||
{file = "ruff-0.4.4-py3-none-win_arm64.whl", hash = "sha256:39df0537b47d3b597293edbb95baf54ff5b49589eb7ff41926d8243caa995ea6"},
|
||||
{file = "ruff-0.4.4.tar.gz", hash = "sha256:f87ea42d5cdebdc6a69761a9d0bc83ae9b3b30d0ad78952005ba6568d6c022af"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
||||
+1
-1
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.21.0rc3"
|
||||
version = "0.21.0rc5"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
|
||||
@@ -46,12 +46,15 @@ from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
box_non_max_suppression,
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
filter_polygons_by_area,
|
||||
mask_iou_batch,
|
||||
mask_non_max_suppression,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
move_masks,
|
||||
pad_boxes,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
scale_boxes,
|
||||
@@ -69,7 +72,11 @@ from supervision.draw.utils import (
|
||||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotators import EdgeAnnotator, VertexAnnotator
|
||||
from supervision.keypoint.annotators import (
|
||||
EdgeAnnotator,
|
||||
VertexAnnotator,
|
||||
VertexLabelAnnotator,
|
||||
)
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
|
||||
@@ -421,6 +421,9 @@ class Detections:
|
||||
xyxy=mmdet_results.pred_instances.bboxes.cpu().numpy(),
|
||||
confidence=mmdet_results.pred_instances.scores.cpu().numpy(),
|
||||
class_id=mmdet_results.pred_instances.labels.cpu().numpy().astype(int),
|
||||
mask=mmdet_results.pred_instances.masks.cpu().numpy()
|
||||
if "masks" in mmdet_results.pred_instances
|
||||
else None,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@@ -834,9 +837,10 @@ class Detections:
|
||||
|
||||
This method takes a list of Detections objects and combines their
|
||||
respective fields (`xyxy`, `mask`, `confidence`, `class_id`, and `tracker_id`)
|
||||
into a single Detections object. If all elements in a field are not
|
||||
`None`, the corresponding field will be stacked.
|
||||
Otherwise, the field will be set to `None`.
|
||||
into a single Detections object.
|
||||
|
||||
For example, if merging Detections with 3 and 4 detected objects, this method
|
||||
will return a Detections with 7 objects (7 entries in `xyxy`, `mask`, etc).
|
||||
|
||||
Args:
|
||||
detections_list (List[Detections]): A list of Detections objects to merge.
|
||||
@@ -894,13 +898,12 @@ class Detections:
|
||||
def stack_or_none(name: str):
|
||||
if all(d.__getattribute__(name) is None for d in detections_list):
|
||||
return None
|
||||
if any(d.__getattribute__(name) is None for d in detections_list):
|
||||
raise ValueError(f"All or none of the '{name}' fields must be None")
|
||||
return (
|
||||
np.vstack([d.__getattribute__(name) for d in detections_list])
|
||||
if name == "mask"
|
||||
else np.hstack([d.__getattribute__(name) for d in detections_list])
|
||||
)
|
||||
stack_list = [
|
||||
d.__getattribute__(name)
|
||||
for d in detections_list
|
||||
if d.__getattribute__(name) is not None
|
||||
]
|
||||
return np.vstack(stack_list) if name == "mask" else np.hstack(stack_list)
|
||||
|
||||
mask = stack_or_none("mask")
|
||||
confidence = stack_or_none("confidence")
|
||||
|
||||
@@ -4,20 +4,36 @@ from typing import Callable, Optional, Tuple
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import move_boxes
|
||||
from supervision.detection.utils import move_boxes, move_masks
|
||||
from supervision.utils.image import crop_image
|
||||
|
||||
|
||||
def move_detections(detections: Detections, offset: np.array) -> Detections:
|
||||
def move_detections(
|
||||
detections: Detections,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: Optional[Tuple[int, int]] = None,
|
||||
) -> Detections:
|
||||
"""
|
||||
Args:
|
||||
detections (sv.Detections): Detections object to be moved.
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
offset (np.ndarray): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution. Required for segmentation detections.
|
||||
|
||||
Returns:
|
||||
(sv.Detections) repositioned Detections object.
|
||||
"""
|
||||
detections.xyxy = move_boxes(xyxy=detections.xyxy, offset=offset)
|
||||
if detections.mask is not None:
|
||||
if resolution_wh is None:
|
||||
raise ValueError(
|
||||
"Resolution width and height are required for moving segmentation "
|
||||
"detections. This should be the same as (width, height) of image shape."
|
||||
)
|
||||
detections.mask = move_masks(
|
||||
masks=detections.mask, offset=offset, resolution_wh=resolution_wh
|
||||
)
|
||||
return detections
|
||||
|
||||
|
||||
@@ -126,7 +142,10 @@ class InferenceSlicer:
|
||||
"""
|
||||
image_slice = crop_image(image=image, xyxy=offset)
|
||||
detections = self.callback(image_slice)
|
||||
detections = move_detections(detections=detections, offset=offset[:2])
|
||||
resolution_wh = (image.shape[1], image.shape[0])
|
||||
detections = move_detections(
|
||||
detections=detections, offset=offset[:2], resolution_wh=resolution_wh
|
||||
)
|
||||
|
||||
return detections
|
||||
|
||||
|
||||
@@ -428,6 +428,35 @@ def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
return result
|
||||
|
||||
|
||||
def pad_boxes(xyxy: np.ndarray, px: int, py: Optional[int] = None) -> np.ndarray:
|
||||
"""
|
||||
Pads bounding boxes coordinates with a constant padding.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in the format
|
||||
`(x_min, y_min, x_max, y_max)`.
|
||||
px (int): The padding value to be added to both the left and right sides of
|
||||
each bounding box.
|
||||
py (Optional[int]): The padding value to be added to both the top and bottom
|
||||
sides of each bounding box. If not provided, `px` will be used for both
|
||||
dimensions.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a
|
||||
bounding box with coordinates padded according to the provided padding
|
||||
values.
|
||||
"""
|
||||
if py is None:
|
||||
py = px
|
||||
|
||||
result = xyxy.copy()
|
||||
result[:, [0, 1]] -= [px, py]
|
||||
result[:, [2, 3]] += [px, py]
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def xywh_to_xyxy(boxes_xywh: np.ndarray) -> np.ndarray:
|
||||
xyxy = boxes_xywh.copy()
|
||||
xyxy[:, 2] = boxes_xywh[:, 0] + boxes_xywh[:, 2]
|
||||
@@ -631,7 +660,7 @@ def process_roboflow_result(
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[np.ndarray],
|
||||
Dict[str, List[np.ndarray]],
|
||||
Dict[str, Union[List[np.ndarray], np.ndarray]],
|
||||
]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return (
|
||||
@@ -723,6 +752,40 @@ def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
|
||||
|
||||
def move_masks(
|
||||
masks: np.ndarray,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: Tuple[int, int] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Offset the masks in an array by the specified (x, y) amount.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
offset (np.ndarray): An array of shape `(2,)` containing non-negative int values
|
||||
`[dx, dy]`.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution.
|
||||
|
||||
Returns:
|
||||
(np.ndarray) repositioned masks, optionally padded to the specified shape.
|
||||
"""
|
||||
|
||||
if offset[0] < 0 or offset[1] < 0:
|
||||
raise ValueError(f"Offset values must be non-negative integers. Got: {offset}")
|
||||
|
||||
mask_array = np.full((masks.shape[0], resolution_wh[1], resolution_wh[0]), False)
|
||||
mask_array[
|
||||
:,
|
||||
offset[1] : masks.shape[1] + offset[1],
|
||||
offset[0] : masks.shape[2] + offset[0],
|
||||
] = masks
|
||||
|
||||
return mask_array
|
||||
|
||||
|
||||
def scale_boxes(xyxy: np.ndarray, factor: float) -> np.ndarray:
|
||||
"""
|
||||
Scale the dimensions of bounding boxes.
|
||||
@@ -809,7 +872,9 @@ def merge_data(
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the instances.
|
||||
data_list: The data payloads of the Detections instances. Each data payload
|
||||
is a dictionary with the same keys, and the values are either lists or
|
||||
np.ndarray.
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
@@ -822,10 +887,6 @@ def merge_data(
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
@@ -833,10 +894,23 @@ def merge_data(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
keys_by_data = [set(data.keys()) for data in data_list]
|
||||
keys_by_data = [keys for keys in keys_by_data if len(keys) > 0]
|
||||
if not keys_by_data:
|
||||
return {}
|
||||
|
||||
common_keys = set.intersection(*keys_by_data)
|
||||
all_keys = set.union(*keys_by_data)
|
||||
if common_keys != all_keys:
|
||||
raise ValueError(
|
||||
f"All sv.Detections.data dictionaries must have the same keys. Common "
|
||||
f"keys: {common_keys}, but some dictionaries have additional keys: "
|
||||
f"{all_keys.difference(common_keys)}."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys}
|
||||
for data in data_list:
|
||||
for key in merged_data:
|
||||
for key in data:
|
||||
merged_data[key].append(data[key])
|
||||
|
||||
for key in merged_data:
|
||||
|
||||
@@ -81,6 +81,58 @@ def draw_filled_rectangle(scene: np.ndarray, rect: Rect, color: Color) -> np.nda
|
||||
return scene
|
||||
|
||||
|
||||
def draw_rounded_rectangle(
|
||||
scene: np.ndarray,
|
||||
rect: Rect,
|
||||
color: Color,
|
||||
border_radius: int,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draws a rounded rectangle on an image.
|
||||
|
||||
Parameters:
|
||||
scene (np.ndarray): The image on which the rounded rectangle will be drawn.
|
||||
rect (Rect): The rectangle to be drawn.
|
||||
color (Color): The color of the rounded rectangle.
|
||||
border_radius (int): The radius of the corner rounding.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The image with the rounded rectangle drawn on it.
|
||||
"""
|
||||
x1, y1, x2, y2 = rect.as_xyxy_int_tuple()
|
||||
width, height = x2 - x1, y2 - y1
|
||||
border_radius = min(border_radius, min(width, height) // 2)
|
||||
|
||||
rectangle_coordinates = [
|
||||
((x1 + border_radius, y1), (x2 - border_radius, y2)),
|
||||
((x1, y1 + border_radius), (x2, y2 - border_radius)),
|
||||
]
|
||||
circle_centers = [
|
||||
(x1 + border_radius, y1 + border_radius),
|
||||
(x2 - border_radius, y1 + border_radius),
|
||||
(x1 + border_radius, y2 - border_radius),
|
||||
(x2 - border_radius, y2 - border_radius),
|
||||
]
|
||||
|
||||
for coordinates in rectangle_coordinates:
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=coordinates[0],
|
||||
pt2=coordinates[1],
|
||||
color=color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
for center in circle_centers:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=center,
|
||||
radius=border_radius,
|
||||
color=color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
return scene
|
||||
|
||||
|
||||
def draw_polygon(
|
||||
scene: np.ndarray, polygon: np.ndarray, color: Color, thickness: int = 2
|
||||
) -> np.ndarray:
|
||||
|
||||
@@ -98,6 +98,11 @@ class Rect:
|
||||
width: float
|
||||
height: float
|
||||
|
||||
@classmethod
|
||||
def from_xyxy(cls, xyxy: Tuple[float, float, float, float]) -> Rect:
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return cls(x=x1, y=y1, width=x2 - x1, height=y2 - y1)
|
||||
|
||||
@property
|
||||
def top_left(self) -> Point:
|
||||
return Point(x=self.x, y=self.y)
|
||||
@@ -113,3 +118,11 @@ class Rect:
|
||||
width=self.width + 2 * padding,
|
||||
height=self.height + 2 * padding,
|
||||
)
|
||||
|
||||
def as_xyxy_int_tuple(self) -> Tuple[int, int, int, int]:
|
||||
return (
|
||||
int(self.x),
|
||||
int(self.y),
|
||||
int(self.x + self.width),
|
||||
int(self.y + self.height),
|
||||
)
|
||||
@@ -1,12 +1,14 @@
|
||||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision import Rect, pad_boxes
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rounded_rectangle
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
@@ -46,8 +48,8 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
points. It draws circles at each key point location.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
scene (ImageType): The image where skeleton vertices will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
@@ -63,7 +65,10 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
vertex_annotator = sv.VertexAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
radius=10
|
||||
)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
@@ -119,7 +124,7 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
edges.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
scene (ImageType): The image where skeleton edges will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
@@ -137,7 +142,10 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
@@ -175,3 +183,236 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class VertexLabelAnnotator:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
points to determine the locations where the vertices should be drawn.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, List[Color]] = Color.ROBOFLOW,
|
||||
text_color: Color = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
border_radius: int = 0,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, List[Color]], optional): The color to use for each
|
||||
keypoint label. If a list is provided, the colors will be used in order
|
||||
for each keypoint.
|
||||
text_color (Color, optional): The color to use for the labels.
|
||||
text_scale (float, optional): The scale of the text.
|
||||
text_thickness (int, optional): The thickness of the text.
|
||||
text_padding (int, optional): The padding around the text.
|
||||
border_radius (int, optional): The radius of the rounded corners of the
|
||||
boxes. Set to a high value to produce circles.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, List[Color]] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
def annotate(
|
||||
self, scene: ImageType, key_points: KeyPoints, labels: List[str] = None
|
||||
) -> ImageType:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
points to determine the locations where the vertices should be drawn.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where vertex labels will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
labels (List[str], optional): A list of labels to be displayed on the
|
||||
annotated image. If not provided, keypoint indices will be used.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
text_color=sv.Color.BLACK,
|
||||
border_radius=5
|
||||
)
|
||||
annotated_frame = vertex_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
|
||||
!!! tip
|
||||
|
||||
`VertexLabelAnnotator` allows to customize the color of each keypoint label
|
||||
values.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
LABELS = [
|
||||
"nose", "left eye", "right eye", "left ear",
|
||||
"right ear", "left shoulder", "right shoulder", "left elbow",
|
||||
"right elbow", "left wrist", "right wrist", "left hip",
|
||||
"right hip", "left knee", "right knee", "left ankle",
|
||||
"right ankle"
|
||||
]
|
||||
|
||||
COLORS = [
|
||||
"#FF6347", "#FF6347", "#FF6347", "#FF6347",
|
||||
"#FF6347", "#FF1493", "#00FF00", "#FF1493",
|
||||
"#00FF00", "#FF1493", "#00FF00", "#FFD700",
|
||||
"#00BFFF", "#FFD700", "#00BFFF", "#FFD700",
|
||||
"#00BFFF"
|
||||
]
|
||||
COLORS = [sv.Color.from_hex(color_hex=c) for c in COLORS]
|
||||
|
||||
vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
color=COLORS,
|
||||
text_color=sv.Color.BLACK,
|
||||
border_radius=5
|
||||
)
|
||||
annotated_frame = vertex_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||

|
||||
"""
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
|
||||
skeletons_count, points_count, _ = key_points.xy.shape
|
||||
if skeletons_count == 0:
|
||||
return scene
|
||||
|
||||
anchors = key_points.xy.reshape(points_count * skeletons_count, 2).astype(int)
|
||||
mask = np.all(anchors != 0, axis=1)
|
||||
|
||||
if not np.any(mask):
|
||||
return scene
|
||||
|
||||
colors = self.preprocess_and_validate_colors(
|
||||
colors=self.color,
|
||||
points_count=points_count,
|
||||
skeletons_count=skeletons_count,
|
||||
)
|
||||
|
||||
labels = self.preprocess_and_validate_labels(
|
||||
labels=labels, points_count=points_count, skeletons_count=skeletons_count
|
||||
)
|
||||
|
||||
anchors = anchors[mask]
|
||||
colors = colors[mask]
|
||||
labels = labels[mask]
|
||||
|
||||
xyxy = np.array(
|
||||
[
|
||||
self.get_text_bounding_box(
|
||||
text=label,
|
||||
font=font,
|
||||
text_scale=self.text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
center_coordinates=tuple(anchor),
|
||||
)
|
||||
for anchor, label in zip(anchors, labels)
|
||||
]
|
||||
)
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy=xyxy, px=self.text_padding)
|
||||
|
||||
for text, color, box, box_padded in zip(labels, colors, xyxy, xyxy_padded):
|
||||
draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
rect=Rect.from_xyxy(box_padded),
|
||||
color=color,
|
||||
border_radius=self.border_radius,
|
||||
)
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
org=(box[0], box[1] + self.text_padding),
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
color=self.text_color.as_rgb(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def get_text_bounding_box(
|
||||
text: str,
|
||||
font: int,
|
||||
text_scale: float,
|
||||
text_thickness: int,
|
||||
center_coordinates: Tuple[int, int],
|
||||
) -> Tuple[int, int, int, int]:
|
||||
text_w, text_h = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
fontScale=text_scale,
|
||||
thickness=text_thickness,
|
||||
)[0]
|
||||
center_x, center_y = center_coordinates
|
||||
return (
|
||||
center_x - text_w // 2,
|
||||
center_y - text_h // 2,
|
||||
center_x + text_w // 2,
|
||||
center_y + text_h // 2,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_labels(
|
||||
labels: Optional[List[str]], points_count: int, skeletons_count: int
|
||||
) -> np.array:
|
||||
if labels and len(labels) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of labels ({len(labels)}) must match number of key points "
|
||||
f"({points_count})."
|
||||
)
|
||||
if labels is None:
|
||||
labels = [str(i) for i in range(points_count)]
|
||||
|
||||
return np.array(labels * skeletons_count)
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_colors(
|
||||
colors: Optional[Union[Color, List[Color]]],
|
||||
points_count: int,
|
||||
skeletons_count: int,
|
||||
) -> np.array:
|
||||
if isinstance(colors, list) and len(colors) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of colors ({len(colors)}) must match number of key points "
|
||||
f"({points_count})."
|
||||
)
|
||||
return (
|
||||
np.array(colors * skeletons_count)
|
||||
if isinstance(colors, list)
|
||||
else np.array([colors] * points_count * skeletons_count)
|
||||
)
|
||||
@@ -487,7 +487,7 @@ class ByteTrack:
|
||||
self.lost_tracks = sub_tracks(self.lost_tracks, self.tracked_tracks)
|
||||
self.lost_tracks.extend(lost_stracks)
|
||||
self.lost_tracks = sub_tracks(self.lost_tracks, self.removed_tracks)
|
||||
self.removed_tracks.extend(removed_stracks)
|
||||
self.removed_tracks = removed_stracks
|
||||
self.tracked_tracks, self.lost_tracks = remove_duplicate_tracks(
|
||||
self.tracked_tracks, self.lost_tracks
|
||||
)
|
||||
|
||||
+118
-34
@@ -30,6 +30,84 @@ DETECTIONS = Detections(
|
||||
)
|
||||
|
||||
|
||||
# Merge test
|
||||
TEST_MASK = np.zeros((1000, 1000), dtype=bool)
|
||||
TEST_MASK[300:351, 200:251] = True
|
||||
TEST_DET_1 = Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40], [50, 50, 60, 60]]),
|
||||
mask=np.array([TEST_MASK, TEST_MASK, TEST_MASK]),
|
||||
confidence=np.array([0.1, 0.2, 0.3]),
|
||||
class_id=np.array([1, 2, 3]),
|
||||
tracker_id=np.array([1, 2, 3]),
|
||||
data={
|
||||
"some_key": [1, 2, 3],
|
||||
"other_key": [["1", "2"], ["3", "4"], ["5", "6"]],
|
||||
},
|
||||
)
|
||||
TEST_DET_2 = Detections(
|
||||
xyxy=np.array([[70, 70, 80, 80], [90, 90, 100, 100]]),
|
||||
mask=np.array([TEST_MASK, TEST_MASK]),
|
||||
confidence=np.array([0.4, 0.5]),
|
||||
class_id=np.array([4, 5]),
|
||||
tracker_id=np.array([4, 5]),
|
||||
data={
|
||||
"some_key": [4, 5],
|
||||
"other_key": [["7", "8"], ["9", "10"]],
|
||||
},
|
||||
)
|
||||
TEST_DET_1_2 = Detections(
|
||||
xyxy=np.array(
|
||||
[
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40],
|
||||
[50, 50, 60, 60],
|
||||
[70, 70, 80, 80],
|
||||
[90, 90, 100, 100],
|
||||
]
|
||||
),
|
||||
mask=np.array([TEST_MASK, TEST_MASK, TEST_MASK, TEST_MASK, TEST_MASK]),
|
||||
confidence=np.array([0.1, 0.2, 0.3, 0.4, 0.5]),
|
||||
class_id=np.array([1, 2, 3, 4, 5]),
|
||||
tracker_id=np.array([1, 2, 3, 4, 5]),
|
||||
data={
|
||||
"some_key": [1, 2, 3, 4, 5],
|
||||
"other_key": [["1", "2"], ["3", "4"], ["5", "6"], ["7", "8"], ["9", "10"]],
|
||||
},
|
||||
)
|
||||
TEST_DET_ZERO_LENGTH = Detections(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
mask=np.empty((0, *TEST_MASK.shape), dtype=bool),
|
||||
confidence=np.empty((0,)),
|
||||
class_id=np.empty((0,)),
|
||||
tracker_id=np.empty((0,)),
|
||||
data={
|
||||
"some_key": [],
|
||||
"other_key": [],
|
||||
},
|
||||
)
|
||||
TEST_DET_NONE = Detections(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
)
|
||||
TEST_DET_DIFFERENT_FIELDS = Detections(
|
||||
xyxy=np.array([[88, 88, 99, 99]]),
|
||||
mask=np.array([np.logical_not(TEST_MASK)]),
|
||||
confidence=None,
|
||||
class_id=None,
|
||||
tracker_id=np.array([9]),
|
||||
data={"some_key": [9], "other_key": [["11", "12"]]},
|
||||
)
|
||||
TEST_DET_DIFFERENT_DATA = Detections(
|
||||
xyxy=np.array([[88, 88, 99, 99]]),
|
||||
mask=np.array([np.logical_not(TEST_MASK)]),
|
||||
confidence=np.array([0.9]),
|
||||
class_id=np.array([9]),
|
||||
tracker_id=np.array([9]),
|
||||
data={
|
||||
"never_seen_key": [9],
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"detections, index, expected_result, exception",
|
||||
[
|
||||
@@ -148,52 +226,58 @@ def test_getitem(
|
||||
DoesNotRaise(),
|
||||
), # single empty detections
|
||||
(
|
||||
[mock_detections(xyxy=[[10, 10, 20, 20]])],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
[Detections.empty(), Detections.empty()],
|
||||
Detections.empty(),
|
||||
DoesNotRaise(),
|
||||
), # single detection with xyxy field
|
||||
), # two empty detections
|
||||
(
|
||||
[TEST_DET_1],
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # single detection with fields
|
||||
(
|
||||
[TEST_DET_NONE],
|
||||
TEST_DET_NONE,
|
||||
DoesNotRaise(),
|
||||
), # Single weakly-defined detection
|
||||
(
|
||||
[TEST_DET_1, TEST_DET_2],
|
||||
TEST_DET_1_2,
|
||||
DoesNotRaise(),
|
||||
), # Fields with same keys
|
||||
# Fields and empty
|
||||
(
|
||||
[TEST_DET_1, Detections.empty()],
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # single detection with fields
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
mock_detections(xyxy=np.empty((0, 4), dtype=np.float32)),
|
||||
TEST_DET_1,
|
||||
TEST_DET_ZERO_LENGTH,
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # single detection with xyxy field + empty detection
|
||||
), # Single detection and empty-array fields
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]]),
|
||||
TEST_DET_1,
|
||||
TEST_DET_NONE,
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]]),
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # two detections with xyxy field
|
||||
), # Single detection and None fields (+ missing Dict keys)
|
||||
# Errors: Non-zero-length differently defined keys & data
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], class_id=[0]),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]]),
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]]),
|
||||
[TEST_DET_1, TEST_DET_DIFFERENT_FIELDS],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # detection with xyxy, class_id fields + detection with xyxy field
|
||||
), # Non-empty detections with different fields
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], class_id=[0]),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]], class_id=[1]),
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], class_id=[0, 1]),
|
||||
DoesNotRaise(),
|
||||
), # two detections with xyxy, class_id fields
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]], data={"test": [2]}),
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], data={"test": [1, 2]}
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two detections with xyxy, data fields
|
||||
[TEST_DET_1, TEST_DET_DIFFERENT_DATA],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Non-empty detections with different data keys
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
|
||||
@@ -911,6 +911,14 @@ def test_calculate_masks_centroids(
|
||||
{"test_1": []},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty list values
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
{"test_1": []},
|
||||
],
|
||||
{"test_1": []},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty list values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([])},
|
||||
@@ -918,6 +926,14 @@ def test_calculate_masks_centroids(
|
||||
{"test_1": np.array([])},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([])},
|
||||
{"test_1": np.array([])},
|
||||
],
|
||||
{"test_1": np.array([])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
@@ -932,7 +948,7 @@ def test_calculate_masks_centroids(
|
||||
],
|
||||
{"test_1": [3, 2, 1]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty and list values
|
||||
), # two data dicts with the same field name; one of with empty list as value
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
@@ -1012,6 +1028,49 @@ def test_calculate_masks_centroids(
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with the same field name and different length arrays values
|
||||
(
|
||||
[{}, {"test_1": [1, 2, 3]}],
|
||||
{"test_1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts; one empty and one non-empty dict
|
||||
(
|
||||
[{"test_1": [], "test_2": []}, {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}],
|
||||
{"test_1": [1, 2, 3], "test_2": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts; one empty and one non-empty dict; same keys
|
||||
(
|
||||
[{"test_1": []}, {"test_1": [1, 2, 3], "test_2": [4, 5, 6]}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one empty and one non-empty dict; different keys
|
||||
(
|
||||
[
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
"test_2": [4, 5, 6],
|
||||
"test_3": [7, 8, 9],
|
||||
},
|
||||
{"test_1": [1, 2, 3], "test_2": [4, 5, 6]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one with three keys, one with two keys
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [1, 2, 3], "test_2": [1, 2, 3]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # some keys missing in one dict
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3], "test_2": ["a", "b"]},
|
||||
{"test_1": [4, 5], "test_2": ["c", "d", "e"]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # different value lengths for the same key
|
||||
],
|
||||
)
|
||||
def test_merge_data(
|
||||
@@ -1021,6 +1080,9 @@ def test_merge_data(
|
||||
):
|
||||
with exception:
|
||||
result = merge_data(data_list=data_list)
|
||||
if expected_result is None:
|
||||
assert False, f"Expected an error, but got result {result}"
|
||||
|
||||
for key in result:
|
||||
if isinstance(result[key], np.ndarray):
|
||||
assert np.array_equal(
|
||||
|
||||
Reference in new issue
Block a user