Merge branch 'develop' into OBB
This commit is contained in:
 LinasKo committed
commit
79ea168fd4
45 files changed
+3589
-809
No files matched your search
@@ -28,7 +28,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.8'
|
||||
rev: '1.7.9'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
@@ -45,7 +45,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.4.4
|
||||
rev: v0.4.9
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
+1
-1
@@ -64,7 +64,7 @@ To run the pre-commit tool, follow these steps:
|
||||
|
||||
3. Run the command `pre-commit run --all-files`. This will execute the pre-commit hooks configured for this project against the modified files. If any issues are found, the pre-commit tool will provide feedback on how to resolve them. Make the necessary changes and re-run the pre-commit command until all issues are resolved.
|
||||
|
||||
4. You can also install pre-commit as a git hook by execute `pre-commit install`. Every time you made `git commit` pre-commit run automatically for you.
|
||||
4. You can also install pre-commit as a git hook by executing `pre-commit install`. Every time you do a `git commit` pre-commit run automatically for you.
|
||||
|
||||
### Docstrings
|
||||
|
||||
|
||||
@@ -1,3 +1,83 @@
|
||||
### 0.21.0 <small>Jun 5, 2024</small>
|
||||
|
||||
- Added [#500](https://github.com/roboflow/supervision/pull/500): [`sv.Detections.with_nmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.with_nmm) to perform non-maximum merging on the current set of object detections.
|
||||
|
||||
- Added [#1221](https://github.com/roboflow/supervision/pull/1221): [`sv.Detections.from_lmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.from_lmm) allowing to parse Large Multimodal Model (LMM) text result into [`sv.Detections`](https://supervision.roboflow.com/develop/detection/core/) object. For now `from_lmm` supports only [PaliGemma](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-finetune-paligemma-on-detection-dataset.ipynb) result parsing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
```
|
||||
|
||||
- Added [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.VertexLabelAnnotator`](https://supervision.roboflow.com/develop/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator.annotate) allowing to annotate every vertex of a keypoint skeleton with custom text and color.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#1147](https://github.com/roboflow/supervision/pull/1147): [`sv.KeyPoints.from_inference`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [Inference](https://github.com/roboflow/inference) result.
|
||||
|
||||
- Added [#1138](https://github.com/roboflow/supervision/pull/1138): [`sv.KeyPoints.from_yolo_nas`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_yolo_nas) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) result.
|
||||
|
||||
- Added [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.mask_to_rle`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) and [`sv.rle_to_mask`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) allowing for easy conversion between mask and rle formats.
|
||||
|
||||
- Changed [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) allowing to select overlap filtering strategy (`NONE`, `NON_MAX_SUPPRESSION` and `NON_MAX_MERGE`).
|
||||
|
||||
- Changed [#1178](https://github.com/roboflow/supervision/pull/1178): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) adding instance segmentation model support.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Changed [#1228](https://github.com/roboflow/supervision/pull/1228): [`sv.LineZone`](https://supervision.roboflow.com/develop/detection/tools/line_zone/) making it 10-20 times faster, depending on the use case.
|
||||
|
||||
- Changed [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) and [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) adding support for run-length encoding (RLE) mask format.
|
||||
|
||||
### 0.20.0 <small>April 24, 2024</small>
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models.
|
||||
|
||||
@@ -1,7 +1,6 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
status: new
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.rle_to_mask">rle_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.rle_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.mask_to_rle">mask_to_rle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.mask_to_rle
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
@@ -0,0 +1,30 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Double Detection Filter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.OverlapFilter">OverlapFilter</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.OverlapFilter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_merge">box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_merge
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
+12
-13
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
@@ -17,18 +16,6 @@ status: new
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
@@ -88,3 +75,15 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_holes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_multiple_segments">contains_multiple_segments</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_multiple_segments
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
+1
-1
@@ -41,7 +41,7 @@ comments: true
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_font_scale">calculate_optimal_font_scale</a></h2>
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_text_scale">calculate_optimal_text_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
+1
-2
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Image Utils
|
||||
@@ -12,7 +11,7 @@ status: new
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.scale_image">crop_image</a></h2>
|
||||
<h2><a href="#supervision.utils.image.scale_image">scale_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Iterables Utils
|
||||
|
||||
+9
-6
@@ -35,19 +35,20 @@ extra_css:
|
||||
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Supervision: index.md
|
||||
- Learn:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
|
||||
- API:
|
||||
- Reference - Code API:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Double Detection Filter: detection/double_detection_filter.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
@@ -61,7 +62,9 @@ nav:
|
||||
- Detection Smoother: detection/tools/smoother.md
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
- Datasets:
|
||||
- Core: datasets/core.md
|
||||
- Utils: datasets/utils.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
@@ -76,7 +79,7 @@ nav:
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- License: license.md
|
||||
- Changelog:
|
||||
- Release Notes:
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
|
||||
|
||||
Generated
+81
-80
@@ -1253,21 +1253,21 @@ test-extra = ["curio", "matplotlib (!=3.2.0)", "nbformat", "numpy (>=1.21)", "pa
|
||||
|
||||
[[package]]
|
||||
name = "ipywidgets"
|
||||
version = "8.1.2"
|
||||
version = "8.1.3"
|
||||
description = "Jupyter interactive widgets"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ipywidgets-8.1.2-py3-none-any.whl", hash = "sha256:bbe43850d79fb5e906b14801d6c01402857996864d1e5b6fa62dd2ee35559f60"},
|
||||
{file = "ipywidgets-8.1.2.tar.gz", hash = "sha256:d0b9b41e49bae926a866e613a39b0f0097745d2b9f1f3dd406641b4a57ec42c9"},
|
||||
{file = "ipywidgets-8.1.3-py3-none-any.whl", hash = "sha256:efafd18f7a142248f7cb0ba890a68b96abd4d6e88ddbda483c9130d12667eaf2"},
|
||||
{file = "ipywidgets-8.1.3.tar.gz", hash = "sha256:f5f9eeaae082b1823ce9eac2575272952f40d748893972956dc09700a6392d9c"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
comm = ">=0.1.3"
|
||||
ipython = ">=6.1.0"
|
||||
jupyterlab-widgets = ">=3.0.10,<3.1.0"
|
||||
jupyterlab-widgets = ">=3.0.11,<3.1.0"
|
||||
traitlets = ">=4.3.1"
|
||||
widgetsnbextension = ">=4.0.10,<4.1.0"
|
||||
widgetsnbextension = ">=4.0.11,<4.1.0"
|
||||
|
||||
[package.extras]
|
||||
test = ["ipykernel", "jsonschema", "pytest (>=3.6.0)", "pytest-cov", "pytz"]
|
||||
@@ -1566,13 +1566,13 @@ test = ["jupyter-server (>=2.0.0)", "pytest (>=7.0)", "pytest-jupyter[server] (>
|
||||
|
||||
[[package]]
|
||||
name = "jupyterlab"
|
||||
version = "4.1.2"
|
||||
version = "4.2.0"
|
||||
description = "JupyterLab computational environment"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "jupyterlab-4.1.2-py3-none-any.whl", hash = "sha256:aa88193f03cf4d3555f6712f04d74112b5eb85edd7d222c588c7603a26d33c5b"},
|
||||
{file = "jupyterlab-4.1.2.tar.gz", hash = "sha256:5d6348b3ed4085181499f621b7dfb6eb0b1f57f3586857aadfc8e3bf4c4885f9"},
|
||||
{file = "jupyterlab-4.2.0-py3-none-any.whl", hash = "sha256:0dfe9278e25a145362289c555d9beb505697d269c10e99909766af7c440ad3cc"},
|
||||
{file = "jupyterlab-4.2.0.tar.gz", hash = "sha256:356e9205a6a2ab689c47c8fe4919dba6c076e376d03f26baadc05748c2435dd5"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -1580,23 +1580,24 @@ async-lru = ">=1.0.0"
|
||||
httpx = ">=0.25.0"
|
||||
importlib-metadata = {version = ">=4.8.3", markers = "python_version < \"3.10\""}
|
||||
importlib-resources = {version = ">=1.4", markers = "python_version < \"3.9\""}
|
||||
ipykernel = "*"
|
||||
ipykernel = ">=6.5.0"
|
||||
jinja2 = ">=3.0.3"
|
||||
jupyter-core = "*"
|
||||
jupyter-lsp = ">=2.0.0"
|
||||
jupyter-server = ">=2.4.0,<3"
|
||||
jupyterlab-server = ">=2.19.0,<3"
|
||||
jupyterlab-server = ">=2.27.1,<3"
|
||||
notebook-shim = ">=0.2"
|
||||
packaging = "*"
|
||||
tomli = {version = "*", markers = "python_version < \"3.11\""}
|
||||
tomli = {version = ">=1.2.2", markers = "python_version < \"3.11\""}
|
||||
tornado = ">=6.2.0"
|
||||
traitlets = "*"
|
||||
|
||||
[package.extras]
|
||||
dev = ["build", "bump2version", "coverage", "hatch", "pre-commit", "pytest-cov", "ruff (==0.2.0)"]
|
||||
dev = ["build", "bump2version", "coverage", "hatch", "pre-commit", "pytest-cov", "ruff (==0.3.5)"]
|
||||
docs = ["jsx-lexer", "myst-parser", "pydata-sphinx-theme (>=0.13.0)", "pytest", "pytest-check-links", "pytest-jupyter", "sphinx (>=1.8,<7.3.0)", "sphinx-copybutton"]
|
||||
docs-screenshots = ["altair (==5.2.0)", "ipython (==8.16.1)", "ipywidgets (==8.1.1)", "jupyterlab-geojson (==3.4.0)", "jupyterlab-language-pack-zh-cn (==4.0.post6)", "matplotlib (==3.8.2)", "nbconvert (>=7.0.0)", "pandas (==2.2.0)", "scipy (==1.12.0)", "vega-datasets (==0.9.0)"]
|
||||
docs-screenshots = ["altair (==5.3.0)", "ipython (==8.16.1)", "ipywidgets (==8.1.2)", "jupyterlab-geojson (==3.4.0)", "jupyterlab-language-pack-zh-cn (==4.1.post2)", "matplotlib (==3.8.3)", "nbconvert (>=7.0.0)", "pandas (==2.2.1)", "scipy (==1.12.0)", "vega-datasets (==0.9.0)"]
|
||||
test = ["coverage", "pytest (>=7.0)", "pytest-check-links (>=0.7)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter (>=0.5.3)", "pytest-timeout", "pytest-tornasync", "requests", "requests-cache", "virtualenv"]
|
||||
upgrade-extension = ["copier (>=8,<10)", "jinja2-time (<0.3)", "pydantic (<2.0)", "pyyaml-include (<2.0)", "tomli-w (<2.0)"]
|
||||
|
||||
[[package]]
|
||||
name = "jupyterlab-pygments"
|
||||
@@ -1611,13 +1612,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "jupyterlab-server"
|
||||
version = "2.25.3"
|
||||
version = "2.27.1"
|
||||
description = "A set of server components for JupyterLab and JupyterLab like applications."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "jupyterlab_server-2.25.3-py3-none-any.whl", hash = "sha256:c48862519fded9b418c71645d85a49b2f0ec50d032ba8316738e9276046088c1"},
|
||||
{file = "jupyterlab_server-2.25.3.tar.gz", hash = "sha256:846f125a8a19656611df5b03e5912c8393cea6900859baa64fa515eb64a8dc40"},
|
||||
{file = "jupyterlab_server-2.27.1-py3-none-any.whl", hash = "sha256:f5e26156e5258b24d532c84e7c74cc212e203bff93eb856f81c24c16daeecc75"},
|
||||
{file = "jupyterlab_server-2.27.1.tar.gz", hash = "sha256:097b5ac709b676c7284ac9c5e373f11930a561f52cd5a86e4fc7e5a9c8a8631d"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -1633,17 +1634,17 @@ requests = ">=2.31"
|
||||
[package.extras]
|
||||
docs = ["autodoc-traits", "jinja2 (<3.2.0)", "mistune (<4)", "myst-parser", "pydata-sphinx-theme", "sphinx", "sphinx-copybutton", "sphinxcontrib-openapi (>0.8)"]
|
||||
openapi = ["openapi-core (>=0.18.0,<0.19.0)", "ruamel-yaml"]
|
||||
test = ["hatch", "ipykernel", "openapi-core (>=0.18.0,<0.19.0)", "openapi-spec-validator (>=0.6.0,<0.8.0)", "pytest (>=7.0)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter[server] (>=0.6.2)", "pytest-timeout", "requests-mock", "ruamel-yaml", "sphinxcontrib-spelling", "strict-rfc3339", "werkzeug"]
|
||||
test = ["hatch", "ipykernel", "openapi-core (>=0.18.0,<0.19.0)", "openapi-spec-validator (>=0.6.0,<0.8.0)", "pytest (>=7.0,<8)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter[server] (>=0.6.2)", "pytest-timeout", "requests-mock", "ruamel-yaml", "sphinxcontrib-spelling", "strict-rfc3339", "werkzeug"]
|
||||
|
||||
[[package]]
|
||||
name = "jupyterlab-widgets"
|
||||
version = "3.0.10"
|
||||
version = "3.0.11"
|
||||
description = "Jupyter interactive widgets for JupyterLab"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "jupyterlab_widgets-3.0.10-py3-none-any.whl", hash = "sha256:dd61f3ae7a5a7f80299e14585ce6cf3d6925a96c9103c978eda293197730cb64"},
|
||||
{file = "jupyterlab_widgets-3.0.10.tar.gz", hash = "sha256:04f2ac04976727e4f9d0fa91cdc2f1ab860f965e504c29dbd6a65c882c9d04c0"},
|
||||
{file = "jupyterlab_widgets-3.0.11-py3-none-any.whl", hash = "sha256:78287fd86d20744ace330a61625024cf5521e1c012a352ddc0a3cdc2348becd0"},
|
||||
{file = "jupyterlab_widgets-3.0.11.tar.gz", hash = "sha256:dd5ac679593c969af29c9bed054c24f26842baa51352114736756bc035deee27"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -2163,13 +2164,13 @@ requests = "*"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-git-revision-date-localized-plugin"
|
||||
version = "1.2.5"
|
||||
version = "1.2.6"
|
||||
description = "Mkdocs plugin that enables displaying the localized date of the last git modification of a markdown file."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.5-py3-none-any.whl", hash = "sha256:d796a18b07cfcdb154c133e3ec099d2bb5f38389e4fd54d3eb516a8a736815b8"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.5.tar.gz", hash = "sha256:0c439816d9d0dba48e027d9d074b2b9f1d7cd179f74ba46b51e4da7bb3dc4b9b"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.6-py3-none-any.whl", hash = "sha256:f015cb0f3894a39b33447b18e270ae391c4e25275cac5a626e80b243784e2692"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.6.tar.gz", hash = "sha256:e432942ce4ee8aa9b9f4493e993dee9d2cc08b3ea2b40a3d6b03ca0f2a4bcaa2"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2198,13 +2199,13 @@ pygments = ">2.12.0"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.23"
|
||||
version = "9.5.27"
|
||||
description = "Documentation that simply works"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_material-9.5.23-py3-none-any.whl", hash = "sha256:ffd08a5beaef3cd135aceb58ded8b98bbbbf2b70e5b656f6a14a63c917d9b001"},
|
||||
{file = "mkdocs_material-9.5.23.tar.gz", hash = "sha256:4627fc3f15de2cba2bde9debc2fd59b9888ef494beabfe67eb352e23d14bf288"},
|
||||
{file = "mkdocs_material-9.5.27-py3-none-any.whl", hash = "sha256:af8cc263fafa98bb79e9e15a8c966204abf15164987569bd1175fd66a7705182"},
|
||||
{file = "mkdocs_material-9.5.27.tar.gz", hash = "sha256:a7d4a35f6d4a62b0c43a0cfe7e987da0980c13587b5bc3c26e690ad494427ec0"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2484,26 +2485,26 @@ setuptools = "*"
|
||||
|
||||
[[package]]
|
||||
name = "notebook"
|
||||
version = "7.1.3"
|
||||
version = "7.2.1"
|
||||
description = "Jupyter Notebook - A web-based notebook environment for interactive computing"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "notebook-7.1.3-py3-none-any.whl", hash = "sha256:919b911e59f41f6e3857ce93c9d93535ba66bb090059712770e5968c07e1004d"},
|
||||
{file = "notebook-7.1.3.tar.gz", hash = "sha256:41fcebff44cf7bb9377180808bcbae066629b55d8c7722f1ebbe75ca44f9cfc1"},
|
||||
{file = "notebook-7.2.1-py3-none-any.whl", hash = "sha256:f45489a3995746f2195a137e0773e2130960b51c9ac3ce257dbc2705aab3a6ca"},
|
||||
{file = "notebook-7.2.1.tar.gz", hash = "sha256:4287b6da59740b32173d01d641f763d292f49c30e7a51b89c46ba8473126341e"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
jupyter-server = ">=2.4.0,<3"
|
||||
jupyterlab = ">=4.1.1,<4.2"
|
||||
jupyterlab-server = ">=2.22.1,<3"
|
||||
jupyterlab = ">=4.2.0,<4.3"
|
||||
jupyterlab-server = ">=2.27.1,<3"
|
||||
notebook-shim = ">=0.2,<0.3"
|
||||
tornado = ">=6.2.0"
|
||||
|
||||
[package.extras]
|
||||
dev = ["hatch", "pre-commit"]
|
||||
docs = ["myst-parser", "nbsphinx", "pydata-sphinx-theme", "sphinx (>=1.3.6)", "sphinxcontrib-github-alt", "sphinxcontrib-spelling"]
|
||||
test = ["importlib-resources (>=5.0)", "ipykernel", "jupyter-server[test] (>=2.4.0,<3)", "jupyterlab-server[test] (>=2.22.1,<3)", "nbval", "pytest (>=7.0)", "pytest-console-scripts", "pytest-timeout", "pytest-tornasync", "requests"]
|
||||
test = ["importlib-resources (>=5.0)", "ipykernel", "jupyter-server[test] (>=2.4.0,<3)", "jupyterlab-server[test] (>=2.27.1,<3)", "nbval", "pytest (>=7.0)", "pytest-console-scripts", "pytest-timeout", "pytest-tornasync", "requests"]
|
||||
|
||||
[[package]]
|
||||
name = "notebook-shim"
|
||||
@@ -3038,13 +3039,13 @@ tomli = {version = ">=1.1.0", markers = "python_version < \"3.11\""}
|
||||
|
||||
[[package]]
|
||||
name = "pytest"
|
||||
version = "8.2.0"
|
||||
version = "8.2.2"
|
||||
description = "pytest: simple powerful testing with Python"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "pytest-8.2.0-py3-none-any.whl", hash = "sha256:1733f0620f6cda4095bbf0d9ff8022486e91892245bb9e7d5542c018f612f233"},
|
||||
{file = "pytest-8.2.0.tar.gz", hash = "sha256:d507d4482197eac0ba2bae2e9babf0672eb333017bcedaa5fb1a3d42c1174b3f"},
|
||||
{file = "pytest-8.2.2-py3-none-any.whl", hash = "sha256:c434598117762e2bd304e526244f67bf66bbd7b5d6cf22138be51ff661980343"},
|
||||
{file = "pytest-8.2.2.tar.gz", hash = "sha256:de4bb8104e201939ccdc688b27a89a7be2079b22e2bd2b07f806b6ba71117977"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -3460,13 +3461,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "requests"
|
||||
version = "2.31.0"
|
||||
version = "2.32.3"
|
||||
description = "Python HTTP for Humans."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "requests-2.31.0-py3-none-any.whl", hash = "sha256:58cd2187c01e70e6e26505bca751777aa9f2ee0b7f4300988b709f44e013003f"},
|
||||
{file = "requests-2.31.0.tar.gz", hash = "sha256:942c5a758f98d790eaed1a29cb6eefc7ffb0d1cf7af05c3d2791656dbd6ad1e1"},
|
||||
{file = "requests-2.32.3-py3-none-any.whl", hash = "sha256:70761cfe03c773ceb22aa2f671b4757976145175cdfca038c02654d061d6dcc6"},
|
||||
{file = "requests-2.32.3.tar.gz", hash = "sha256:55365417734eb18255590a9ff9eb97e9e1da868d4ccd6402399eaf68af20a760"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -3661,28 +3662,28 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.4.4"
|
||||
version = "0.4.9"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.4.4-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:29d44ef5bb6a08e235c8249294fa8d431adc1426bfda99ed493119e6f9ea1bf6"},
|
||||
{file = "ruff-0.4.4-py3-none-macosx_11_0_arm64.whl", hash = "sha256:c4efe62b5bbb24178c950732ddd40712b878a9b96b1d02b0ff0b08a090cbd891"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4c8e2f1e8fc12d07ab521a9005d68a969e167b589cbcaee354cb61e9d9de9c15"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:60ed88b636a463214905c002fa3eaab19795679ed55529f91e488db3fe8976ab"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:b90fc5e170fc71c712cc4d9ab0e24ea505c6a9e4ebf346787a67e691dfb72e85"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:8e7e6ebc10ef16dcdc77fd5557ee60647512b400e4a60bdc4849468f076f6eef"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:b9ddb2c494fb79fc208cd15ffe08f32b7682519e067413dbaf5f4b01a6087bcd"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:c51c928a14f9f0a871082603e25a1588059b7e08a920f2f9fa7157b5bf08cfe9"},
|
||||
{file = "ruff-0.4.4-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:b5eb0a4bfd6400b7d07c09a7725e1a98c3b838be557fee229ac0f84d9aa49c36"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:b1867ee9bf3acc21778dcb293db504692eda5f7a11a6e6cc40890182a9f9e595"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:1aecced1269481ef2894cc495647392a34b0bf3e28ff53ed95a385b13aa45768"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_i686.whl", hash = "sha256:9da73eb616b3241a307b837f32756dc20a0b07e2bcb694fec73699c93d04a69e"},
|
||||
{file = "ruff-0.4.4-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:958b4ea5589706a81065e2a776237de2ecc3e763342e5cc8e02a4a4d8a5e6f95"},
|
||||
{file = "ruff-0.4.4-py3-none-win32.whl", hash = "sha256:cb53473849f011bca6e754f2cdf47cafc9c4f4ff4570003a0dad0b9b6890e876"},
|
||||
{file = "ruff-0.4.4-py3-none-win_amd64.whl", hash = "sha256:424e5b72597482543b684c11def82669cc6b395aa8cc69acc1858b5ef3e5daae"},
|
||||
{file = "ruff-0.4.4-py3-none-win_arm64.whl", hash = "sha256:39df0537b47d3b597293edbb95baf54ff5b49589eb7ff41926d8243caa995ea6"},
|
||||
{file = "ruff-0.4.4.tar.gz", hash = "sha256:f87ea42d5cdebdc6a69761a9d0bc83ae9b3b30d0ad78952005ba6568d6c022af"},
|
||||
{file = "ruff-0.4.9-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:b262ed08d036ebe162123170b35703aaf9daffecb698cd367a8d585157732991"},
|
||||
{file = "ruff-0.4.9-py3-none-macosx_11_0_arm64.whl", hash = "sha256:98ec2775fd2d856dc405635e5ee4ff177920f2141b8e2d9eb5bd6efd50e80317"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4555056049d46d8a381f746680db1c46e67ac3b00d714606304077682832998e"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:e91175fbe48f8a2174c9aad70438fe9cb0a5732c4159b2a10a3565fea2d94cde"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:0e8e7b95673f22e0efd3571fb5b0cf71a5eaaa3cc8a776584f3b2cc878e46bff"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:2d45ddc6d82e1190ea737341326ecbc9a61447ba331b0a8962869fcada758505"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:78de3fdb95c4af084087628132336772b1c5044f6e710739d440fc0bccf4d321"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:06b60f91bfa5514bb689b500a25ba48e897d18fea14dce14b48a0c40d1635893"},
|
||||
{file = "ruff-0.4.9-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:88bffe9c6a454bf8529f9ab9091c99490578a593cc9f9822b7fc065ee0712a06"},
|
||||
{file = "ruff-0.4.9-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:673bddb893f21ab47a8334c8e0ea7fd6598ecc8e698da75bcd12a7b9d0a3206e"},
|
||||
{file = "ruff-0.4.9-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:8c1aff58c31948cc66d0b22951aa19edb5af0a3af40c936340cd32a8b1ab7438"},
|
||||
{file = "ruff-0.4.9-py3-none-musllinux_1_2_i686.whl", hash = "sha256:784d3ec9bd6493c3b720a0b76f741e6c2d7d44f6b2be87f5eef1ae8cc1d54c84"},
|
||||
{file = "ruff-0.4.9-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:732dd550bfa5d85af8c3c6cbc47ba5b67c6aed8a89e2f011b908fc88f87649db"},
|
||||
{file = "ruff-0.4.9-py3-none-win32.whl", hash = "sha256:8064590fd1a50dcf4909c268b0e7c2498253273309ad3d97e4a752bb9df4f521"},
|
||||
{file = "ruff-0.4.9-py3-none-win_amd64.whl", hash = "sha256:e0a22c4157e53d006530c902107c7f550b9233e9706313ab57b892d7197d8e52"},
|
||||
{file = "ruff-0.4.9-py3-none-win_arm64.whl", hash = "sha256:5d5460f789ccf4efd43f265a58538a2c24dbce15dbf560676e430375f20a8198"},
|
||||
{file = "ruff-0.4.9.tar.gz", hash = "sha256:f1cb0828ac9533ba0135d148d214e284711ede33640465e706772645483427e3"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -3927,33 +3928,33 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "tornado"
|
||||
version = "6.4"
|
||||
version = "6.4.1"
|
||||
description = "Tornado is a Python web framework and asynchronous networking library, originally developed at FriendFeed."
|
||||
optional = false
|
||||
python-versions = ">= 3.8"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "tornado-6.4-cp38-abi3-macosx_10_9_universal2.whl", hash = "sha256:02ccefc7d8211e5a7f9e8bc3f9e5b0ad6262ba2fbb683a6443ecc804e5224ce0"},
|
||||
{file = "tornado-6.4-cp38-abi3-macosx_10_9_x86_64.whl", hash = "sha256:27787de946a9cffd63ce5814c33f734c627a87072ec7eed71f7fc4417bb16263"},
|
||||
{file = "tornado-6.4-cp38-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f7894c581ecdcf91666a0912f18ce5e757213999e183ebfc2c3fdbf4d5bd764e"},
|
||||
{file = "tornado-6.4-cp38-abi3-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:e43bc2e5370a6a8e413e1e1cd0c91bedc5bd62a74a532371042a18ef19e10579"},
|
||||
{file = "tornado-6.4-cp38-abi3-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f0251554cdd50b4b44362f73ad5ba7126fc5b2c2895cc62b14a1c2d7ea32f212"},
|
||||
{file = "tornado-6.4-cp38-abi3-musllinux_1_1_aarch64.whl", hash = "sha256:fd03192e287fbd0899dd8f81c6fb9cbbc69194d2074b38f384cb6fa72b80e9c2"},
|
||||
{file = "tornado-6.4-cp38-abi3-musllinux_1_1_i686.whl", hash = "sha256:88b84956273fbd73420e6d4b8d5ccbe913c65d31351b4c004ae362eba06e1f78"},
|
||||
{file = "tornado-6.4-cp38-abi3-musllinux_1_1_x86_64.whl", hash = "sha256:71ddfc23a0e03ef2df1c1397d859868d158c8276a0603b96cf86892bff58149f"},
|
||||
{file = "tornado-6.4-cp38-abi3-win32.whl", hash = "sha256:6f8a6c77900f5ae93d8b4ae1196472d0ccc2775cc1dfdc9e7727889145c45052"},
|
||||
{file = "tornado-6.4-cp38-abi3-win_amd64.whl", hash = "sha256:10aeaa8006333433da48dec9fe417877f8bcc21f48dda8d661ae79da357b2a63"},
|
||||
{file = "tornado-6.4.tar.gz", hash = "sha256:72291fa6e6bc84e626589f1c29d90a5a6d593ef5ae68052ee2ef000dfd273dee"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-macosx_10_9_universal2.whl", hash = "sha256:163b0aafc8e23d8cdc3c9dfb24c5368af84a81e3364745ccb4427669bf84aec8"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-macosx_10_9_x86_64.whl", hash = "sha256:6d5ce3437e18a2b66fbadb183c1d3364fb03f2be71299e7d10dbeeb69f4b2a14"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:e2e20b9113cd7293f164dc46fffb13535266e713cdb87bd2d15ddb336e96cfc4"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:8ae50a504a740365267b2a8d1a90c9fbc86b780a39170feca9bcc1787ff80842"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:613bf4ddf5c7a95509218b149b555621497a6cc0d46ac341b30bd9ec19eac7f3"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-musllinux_1_2_aarch64.whl", hash = "sha256:25486eb223babe3eed4b8aecbac33b37e3dd6d776bc730ca14e1bf93888b979f"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-musllinux_1_2_i686.whl", hash = "sha256:454db8a7ecfcf2ff6042dde58404164d969b6f5d58b926da15e6b23817950fc4"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-musllinux_1_2_x86_64.whl", hash = "sha256:a02a08cc7a9314b006f653ce40483b9b3c12cda222d6a46d4ac63bb6c9057698"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-win32.whl", hash = "sha256:d9a566c40b89757c9aa8e6f032bcdb8ca8795d7c1a9762910c722b1635c9de4d"},
|
||||
{file = "tornado-6.4.1-cp38-abi3-win_amd64.whl", hash = "sha256:b24b8982ed444378d7f21d563f4180a2de31ced9d8d84443907a0a64da2072e7"},
|
||||
{file = "tornado-6.4.1.tar.gz", hash = "sha256:92d3ab53183d8c50f8204a51e6f91d18a15d5ef261e84d452800d4ff6fc504e9"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "tox"
|
||||
version = "4.15.0"
|
||||
version = "4.15.1"
|
||||
description = "tox is a generic virtualenv management and test command line tool"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "tox-4.15.0-py3-none-any.whl", hash = "sha256:300055f335d855b2ab1b12c5802de7f62a36d4fd53f30bd2835f6a201dda46ea"},
|
||||
{file = "tox-4.15.0.tar.gz", hash = "sha256:7a0beeef166fbe566f54f795b4906c31b428eddafc0102ac00d20998dd1933f6"},
|
||||
{file = "tox-4.15.1-py3-none-any.whl", hash = "sha256:f00a5dc4222b358e69694e47e3da0227ac41253509bca9f45aa8f012053e8d9d"},
|
||||
{file = "tox-4.15.1.tar.gz", hash = "sha256:53a092527d65e873e39213ebd4bd027a64623320b6b0326136384213f95b7076"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -4067,13 +4068,13 @@ dev = ["flake8", "flake8-annotations", "flake8-bandit", "flake8-bugbear", "flake
|
||||
|
||||
[[package]]
|
||||
name = "urllib3"
|
||||
version = "2.2.1"
|
||||
version = "2.2.2"
|
||||
description = "HTTP library with thread-safe connection pooling, file post, and more."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "urllib3-2.2.1-py3-none-any.whl", hash = "sha256:450b20ec296a467077128bff42b73080516e71b56ff59a60a02bef2232c4fa9d"},
|
||||
{file = "urllib3-2.2.1.tar.gz", hash = "sha256:d0570876c61ab9e520d776c38acbbb5b05a776d3f9ff98a5c8fd5162a444cf19"},
|
||||
{file = "urllib3-2.2.2-py3-none-any.whl", hash = "sha256:a448b2f64d686155468037e1ace9f2d2199776e17f0a46610480d311f73e3472"},
|
||||
{file = "urllib3-2.2.2.tar.gz", hash = "sha256:dd505485549a7a552833da5e6063639d0d177c04f23bc3864e41e5dc5f612168"},
|
||||
]
|
||||
|
||||
[package.extras]
|
||||
@@ -4226,13 +4227,13 @@ test = ["pytest (>=6.0.0)", "setuptools (>=65)"]
|
||||
|
||||
[[package]]
|
||||
name = "widgetsnbextension"
|
||||
version = "4.0.10"
|
||||
version = "4.0.11"
|
||||
description = "Jupyter interactive widgets for Jupyter Notebook"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "widgetsnbextension-4.0.10-py3-none-any.whl", hash = "sha256:d37c3724ec32d8c48400a435ecfa7d3e259995201fbefa37163124a9fcb393cc"},
|
||||
{file = "widgetsnbextension-4.0.10.tar.gz", hash = "sha256:64196c5ff3b9a9183a8e699a4227fb0b7002f252c814098e66c4d1cd0644688f"},
|
||||
{file = "widgetsnbextension-4.0.11-py3-none-any.whl", hash = "sha256:55d4d6949d100e0d08b94948a42efc3ed6dfdc0e9468b2c4b128c9a2ce3a7a36"},
|
||||
{file = "widgetsnbextension-4.0.11.tar.gz", hash = "sha256:8b22a8f1910bfd188e596fe7fc05dcbd87e810c8a4ba010bdb3da86637398474"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -4257,4 +4258,4 @@ desktop = ["opencv-python"]
|
||||
[metadata]
|
||||
lock-version = "2.0"
|
||||
python-versions = "^3.8"
|
||||
content-hash = "29af5aa06f97e77a2dba94c5a6d77d7d1903448724df07416026a378d3c6a64d"
|
||||
content-hash = "19649609326e741c97bf1b32b28dc5dee72e18d9ce2a53c554980c81e0fe49a9"
|
||||
+3
-3
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.21.0rc5"
|
||||
version = "0.21.0"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -32,7 +32,7 @@ classifiers=[
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
python = "^3.8"
|
||||
numpy = ">=1.21.2"
|
||||
numpy = ">=1.21.2,<2.0.0"
|
||||
scipy = [
|
||||
{ version = "1.10.0", python = "<3.9" },
|
||||
{ version = "^1.10.0", python = ">=3.9" }
|
||||
@@ -42,7 +42,7 @@ pyyaml = ">=5.3"
|
||||
defusedxml = "^0.7.1"
|
||||
opencv-python = { version = ">=4.5.5.64", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64"
|
||||
requests = { version = ">=2.26.0,<=2.31.0", optional = true }
|
||||
requests = { version = ">=2.26.0,<=2.32.3", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.4", optional = true }
|
||||
pillow = ">=9.4"
|
||||
|
||||
|
||||
+10
-2
@@ -35,9 +35,17 @@ from supervision.dataset.core import (
|
||||
ClassificationDataset,
|
||||
DetectionDataset,
|
||||
)
|
||||
from supervision.dataset.utils import mask_to_rle, rle_to_mask
|
||||
from supervision.detection.annotate import BoxAnnotator
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.line_zone import LineZone, LineZoneAnnotator
|
||||
from supervision.detection.lmm import LMM
|
||||
from supervision.detection.overlap_filter import (
|
||||
OverlapFilter,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.json_sink import JSONSink
|
||||
@@ -45,12 +53,12 @@ from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnn
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
box_non_max_suppression,
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_polygons_by_area,
|
||||
mask_iou_batch,
|
||||
mask_non_max_suppression,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
|
||||
+23
-11
@@ -116,13 +116,12 @@ class DetectionDataset(BaseDataset):
|
||||
Tuple[DetectionDataset, DetectionDataset]: A tuple containing
|
||||
the training and testing datasets.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
train_ds, test_ds = ds.split(split_ratio=0.7,
|
||||
random_state=42, shuffle=True)
|
||||
train_ds, test_ds = ds.split(split_ratio=0.7, random_state=42, shuffle=True)
|
||||
len(train_ds), len(test_ds)
|
||||
# (700, 300)
|
||||
```
|
||||
@@ -229,7 +228,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance containing
|
||||
the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -289,7 +288,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance
|
||||
containing the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -395,7 +394,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance containing
|
||||
the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -435,6 +434,20 @@ class DetectionDataset(BaseDataset):
|
||||
Exports the dataset to COCO format. This method saves the
|
||||
images and their corresponding annotations in COCO format.
|
||||
|
||||
!!! tip
|
||||
|
||||
The format of the mask is determined automatically based on its structure:
|
||||
|
||||
- If a mask contains multiple disconnected components or holes, it will be
|
||||
saved using the Run-Length Encoding (RLE) format for efficient storage and
|
||||
processing.
|
||||
- If a mask consists of a single, contiguous region without any holes, it
|
||||
will be encoded as a polygon, preserving the outline of the object.
|
||||
|
||||
This automatic selection ensures that the masks are stored in the most
|
||||
appropriate and space-efficient format, complying with COCO dataset
|
||||
standards.
|
||||
|
||||
Args:
|
||||
images_directory_path (Optional[str]): The path to the directory
|
||||
where the images should be saved.
|
||||
@@ -486,7 +499,7 @@ class DetectionDataset(BaseDataset):
|
||||
(DetectionDataset): A single `DetectionDataset` object containing
|
||||
the merged data from the input list.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
@@ -571,13 +584,12 @@ class ClassificationDataset(BaseDataset):
|
||||
Tuple[ClassificationDataset, ClassificationDataset]: A tuple containing
|
||||
the training and testing datasets.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
cd = sv.ClassificationDataset(...)
|
||||
train_cd,test_cd = cd.split(split_ratio=0.7,
|
||||
random_state=42,shuffle=True)
|
||||
train_cd,test_cd = cd.split(split_ratio=0.7, random_state=42,shuffle=True)
|
||||
len(train_cd), len(test_cd)
|
||||
# (700, 300)
|
||||
```
|
||||
@@ -639,7 +651,7 @@ class ClassificationDataset(BaseDataset):
|
||||
Returns:
|
||||
ClassificationDataset: The dataset.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
|
||||
@@ -5,13 +5,20 @@ from typing import Dict, List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.dataset.utils import (
|
||||
approximate_mask_with_polygons,
|
||||
map_detections_class_id,
|
||||
mask_to_rle,
|
||||
rle_to_mask,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask
|
||||
from supervision.detection.utils import (
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
polygon_to_mask,
|
||||
)
|
||||
from supervision.utils.file import read_json_file, save_json_file
|
||||
|
||||
|
||||
@@ -57,13 +64,24 @@ def group_coco_annotations_by_image_id(
|
||||
return annotations
|
||||
|
||||
|
||||
def _polygons_to_masks(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
def coco_annotations_to_masks(
|
||||
image_annotations: List[dict], resolution_wh: Tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
return np.array(
|
||||
[
|
||||
polygon_to_mask(polygon=polygon, resolution_wh=resolution_wh)
|
||||
for polygon in polygons
|
||||
rle_to_mask(
|
||||
rle=np.array(image_annotation["segmentation"]["counts"]),
|
||||
resolution_wh=resolution_wh,
|
||||
)
|
||||
if image_annotation["iscrowd"]
|
||||
else polygon_to_mask(
|
||||
polygon=np.reshape(
|
||||
np.asarray(image_annotation["segmentation"], dtype=np.int32),
|
||||
(-1, 2),
|
||||
),
|
||||
resolution_wh=resolution_wh,
|
||||
)
|
||||
for image_annotation in image_annotations
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
@@ -83,13 +101,9 @@ def coco_annotations_to_detections(
|
||||
xyxy[:, 2:4] += xyxy[:, 0:2]
|
||||
|
||||
if with_masks:
|
||||
polygons = [
|
||||
np.reshape(
|
||||
np.asarray(image_annotation["segmentation"], dtype=np.int32), (-1, 2)
|
||||
)
|
||||
for image_annotation in image_annotations
|
||||
]
|
||||
mask = _polygons_to_masks(polygons=polygons, resolution_wh=resolution_wh)
|
||||
mask = coco_annotations_to_masks(
|
||||
image_annotations=image_annotations, resolution_wh=resolution_wh
|
||||
)
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask
|
||||
)
|
||||
@@ -108,24 +122,35 @@ def detections_to_coco_annotations(
|
||||
coco_annotations = []
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
polygon = []
|
||||
segmentation = []
|
||||
iscrowd = 0
|
||||
if mask is not None:
|
||||
polygon = list(
|
||||
approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)[0].flatten()
|
||||
)
|
||||
iscrowd = contains_holes(mask=mask) or contains_multiple_segments(mask=mask)
|
||||
|
||||
if iscrowd:
|
||||
segmentation = {
|
||||
"counts": mask_to_rle(mask=mask),
|
||||
"size": list(mask.shape[:2]),
|
||||
}
|
||||
else:
|
||||
segmentation = [
|
||||
list(
|
||||
approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)[0].flatten()
|
||||
)
|
||||
]
|
||||
coco_annotation = {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": int(class_id),
|
||||
"bbox": [xyxy[0], xyxy[1], box_width, box_height],
|
||||
"area": box_width * box_height,
|
||||
"segmentation": [polygon] if polygon else [],
|
||||
"iscrowd": 0,
|
||||
"segmentation": segmentation,
|
||||
"iscrowd": iscrowd,
|
||||
}
|
||||
coco_annotations.append(coco_annotation)
|
||||
annotation_id += 1
|
||||
|
||||
@@ -2,10 +2,11 @@ import copy
|
||||
import os
|
||||
import random
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
@@ -129,3 +130,123 @@ def train_test_split(
|
||||
|
||||
split_index = int(len(data) * train_ratio)
|
||||
return data[:split_index], data[split_index:]
|
||||
|
||||
|
||||
def rle_to_mask(
|
||||
rle: Union[npt.NDArray[np.int_], List[int]], resolution_wh: Tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Converts run-length encoding (RLE) to a binary mask.
|
||||
|
||||
Args:
|
||||
rle (Union[npt.NDArray[np.int_], List[int]]): The 1D RLE array, the format
|
||||
used in the COCO dataset (column-wise encoding, values of an array with
|
||||
even indices represent the number of pixels assigned as background,
|
||||
values of an array with odd indices represent the number of pixels
|
||||
assigned as foreground object).
|
||||
resolution_wh (Tuple[int, int]): The width (w) and height (h)
|
||||
of the desired binary mask.
|
||||
|
||||
Returns:
|
||||
The generated 2D Boolean mask of shape `(h, w)`, where the foreground object is
|
||||
marked with `True`'s and the rest is filled with `False`'s.
|
||||
|
||||
Raises:
|
||||
AssertionError: If the sum of pixels encoded in RLE differs from the
|
||||
number of pixels in the expected mask (computed based on resolution_wh).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.rle_to_mask([5, 2, 2, 2, 5], (4, 4))
|
||||
# array([
|
||||
# [False, False, False, False],
|
||||
# [False, True, True, False],
|
||||
# [False, True, True, False],
|
||||
# [False, False, False, False],
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
if isinstance(rle, list):
|
||||
rle = np.array(rle, dtype=int)
|
||||
|
||||
width, height = resolution_wh
|
||||
|
||||
assert width * height == np.sum(rle), (
|
||||
"the sum of the number of pixels in the RLE must be the same "
|
||||
"as the number of pixels in the expected mask"
|
||||
)
|
||||
|
||||
zero_one_values = np.zeros(shape=(rle.size, 1), dtype=np.uint8)
|
||||
zero_one_values[1::2] = 1
|
||||
|
||||
decoded_rle = np.repeat(zero_one_values, rle, axis=0)
|
||||
decoded_rle = np.append(
|
||||
decoded_rle, np.zeros(width * height - len(decoded_rle), dtype=np.uint8)
|
||||
)
|
||||
return decoded_rle.reshape((height, width), order="F")
|
||||
|
||||
|
||||
def mask_to_rle(mask: npt.NDArray[np.bool_]) -> List[int]:
|
||||
"""
|
||||
Converts a binary mask into a run-length encoding (RLE).
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
|
||||
Returns:
|
||||
The run-length encoded mask. Values of a list with even indices
|
||||
represent the number of pixels assigned as background (`False`), values
|
||||
of a list with odd indices represent the number of pixels assigned
|
||||
as foreground object (`True`).
|
||||
|
||||
Raises:
|
||||
AssertionError: If input mask is not 2D or is empty.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
])
|
||||
sv.mask_to_rle(mask)
|
||||
# [0, 16]
|
||||
|
||||
mask = np.array([
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
])
|
||||
sv.mask_to_rle(mask)
|
||||
# [5, 2, 2, 2, 5]
|
||||
```
|
||||
|
||||
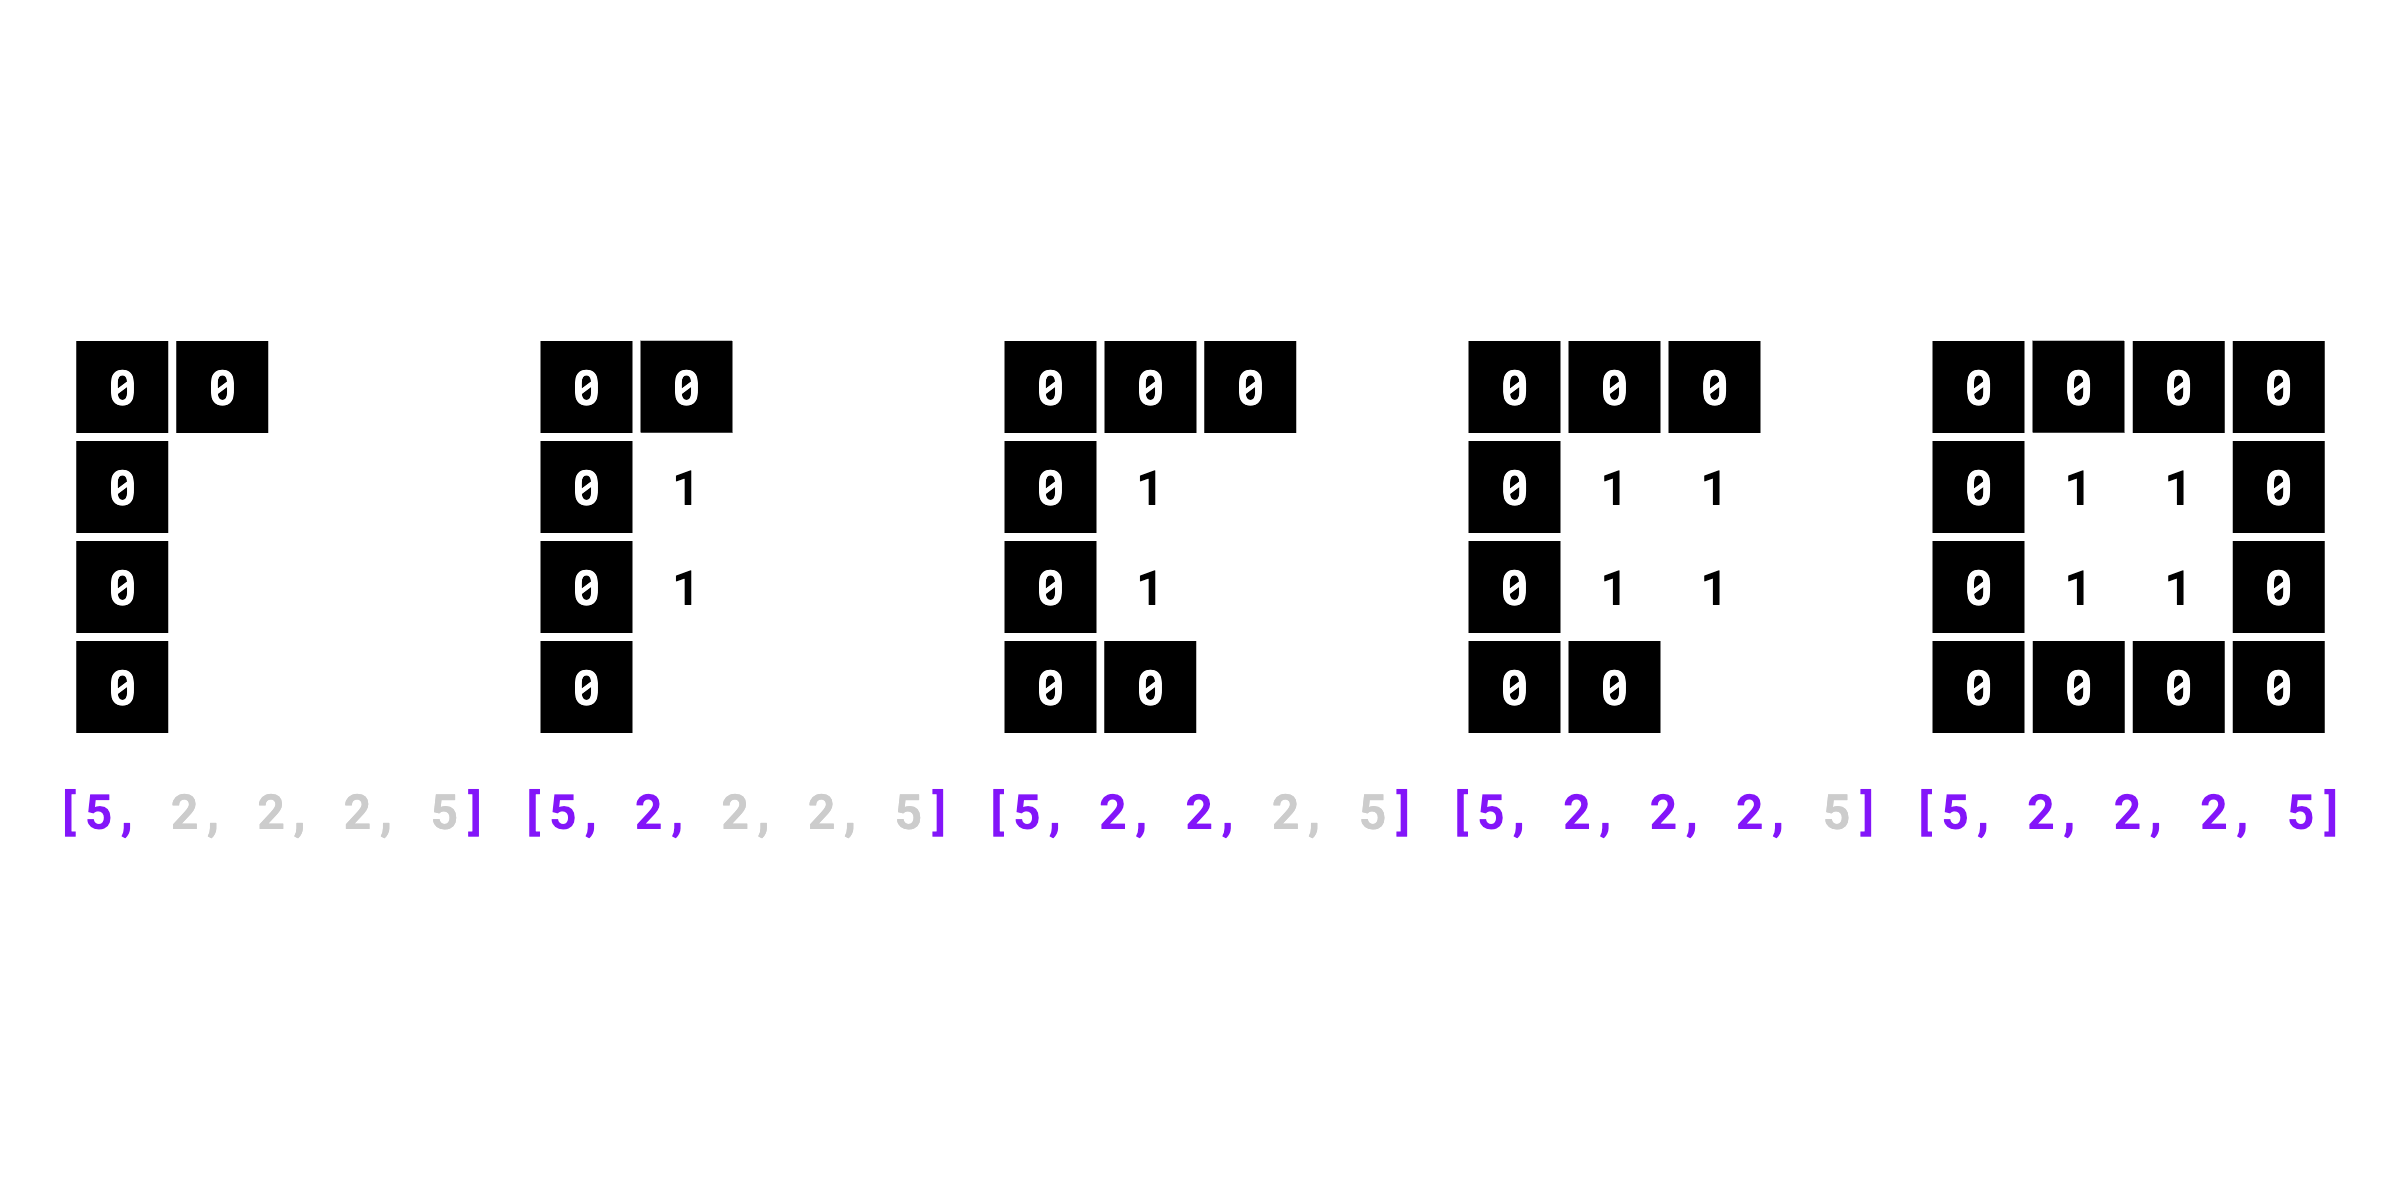{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
assert mask.ndim == 2, "Input mask must be 2D"
|
||||
assert mask.size != 0, "Input mask cannot be empty"
|
||||
|
||||
on_value_change_indices = np.where(
|
||||
mask.ravel(order="F") != np.roll(mask.ravel(order="F"), 1)
|
||||
)[0]
|
||||
|
||||
on_value_change_indices = np.append(on_value_change_indices, mask.size)
|
||||
# need to add 0 at the beginning when the same value is in the first and
|
||||
# last element of the flattened mask
|
||||
if on_value_change_indices[0] != 0:
|
||||
on_value_change_indices = np.insert(on_value_change_indices, 0, 0)
|
||||
|
||||
rle = np.diff(on_value_change_indices)
|
||||
|
||||
if mask[0][0] == 1:
|
||||
rle = np.insert(rle, 0, 0)
|
||||
|
||||
return list(rle)
|
||||
+270
-10
@@ -7,20 +7,25 @@ from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.utils import (
|
||||
from supervision.detection.lmm import LMM, from_paligemma, validate_lmm_and_kwargs
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
mask_non_max_suppression,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
process_roboflow_result,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.utils.internal import deprecated, get_instance_variables
|
||||
from supervision.validators import validate_detections_fields
|
||||
|
||||
|
||||
@@ -240,7 +245,7 @@ class Detections:
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if "obb" in ultralytics_results and ultralytics_results.obb is not None:
|
||||
if hasattr(ultralytics_results, "obb") and ultralytics_results.obb is not None:
|
||||
class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy()
|
||||
@@ -805,6 +810,52 @@ class Detections:
|
||||
class_id=paddledet_result["bbox"][:, 0].astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_lmm(cls, lmm: Union[LMM, str], result: str, **kwargs) -> Detections:
|
||||
"""
|
||||
Creates a Detections object from the given result string based on the specified
|
||||
Large Multimodal Model (LMM).
|
||||
|
||||
Args:
|
||||
lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use.
|
||||
result (str): The result string containing the detection data.
|
||||
**kwargs: Additional keyword arguments required by the specified LMM.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Raises:
|
||||
ValueError: If the LMM is invalid, required arguments are missing, or
|
||||
disallowed arguments are provided.
|
||||
ValueError: If the specified LMM is not supported.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
```
|
||||
"""
|
||||
lmm = validate_lmm_and_kwargs(lmm, kwargs)
|
||||
|
||||
if lmm == LMM.PALIGEMMA:
|
||||
xyxy, class_id, class_name = from_paligemma(result, **kwargs)
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
||||
|
||||
raise ValueError(f"Unsupported LMM: {lmm}")
|
||||
|
||||
@classmethod
|
||||
def empty(cls) -> Detections:
|
||||
"""
|
||||
@@ -827,6 +878,14 @@ class Detections:
|
||||
class_id=np.array([], dtype=int),
|
||||
)
|
||||
|
||||
def is_empty(self) -> bool:
|
||||
"""
|
||||
Returns `True` if the `Detections` object is considered empty.
|
||||
"""
|
||||
empty_detections = Detections.empty()
|
||||
empty_detections.data = self.data
|
||||
return self == empty_detections
|
||||
|
||||
@classmethod
|
||||
def merge(cls, detections_list: List[Detections]) -> Detections:
|
||||
"""
|
||||
@@ -839,6 +898,10 @@ class Detections:
|
||||
For example, if merging Detections with 3 and 4 detected objects, this method
|
||||
will return a Detections with 7 objects (7 entries in `xyxy`, `mask`, etc).
|
||||
|
||||
!!! Note
|
||||
|
||||
When merging, empty `Detections` objects are ignored.
|
||||
|
||||
Args:
|
||||
detections_list (List[Detections]): A list of Detections objects to merge.
|
||||
|
||||
@@ -877,6 +940,10 @@ class Detections:
|
||||
array([0.1, 0.2, 0.3])
|
||||
```
|
||||
"""
|
||||
detections_list = [
|
||||
detections for detections in detections_list if not detections.is_empty()
|
||||
]
|
||||
|
||||
if len(detections_list) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
@@ -895,12 +962,13 @@ class Detections:
|
||||
def stack_or_none(name: str):
|
||||
if all(d.__getattribute__(name) is None for d in detections_list):
|
||||
return None
|
||||
stack_list = [
|
||||
d.__getattribute__(name)
|
||||
for d in detections_list
|
||||
if d.__getattribute__(name) is not None
|
||||
]
|
||||
return np.vstack(stack_list) if name == "mask" else np.hstack(stack_list)
|
||||
if any(d.__getattribute__(name) is None for d in detections_list):
|
||||
raise ValueError(f"All or none of the '{name}' fields must be None")
|
||||
return (
|
||||
np.vstack([d.__getattribute__(name) for d in detections_list])
|
||||
if name == "mask"
|
||||
else np.hstack([d.__getattribute__(name) for d in detections_list])
|
||||
)
|
||||
|
||||
mask = stack_or_none("mask")
|
||||
confidence = stack_or_none("confidence")
|
||||
@@ -1150,3 +1218,195 @@ class Detections:
|
||||
)
|
||||
|
||||
return self[indices]
|
||||
|
||||
def with_nmm(
|
||||
self, threshold: float = 0.5, class_agnostic: bool = False
|
||||
) -> Detections:
|
||||
"""
|
||||
Perform non-maximum merging on the current set of object detections.
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum merging. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic
|
||||
non-maximum merging. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
after non-maximum merging.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `confidence` is None or `class_id` is None and
|
||||
class_agnostic is False.
|
||||
|
||||
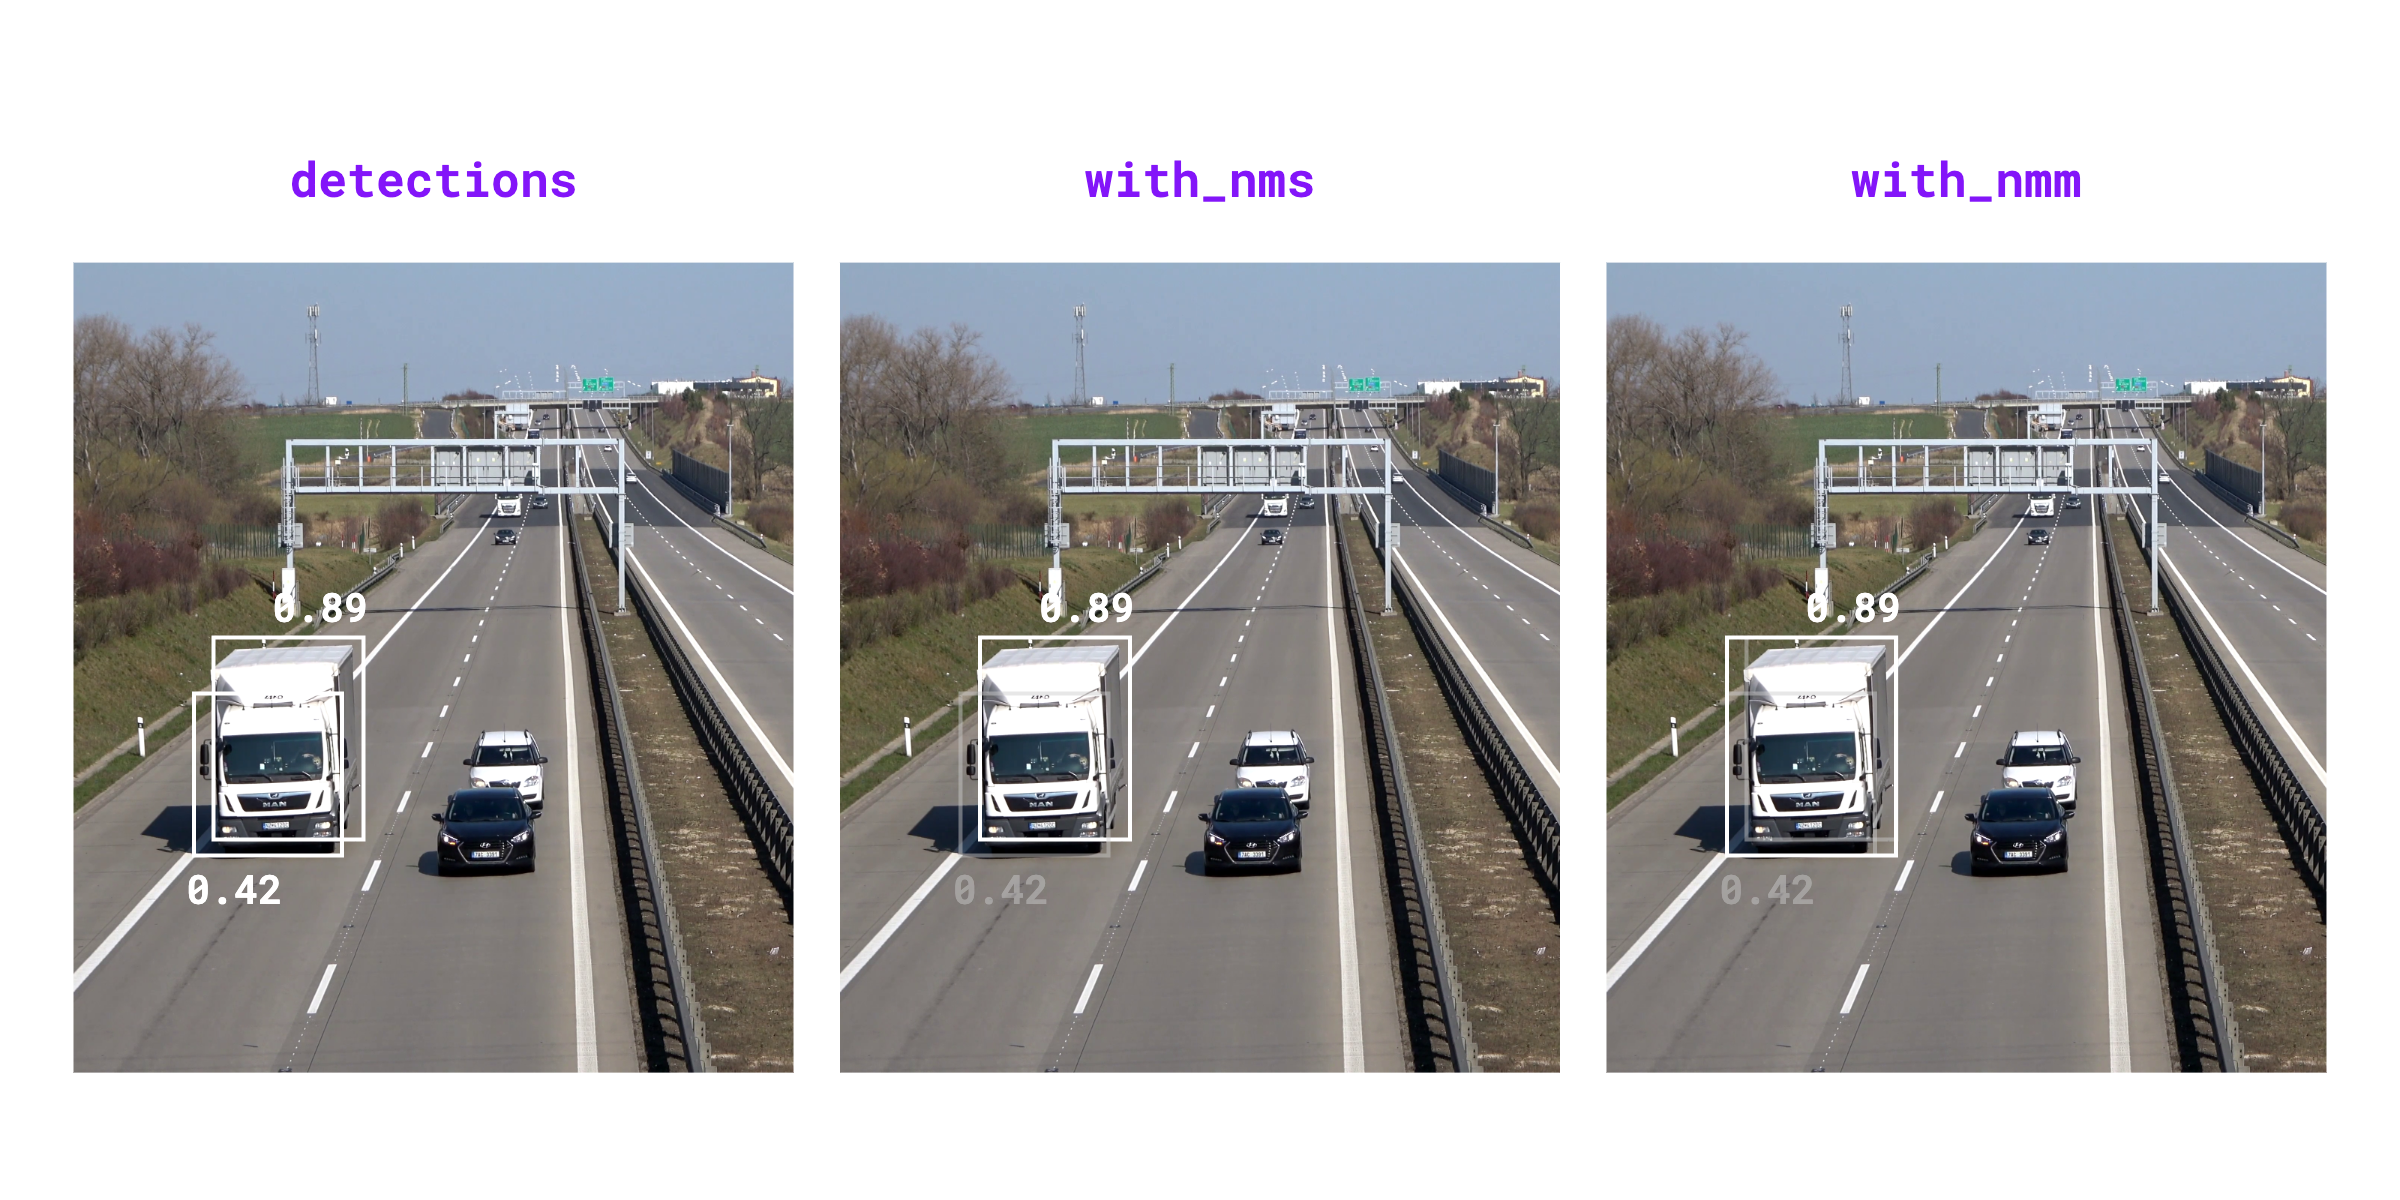{ align=center width="800" }
|
||||
""" # noqa: E501 // docs
|
||||
if len(self) == 0:
|
||||
return self
|
||||
|
||||
assert (
|
||||
self.confidence is not None
|
||||
), "Detections confidence must be given for NMM to be executed."
|
||||
|
||||
if class_agnostic:
|
||||
predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1)))
|
||||
else:
|
||||
assert self.class_id is not None, (
|
||||
"Detections class_id must be given for NMM to be executed. If you"
|
||||
" intended to perform class agnostic NMM set class_agnostic=True."
|
||||
)
|
||||
predictions = np.hstack(
|
||||
(
|
||||
self.xyxy,
|
||||
self.confidence.reshape(-1, 1),
|
||||
self.class_id.reshape(-1, 1),
|
||||
)
|
||||
)
|
||||
|
||||
merge_groups = box_non_max_merge(
|
||||
predictions=predictions, iou_threshold=threshold
|
||||
)
|
||||
|
||||
result = []
|
||||
for merge_group in merge_groups:
|
||||
unmerged_detections = [self[i] for i in merge_group]
|
||||
merged_detections = merge_inner_detections_objects(
|
||||
unmerged_detections, threshold
|
||||
)
|
||||
result.append(merged_detections)
|
||||
|
||||
return Detections.merge(result)
|
||||
|
||||
|
||||
def merge_inner_detection_object_pair(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> Detections:
|
||||
"""
|
||||
Merges two Detections object into a single Detections object.
|
||||
Assumes each Detections contains exactly one object.
|
||||
|
||||
A `winning` detection is determined based on the confidence score of the two
|
||||
input detections. This winning detection is then used to specify which
|
||||
`class_id`, `tracker_id`, and `data` to include in the merged Detections object.
|
||||
|
||||
The resulting `confidence` of the merged object is calculated by the weighted
|
||||
contribution of ea detection to the merged object.
|
||||
The bounding boxes and masks of the two input detections are merged into a
|
||||
single bounding box and mask, respectively.
|
||||
|
||||
Args:
|
||||
detections_1 (Detections):
|
||||
The first Detections object
|
||||
detections_2 (Detections):
|
||||
The second Detections object
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object, with merged attributes.
|
||||
|
||||
Raises:
|
||||
ValueError: If the input Detections objects do not have exactly 1 detected
|
||||
object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
merged_detections = merge_object_detection_pair(
|
||||
detections[0], detections[1])
|
||||
```
|
||||
"""
|
||||
if len(detections_1) != 1 or len(detections_2) != 1:
|
||||
raise ValueError("Both Detections should have exactly 1 detected object.")
|
||||
|
||||
validate_fields_both_defined_or_none(detections_1, detections_2)
|
||||
|
||||
xyxy_1 = detections_1.xyxy[0]
|
||||
xyxy_2 = detections_2.xyxy[0]
|
||||
if detections_1.confidence is None and detections_2.confidence is None:
|
||||
merged_confidence = None
|
||||
else:
|
||||
detection_1_area = (xyxy_1[2] - xyxy_1[0]) * (xyxy_1[3] - xyxy_1[1])
|
||||
detections_2_area = (xyxy_2[2] - xyxy_2[0]) * (xyxy_2[3] - xyxy_2[1])
|
||||
merged_confidence = (
|
||||
detection_1_area * detections_1.confidence[0]
|
||||
+ detections_2_area * detections_2.confidence[0]
|
||||
) / (detection_1_area + detections_2_area)
|
||||
merged_confidence = np.array([merged_confidence])
|
||||
|
||||
merged_x1, merged_y1 = np.minimum(xyxy_1[:2], xyxy_2[:2])
|
||||
merged_x2, merged_y2 = np.maximum(xyxy_1[2:], xyxy_2[2:])
|
||||
merged_xyxy = np.array([[merged_x1, merged_y1, merged_x2, merged_y2]])
|
||||
|
||||
if detections_1.mask is None and detections_2.mask is None:
|
||||
merged_mask = None
|
||||
else:
|
||||
merged_mask = np.logical_or(detections_1.mask, detections_2.mask)
|
||||
|
||||
if detections_1.confidence is None and detections_2.confidence is None:
|
||||
winning_detection = detections_1
|
||||
elif detections_1.confidence[0] >= detections_2.confidence[0]:
|
||||
winning_detection = detections_1
|
||||
else:
|
||||
winning_detection = detections_2
|
||||
|
||||
return Detections(
|
||||
xyxy=merged_xyxy,
|
||||
mask=merged_mask,
|
||||
confidence=merged_confidence,
|
||||
class_id=winning_detection.class_id,
|
||||
tracker_id=winning_detection.tracker_id,
|
||||
data=winning_detection.data,
|
||||
)
|
||||
|
||||
|
||||
def merge_inner_detections_objects(
|
||||
detections: List[Detections], threshold=0.5
|
||||
) -> Detections:
|
||||
"""
|
||||
Given N detections each of length 1 (exactly one object inside), combine them into a
|
||||
single detection object of length 1. The contained inner object will be the merged
|
||||
result of all the input detections.
|
||||
|
||||
For example, this lets you merge N boxes into one big box, N masks into one mask,
|
||||
etc.
|
||||
"""
|
||||
detections_1 = detections[0]
|
||||
for detections_2 in detections[1:]:
|
||||
box_iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy)[0]
|
||||
if box_iou < threshold:
|
||||
break
|
||||
detections_1 = merge_inner_detection_object_pair(detections_1, detections_2)
|
||||
return detections_1
|
||||
|
||||
|
||||
def validate_fields_both_defined_or_none(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> None:
|
||||
"""
|
||||
Verify that for each optional field in the Detections, both instances either have
|
||||
the field set to None or both have it set to non-None values.
|
||||
|
||||
`data` field is ignored.
|
||||
|
||||
Raises:
|
||||
ValueError: If one field is None and the other is not, for any of the fields.
|
||||
"""
|
||||
attributes = get_instance_variables(detections_1)
|
||||
for attribute in attributes:
|
||||
value_1 = getattr(detections_1, attribute)
|
||||
value_2 = getattr(detections_2, attribute)
|
||||
|
||||
if (value_1 is None) != (value_2 is None):
|
||||
raise ValueError(
|
||||
f"Field '{attribute}' should be consistently None or not None in both "
|
||||
"Detections."
|
||||
)
|
||||
@@ -1,12 +1,15 @@
|
||||
import warnings
|
||||
from typing import Dict, Iterable, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import cross_product
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_text
|
||||
from supervision.geometry.core import Point, Position, Vector
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
class LineZone:
|
||||
@@ -81,6 +84,8 @@ class LineZone:
|
||||
self.in_count: int = 0
|
||||
self.out_count: int = 0
|
||||
self.triggering_anchors = triggering_anchors
|
||||
if not list(self.triggering_anchors):
|
||||
raise ValueError("Triggering anchors cannot be empty.")
|
||||
|
||||
@staticmethod
|
||||
def calculate_region_of_interest_limits(vector: Vector) -> Tuple[Vector, Vector]:
|
||||
@@ -140,6 +145,15 @@ class LineZone:
|
||||
if len(detections) == 0:
|
||||
return crossed_in, crossed_out
|
||||
|
||||
if detections.tracker_id is None:
|
||||
warnings.warn(
|
||||
"Line zone counting skipped. LineZone requires tracker_id. Refer to "
|
||||
"https://supervision.roboflow.com/latest/trackers for more "
|
||||
"information.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
return crossed_in, crossed_out
|
||||
|
||||
all_anchors = np.array(
|
||||
[
|
||||
detections.get_anchors_coordinates(anchor)
|
||||
@@ -147,31 +161,23 @@ class LineZone:
|
||||
]
|
||||
)
|
||||
|
||||
cross_products_1 = cross_product(all_anchors, self.limits[0])
|
||||
cross_products_2 = cross_product(all_anchors, self.limits[1])
|
||||
in_limits = (cross_products_1 > 0) == (cross_products_2 > 0)
|
||||
in_limits = np.all(in_limits, axis=0)
|
||||
|
||||
triggers = cross_product(all_anchors, self.vector) < 0
|
||||
has_any_left_trigger = np.any(triggers, axis=0)
|
||||
has_any_right_trigger = np.any(~triggers, axis=0)
|
||||
is_uniformly_triggered = ~(has_any_left_trigger & has_any_right_trigger)
|
||||
for i, tracker_id in enumerate(detections.tracker_id):
|
||||
if tracker_id is None:
|
||||
if not in_limits[i]:
|
||||
continue
|
||||
|
||||
box_anchors = [Point(x=x, y=y) for x, y in all_anchors[:, i, :]]
|
||||
|
||||
in_limits = all(
|
||||
[
|
||||
self.is_point_in_limits(point=anchor, limits=self.limits)
|
||||
for anchor in box_anchors
|
||||
]
|
||||
)
|
||||
|
||||
if not in_limits:
|
||||
if not is_uniformly_triggered[i]:
|
||||
continue
|
||||
|
||||
triggers = [
|
||||
self.vector.cross_product(point=anchor) < 0 for anchor in box_anchors
|
||||
]
|
||||
|
||||
if len(set(triggers)) == 2:
|
||||
continue
|
||||
|
||||
tracker_state = triggers[0]
|
||||
|
||||
tracker_state = has_any_left_trigger[i]
|
||||
if tracker_id not in self.tracker_state:
|
||||
self.tracker_state[tracker_id] = tracker_state
|
||||
continue
|
||||
|
||||
@@ -0,0 +1,59 @@
|
||||
import re
|
||||
from enum import Enum
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
class LMM(Enum):
|
||||
PALIGEMMA = "paligemma"
|
||||
|
||||
|
||||
REQUIRED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh"]}
|
||||
|
||||
ALLOWED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh", "classes"]}
|
||||
|
||||
|
||||
def validate_lmm_and_kwargs(lmm: Union[LMM, str], kwargs: Dict[str, Any]) -> LMM:
|
||||
if isinstance(lmm, str):
|
||||
try:
|
||||
lmm = LMM(lmm.lower())
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid lmm value: {lmm}. Must be one of {[e.value for e in LMM]}"
|
||||
)
|
||||
|
||||
required_args = REQUIRED_ARGUMENTS.get(lmm, [])
|
||||
for arg in required_args:
|
||||
if arg not in kwargs:
|
||||
raise ValueError(f"Missing required argument: {arg}")
|
||||
|
||||
allowed_args = ALLOWED_ARGUMENTS.get(lmm, [])
|
||||
for arg in kwargs:
|
||||
if arg not in allowed_args:
|
||||
raise ValueError(f"Argument {arg} is not allowed for {lmm.name}")
|
||||
|
||||
return lmm
|
||||
|
||||
|
||||
def from_paligemma(
|
||||
result: str, resolution_wh: Tuple[int, int], classes: Optional[List[str]] = None
|
||||
) -> Tuple[np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
w, h = resolution_wh
|
||||
pattern = re.compile(
|
||||
r"(?<!<loc\d{4}>)<loc(\d{4})><loc(\d{4})><loc(\d{4})><loc(\d{4})> ([\w\s\-]+)"
|
||||
)
|
||||
matches = pattern.findall(result)
|
||||
matches = np.array(matches) if matches else np.empty((0, 5))
|
||||
|
||||
xyxy, class_name = matches[:, [1, 0, 3, 2]], matches[:, 4]
|
||||
xyxy = xyxy.astype(int) / 1024 * np.array([w, h, w, h])
|
||||
class_name = np.char.strip(class_name.astype(str))
|
||||
class_id = None
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name]).astype(bool)
|
||||
xyxy, class_name = xyxy[mask], class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
|
||||
return xyxy, class_id, class_name
|
||||
@@ -0,0 +1,263 @@
|
||||
from enum import Enum
|
||||
from typing import List, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils import box_iou_batch, mask_iou_batch
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
return resized_masks
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int, optional): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray, iou_threshold: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64], iou_threshold: float = 0.5
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: List[List[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(predictions[order][:, :4], merge_candidate[:, :4])
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx] + np.flip(order[above_threshold]).tolist()
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return group_overlapping_boxes(predictions, iou_threshold)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging "
|
||||
f"detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
|
||||
def validate_overlap_filter(
|
||||
strategy: Union[OverlapFilter, str],
|
||||
) -> OverlapFilter:
|
||||
if isinstance(strategy, str):
|
||||
try:
|
||||
strategy = OverlapFilter(strategy.lower())
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid strategy value: {strategy}. Must be one of "
|
||||
f"{[e.value for e in OverlapFilter]}"
|
||||
)
|
||||
return strategy
|
||||
@@ -1,11 +1,14 @@
|
||||
import warnings
|
||||
from concurrent.futures import ThreadPoolExecutor, as_completed
|
||||
from typing import Callable, Optional, Tuple
|
||||
from typing import Callable, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.overlap_filter import OverlapFilter, validate_overlap_filter
|
||||
from supervision.detection.utils import move_boxes, move_masks
|
||||
from supervision.utils.image import crop_image
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
def move_detections(
|
||||
@@ -50,8 +53,10 @@ class InferenceSlicer:
|
||||
`(width, height)`.
|
||||
overlap_ratio_wh (Tuple[float, float]): Overlap ratio between consecutive
|
||||
slices in the format `(width_ratio, height_ratio)`.
|
||||
iou_threshold (Optional[float]): Intersection over Union (IoU) threshold
|
||||
used for non-max suppression.
|
||||
overlap_filter_strategy (Union[OverlapFilter, str]): Strategy for
|
||||
filtering or merging overlapping detections in slices.
|
||||
iou_threshold (float): Intersection over Union (IoU) threshold
|
||||
used when filtering by overlap.
|
||||
callback (Callable): A function that performs inference on a given image
|
||||
slice and returns detections.
|
||||
thread_workers (int): Number of threads for parallel execution.
|
||||
@@ -68,12 +73,18 @@ class InferenceSlicer:
|
||||
callback: Callable[[np.ndarray], Detections],
|
||||
slice_wh: Tuple[int, int] = (320, 320),
|
||||
overlap_ratio_wh: Tuple[float, float] = (0.2, 0.2),
|
||||
iou_threshold: Optional[float] = 0.5,
|
||||
overlap_filter_strategy: Union[
|
||||
OverlapFilter, str
|
||||
] = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
iou_threshold: float = 0.5,
|
||||
thread_workers: int = 1,
|
||||
):
|
||||
overlap_filter_strategy = validate_overlap_filter(overlap_filter_strategy)
|
||||
|
||||
self.slice_wh = slice_wh
|
||||
self.overlap_ratio_wh = overlap_ratio_wh
|
||||
self.iou_threshold = iou_threshold
|
||||
self.overlap_filter_strategy = overlap_filter_strategy
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
|
||||
@@ -104,7 +115,10 @@ class InferenceSlicer:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
slicer = sv.InferenceSlicer(
|
||||
callback=callback,
|
||||
overlap_filter_strategy=sv.OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
)
|
||||
|
||||
detections = slicer(image)
|
||||
```
|
||||
@@ -124,9 +138,19 @@ class InferenceSlicer:
|
||||
for future in as_completed(futures):
|
||||
detections_list.append(future.result())
|
||||
|
||||
return Detections.merge(detections_list=detections_list).with_nms(
|
||||
threshold=self.iou_threshold
|
||||
)
|
||||
merged = Detections.merge(detections_list=detections_list)
|
||||
if self.overlap_filter_strategy == OverlapFilter.NONE:
|
||||
return merged
|
||||
elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_SUPPRESSION:
|
||||
return merged.with_nms(threshold=self.iou_threshold)
|
||||
elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_MERGE:
|
||||
return merged.with_nmm(threshold=self.iou_threshold)
|
||||
else:
|
||||
warnings.warn(
|
||||
f"Invalid overlap filter strategy: {self.overlap_filter_strategy}",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
return merged
|
||||
|
||||
def _run_callback(self, image, offset) -> Detections:
|
||||
"""
|
||||
|
||||
@@ -54,6 +54,8 @@ class PolygonZone:
|
||||
|
||||
self.polygon = polygon.astype(int)
|
||||
self.triggering_anchors = triggering_anchors
|
||||
if not list(self.triggering_anchors):
|
||||
raise ValueError("Triggering anchors cannot be empty.")
|
||||
|
||||
self.current_count = 0
|
||||
|
||||
|
||||
@@ -1,3 +1,4 @@
|
||||
import warnings
|
||||
from collections import defaultdict, deque
|
||||
from copy import deepcopy
|
||||
from typing import Optional
|
||||
@@ -5,6 +6,7 @@ from typing import Optional
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
class DetectionsSmoother:
|
||||
@@ -70,16 +72,16 @@ class DetectionsSmoother:
|
||||
"""
|
||||
|
||||
if detections.tracker_id is None:
|
||||
print(
|
||||
warnings.warn(
|
||||
"Smoothing skipped. DetectionsSmoother requires tracker_id. Refer to "
|
||||
"https://supervision.roboflow.com/latest/trackers for more information."
|
||||
"https://supervision.roboflow.com/latest/trackers for more "
|
||||
"information.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
return detections
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
tracker_id = detections.tracker_id[detection_idx]
|
||||
if tracker_id is None:
|
||||
continue
|
||||
|
||||
self.tracks[tracker_id].append(detections[detection_idx])
|
||||
|
||||
|
||||
+228
-191
@@ -3,8 +3,10 @@ from typing import Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.geometry.core import Vector
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
@@ -56,7 +58,9 @@ def box_iou_batch(boxes_true: np.ndarray, boxes_detection: np.ndarray) -> np.nda
|
||||
bottom_right = np.minimum(boxes_true[:, None, 2:], boxes_detection[:, 2:])
|
||||
|
||||
area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2)
|
||||
return area_inter / (area_true[:, None] + area_detection - area_inter)
|
||||
ious = area_inter / (area_true[:, None] + area_detection - area_inter)
|
||||
ious = np.nan_to_num(ious)
|
||||
return ious
|
||||
|
||||
|
||||
def _mask_iou_batch_split(
|
||||
@@ -136,144 +140,6 @@ def mask_iou_batch(
|
||||
return np.vstack(ious)
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
return resized_masks
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int, optional): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray, iou_threshold: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Clips bounding boxes coordinates to fit within the frame resolution.
|
||||
@@ -289,6 +155,25 @@ def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box with coordinates clipped to fit
|
||||
within the frame resolution.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 300, 200],
|
||||
[15, 25, 350, 450],
|
||||
[-10, -20, 30, 40]
|
||||
])
|
||||
|
||||
sv.clip_boxes(xyxy=xyxy, resolution_wh=(320, 240))
|
||||
# array([
|
||||
# [ 10, 20, 300, 200],
|
||||
# [ 15, 25, 320, 240],
|
||||
# [ 0, 0, 30, 40]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
result = np.copy(xyxy)
|
||||
width, height = resolution_wh
|
||||
@@ -315,6 +200,23 @@ def pad_boxes(xyxy: np.ndarray, px: int, py: Optional[int] = None) -> np.ndarray
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a
|
||||
bounding box with coordinates padded according to the provided padding
|
||||
values.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 30, 40],
|
||||
[15, 25, 35, 45]
|
||||
])
|
||||
|
||||
sv.pad_boxes(xyxy=xyxy, px=5, py=10)
|
||||
# array([
|
||||
# [ 5, 10, 35, 50],
|
||||
# [10, 15, 40, 55]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
if py is None:
|
||||
py = px
|
||||
@@ -346,7 +248,7 @@ def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
`(x_min, y_min, x_max, y_max)` for each mask
|
||||
"""
|
||||
n = masks.shape[0]
|
||||
bboxes = np.zeros((n, 4), dtype=int)
|
||||
xyxy = np.zeros((n, 4), dtype=int)
|
||||
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
@@ -354,9 +256,9 @@ def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
x_min, x_max = np.min(cols), np.max(cols)
|
||||
y_min, y_max = np.min(rows), np.max(rows)
|
||||
bboxes[i, :] = [x_min, y_min, x_max, y_max]
|
||||
xyxy[i, :] = [x_min, y_min, x_max, y_max]
|
||||
|
||||
return bboxes
|
||||
return xyxy
|
||||
|
||||
|
||||
def mask_to_polygons(mask: np.ndarray) -> List[np.ndarray]:
|
||||
@@ -592,29 +494,34 @@ def process_roboflow_result(
|
||||
return xyxy, confidence, class_id, masks, tracker_id, data
|
||||
|
||||
|
||||
def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
def move_boxes(
|
||||
xyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes
|
||||
coordinates in format `[x1, y1, x2, y2]`
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Repositioned bounding boxes.
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
moved_box = sv.move_boxes(boxes, offset)
|
||||
print(moved_box)
|
||||
# np.array([
|
||||
|
||||
sv.move_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [15, 15, 25, 25],
|
||||
# [35, 35, 45, 45]
|
||||
# [35, 35, 45, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
@@ -622,24 +529,25 @@ def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
|
||||
|
||||
def move_masks(
|
||||
masks: np.ndarray,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: Tuple[int, int] = None,
|
||||
) -> np.ndarray:
|
||||
masks: npt.NDArray[np.bool_],
|
||||
offset: npt.NDArray[np.int32],
|
||||
resolution_wh: Tuple[int, int],
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Offset the masks in an array by the specified (x, y) amount.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
offset (np.ndarray): An array of shape `(2,)` containing non-negative int values
|
||||
`[dx, dy]`.
|
||||
masks (npt.NDArray[np.bool_]): A 3D array of binary masks corresponding to the
|
||||
predictions. Shape: `(N, H, W)`, where N is the number of predictions, and
|
||||
H, W are the dimensions of each mask.
|
||||
offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing non-negative
|
||||
int values `[dx, dy]`.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution.
|
||||
|
||||
Returns:
|
||||
(np.ndarray) repositioned masks, optionally padded to the specified shape.
|
||||
(npt.NDArray[np.bool_]) repositioned masks, optionally padded to the specified
|
||||
shape.
|
||||
"""
|
||||
|
||||
if offset[0] < 0 or offset[1] < 0:
|
||||
@@ -655,30 +563,34 @@ def move_masks(
|
||||
return mask_array
|
||||
|
||||
|
||||
def scale_boxes(xyxy: np.ndarray, factor: float) -> np.ndarray:
|
||||
def scale_boxes(
|
||||
xyxy: npt.NDArray[np.float64], factor: float
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Scale the dimensions of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes
|
||||
coordinates in format `[x1, y1, x2, y2]`
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
factor (float): A float value representing the factor by which the box
|
||||
dimensions are scaled. A factor greater than 1 enlarges the boxes, while a
|
||||
factor less than 1 shrinks them.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Scaled bounding boxes.
|
||||
npt.NDArray[np.float64]: Scaled bounding boxes.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
factor = 1.5
|
||||
scaled_bb = sv.scale_boxes(boxes, factor)
|
||||
print(scaled_bb)
|
||||
# np.array([
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
|
||||
sv.scale_boxes(xyxy=xyxy, factor=1.5)
|
||||
# array([
|
||||
# [ 7.5, 7.5, 22.5, 22.5],
|
||||
# [27.5, 27.5, 42.5, 42.5]
|
||||
# ])
|
||||
@@ -735,19 +647,19 @@ def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray])
|
||||
|
||||
|
||||
def merge_data(
|
||||
data_list: List[Dict[str, Union[np.ndarray, List]]],
|
||||
) -> Dict[str, Union[np.ndarray, List]]:
|
||||
data_list: List[Dict[str, Union[npt.NDArray[np.generic], List]]],
|
||||
) -> Dict[str, Union[npt.NDArray[np.generic], List]]:
|
||||
"""
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the Detections instances. Each data payload
|
||||
is a dictionary with the same keys, and the values are either lists or
|
||||
np.ndarray.
|
||||
npt.NDArray[np.generic].
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
types (list or np.ndarray).
|
||||
types (list or npt.NDArray[np.generic]).
|
||||
|
||||
Raises:
|
||||
ValueError: If data values within a single object have different lengths or if
|
||||
@@ -756,6 +668,10 @@ def merge_data(
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
@@ -763,21 +679,7 @@ def merge_data(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
keys_by_data = [set(data.keys()) for data in data_list]
|
||||
keys_by_data = [keys for keys in keys_by_data if len(keys) > 0]
|
||||
if not keys_by_data:
|
||||
return {}
|
||||
|
||||
common_keys = set.intersection(*keys_by_data)
|
||||
all_keys = set.union(*keys_by_data)
|
||||
if common_keys != all_keys:
|
||||
raise ValueError(
|
||||
f"All sv.Detections.data dictionaries must have the same keys. Common "
|
||||
f"keys: {common_keys}, but some dictionaries have additional keys: "
|
||||
f"{all_keys.difference(common_keys)}."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys}
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
for data in data_list:
|
||||
for key in data:
|
||||
merged_data[key].append(data[key])
|
||||
@@ -840,3 +742,138 @@ def get_data_item(
|
||||
raise TypeError(f"Unsupported data type for key '{key}': {type(value)}")
|
||||
|
||||
return subset_data
|
||||
|
||||
|
||||
def contains_holes(mask: npt.NDArray[np.bool_]) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains holes (background pixels fully enclosed by
|
||||
foreground pixels).
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
|
||||
Returns:
|
||||
True if holes are detected, False otherwise.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 0, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# False
|
||||
```
|
||||
|
||||
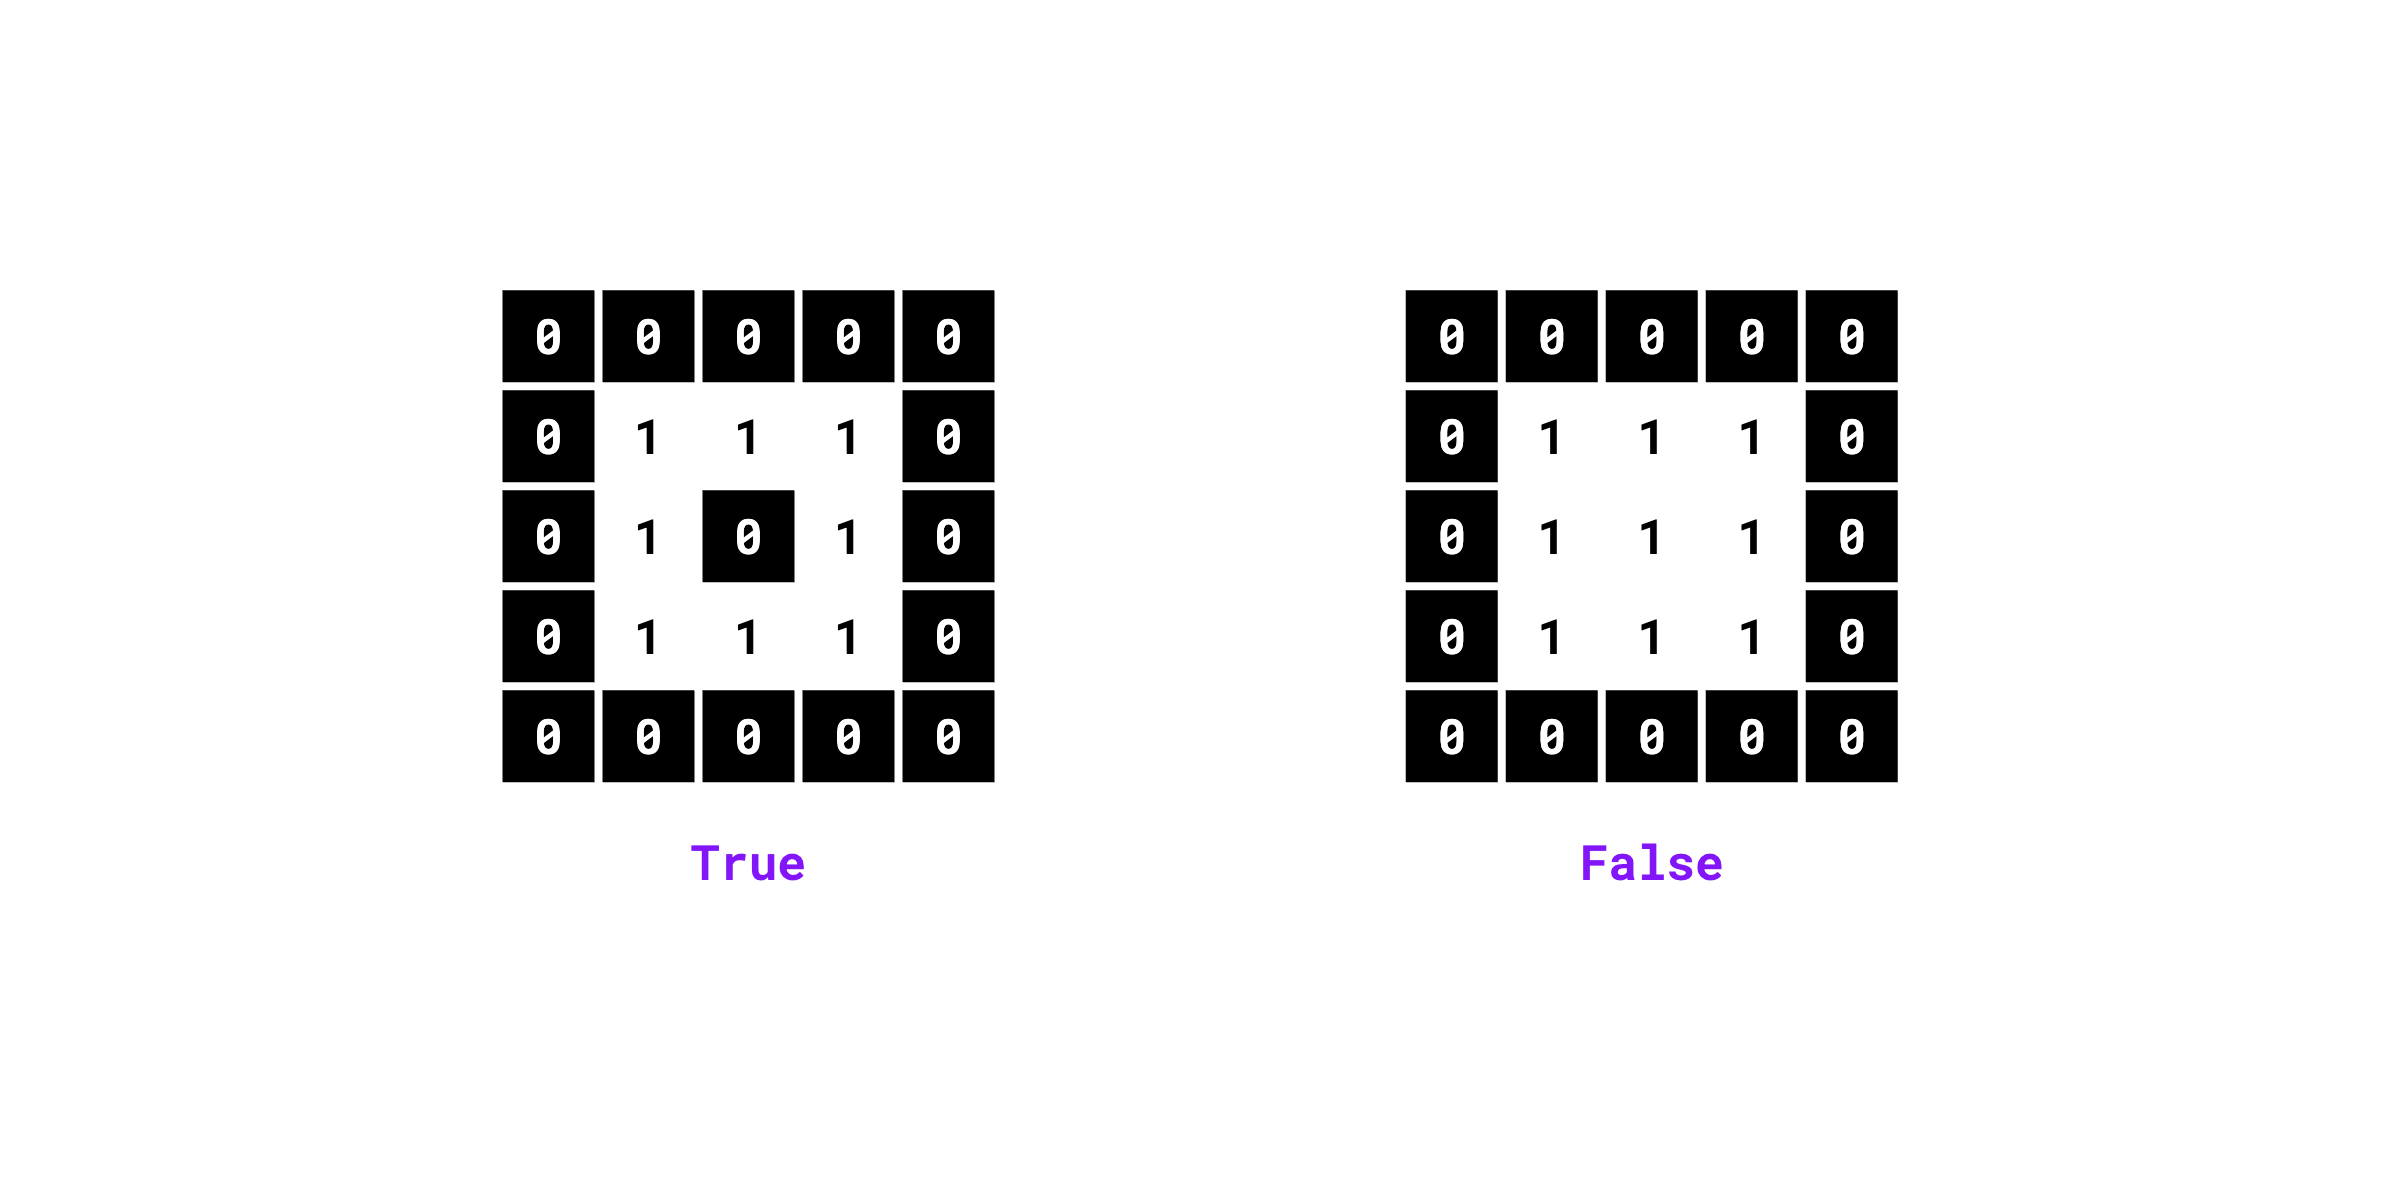{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
_, hierarchy = cv2.findContours(mask_uint8, cv2.RETR_CCOMP, cv2.CHAIN_APPROX_SIMPLE)
|
||||
|
||||
if hierarchy is not None:
|
||||
parent_contour_index = 3
|
||||
for h in hierarchy[0]:
|
||||
if h[parent_contour_index] != -1:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def contains_multiple_segments(
|
||||
mask: npt.NDArray[np.bool_], connectivity: int = 4
|
||||
) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains multiple unconnected foreground segments.
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
connectivity (int) : Default: 4 is 4-way connectivity, which means that
|
||||
foreground pixels are the part of the same segment/component
|
||||
if their edges touch.
|
||||
Alternatively: 8 for 8-way connectivity, when foreground pixels are
|
||||
connected by their edges or corners touch.
|
||||
|
||||
Returns:
|
||||
True when the mask contains multiple not connected components, False otherwise.
|
||||
|
||||
Raises:
|
||||
ValueError: If connectivity(int) parameter value is not 4 or 8.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# False
|
||||
```
|
||||
|
||||
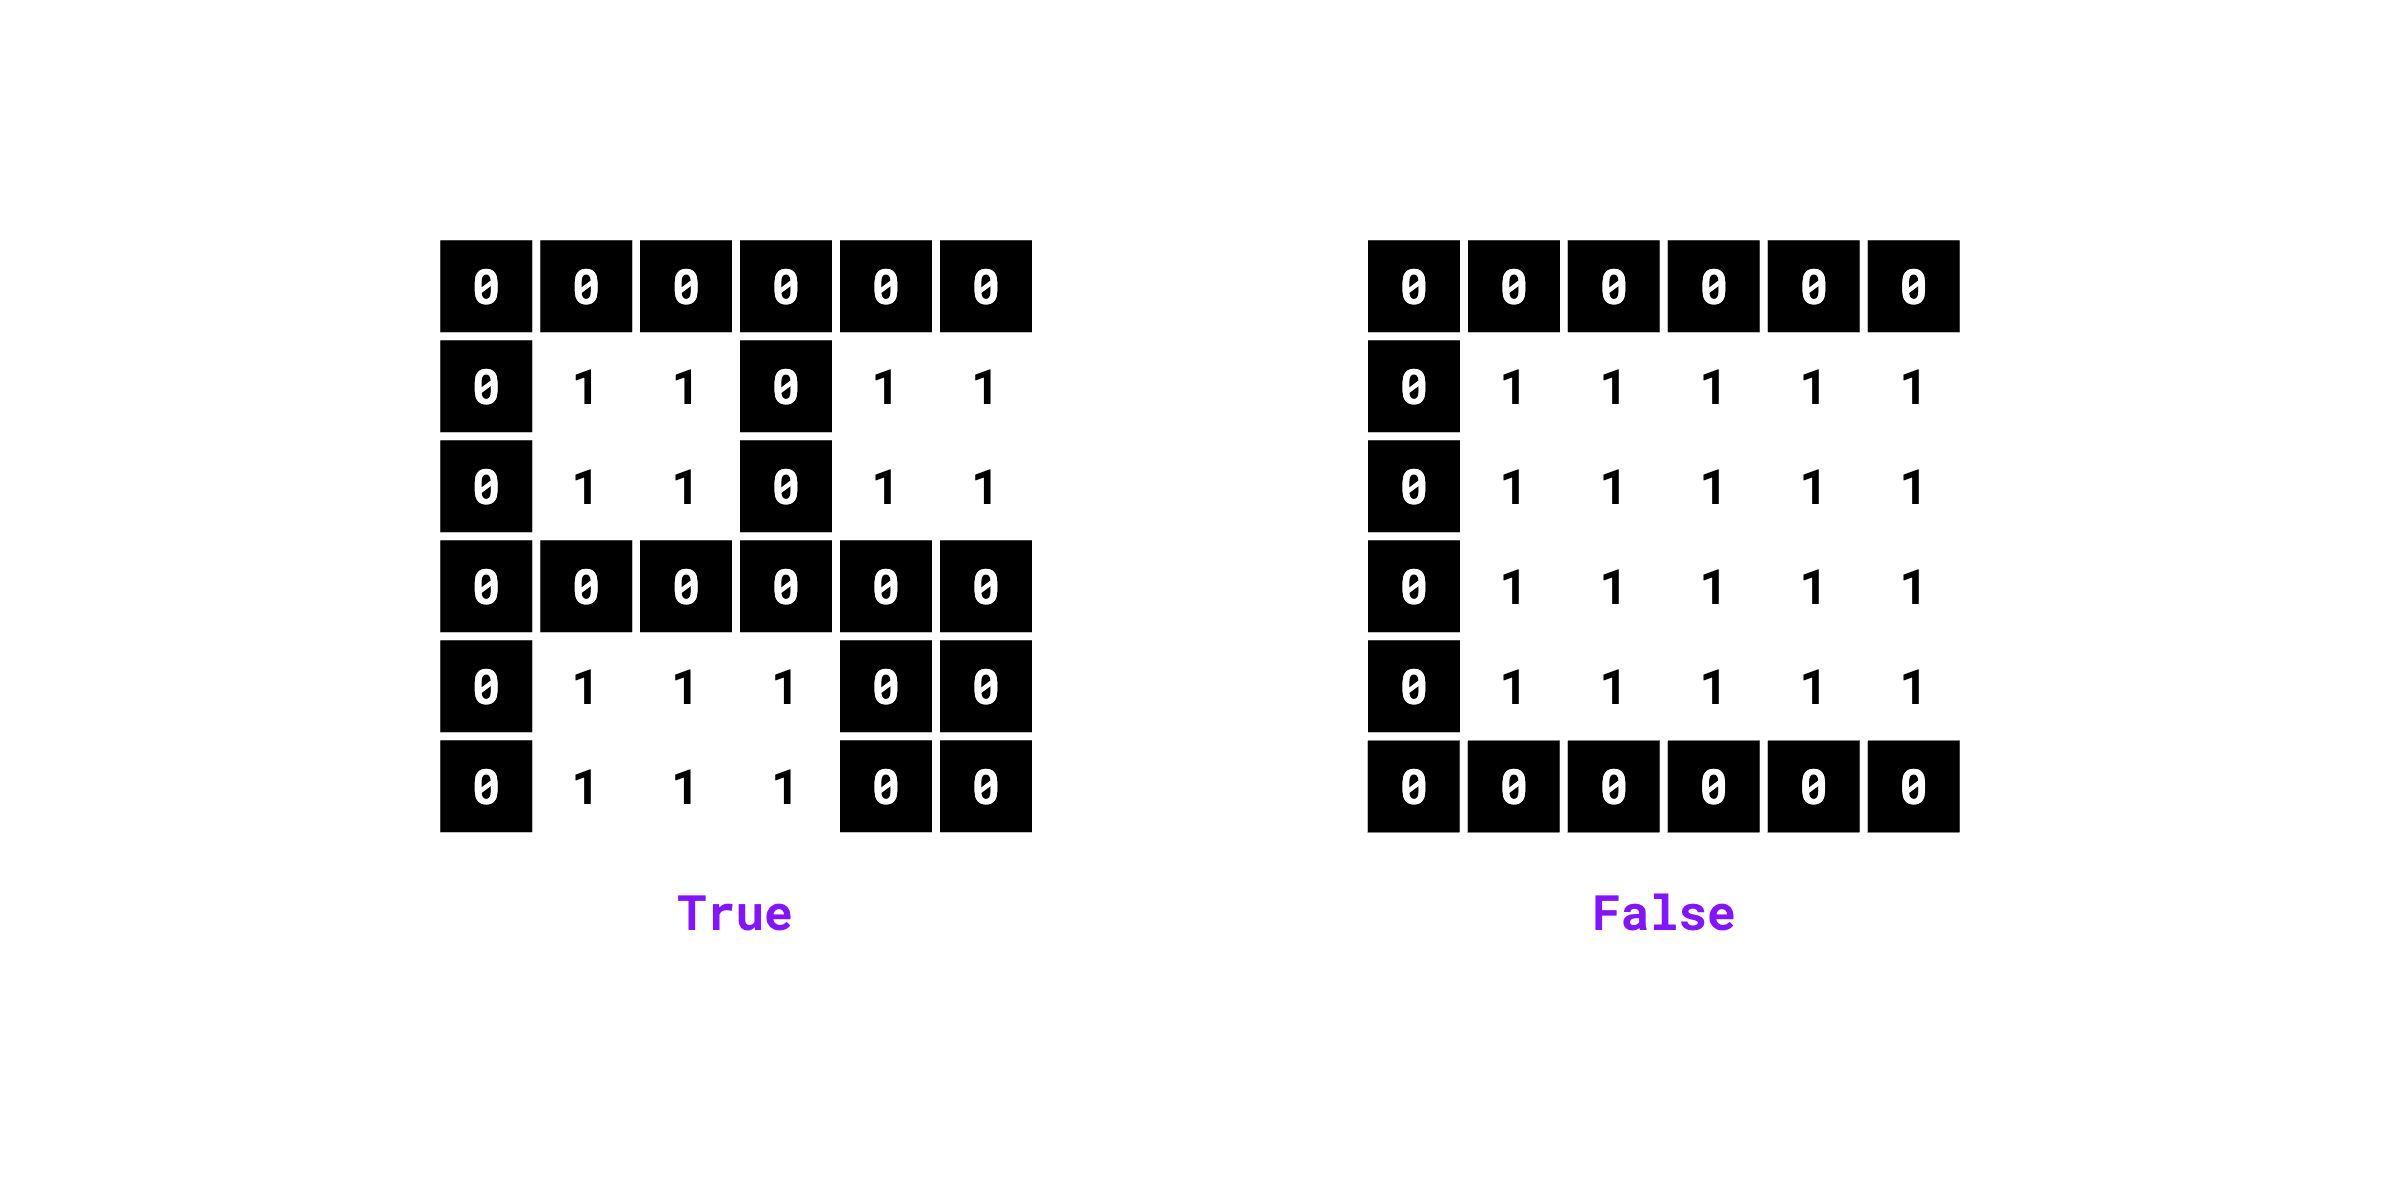{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if connectivity != 4 and connectivity != 8:
|
||||
raise ValueError(
|
||||
"Incorrect connectivity value. Possible connectivity values: 4 or 8."
|
||||
)
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
labels = np.zeros_like(mask_uint8, dtype=np.int32)
|
||||
number_of_labels, _ = cv2.connectedComponents(
|
||||
mask_uint8, labels, connectivity=connectivity
|
||||
)
|
||||
return number_of_labels > 2
|
||||
|
||||
|
||||
def cross_product(anchors: np.ndarray, vector: Vector) -> np.ndarray:
|
||||
"""
|
||||
Get array of cross products of each anchor with a vector.
|
||||
Args:
|
||||
anchors: Array of anchors of shape (number of anchors, detections, 2)
|
||||
vector: Vector to calculate cross product with
|
||||
|
||||
Returns:
|
||||
Array of cross products of shape (number of anchors, detections)
|
||||
"""
|
||||
vector_at_zero = np.array(
|
||||
[vector.end.x - vector.start.x, vector.end.y - vector.start.y]
|
||||
)
|
||||
vector_start = np.array([vector.start.x, vector.start.y])
|
||||
return np.cross(vector_at_zero, anchors - vector_start)
|
||||
+190
-46
@@ -18,12 +18,13 @@ class KeyPoints:
|
||||
The `sv.KeyPoints` class in the Supervision library standardizes results from
|
||||
various keypoint detection and pose estimation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision annotators.
|
||||
integration with Supervision [keypoints annotators](/keypoint/annotators).
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_ultralytics)
|
||||
method, which accepts model results.
|
||||
method, which accepts [YOLOv8](https://github.com/ultralytics/ultralytics)
|
||||
pose result.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
@@ -32,10 +33,60 @@ class KeyPoints:
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
Use [`sv.KeyPoints.from_inference`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference)
|
||||
method, which accepts [Inference](https://inference.roboflow.com/) pose result.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id=<POSE_MODEL_ID>, api_key=<ROBOFLOW_API_KEY>)
|
||||
|
||||
result = model.infer(image)[0]
|
||||
key_points = sv.KeyPoints.from_inference(result)
|
||||
```
|
||||
|
||||
=== "MediaPipe"
|
||||
|
||||
Use [`sv.KeyPoints.from_mediapipe`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_mediapipe)
|
||||
method, which accepts [MediaPipe](https://github.com/google-ai-edge/mediapipe)
|
||||
pose result.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import mediapipe as mp
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image_height, image_width, _ = image.shape
|
||||
mediapipe_image = mp.Image(
|
||||
image_format=mp.ImageFormat.SRGB,
|
||||
data=cv2.cvtColor(image, cv2.COLOR_BGR2RGB))
|
||||
|
||||
options = mp.tasks.vision.PoseLandmarkerOptions(
|
||||
base_options=mp.tasks.BaseOptions(
|
||||
model_asset_path="pose_landmarker_heavy.task"
|
||||
),
|
||||
running_mode=mp.tasks.vision.RunningMode.IMAGE,
|
||||
num_poses=2)
|
||||
|
||||
PoseLandmarker = mp.tasks.vision.PoseLandmarker
|
||||
with PoseLandmarker.create_from_options(options) as landmarker:
|
||||
pose_landmarker_result = landmarker.detect(mediapipe_image)
|
||||
|
||||
key_points = sv.KeyPoints.from_mediapipe(
|
||||
pose_landmarker_result, (image_width, image_height))
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, 2)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1]`
|
||||
@@ -63,7 +114,7 @@ class KeyPoints:
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Returns the number of keypoints in the keypoints object.
|
||||
Returns the number of keypoints in the `sv.KeyPoints` object.
|
||||
"""
|
||||
return len(self.xy)
|
||||
|
||||
@@ -106,18 +157,17 @@ class KeyPoints:
|
||||
"""
|
||||
Create a `sv.KeyPoints` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. When a keypoint detection model is used, this method
|
||||
extracts the keypoint coordinates, class IDs, confidences, and class names.
|
||||
package results.
|
||||
|
||||
Args:
|
||||
inference_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions with keypoints.
|
||||
|
||||
Returns:
|
||||
(KeyPoints): A KeyPoints object containing the keypoint coordinates,
|
||||
class IDs, and confidences of each keypoint.
|
||||
A `sv.KeyPoints` object containing the keypoint coordinates, class IDs,
|
||||
and class names, and confidences of each keypoint.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
@@ -151,8 +201,6 @@ class KeyPoints:
|
||||
"You can retrieve it like so: inference_result = model.infer(image)[0]"
|
||||
)
|
||||
|
||||
# Unpack the result if received from inference.get_model,
|
||||
# rather than inference_sdk.InferenceHTTPClient
|
||||
with suppress(AttributeError):
|
||||
inference_result = inference_result.dict(exclude_none=True, by_alias=True)
|
||||
|
||||
@@ -185,20 +233,105 @@ class KeyPoints:
|
||||
data=data,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_mediapipe(
|
||||
cls, mediapipe_results, resolution_wh: Tuple[int, int]
|
||||
) -> KeyPoints:
|
||||
"""
|
||||
Creates a `sv.KeyPoints` instance from a
|
||||
[MediaPipe](https://github.com/google-ai-edge/mediapipe)
|
||||
pose landmark detection inference result.
|
||||
|
||||
Args:
|
||||
mediapipe_results (Union[PoseLandmarkerResult, SolutionOutputs]):
|
||||
The output results from Mediapipe. It supports both: the inference
|
||||
result `PoseLandmarker` and the legacy one from `Pose`.
|
||||
resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)`
|
||||
representing the resolution of the frame.
|
||||
|
||||
Returns:
|
||||
A `sv.KeyPoints` object containing the keypoint coordinates and
|
||||
confidences of each keypoint.
|
||||
|
||||
!!! tip
|
||||
Before you start, download model bundles from the
|
||||
[MediaPipe website](https://ai.google.dev/edge/mediapipe/solutions/vision/pose_landmarker/index#models).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import mediapipe as mp
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image_height, image_width, _ = image.shape
|
||||
mediapipe_image = mp.Image(
|
||||
image_format=mp.ImageFormat.SRGB,
|
||||
data=cv2.cvtColor(image, cv2.COLOR_BGR2RGB))
|
||||
|
||||
options = mp.tasks.vision.PoseLandmarkerOptions(
|
||||
base_options=mp.tasks.BaseOptions(
|
||||
model_asset_path="pose_landmarker_heavy.task"
|
||||
),
|
||||
running_mode=mp.tasks.vision.RunningMode.IMAGE,
|
||||
num_poses=2)
|
||||
|
||||
PoseLandmarker = mp.tasks.vision.PoseLandmarker
|
||||
with PoseLandmarker.create_from_options(options) as landmarker:
|
||||
pose_landmarker_result = landmarker.detect(mediapipe_image)
|
||||
|
||||
key_points = sv.KeyPoints.from_mediapipe(
|
||||
pose_landmarker_result, (image_width, image_height))
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
results = mediapipe_results.pose_landmarks
|
||||
if not isinstance(mediapipe_results.pose_landmarks, list):
|
||||
if mediapipe_results.pose_landmarks is None:
|
||||
results = []
|
||||
else:
|
||||
results = [
|
||||
[landmark for landmark in mediapipe_results.pose_landmarks.landmark]
|
||||
]
|
||||
|
||||
if len(results) == 0:
|
||||
return cls.empty()
|
||||
|
||||
xy = []
|
||||
confidence = []
|
||||
for pose in results:
|
||||
prediction_xy = []
|
||||
prediction_confidence = []
|
||||
for landmark in pose:
|
||||
keypoint_xy = [
|
||||
landmark.x * resolution_wh[0],
|
||||
landmark.y * resolution_wh[1],
|
||||
]
|
||||
prediction_xy.append(keypoint_xy)
|
||||
prediction_confidence.append(landmark.visibility)
|
||||
|
||||
xy.append(prediction_xy)
|
||||
confidence.append(prediction_confidence)
|
||||
|
||||
return cls(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=np.array(confidence, dtype=np.float32),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> KeyPoints:
|
||||
"""
|
||||
Creates a KeyPoints instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
Creates a `sv.KeyPoints` instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) pose inference result.
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.engine.results.Keypoints):
|
||||
The output Results instance from YOLOv8
|
||||
|
||||
Returns:
|
||||
KeyPoints: A new KeyPoints object.
|
||||
A `sv.KeyPoints` object containing the keypoint coordinates, class IDs,
|
||||
and class names, and confidences of each keypoint.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
@@ -206,8 +339,9 @@ class KeyPoints:
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
"""
|
||||
if ultralytics_results.keypoints.xy.numel() == 0:
|
||||
@@ -224,16 +358,18 @@ class KeyPoints:
|
||||
@classmethod
|
||||
def from_yolo_nas(cls, yolo_nas_results) -> KeyPoints:
|
||||
"""
|
||||
Create a KeyPoints instance from a YOLO NAS results.
|
||||
Create a `sv.KeyPoints` instance from a [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS-POSE.md)
|
||||
pose inference results.
|
||||
|
||||
Args:
|
||||
yolo_nas_results (ImagePoseEstimationPrediction):
|
||||
The output object from YOLO NAS.
|
||||
yolo_nas_results (ImagePoseEstimationPrediction): The output object from
|
||||
YOLO NAS.
|
||||
|
||||
Returns:
|
||||
KeyPoints: A new KeyPoints object.
|
||||
A `sv.KeyPoints` object containing the keypoint coordinates, class IDs,
|
||||
and class names, and confidences of each keypoint.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import torch
|
||||
@@ -243,13 +379,13 @@ class KeyPoints:
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
yolo_nas = super_gradients.training.models.get(
|
||||
model = super_gradients.training.models.get(
|
||||
"yolo_nas_pose_s", pretrained_weights="coco_pose").to(device)
|
||||
|
||||
results = yolo_nas.predict(image, conf=0.1)
|
||||
keypoints = sv.KeyPoints.from_yolo_nas(results)
|
||||
results = model.predict(image, conf=0.1)
|
||||
key_points = sv.KeyPoints.from_yolo_nas(results)
|
||||
```
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
if len(yolo_nas_results.prediction.poses) == 0:
|
||||
return cls.empty()
|
||||
|
||||
@@ -282,34 +418,41 @@ class KeyPoints:
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union[KeyPoints, List, np.ndarray, None]:
|
||||
"""
|
||||
Get a subset of the KeyPoints object or access an item from its data field.
|
||||
Get a subset of the `sv.KeyPoints` object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new KeyPoints object that represents a subset of the original
|
||||
keypoints. When provided with a string, it accesses the corresponding item in
|
||||
the data dictionary.
|
||||
method returns a new `sv.KeyPoints` object that represents a subset of the
|
||||
original `sv.KeyPoints`. When provided with a string, it accesses the
|
||||
corresponding item in the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the KeyPoints or an item from the data.
|
||||
or key to access a subset of the `sv.KeyPoints` or an item from the
|
||||
data.
|
||||
|
||||
Returns:
|
||||
Union[KeyPoints, Any]: A subset of the KeyPoints object or an item from
|
||||
the data field.
|
||||
A subset of the `sv.KeyPoints` object or an item from the data field.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
keypoints = sv.KeyPoints()
|
||||
key_points = sv.KeyPoints()
|
||||
|
||||
first_detection = keypoints[0]
|
||||
first_10_keypoints = keypoints[0:10]
|
||||
some_keypoints = keypoints[[0, 2, 4]]
|
||||
class_0_keypoints = keypoints[keypoints.class_id == 0]
|
||||
high_confidence_keypoints = keypoints[keypoints.confidence > 0.5]
|
||||
# access the first keypoint using an integer index
|
||||
key_points[0]
|
||||
|
||||
feature_vector = keypoints['feature_vector']
|
||||
# access the first 10 keypoints using index slice
|
||||
key_points[0:10]
|
||||
|
||||
# access selected keypoints using a list of indices
|
||||
key_points[[0, 2, 4]]
|
||||
|
||||
# access keypoints with selected class_id
|
||||
key_points[key_points.class_id == 0]
|
||||
|
||||
# access keypoints with confidence greater than 0.5
|
||||
key_points[key_points.confidence > 0.5]
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
@@ -325,13 +468,13 @@ class KeyPoints:
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
"""
|
||||
Set a value in the data dictionary of the KeyPoints object.
|
||||
Set a value in the data dictionary of the `sv.KeyPoints` object.
|
||||
|
||||
Args:
|
||||
key (str): The key in the data dictionary to set.
|
||||
value (Union[np.ndarray, List]): The value to set for the key.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
@@ -343,7 +486,7 @@ class KeyPoints:
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
keypoints['names'] = [
|
||||
keypoints['class_name'] = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in keypoints.class_id
|
||||
@@ -364,12 +507,13 @@ class KeyPoints:
|
||||
Create an empty Keypoints object with no keypoints.
|
||||
|
||||
Returns:
|
||||
(KeyPoints): An empty Keypoints object.
|
||||
An empty `sv.KeyPoints` object.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
from supervision import Keypoints
|
||||
empty_keypoints = Keypoints.empty()
|
||||
import supervision as sv
|
||||
|
||||
key_points = sv.KeyPoints.empty()
|
||||
```
|
||||
"""
|
||||
return cls(xy=np.empty((0, 0, 2), dtype=np.float32))
|
||||
@@ -25,6 +25,44 @@ class Skeleton(Enum):
|
||||
(17, 15),
|
||||
]
|
||||
|
||||
GHUM = [
|
||||
(1, 2),
|
||||
(1, 5),
|
||||
(2, 3),
|
||||
(3, 4),
|
||||
(4, 8),
|
||||
(5, 6),
|
||||
(6, 7),
|
||||
(7, 9),
|
||||
(10, 11),
|
||||
(12, 13),
|
||||
(12, 14),
|
||||
(12, 24),
|
||||
(13, 15),
|
||||
(13, 25),
|
||||
(14, 16),
|
||||
(15, 17),
|
||||
(16, 18),
|
||||
(15, 19),
|
||||
(16, 22),
|
||||
(17, 19),
|
||||
(17, 21),
|
||||
(17, 23),
|
||||
(18, 20),
|
||||
(19, 21),
|
||||
(24, 25),
|
||||
(24, 26),
|
||||
(25, 27),
|
||||
(26, 28),
|
||||
(27, 29),
|
||||
(28, 30),
|
||||
(28, 32),
|
||||
(29, 31),
|
||||
(29, 33),
|
||||
(30, 32),
|
||||
(31, 33),
|
||||
]
|
||||
|
||||
|
||||
SKELETONS_BY_EDGE_COUNT: Dict[int, Edges] = {}
|
||||
SKELETONS_BY_VERTEX_COUNT: Dict[int, Edges] = {}
|
||||
|
||||
@@ -1,7 +1,8 @@
|
||||
import functools
|
||||
import inspect
|
||||
import os
|
||||
import warnings
|
||||
from typing import Callable
|
||||
from typing import Any, Callable, Set
|
||||
|
||||
|
||||
class SupervisionWarnings(Warning):
|
||||
@@ -141,3 +142,42 @@ class classproperty(property):
|
||||
The result of calling the function stored in 'fget' with 'owner_cls'.
|
||||
"""
|
||||
return self.fget(owner_cls)
|
||||
|
||||
|
||||
def get_instance_variables(instance: Any, include_properties=False) -> Set[str]:
|
||||
"""
|
||||
Get the public variables of a class instance.
|
||||
|
||||
Args:
|
||||
instance (Any): The instance of a class
|
||||
include_properties (bool): Whether to include properties in the result
|
||||
|
||||
Usage:
|
||||
```python
|
||||
detections = Detections(xyxy=np.array([1,2,3,4]))
|
||||
variables = get_class_variables(detections)
|
||||
# ["xyxy", "mask", "confidence", ..., "data"]
|
||||
```
|
||||
"""
|
||||
if isinstance(instance, type):
|
||||
raise ValueError("Only class instances are supported, not classes.")
|
||||
|
||||
fields = set(
|
||||
(
|
||||
name
|
||||
for name, val in inspect.getmembers(instance)
|
||||
if not callable(val) and not name.startswith("_")
|
||||
)
|
||||
)
|
||||
|
||||
if not include_properties:
|
||||
properties = set(
|
||||
(
|
||||
name
|
||||
for name, val in inspect.getmembers(instance.__class__)
|
||||
if isinstance(val, property)
|
||||
)
|
||||
)
|
||||
fields -= properties
|
||||
|
||||
return fields
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import Dict, List, Tuple
|
||||
from typing import Dict, List, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
@@ -10,24 +10,30 @@ from supervision.dataset.formats.coco import (
|
||||
classes_to_coco_categories,
|
||||
coco_annotations_to_detections,
|
||||
coco_categories_to_classes,
|
||||
detections_to_coco_annotations,
|
||||
group_coco_annotations_by_image_id,
|
||||
)
|
||||
|
||||
|
||||
def mock_cock_coco_annotation(
|
||||
def mock_coco_annotation(
|
||||
annotation_id: int = 0,
|
||||
image_id: int = 0,
|
||||
category_id: int = 0,
|
||||
bbox: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0),
|
||||
area: float = 0.0,
|
||||
segmentation: Union[List[list], Dict] = None,
|
||||
iscrowd: bool = False,
|
||||
) -> dict:
|
||||
if not segmentation:
|
||||
segmentation = []
|
||||
return {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": category_id,
|
||||
"bbox": list(bbox),
|
||||
"area": area,
|
||||
"iscrowd": 0,
|
||||
"segmentation": segmentation,
|
||||
"iscrowd": int(iscrowd),
|
||||
}
|
||||
|
||||
|
||||
@@ -101,74 +107,46 @@ def test_classes_to_coco_categories_and_back_to_classes(
|
||||
[
|
||||
([], {}, DoesNotRaise()), # empty coco annotations
|
||||
(
|
||||
[mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0)],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=0, image_id=0, category_id=0
|
||||
)
|
||||
]
|
||||
},
|
||||
[mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)],
|
||||
{0: [mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)]},
|
||||
DoesNotRaise(),
|
||||
), # single coco annotation
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=0),
|
||||
mock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_coco_annotation(annotation_id=1, image_id=1, category_id=0),
|
||||
],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=0, image_id=0, category_id=0
|
||||
)
|
||||
],
|
||||
1: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=1, image_id=1, category_id=0
|
||||
)
|
||||
],
|
||||
0: [mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)],
|
||||
1: [mock_coco_annotation(annotation_id=1, image_id=1, category_id=0)],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # two coco annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=2, image_id=1, category_id=2),
|
||||
mock_cock_coco_annotation(annotation_id=3, image_id=2, category_id=3),
|
||||
mock_cock_coco_annotation(annotation_id=4, image_id=3, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=2),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=3),
|
||||
mock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_coco_annotation(annotation_id=1, image_id=1, category_id=1),
|
||||
mock_coco_annotation(annotation_id=2, image_id=1, category_id=2),
|
||||
mock_coco_annotation(annotation_id=3, image_id=2, category_id=3),
|
||||
mock_coco_annotation(annotation_id=4, image_id=3, category_id=1),
|
||||
mock_coco_annotation(annotation_id=5, image_id=3, category_id=2),
|
||||
mock_coco_annotation(annotation_id=5, image_id=3, category_id=3),
|
||||
],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=0, image_id=0, category_id=0
|
||||
),
|
||||
mock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
],
|
||||
1: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=1, image_id=1, category_id=1
|
||||
),
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=2, image_id=1, category_id=2
|
||||
),
|
||||
mock_coco_annotation(annotation_id=1, image_id=1, category_id=1),
|
||||
mock_coco_annotation(annotation_id=2, image_id=1, category_id=2),
|
||||
],
|
||||
2: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=3, image_id=2, category_id=3
|
||||
),
|
||||
mock_coco_annotation(annotation_id=3, image_id=2, category_id=3),
|
||||
],
|
||||
3: [
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=4, image_id=3, category_id=1
|
||||
),
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=5, image_id=3, category_id=2
|
||||
),
|
||||
mock_cock_coco_annotation(
|
||||
annotation_id=5, image_id=3, category_id=3
|
||||
),
|
||||
mock_coco_annotation(annotation_id=4, image_id=3, category_id=1),
|
||||
mock_coco_annotation(annotation_id=5, image_id=3, category_id=2),
|
||||
mock_coco_annotation(annotation_id=5, image_id=3, category_id=3),
|
||||
],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
@@ -195,7 +173,7 @@ def test_group_coco_annotations_by_image_id(
|
||||
), # empty image annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(
|
||||
mock_coco_annotation(
|
||||
category_id=0, bbox=(0, 0, 100, 100), area=100 * 100
|
||||
)
|
||||
],
|
||||
@@ -209,10 +187,10 @@ def test_group_coco_annotations_by_image_id(
|
||||
), # single image annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(
|
||||
mock_coco_annotation(
|
||||
category_id=0, bbox=(0, 0, 100, 100), area=100 * 100
|
||||
),
|
||||
mock_cock_coco_annotation(
|
||||
mock_coco_annotation(
|
||||
category_id=0, bbox=(100, 100, 100, 100), area=100 * 100
|
||||
),
|
||||
],
|
||||
@@ -226,6 +204,156 @@ def test_group_coco_annotations_by_image_id(
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two image annotations
|
||||
(
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]],
|
||||
)
|
||||
],
|
||||
(5, 5),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single image annotations with mask as polygon
|
||||
(
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation={
|
||||
"size": [5, 5],
|
||||
"counts": [0, 15, 2, 3, 2, 3],
|
||||
},
|
||||
iscrowd=True,
|
||||
)
|
||||
],
|
||||
(5, 5),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single image annotations with mask, RLE segmentation mask
|
||||
(
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]],
|
||||
),
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(3, 0, 2, 2),
|
||||
area=2 * 2,
|
||||
segmentation={
|
||||
"size": [5, 5],
|
||||
"counts": [15, 2, 3, 2, 3],
|
||||
},
|
||||
iscrowd=True,
|
||||
),
|
||||
],
|
||||
(5, 5),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5], [3, 0, 5, 2]], dtype=np.float32),
|
||||
class_id=np.array([0, 0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
],
|
||||
[
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
],
|
||||
]
|
||||
),
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two image annotations with mask, one mask as polygon ans second as RLE
|
||||
(
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(3, 0, 2, 2),
|
||||
area=2 * 2,
|
||||
segmentation={
|
||||
"size": [5, 5],
|
||||
"counts": [15, 2, 3, 2, 3],
|
||||
},
|
||||
iscrowd=True,
|
||||
),
|
||||
mock_coco_annotation(
|
||||
category_id=1,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]],
|
||||
),
|
||||
],
|
||||
(5, 5),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([[3, 0, 5, 2], [0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([0, 1], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
],
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
],
|
||||
]
|
||||
),
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two image annotations with mask, first mask as RLE and second as polygon
|
||||
],
|
||||
)
|
||||
def test_coco_annotations_to_detections(
|
||||
@@ -301,3 +429,131 @@ def test_build_coco_class_index_mapping(
|
||||
coco_categories=coco_categories, target_classes=target_classes
|
||||
)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"detections, image_id, annotation_id, expected_result, exception",
|
||||
[
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 100, 100]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
),
|
||||
0,
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0, bbox=(0, 0, 100, 100), area=100 * 100
|
||||
)
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # no segmentation mask
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 4, 5]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 1, 0],
|
||||
[1, 1, 1, 1, 0],
|
||||
[1, 1, 1, 1, 0],
|
||||
[1, 1, 1, 1, 0],
|
||||
[1, 1, 1, 1, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
),
|
||||
0,
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 4, 5),
|
||||
area=4 * 5,
|
||||
segmentation=[[0, 0, 0, 4, 3, 4, 3, 0]],
|
||||
)
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # segmentation mask in single component,no holes in mask,
|
||||
# expects polygon mask
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
),
|
||||
0,
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation={
|
||||
"size": [5, 5],
|
||||
"counts": [0, 3, 2, 3, 2, 3, 5, 2, 3, 2],
|
||||
},
|
||||
iscrowd=True,
|
||||
)
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # segmentation mask with 2 components, no holes in mask, expects RLE mask
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array(
|
||||
[
|
||||
[
|
||||
[0, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1],
|
||||
[1, 1, 0, 0, 1],
|
||||
[1, 1, 0, 0, 1],
|
||||
[1, 1, 1, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
),
|
||||
0,
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation={
|
||||
"size": [5, 5],
|
||||
"counts": [2, 10, 2, 3, 2, 6],
|
||||
},
|
||||
iscrowd=True,
|
||||
)
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # seg mask in single component, with holes in mask, expects RLE mask
|
||||
],
|
||||
)
|
||||
def test_detections_to_coco_annotations(
|
||||
detections: Detections,
|
||||
image_id: int,
|
||||
annotation_id: int,
|
||||
expected_result: List[Dict],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result, _ = detections_to_coco_annotations(
|
||||
detections=detections,
|
||||
image_id=image_id,
|
||||
annotation_id=annotation_id,
|
||||
)
|
||||
assert result == expected_result
|
||||
@@ -2,13 +2,17 @@ from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
import pytest
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.dataset.utils import (
|
||||
build_class_index_mapping,
|
||||
map_detections_class_id,
|
||||
mask_to_rle,
|
||||
merge_class_lists,
|
||||
rle_to_mask,
|
||||
train_test_split,
|
||||
)
|
||||
|
||||
@@ -229,3 +233,131 @@ def test_map_detections_class_id(
|
||||
source_to_target_mapping=source_to_target_mapping, detections=detections
|
||||
)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, expected_rle, exception",
|
||||
[
|
||||
(
|
||||
np.zeros((3, 3)).astype(bool),
|
||||
[9],
|
||||
DoesNotRaise(),
|
||||
), # mask with background only (mask with only False values)
|
||||
(
|
||||
np.ones((3, 3)).astype(bool),
|
||||
[0, 9],
|
||||
DoesNotRaise(),
|
||||
), # mask with foreground only (mask with only True values)
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 0, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
]
|
||||
).astype(bool),
|
||||
[6, 3, 2, 1, 1, 1, 2, 3, 6],
|
||||
DoesNotRaise(),
|
||||
), # mask where foreground object has hole
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
]
|
||||
).astype(bool),
|
||||
[0, 5, 5, 5, 5, 5],
|
||||
DoesNotRaise(),
|
||||
), # mask where foreground consists of 3 separate components
|
||||
(
|
||||
np.array([[[]]]).astype(bool),
|
||||
None,
|
||||
pytest.raises(AssertionError),
|
||||
), # raises AssertionError because mask dimentionality is not 2D
|
||||
(
|
||||
np.array([[]]).astype(bool),
|
||||
None,
|
||||
pytest.raises(AssertionError),
|
||||
), # raises AssertionError because mask is empty
|
||||
],
|
||||
)
|
||||
def test_mask_to_rle(
|
||||
mask: npt.NDArray[np.bool_], expected_rle: List[int], exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = mask_to_rle(mask=mask)
|
||||
assert result == expected_rle
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"rle, resolution_wh, expected_mask, exception",
|
||||
[
|
||||
(
|
||||
np.array([9]),
|
||||
[3, 3],
|
||||
np.zeros((3, 3)).astype(bool),
|
||||
DoesNotRaise(),
|
||||
), # mask with background only (mask with only False values); rle as array
|
||||
(
|
||||
[9],
|
||||
[3, 3],
|
||||
np.zeros((3, 3)).astype(bool),
|
||||
DoesNotRaise(),
|
||||
), # mask with background only (mask with only False values); rle as list
|
||||
(
|
||||
np.array([0, 9]),
|
||||
[3, 3],
|
||||
np.ones((3, 3)).astype(bool),
|
||||
DoesNotRaise(),
|
||||
), # mask with foreground only (mask with only True values)
|
||||
(
|
||||
np.array([6, 3, 2, 1, 1, 1, 2, 3, 6]),
|
||||
[5, 5],
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 0, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
]
|
||||
).astype(bool),
|
||||
DoesNotRaise(),
|
||||
), # mask where foreground object has hole
|
||||
(
|
||||
np.array([0, 5, 5, 5, 5, 5]),
|
||||
[5, 5],
|
||||
np.array(
|
||||
[
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
[1, 0, 1, 0, 1],
|
||||
]
|
||||
).astype(bool),
|
||||
DoesNotRaise(),
|
||||
), # mask where foreground consists of 3 separate components
|
||||
(
|
||||
np.array([0, 5, 5, 5, 5, 5]),
|
||||
[2, 2],
|
||||
None,
|
||||
pytest.raises(AssertionError),
|
||||
), # raises AssertionError because number of pixels in RLE does not match
|
||||
# number of pixels in expected mask (width x height).
|
||||
],
|
||||
)
|
||||
def test_rle_to_mask(
|
||||
rle: npt.NDArray[np.int_],
|
||||
resolution_wh: Tuple[int, int],
|
||||
expected_mask: npt.NDArray[np.bool_],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = rle_to_mask(rle=rle, resolution_wh=resolution_wh)
|
||||
assert np.all(result == expected_mask)
|
||||
+189
-5
@@ -5,7 +5,7 @@ from typing import List, Optional, Union
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.core import Detections, merge_inner_detection_object_pair
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
PREDICTIONS = np.array(
|
||||
@@ -245,7 +245,6 @@ def test_getitem(
|
||||
TEST_DET_1_2,
|
||||
DoesNotRaise(),
|
||||
), # Fields with same keys
|
||||
# Fields and empty
|
||||
(
|
||||
[TEST_DET_1, Detections.empty()],
|
||||
TEST_DET_1,
|
||||
@@ -264,9 +263,9 @@ def test_getitem(
|
||||
TEST_DET_1,
|
||||
TEST_DET_NONE,
|
||||
],
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # Single detection and None fields (+ missing Dict keys)
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Empty detection, but not Detections.empty()
|
||||
# Errors: Non-zero-length differently defined keys & data
|
||||
(
|
||||
[TEST_DET_1, TEST_DET_DIFFERENT_FIELDS],
|
||||
@@ -278,6 +277,22 @@ def test_getitem(
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Non-empty detections with different data keys
|
||||
(
|
||||
[
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20]],
|
||||
class_id=[1],
|
||||
mask=[np.zeros((4, 4), dtype=bool)],
|
||||
),
|
||||
Detections.empty(),
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20]],
|
||||
class_id=[1],
|
||||
mask=[np.zeros((4, 4), dtype=bool)],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Segmentation + Empty
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
@@ -421,3 +436,172 @@ def test_equal(
|
||||
detections_a: Detections, detections_b: Detections, expected_result: bool
|
||||
) -> None:
|
||||
assert (detections_a == detections_b) == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"detection_1, detection_2, expected_result, exception",
|
||||
[
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Merge with self
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
),
|
||||
Detections.empty(),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # merge with empty: error
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30], [40, 40, 60, 60]],
|
||||
),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # merge with 2+ objects: error
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
confidence=[0.1],
|
||||
class_id=[1],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)],
|
||||
tracker_id=[1],
|
||||
data={"key_1": [1]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[20, 20, 40, 40]],
|
||||
confidence=[0.1],
|
||||
class_id=[2],
|
||||
mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[2],
|
||||
data={"key_2": [2]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 40, 40]],
|
||||
confidence=[0.1],
|
||||
class_id=[1],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[1],
|
||||
data={"key_1": [1]},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Same confidence - merge box & mask, tie-break to detection_1
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[0, 0, 20, 20]],
|
||||
confidence=[0.1],
|
||||
class_id=[1],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)],
|
||||
tracker_id=[1],
|
||||
data={"key_1": [1]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 50, 50]],
|
||||
confidence=[0.2],
|
||||
class_id=[2],
|
||||
mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[2],
|
||||
data={"key_2": [2]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[0, 0, 50, 50]],
|
||||
confidence=[(1 * 0.1 + 4 * 0.2) / 5],
|
||||
class_id=[2],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[2],
|
||||
data={"key_2": [2]},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Different confidence, different area
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
confidence=None,
|
||||
class_id=[1],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)],
|
||||
tracker_id=[1],
|
||||
data={"key_1": [1]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[20, 20, 40, 40]],
|
||||
confidence=None,
|
||||
class_id=[2],
|
||||
mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[2],
|
||||
data={"key_2": [2]},
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 40, 40]],
|
||||
confidence=None,
|
||||
class_id=[1],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)],
|
||||
tracker_id=[1],
|
||||
data={"key_1": [1]},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # No confidence at all
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[0, 0, 20, 20]],
|
||||
confidence=None,
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
confidence=[0.2],
|
||||
),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # confidence: None + [x]
|
||||
(
|
||||
mock_detections(
|
||||
xyxy=[[0, 0, 20, 20]],
|
||||
mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)],
|
||||
),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
mask=None,
|
||||
),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # mask: None + [x]
|
||||
(
|
||||
mock_detections(xyxy=[[0, 0, 20, 20]], tracker_id=[1]),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
tracker_id=None,
|
||||
),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # tracker_id: None + []
|
||||
(
|
||||
mock_detections(xyxy=[[0, 0, 20, 20]], class_id=[1]),
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 30, 30]],
|
||||
class_id=None,
|
||||
),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # class_id: None + []
|
||||
],
|
||||
)
|
||||
def test_merge_inner_detection_object_pair(
|
||||
detection_1: Detections,
|
||||
detection_2: Detections,
|
||||
expected_result: Optional[Detections],
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = merge_inner_detection_object_pair(detection_1, detection_2)
|
||||
assert result == expected_result
|
||||
@@ -1,10 +1,11 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import Optional, Tuple
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import LineZone
|
||||
from supervision.geometry.core import Point, Vector
|
||||
from supervision.geometry.core import Point, Position, Vector
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
@@ -70,3 +71,409 @@ def test_calculate_region_of_interest_limits(
|
||||
with exception:
|
||||
result = LineZone.calculate_region_of_interest_limits(vector=vector)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"vector, xyxy_sequence, expected_crossed_in, expected_crossed_out",
|
||||
[
|
||||
( # Vertical line, simple crossing
|
||||
Vector(Point(0, 0), Point(0, 10)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4 - 10, 4, 6 - 10, 6],
|
||||
[4, 4, 6, 6],
|
||||
[4 - 10, 4, 6 - 10, 6],
|
||||
],
|
||||
[False, False, True, False],
|
||||
[False, True, False, True],
|
||||
),
|
||||
( # Vertical line reversed, simple crossing
|
||||
Vector(Point(0, 10), Point(0, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4 - 10, 4, 6 - 10, 6],
|
||||
[4, 4, 6, 6],
|
||||
[4 - 10, 4, 6 - 10, 6],
|
||||
],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Horizontal line, simple crossing
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Horizontal line reversed, simple crossing
|
||||
Vector(Point(10, 0), Point(0, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
],
|
||||
[False, False, True, False],
|
||||
[False, True, False, True],
|
||||
),
|
||||
( # Diagonal line, simple crossing
|
||||
Vector(Point(5, 0), Point(0, 5)),
|
||||
[
|
||||
[0, 0, 2, 2],
|
||||
[0 + 10, 0 + 10, 2 + 10, 2 + 10],
|
||||
[0, 0, 2, 2],
|
||||
[0 + 10, 0 + 10, 2 + 10, 2 + 10],
|
||||
],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Crossing beside - right side
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[20, 4, 24, 6],
|
||||
[20, 4 - 10, 24, 6 - 10],
|
||||
[20, 4, 24, 6],
|
||||
[20, 4 - 10, 24, 6 - 10],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Horizontal line, simple crossing, far away
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[4, 1e32, 6, 1e32 + 2],
|
||||
[4, -1e32, 6, -1e32 + 2],
|
||||
[4, 1e32, 6, 1e32 + 2],
|
||||
[4, -1e32, 6, -1e32 + 2],
|
||||
],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Crossing beside - left side
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-20, 4, -24, 6],
|
||||
[-20, 4 - 10, -24, 6 - 10],
|
||||
[-20, 4, -24, 6],
|
||||
[-20, 4 - 10, -24, 6 - 10],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Move above
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-4, 4, -2, 6],
|
||||
[-4 + 20, 4, -2 + 20, 6],
|
||||
[-4, 4, -2, 6],
|
||||
[-4 + 20, 4, -2 + 20, 6],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Move below
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-4, -6, -2, -4],
|
||||
[-4 + 20, -6, -2 + 20, -4],
|
||||
[-4, -6, -2, -4],
|
||||
[-4 + 20, -6, -2 + 20, -4],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Move into line partway
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4 + 5, 4, 6 + 5, 6],
|
||||
[4, 4, 6, 6],
|
||||
[4 + 5, 4, 6 + 5, 6],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # V-shaped crossing from outside limits - not supported.
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[[-3, 6, -1, 8], [4, -6, 6, -4], [11, 6, 13, 8]],
|
||||
[False, False, False],
|
||||
[False, False, False],
|
||||
),
|
||||
( # Diagonal movement, from within limits to outside - not supported
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[[4, 1, 6, 3], [11, 1 - 20, 13, 3 - 20]],
|
||||
[False, False],
|
||||
[False, False],
|
||||
),
|
||||
( # Diagonal movement, from outside limits to within - not supported
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[11, 21, 13, 23],
|
||||
[4, -3, 6, -1],
|
||||
],
|
||||
[False, False],
|
||||
[False, False],
|
||||
),
|
||||
( # Diagonal crossing, from outside to outside limits - not supported.
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-4, 4, -2, 8],
|
||||
[-4 + 16, -4, -2 + 16, -6],
|
||||
[-4, 4, -2, 8],
|
||||
[-4 + 16, -4, -2 + 16, -6],
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_line_zone_one_detection_default_anchors(
|
||||
vector: Vector,
|
||||
xyxy_sequence: List[List[float]],
|
||||
expected_crossed_in: List[bool],
|
||||
expected_crossed_out: List[bool],
|
||||
) -> None:
|
||||
line_zone = LineZone(start=vector.start, end=vector.end)
|
||||
|
||||
crossed_in_list = []
|
||||
crossed_out_list = []
|
||||
for i, bbox in enumerate(xyxy_sequence):
|
||||
detections = mock_detections(
|
||||
xyxy=[bbox],
|
||||
tracker_id=[0],
|
||||
)
|
||||
crossed_in, crossed_out = line_zone.trigger(detections)
|
||||
crossed_in_list.append(crossed_in[0])
|
||||
crossed_out_list.append(crossed_out[0])
|
||||
|
||||
assert (
|
||||
crossed_in_list == expected_crossed_in
|
||||
), f"expected {expected_crossed_in}, got {crossed_in_list}"
|
||||
assert (
|
||||
crossed_out_list == expected_crossed_out
|
||||
), f"expected {expected_crossed_out}, got {crossed_out_list}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"vector, xyxy_sequence, triggering_anchors, expected_crossed_in, "
|
||||
"expected_crossed_out",
|
||||
[
|
||||
( # Scrape line, left side, corner anchors
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
],
|
||||
[
|
||||
Position.TOP_LEFT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Scrape line, left side, right anchors
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
],
|
||||
[Position.TOP_RIGHT, Position.BOTTOM_RIGHT],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Scrape line, left side, center anchor (along line point)
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
[-2, 4, 2, 6],
|
||||
[-2, 4 - 10, 2, 6 - 10],
|
||||
],
|
||||
[Position.CENTER],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Scrape line, right side, corner anchors
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
],
|
||||
[
|
||||
Position.TOP_LEFT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
),
|
||||
( # Scrape line, right side, left anchors
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
],
|
||||
[Position.TOP_LEFT, Position.BOTTOM_LEFT],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Scrape line, right side, center anchor (along line point)
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
[8, 4, 12, 6],
|
||||
[8, 4 - 10, 12, 6 - 10],
|
||||
],
|
||||
[Position.CENTER],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Simple crossing, one anchor
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
],
|
||||
[Position.CENTER],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
( # Simple crossing, all box anchors
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
[4, 4, 6, 6],
|
||||
[4, 4 - 10, 6, 6 - 10],
|
||||
],
|
||||
[
|
||||
Position.CENTER,
|
||||
Position.CENTER_LEFT,
|
||||
Position.CENTER_RIGHT,
|
||||
Position.TOP_CENTER,
|
||||
Position.TOP_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.BOTTOM_CENTER,
|
||||
Position.BOTTOM_RIGHT,
|
||||
],
|
||||
[False, True, False, True],
|
||||
[False, False, True, False],
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_line_zone_one_detection(
|
||||
vector: Vector,
|
||||
xyxy_sequence: List[List[float]],
|
||||
triggering_anchors: List[Position],
|
||||
expected_crossed_in: List[bool],
|
||||
expected_crossed_out: List[bool],
|
||||
) -> None:
|
||||
line_zone = LineZone(
|
||||
start=vector.start, end=vector.end, triggering_anchors=triggering_anchors
|
||||
)
|
||||
|
||||
crossed_in_list = []
|
||||
crossed_out_list = []
|
||||
for i, bbox in enumerate(xyxy_sequence):
|
||||
detections = mock_detections(
|
||||
xyxy=[bbox],
|
||||
tracker_id=[0],
|
||||
)
|
||||
crossed_in, crossed_out = line_zone.trigger(detections)
|
||||
crossed_in_list.append(crossed_in[0])
|
||||
crossed_out_list.append(crossed_out[0])
|
||||
|
||||
assert (
|
||||
crossed_in_list == expected_crossed_in
|
||||
), f"expected {expected_crossed_in}, got {crossed_in_list}"
|
||||
assert (
|
||||
crossed_out_list == expected_crossed_out
|
||||
), f"expected {expected_crossed_out}, got {crossed_out_list}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"vector, xyxy_sequence, anchors, expected_crossed_in, "
|
||||
"expected_crossed_out, exception",
|
||||
[
|
||||
( # One stays, one crosses
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[[4, 4, 6, 6], [4, 4, 6, 6]],
|
||||
[[4, 4, 6, 6], [4, 4 - 10, 6, 6 - 10]],
|
||||
[[4, 4, 6, 6], [4, 4, 6, 6]],
|
||||
[[4, 4, 6, 6], [4, 4 - 10, 6, 6 - 10]],
|
||||
],
|
||||
[
|
||||
Position.TOP_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
],
|
||||
[[False, False], [False, True], [False, False], [False, True]],
|
||||
[[False, False], [False, False], [False, True], [False, False]],
|
||||
DoesNotRaise(),
|
||||
),
|
||||
( # Both cross at the same time
|
||||
Vector(Point(0, 0), Point(10, 0)),
|
||||
[
|
||||
[[4, 4, 6, 6], [4, 4, 6, 6]],
|
||||
[[4, 4 - 10, 6, 6 - 10], [4, 4 - 10, 6, 6 - 10]],
|
||||
[[4, 4, 6, 6], [4, 4, 6, 6]],
|
||||
[[4, 4 - 10, 6, 6 - 10], [4, 4 - 10, 6, 6 - 10]],
|
||||
],
|
||||
[
|
||||
Position.TOP_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
],
|
||||
[[False, False], [True, True], [False, False], [True, True]],
|
||||
[[False, False], [False, False], [True, True], [False, False]],
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_line_zone_multiple_detections(
|
||||
vector: Vector,
|
||||
xyxy_sequence: List[List[List[float]]],
|
||||
anchors: List[Position],
|
||||
expected_crossed_in: List[List[bool]],
|
||||
expected_crossed_out: List[List[bool]],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
line_zone = LineZone(
|
||||
start=vector.start, end=vector.end, triggering_anchors=anchors
|
||||
)
|
||||
crossed_in_list = []
|
||||
crossed_out_list = []
|
||||
for bboxes in xyxy_sequence:
|
||||
detections = mock_detections(
|
||||
xyxy=bboxes,
|
||||
tracker_id=[i for i in range(0, len(bboxes))],
|
||||
)
|
||||
crossed_in, crossed_out = line_zone.trigger(detections)
|
||||
crossed_in_list.append(list(crossed_in))
|
||||
crossed_out_list.append(list(crossed_out))
|
||||
|
||||
assert crossed_in_list == expected_crossed_in
|
||||
assert crossed_out_list == expected_crossed_out
|
||||
@@ -0,0 +1,151 @@
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.lmm import from_paligemma
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"result, resolution_wh, classes, expected_results",
|
||||
[
|
||||
(
|
||||
"",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # empty response
|
||||
(
|
||||
"",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # empty response with classes
|
||||
(
|
||||
"\n",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # new line response
|
||||
(
|
||||
"the quick brown fox jumps over the lazy dog.",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # response with no location
|
||||
(
|
||||
"<loc0256><loc0768><loc0768> cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # response with missing location
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768><loc0768> cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # response with extra location
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768>",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
), # response with no class
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> catt",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(np.empty((0, 4)), np.empty(0), np.empty(0).astype(str)),
|
||||
), # response with invalid class
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
None,
|
||||
np.array(["cat"]).astype(str),
|
||||
),
|
||||
), # correct response; no classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> black cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
None,
|
||||
np.array(["black cat"]).astype(np.dtype("U")),
|
||||
),
|
||||
), # correct response; class name with space; no classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> black-cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
None,
|
||||
np.array(["black-cat"]).astype(np.dtype("U")),
|
||||
),
|
||||
), # correct response; class name with hyphen; no classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> black_cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
None,
|
||||
np.array(["black_cat"]).astype(np.dtype("U")),
|
||||
),
|
||||
), # correct response; class name with underscore; no classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> cat ;",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
np.array([0]),
|
||||
np.array(["cat"]).astype(str),
|
||||
),
|
||||
), # correct response; with classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> cat ; <loc0256><loc0256><loc0768><loc0768> dog", # noqa: E501
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0], [250.0, 250.0, 750.0, 750.0]]),
|
||||
np.array([0, 1]),
|
||||
np.array(["cat", "dog"]).astype(np.dtype("U")),
|
||||
),
|
||||
), # correct response; with classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> cat ; <loc0256><loc0256><loc0768> cat", # noqa: E501
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
np.array([0]),
|
||||
np.array(["cat"]).astype(str),
|
||||
),
|
||||
), # partially correct response; with classes
|
||||
(
|
||||
"<loc0256><loc0256><loc0768><loc0768> cat ; <loc0256><loc0256><loc0768><loc0768><loc0768> cat", # noqa: E501
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(
|
||||
np.array([[250.0, 250.0, 750.0, 750.0]]),
|
||||
np.array([0]),
|
||||
np.array(["cat"]).astype(str),
|
||||
),
|
||||
), # partially correct response; with classes
|
||||
],
|
||||
)
|
||||
def test_from_paligemma(
|
||||
result: str,
|
||||
resolution_wh: Tuple[int, int],
|
||||
classes: Optional[List[str]],
|
||||
expected_results: Tuple[np.ndarray, Optional[np.ndarray], np.ndarray],
|
||||
) -> None:
|
||||
result = from_paligemma(result=result, resolution_wh=resolution_wh, classes=classes)
|
||||
np.testing.assert_array_equal(result[0], expected_results[0])
|
||||
np.testing.assert_array_equal(result[1], expected_results[1])
|
||||
np.testing.assert_array_equal(result[2], expected_results[2])
|
||||
@@ -0,0 +1,449 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, Optional
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_suppression,
|
||||
group_overlapping_boxes,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 5), dtype=float),
|
||||
0.5,
|
||||
[],
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0]]),
|
||||
0.5,
|
||||
[[0]],
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]),
|
||||
0.5,
|
||||
[[1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # High overlap, tie-break to second det
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 0.99]]),
|
||||
0.5,
|
||||
[[0, 1]],
|
||||
DoesNotRaise(),
|
||||
), # High overlap, merge to high confidence
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 0.99], [0, 0, 9, 9, 1.0]]),
|
||||
0.5,
|
||||
[[1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # (test symmetry) High overlap, merge to high confidence
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 0.90], [0, 0, 9, 9, 1.0]]),
|
||||
0.5,
|
||||
[[1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # (test symmetry) High overlap, merge to high confidence
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]),
|
||||
1.0,
|
||||
[[1], [0]],
|
||||
DoesNotRaise(),
|
||||
), # High IOU required
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]),
|
||||
0.0,
|
||||
[[1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # No IOU required
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 5, 5, 0.9]]),
|
||||
0.25,
|
||||
[[0, 1]],
|
||||
DoesNotRaise(),
|
||||
), # Below IOU requirement
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 5, 5, 0.9]]),
|
||||
0.26,
|
||||
[[0], [1]],
|
||||
DoesNotRaise(),
|
||||
), # Above IOU requirement
|
||||
(
|
||||
np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0], [0, 0, 8, 8, 1.0]]),
|
||||
0.5,
|
||||
[[2, 1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # 3 boxes
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 10, 10, 1.0],
|
||||
[0, 0, 9, 9, 1.0],
|
||||
[5, 5, 10, 10, 1.0],
|
||||
[6, 6, 10, 10, 1.0],
|
||||
[9, 9, 10, 10, 1.0],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
[[4], [3, 2], [1, 0]],
|
||||
DoesNotRaise(),
|
||||
), # 5 boxes, 2 merges, 1 separate
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 2, 1, 1.0],
|
||||
[1, 0, 3, 1, 1.0],
|
||||
[2, 0, 4, 1, 1.0],
|
||||
[3, 0, 5, 1, 1.0],
|
||||
[4, 0, 6, 1, 1.0],
|
||||
]
|
||||
),
|
||||
0.33,
|
||||
[[4, 3], [2, 1], [0]],
|
||||
DoesNotRaise(),
|
||||
), # sequential merge, half overlap
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 2, 1, 0.9],
|
||||
[1, 0, 3, 1, 0.9],
|
||||
[2, 0, 4, 1, 1.0],
|
||||
[3, 0, 5, 1, 0.9],
|
||||
[4, 0, 6, 1, 0.9],
|
||||
]
|
||||
),
|
||||
0.33,
|
||||
[[2, 3, 1], [4], [0]],
|
||||
DoesNotRaise(),
|
||||
), # confidence
|
||||
],
|
||||
)
|
||||
def test_group_overlapping_boxes(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: List[List[int]],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = group_overlapping_boxes(
|
||||
predictions=predictions, iou_threshold=iou_threshold
|
||||
)
|
||||
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 5)),
|
||||
0.5,
|
||||
np.array([]),
|
||||
DoesNotRaise(),
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([[10.0, 10.0, 40.0, 40.0, 0.8]]),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([[10.0, 10.0, 40.0, 40.0, 0.8, 0]]),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single box with category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 1],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with different category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 0],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with same category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, False]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 1],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 2],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with same category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 0],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 1],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with different category
|
||||
],
|
||||
)
|
||||
def test_box_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: Optional[np.ndarray],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = box_non_max_suppression(
|
||||
predictions=predictions, iou_threshold=iou_threshold
|
||||
)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, masks, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty((0, 6)),
|
||||
np.empty((0, 5, 5)),
|
||||
0.5,
|
||||
np.array([]),
|
||||
DoesNotRaise(),
|
||||
), # empty predictions and masks
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8, 0]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks non-overlapping with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.4,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks partially overlapping with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8, 0], [0, 0, 0, 0, 0.9, 1]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks partially overlapping with different category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0.8],
|
||||
[0, 0, 0, 0, 0.85],
|
||||
[0, 0, 0, 0, 0.9],
|
||||
]
|
||||
),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three masks with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0.8, 0],
|
||||
[0, 0, 0, 0, 0.85, 1],
|
||||
[0, 0, 0, 0, 0.9, 2],
|
||||
]
|
||||
),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three masks with different category
|
||||
],
|
||||
)
|
||||
def test_mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: Optional[np.ndarray],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = mask_non_max_suppression(
|
||||
predictions=predictions, masks=masks, iou_threshold=iou_threshold
|
||||
)
|
||||
assert np.array_equal(result, expected_result)
|
||||
@@ -92,3 +92,19 @@ def test_polygon_zone_trigger(
|
||||
with exception:
|
||||
in_zone = polygon_zone.trigger(detections)
|
||||
assert np.all(in_zone == expected_results)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"polygon, triggering_anchors, exception",
|
||||
[
|
||||
(POLYGON, [sv.Position.CENTER], DoesNotRaise()),
|
||||
(
|
||||
POLYGON,
|
||||
[],
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_polygon_zone_initialization(polygon, triggering_anchors, exception):
|
||||
with exception:
|
||||
sv.PolygonZone(polygon, FRAME_RESOLUTION, triggering_anchors=triggering_anchors)
|
||||
+140
-315
@@ -2,16 +2,17 @@ from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
import pytest
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import (
|
||||
box_non_max_suppression,
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_polygons_by_area,
|
||||
get_data_item,
|
||||
mask_non_max_suppression,
|
||||
merge_data,
|
||||
move_boxes,
|
||||
process_roboflow_result,
|
||||
@@ -22,317 +23,6 @@ TEST_MASK = np.zeros((1, 1000, 1000), dtype=bool)
|
||||
TEST_MASK[:, 300:351, 200:251] = True
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 5)),
|
||||
0.5,
|
||||
np.array([]),
|
||||
DoesNotRaise(),
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([[10.0, 10.0, 40.0, 40.0, 0.8]]),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([[10.0, 10.0, 40.0, 40.0, 0.8, 0]]),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single box with category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 1],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with different category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 0],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with same category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, False]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 1],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 2],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with same category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 0],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 1],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three boxes with different category
|
||||
],
|
||||
)
|
||||
def test_box_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: Optional[np.ndarray],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = box_non_max_suppression(
|
||||
predictions=predictions, iou_threshold=iou_threshold
|
||||
)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, masks, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty((0, 6)),
|
||||
np.empty((0, 5, 5)),
|
||||
0.5,
|
||||
np.array([]),
|
||||
DoesNotRaise(),
|
||||
), # empty predictions and masks
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8, 0]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks non-overlapping with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.4,
|
||||
np.array([False, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks partially overlapping with no category
|
||||
(
|
||||
np.array([[0, 0, 0, 0, 0.8, 0], [0, 0, 0, 0, 0.9, 1]]),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True]),
|
||||
DoesNotRaise(),
|
||||
), # two masks partially overlapping with different category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0.8],
|
||||
[0, 0, 0, 0, 0.85],
|
||||
[0, 0, 0, 0, 0.9],
|
||||
]
|
||||
),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([False, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three masks with no category
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0.8, 0],
|
||||
[0, 0, 0, 0, 0.85, 1],
|
||||
[0, 0, 0, 0, 0.9, 2],
|
||||
]
|
||||
),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
]
|
||||
),
|
||||
0.5,
|
||||
np.array([True, True, True]),
|
||||
DoesNotRaise(),
|
||||
), # three masks with different category
|
||||
],
|
||||
)
|
||||
def test_mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: Optional[np.ndarray],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = mask_non_max_suppression(
|
||||
predictions=predictions, masks=masks, iou_threshold=iou_threshold
|
||||
)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, resolution_wh, expected_result",
|
||||
[
|
||||
@@ -1030,8 +720,8 @@ def test_calculate_masks_centroids(
|
||||
), # two data dicts with the same field name and different length arrays values
|
||||
(
|
||||
[{}, {"test_1": [1, 2, 3]}],
|
||||
{"test_1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one empty and one non-empty dict
|
||||
(
|
||||
[{"test_1": [], "test_2": []}, {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}],
|
||||
@@ -1265,3 +955,138 @@ def test_get_data_item(
|
||||
assert (
|
||||
result[key] == expected_result[key]
|
||||
), f"Mismatch in non-array data for key {key}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in one continuous piece
|
||||
(
|
||||
np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 seperate elements
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # no foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # only foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 0], [1, 1, 1, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 1 hole
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 2 holes
|
||||
],
|
||||
)
|
||||
def test_contains_holes(
|
||||
mask: npt.NDArray[np.bool_], expected_result: bool, exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = contains_holes(mask)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, connectivity, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in one continuous piece
|
||||
(
|
||||
np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 seperate elements
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # no foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # only foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 2 holes, but is in single piece
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 elements with respect to 4-way connectivity
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
8,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in single piece with respect to 8-way connectivity
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
5,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Incorrect connectivity parameter value, raises ValueError
|
||||
],
|
||||
)
|
||||
def test_contains_multiple_segments(
|
||||
mask: npt.NDArray[np.bool_],
|
||||
connectivity: int,
|
||||
expected_result: bool,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = contains_multiple_segments(mask=mask, connectivity=connectivity)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,193 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Set
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.utils.internal import get_instance_variables
|
||||
|
||||
|
||||
class MockClass:
|
||||
def __init__(self):
|
||||
self.public = 0
|
||||
self._protected = 1
|
||||
self.__private = 2
|
||||
|
||||
def public_method(self):
|
||||
pass
|
||||
|
||||
def _protected_method(self):
|
||||
pass
|
||||
|
||||
def __private_method(self):
|
||||
pass
|
||||
|
||||
@property
|
||||
def public_property(self):
|
||||
return 0
|
||||
|
||||
@property
|
||||
def _protected_property(self):
|
||||
return 1
|
||||
|
||||
@property
|
||||
def __private_property(self):
|
||||
return 2
|
||||
|
||||
|
||||
@dataclass
|
||||
class MockDataclass:
|
||||
public: int = 0
|
||||
_protected: int = 1
|
||||
__private: int = 2
|
||||
|
||||
public_field: int = field(default=0)
|
||||
_protected_field: int = field(default=1)
|
||||
__private_field: int = field(default=2)
|
||||
|
||||
public_field_with_factory: dict = field(default_factory=dict)
|
||||
_protected_field_with_factory: dict = field(default_factory=dict)
|
||||
__private_field_with_factory: dict = field(default_factory=dict)
|
||||
|
||||
def public_method(self):
|
||||
pass
|
||||
|
||||
def _protected_method(self):
|
||||
pass
|
||||
|
||||
def __private_method(self):
|
||||
pass
|
||||
|
||||
@property
|
||||
def public_property(self):
|
||||
return 0
|
||||
|
||||
@property
|
||||
def _protected_property(self):
|
||||
return 1
|
||||
|
||||
@property
|
||||
def __private_property(self):
|
||||
return 2
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"input_instance, include_properties, expected, exception",
|
||||
[
|
||||
(
|
||||
MockClass,
|
||||
False,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
(
|
||||
MockClass(),
|
||||
False,
|
||||
{"public"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
MockClass(),
|
||||
True,
|
||||
{"public", "public_property"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
MockDataclass(),
|
||||
False,
|
||||
{"public", "public_field", "public_field_with_factory"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
MockDataclass(),
|
||||
True,
|
||||
{"public", "public_field", "public_field_with_factory", "public_property"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
Detections,
|
||||
False,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
(
|
||||
Detections,
|
||||
True,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
(
|
||||
Detections.empty(),
|
||||
False,
|
||||
{"xyxy", "class_id", "confidence", "mask", "tracker_id", "data"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
Detections.empty(),
|
||||
True,
|
||||
{
|
||||
"xyxy",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"mask",
|
||||
"tracker_id",
|
||||
"data",
|
||||
"area",
|
||||
"box_area",
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
Detections(xyxy=np.array([[1, 2, 3, 4]])),
|
||||
False,
|
||||
{
|
||||
"xyxy",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"mask",
|
||||
"tracker_id",
|
||||
"data",
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[1, 2, 3, 4], [5, 6, 7, 8]]),
|
||||
class_id=np.array([1, 2]),
|
||||
confidence=np.array([0.1, 0.2]),
|
||||
mask=np.array([[[1]], [[2]]]),
|
||||
tracker_id=np.array([1, 2]),
|
||||
data={"key_1": [1, 2], "key_2": [3, 4]},
|
||||
),
|
||||
False,
|
||||
{
|
||||
"xyxy",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"mask",
|
||||
"tracker_id",
|
||||
"data",
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
Detections.empty(),
|
||||
False,
|
||||
{"xyxy", "class_id", "confidence", "mask", "tracker_id", "data"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_get_instance_variables(
|
||||
input_instance: Any,
|
||||
include_properties: bool,
|
||||
expected: Set[str],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = get_instance_variables(
|
||||
input_instance, include_properties=include_properties
|
||||
)
|
||||
assert result == expected
|
||||
Reference in new issue
Block a user