Merge branch 'develop' of github.com:jeslinpjames/supervision into RichLabelAnnotator
This commit is contained in:
 Jeslin P James committed
commit
a41eea7c45
21 files changed
+764
-251
No files matched your search
File renamed without changes.
@@ -0,0 +1,55 @@
|
||||
name: Supervision Release Documentation Workflow 📚
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
doc-build-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.head_ref }}
|
||||
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions 👷
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material 📚
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push --update-aliases $latest_tag latest
|
||||
@@ -7,7 +7,7 @@ ci:
|
||||
|
||||
repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.5.0
|
||||
rev: v4.6.0
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
@@ -45,7 +45,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.3.4
|
||||
rev: v0.3.5
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
@@ -217,19 +217,23 @@ len(dataset)
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
Want to learn how to use Supervision? Explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/), [end-to-end examples](https://github.com/roboflow/supervision/tree/develop/examples), and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/)!
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/a742823d-c158-407d-b30f-063a5d11b4e1" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><strong>Dwell Time Analysis with Computer Vision | Real-Time Stream Processing</strong></a>
|
||||
<div><strong>Created: 5 Apr 2024</strong></div>
|
||||
<br/>Learn how to use computer vision to analyze wait times and optimize processes. This tutorial covers object detection, tracking, and calculating time spent in designated zones. Use these techniques to improve customer experience in retail, traffic management, or other scenarios.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
|
||||
@@ -15,7 +15,7 @@ source image.
|
||||
|
||||
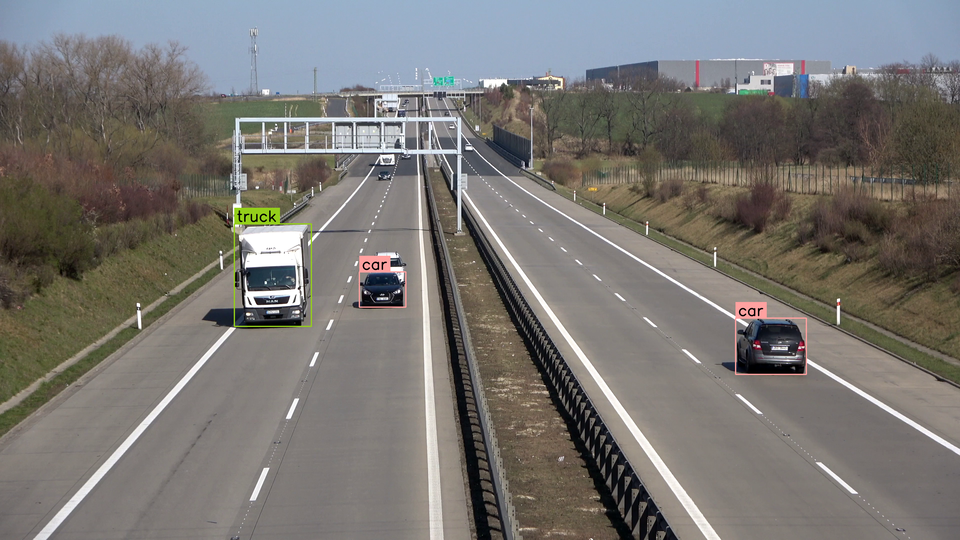
|
||||
|
||||
## Run Inference
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
@@ -0,0 +1,299 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
+16
-10
@@ -5,12 +5,6 @@ status: new
|
||||
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
</div>
|
||||
@@ -18,10 +12,10 @@ status: new
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>letterbox_image</h2>
|
||||
<h2>scale_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
@@ -30,7 +24,19 @@ status: new
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>place_image</h2>
|
||||
<h2>letterbox_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.place_image
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>overlay_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
+3
-23
@@ -1,8 +1,8 @@
|
||||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
Here, you'll find end-to-end examples that show how to solve common computer vision problems using Supervision.
|
||||
|
||||
For more information and examples, visit our [documentation](https://supervision.roboflow.com/develop/annotators/) and explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/) and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/). Join our [Discord](https://discord.com/invite/GbfgXGJ8Bk) and meet other Supervision power users!
|
||||
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
@@ -10,23 +10,3 @@ interfaces with diverse applications.
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
1. Create a pull request (PR) with the `[Example]` prefix in the title, adding your
|
||||
project folder to the `examples/` directory in the repository.
|
||||
2. Confirm your project aligns with the following standards:
|
||||
- Incorporates the `supervision` package.
|
||||
- Provides a `README.md` file, detailing the instructions to execute the project.
|
||||
- Showcases visual results, demonstrating the app's functionality.
|
||||
- Avoids adding large assets or dependencies unless absolutely necessary.
|
||||
- The contributor is expected to provide support for issues related to their
|
||||
examples.
|
||||
- In case the presented model has licensing complications, kindly specify them to
|
||||
circumvent potential misunderstandings.
|
||||
|
||||
For inquiries or concerns about these prerequisites, feel free to raise a PR. We are
|
||||
committed to assist and guide you.
|
||||
@@ -1,5 +1,8 @@
|
||||
# count people in zone
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb)
|
||||
[](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
|
||||
@@ -1,5 +1,7 @@
|
||||
# time in zone
|
||||
|
||||
[](https://www.youtube.com/watch?v=hAWpsIuem10)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
|
||||
+3
-1
@@ -38,9 +38,11 @@ nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
|
||||
Generated
+24
-28
@@ -1122,13 +1122,13 @@ license = ["ukkonen"]
|
||||
|
||||
[[package]]
|
||||
name = "idna"
|
||||
version = "3.6"
|
||||
version = "3.7"
|
||||
description = "Internationalized Domain Names in Applications (IDNA)"
|
||||
optional = false
|
||||
python-versions = ">=3.5"
|
||||
files = [
|
||||
{file = "idna-3.6-py3-none-any.whl", hash = "sha256:c05567e9c24a6b9faaa835c4821bad0590fbb9d5779e7caa6e1cc4978e7eb24f"},
|
||||
{file = "idna-3.6.tar.gz", hash = "sha256:9ecdbbd083b06798ae1e86adcbfe8ab1479cf864e4ee30fe4e46a003d12491ca"},
|
||||
{file = "idna-3.7-py3-none-any.whl", hash = "sha256:82fee1fc78add43492d3a1898bfa6d8a904cc97d8427f683ed8e798d07761aa0"},
|
||||
{file = "idna-3.7.tar.gz", hash = "sha256:028ff3aadf0609c1fd278d8ea3089299412a7a8b9bd005dd08b9f8285bcb5cfc"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -2162,13 +2162,12 @@ pytz = "*"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-jupyter"
|
||||
version = "0.24.3"
|
||||
version = "0.24.7"
|
||||
description = "Use Jupyter in mkdocs websites"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_jupyter-0.24.3-py3-none-any.whl", hash = "sha256:904262a8678a5e5920b7c3c03b5010b36301a69d0a38f2fcbf430493adf6879e"},
|
||||
{file = "mkdocs_jupyter-0.24.3.tar.gz", hash = "sha256:3d81da9aea27480e93bab22438910c4f0b9630613e74f85b576590d78e0e8b14"},
|
||||
{file = "mkdocs_jupyter-0.24.7-py3-none-any.whl", hash = "sha256:893d04bea1e007479a46e4e72852cd4d280c4d358ce4a0445250f3f80c639723"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2179,9 +2178,6 @@ mkdocs-material = ">9.0.0"
|
||||
nbconvert = ">=7.2.9,<8"
|
||||
pygments = ">2.12.0"
|
||||
|
||||
[package.extras]
|
||||
test = ["coverage[toml]", "pymdown-extensions", "pytest", "pytest-cov"]
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.17"
|
||||
@@ -3647,28 +3643,28 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.3.5"
|
||||
version = "0.3.6"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.3.5-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:aef5bd3b89e657007e1be6b16553c8813b221ff6d92c7526b7e0227450981eac"},
|
||||
{file = "ruff-0.3.5-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:89b1e92b3bd9fca249153a97d23f29bed3992cff414b222fcd361d763fc53f12"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:5e55771559c89272c3ebab23326dc23e7f813e492052391fe7950c1a5a139d89"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:dabc62195bf54b8a7876add6e789caae0268f34582333cda340497c886111c39"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:3a05f3793ba25f194f395578579c546ca5d83e0195f992edc32e5907d142bfa3"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:dfd3504e881082959b4160ab02f7a205f0fadc0a9619cc481982b6837b2fd4c0"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:87258e0d4b04046cf1d6cc1c56fadbf7a880cc3de1f7294938e923234cf9e498"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:712e71283fc7d9f95047ed5f793bc019b0b0a29849b14664a60fd66c23b96da1"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:a532a90b4a18d3f722c124c513ffb5e5eaff0cc4f6d3aa4bda38e691b8600c9f"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:122de171a147c76ada00f76df533b54676f6e321e61bd8656ae54be326c10296"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:d80a6b18a6c3b6ed25b71b05eba183f37d9bc8b16ace9e3d700997f00b74660b"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_i686.whl", hash = "sha256:a7b6e63194c68bca8e71f81de30cfa6f58ff70393cf45aab4c20f158227d5936"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:a759d33a20c72f2dfa54dae6e85e1225b8e302e8ac655773aff22e542a300985"},
|
||||
{file = "ruff-0.3.5-py3-none-win32.whl", hash = "sha256:9d8605aa990045517c911726d21293ef4baa64f87265896e491a05461cae078d"},
|
||||
{file = "ruff-0.3.5-py3-none-win_amd64.whl", hash = "sha256:dc56bb16a63c1303bd47563c60482a1512721053d93231cf7e9e1c6954395a0e"},
|
||||
{file = "ruff-0.3.5-py3-none-win_arm64.whl", hash = "sha256:faeeae9905446b975dcf6d4499dc93439b131f1443ee264055c5716dd947af55"},
|
||||
{file = "ruff-0.3.5.tar.gz", hash = "sha256:a067daaeb1dc2baf9b82a32dae67d154d95212080c80435eb052d95da647763d"},
|
||||
{file = "ruff-0.3.6-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:732ef99984275534f9466fbc01121523caf72aa8c2bdeb36fd2edf2bc294a992"},
|
||||
{file = "ruff-0.3.6-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:93699d61116807edc5ca1cdf9d2d22cf8d93335d59e3ff0ca7aee62c1818a736"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:fc4006cbc6c11fefc25f122d2eb4731d7a3d815dc74d67c54991cc3f99c90177"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:878ef1a55ce931f3ca23b690b159cd0659f495a4c231a847b00ca55e4c688baf"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:ecb87788284af96725643eae9ab3ac746d8cc09aad140268523b019f7ac3cd98"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:b2e79f8e1b6bd5411d7ddad3f2abff3f9d371beda29daef86400d416dedb7e02"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:cf48ec2c4bfae7837dc325c431a2932dc23a1485e71c59591c1df471ba234e0e"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:c466a52c522e6a08df0af018f550902f154f5649ad09e7f0d43da766e7399ebc"},
|
||||
{file = "ruff-0.3.6-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:28ccf3fb6d1162a73cd286c63a5e4d885f46a1f99f0b392924bc95ccbd18ea8f"},
|
||||
{file = "ruff-0.3.6-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:b11e09439d9df6cc12d9f622065834654417c40216d271f639512d80e80e3e53"},
|
||||
{file = "ruff-0.3.6-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:647f1fb5128a3e24ce68878b8050bb55044c45bb3f3ae4710d4da9ca96ede5cb"},
|
||||
{file = "ruff-0.3.6-py3-none-musllinux_1_2_i686.whl", hash = "sha256:2b0c4c70578ef1871a9ac5c85ed7a8c33470e976c73ba9211a111d2771b5f787"},
|
||||
{file = "ruff-0.3.6-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:e3da499ded004d0b956ab04248b2ae17e54a67ffc81353514ac583af5959a255"},
|
||||
{file = "ruff-0.3.6-py3-none-win32.whl", hash = "sha256:4056480f5cf38ad278667c31b0ef334c29acdfcea617cb89c4ccbc7d96f1637f"},
|
||||
{file = "ruff-0.3.6-py3-none-win_amd64.whl", hash = "sha256:f1aa621beed533f46e9c7d6fe00e7f6e4570155b61d8f020387b72ace2b42e04"},
|
||||
{file = "ruff-0.3.6-py3-none-win_arm64.whl", hash = "sha256:7c8a2a0e0cab077a07465259ffe3b3c090e747ca8097c5dc4c36ca0fdaaac90d"},
|
||||
{file = "ruff-0.3.6.tar.gz", hash = "sha256:26071fb530038602b984e3bbe1443ef82a38450c4dcb1344a9caf67234ff9756"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
||||
@@ -71,15 +71,16 @@ from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
place_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
|
||||
@@ -14,7 +14,7 @@ from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.image import crop_image, place_image, resize_image
|
||||
from supervision.utils.image import crop_image, overlay_image, scale_image
|
||||
|
||||
|
||||
class BoundingBoxAnnotator(BaseAnnotator):
|
||||
@@ -2110,7 +2110,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
crop_image(image=scene, xyxy=xyxy) for xyxy in detections.xyxy.astype(int)
|
||||
]
|
||||
resized_crops = [
|
||||
resize_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
scale_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
]
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
@@ -2119,7 +2119,9 @@ class CropAnnotator(BaseAnnotator):
|
||||
(x1, y1), (x2, y2) = self.calculate_crop_coordinates(
|
||||
anchor=anchor, crop_wh=crop_wh, position=self.position
|
||||
)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=(x1, y1))
|
||||
scene = overlay_image(
|
||||
scene=scene, inserted_image=resized_crop, anchor=(x1, y1)
|
||||
)
|
||||
color = resolve_color(
|
||||
color=self.border_color,
|
||||
detections=detections,
|
||||
|
||||
@@ -18,6 +18,7 @@ class VideoAssets(Enum):
|
||||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
| `BEACH` | `beach-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/beach-1.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
@@ -27,6 +28,7 @@ class VideoAssets(Enum):
|
||||
SUBWAY = "subway.mp4"
|
||||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
BEACH = "beach-1.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
@@ -62,4 +64,8 @@ VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.PEOPLE_WALKING.value}",
|
||||
"0574c053c8686c3f1dc0aa3743e45cb9",
|
||||
),
|
||||
VideoAssets.BEACH.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BEACH.value}",
|
||||
"4175d42fec4d450ed081523fd39e0cf8",
|
||||
),
|
||||
}
|
||||
@@ -1,3 +1,4 @@
|
||||
import warnings
|
||||
from dataclasses import replace
|
||||
from typing import Iterable, Optional, Tuple
|
||||
|
||||
@@ -11,7 +12,7 @@ from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.utils.internal import deprecated_parameter
|
||||
from supervision.utils.internal import SupervisionWarnings, deprecated_parameter
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
@@ -21,7 +22,6 @@ class PolygonZone:
|
||||
Attributes:
|
||||
polygon (np.ndarray): A polygon represented by a numpy array of shape
|
||||
`(N, 2)`, containing the `x`, `y` coordinates of the points.
|
||||
frame_resolution_wh (Tuple[int, int]): The frame resolution (width, height)
|
||||
triggering_anchors (Iterable[sv.Position]): A list of positions specifying
|
||||
which anchors of the detections bounding box to consider when deciding on
|
||||
whether the detection fits within the PolygonZone
|
||||
@@ -41,18 +41,26 @@ class PolygonZone:
|
||||
def __init__(
|
||||
self,
|
||||
polygon: npt.NDArray[np.int64],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
frame_resolution_wh: Optional[Tuple[int, int]] = None,
|
||||
triggering_anchors: Iterable[Position] = (Position.BOTTOM_CENTER,),
|
||||
):
|
||||
if frame_resolution_wh is not None:
|
||||
warnings.warn(
|
||||
"The `frame_resolution_wh` parameter is no longer required and will be "
|
||||
"dropped in version supervision-0.24.0. The mask resolution is now "
|
||||
"calculated automatically based on the polygon coordinates.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
|
||||
self.polygon = polygon.astype(int)
|
||||
self.frame_resolution_wh = frame_resolution_wh
|
||||
self.triggering_anchors = triggering_anchors
|
||||
|
||||
self.current_count = 0
|
||||
|
||||
width, height = frame_resolution_wh
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
self.frame_resolution_wh = (x_max + 1, y_max + 1)
|
||||
self.mask = polygon_to_mask(
|
||||
polygon=polygon, resolution_wh=(width + 1, height + 1)
|
||||
polygon=polygon, resolution_wh=(x_max + 2, y_max + 2)
|
||||
)
|
||||
|
||||
def trigger(self, detections: Detections) -> npt.NDArray[np.bool_]:
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple
|
||||
from typing import List, Tuple, Union
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
@@ -448,3 +448,19 @@ class ColorPalette:
|
||||
raise ValueError("idx argument should not be negative")
|
||||
idx = idx % len(self.colors)
|
||||
return self.colors[idx]
|
||||
|
||||
|
||||
def unify_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
"""
|
||||
Converts a color input in multiple formats to a standardized BGR format.
|
||||
|
||||
Args:
|
||||
color (Union[Tuple[int, int, int], Color]): The color input to be converted,
|
||||
which can be either a tuple of RGB values or an instance of a Color class.
|
||||
|
||||
Returns:
|
||||
Tuple[int, int, int]: The color in BGR format as a tuple of three integers.
|
||||
"""
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
@@ -81,7 +81,7 @@ def pillow_to_cv2(image: Image.Image) -> np.ndarray:
|
||||
image (Image.Image): Pillow image (in RGB format).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Input image converted to OpenCV format.
|
||||
(np.ndarray): Input image converted to OpenCV format.
|
||||
"""
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
@@ -97,7 +97,7 @@ def cv2_to_pillow(image: np.ndarray) -> Image.Image:
|
||||
image (np.ndarray): OpenCV image (in BGR format).
|
||||
|
||||
Returns:
|
||||
Image.Image: Input image converted to Pillow format.
|
||||
(Image.Image): Input image converted to Pillow format.
|
||||
"""
|
||||
image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)
|
||||
return Image.fromarray(image)
|
||||
+283
-148
@@ -7,9 +7,10 @@ from typing import Callable, List, Literal, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.color import Color, unify_to_bgr
|
||||
from supervision.draw.utils import calculate_optimal_text_scale, draw_text
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.utils.conversion import (
|
||||
@@ -25,103 +26,326 @@ MAX_COLUMNS_FOR_SINGLE_ROW_GRID = 3
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def crop_image(image: np.ndarray, xyxy: np.ndarray) -> np.ndarray:
|
||||
def crop_image(
|
||||
image: ImageType,
|
||||
xyxy: Union[npt.NDArray[int], List[int], Tuple[int, int, int, int]],
|
||||
) -> ImageType:
|
||||
"""
|
||||
Crops the given image based on the given bounding box.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be cropped, represented as a numpy array.
|
||||
xyxy (np.ndarray): A numpy array containing the bounding box coordinates
|
||||
in the format (x1, y1, x2, y2).
|
||||
image (ImageType): The image to be cropped. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
xyxy (Union[np.ndarray, List[int], Tuple[int, int, int, int]]): A bounding box
|
||||
coordinates in the format `(x_min, y_min, x_max, y_max)`, accepted as either
|
||||
a `numpy.ndarray`, a `list`, or a `tuple`.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The cropped image as a numpy array.
|
||||
(ImageType): The cropped image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
detection = sv.Detections(...)
|
||||
with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
for xyxy in detection.xyxy:
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
sink.save_image(image=cropped_image)
|
||||
```
|
||||
"""
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.shape
|
||||
# (400, 400, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.size
|
||||
# (400, 400)
|
||||
```
|
||||
|
||||
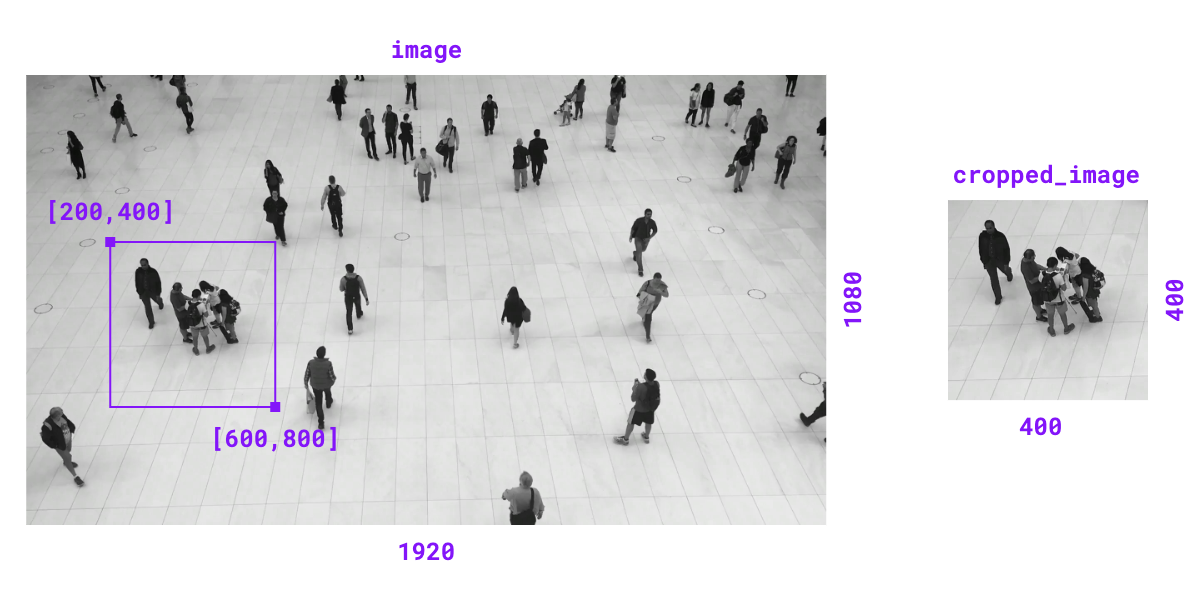{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if isinstance(xyxy, (list, tuple)):
|
||||
xyxy = np.array(xyxy)
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return image[y1:y2, x1:x2]
|
||||
x_min, y_min, x_max, y_max = xyxy.flatten()
|
||||
return image[y_min:y_max, x_min:x_max]
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image(image: np.ndarray, scale_factor: float) -> np.ndarray:
|
||||
def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
"""
|
||||
Resizes an image by a given scale factor using cv2.INTER_LINEAR interpolation.
|
||||
Scales the given image based on the given scale factor.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The input image to be resized.
|
||||
image (ImageType): The image to be scaled. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale
|
||||
factor > 1.0 zooms in, < 1.0 zooms out.
|
||||
factor > `1.0` zooms in, < `1.0` zooms out.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The resized image.
|
||||
(ImageType): The scaled image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Raises:
|
||||
ValueError: If the scale factor is non-positive.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.shape
|
||||
# (540, 960, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.size
|
||||
# (960, 540)
|
||||
```
|
||||
"""
|
||||
if scale_factor <= 0:
|
||||
raise ValueError("Scale factor must be positive.")
|
||||
|
||||
old_width, old_height = image.shape[1], image.shape[0]
|
||||
nwe_width = int(old_width * scale_factor)
|
||||
new_height = int(old_height * scale_factor)
|
||||
|
||||
return cv2.resize(image, (nwe_width, new_height), interpolation=cv2.INTER_LINEAR)
|
||||
width_old, height_old = image.shape[1], image.shape[0]
|
||||
width_new = int(width_old * scale_factor)
|
||||
height_new = int(height_old * scale_factor)
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
def place_image(
|
||||
scene: np.ndarray, image: np.ndarray, anchor: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def resize_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
keep_aspect_ratio: bool = False,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes the given image to a specified resolution. Can maintain the original aspect
|
||||
ratio or resize directly to the desired dimensions.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool, optional): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.shape
|
||||
# (562, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.size
|
||||
# (1000, 562)
|
||||
```
|
||||
|
||||
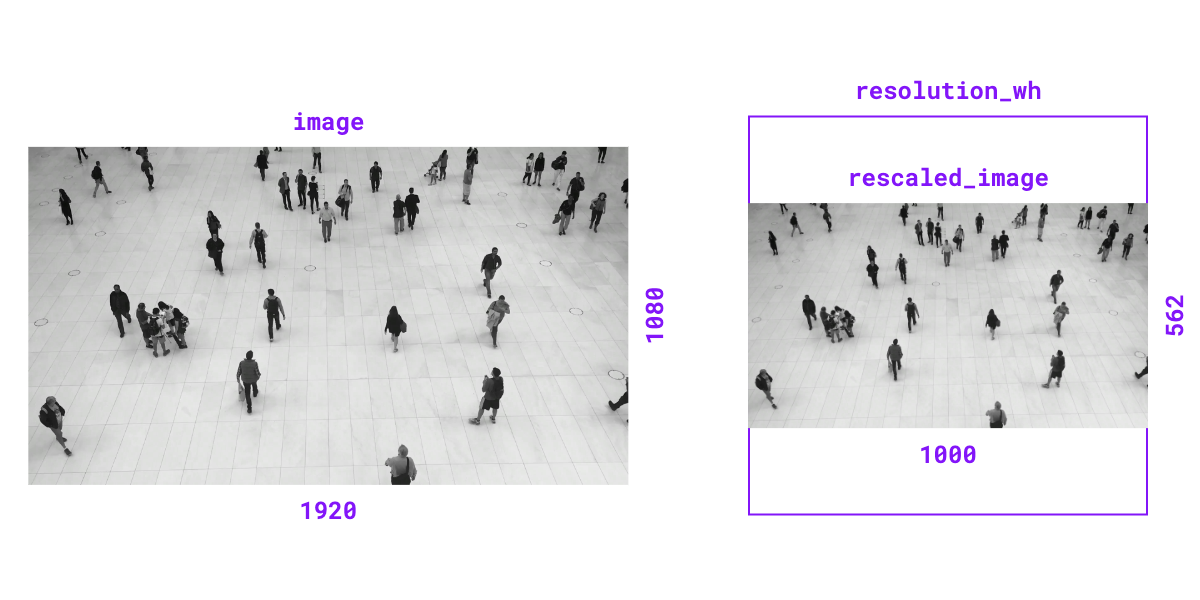{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if keep_aspect_ratio:
|
||||
image_ratio = image.shape[1] / image.shape[0]
|
||||
target_ratio = resolution_wh[0] / resolution_wh[1]
|
||||
if image_ratio >= target_ratio:
|
||||
width_new = resolution_wh[0]
|
||||
height_new = int(resolution_wh[0] / image_ratio)
|
||||
else:
|
||||
height_new = resolution_wh[1]
|
||||
width_new = int(resolution_wh[1] * image_ratio)
|
||||
else:
|
||||
width_new, height_new = resolution_wh
|
||||
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = Color.BLACK,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes and pads an image to a specified resolution with a given color, maintaining
|
||||
the original aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
color (Union[Tuple[int, int, int], Color]): The color to pad with. If tuple
|
||||
provided it should be in BGR format.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.shape
|
||||
# (1000, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.size
|
||||
# (1000, 1000)
|
||||
```
|
||||
|
||||
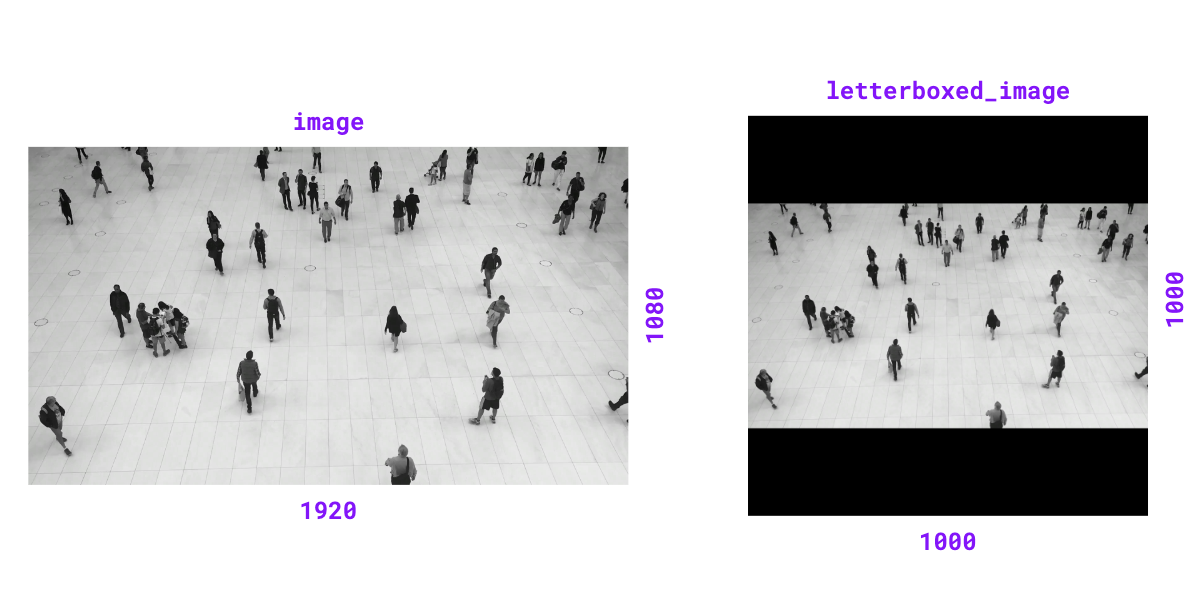{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
color = unify_to_bgr(color=color)
|
||||
resized_image = resize_image(
|
||||
image=image, resolution_wh=resolution_wh, keep_aspect_ratio=True
|
||||
)
|
||||
height_new, width_new = resized_image.shape[:2]
|
||||
padding_top = (resolution_wh[1] - height_new) // 2
|
||||
padding_bottom = resolution_wh[1] - height_new - padding_top
|
||||
padding_left = (resolution_wh[0] - width_new) // 2
|
||||
padding_right = resolution_wh[0] - width_new - padding_left
|
||||
return cv2.copyMakeBorder(
|
||||
resized_image,
|
||||
padding_top,
|
||||
padding_bottom,
|
||||
padding_left,
|
||||
padding_right,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
overlay: npt.NDArray[np.uint8],
|
||||
anchor: Tuple[int, int],
|
||||
) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
Places an image onto a scene at a given anchor point, handling cases where
|
||||
the image's position is partially or completely outside the scene's bounds.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The background scene onto which the image is placed.
|
||||
image (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The (x, y) coordinates in the scene where the
|
||||
image (np.ndarray): The background scene onto which the image is placed.
|
||||
overlay (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The `(x, y)` coordinates in the scene where the
|
||||
top-left corner of the image will be placed.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The modified scene with the image placed at the anchor point,
|
||||
or unchanged if the image placement is completely outside the scene.
|
||||
"""
|
||||
scene_height, scene_width = scene.shape[:2]
|
||||
image_height, image_width = image.shape[:2]
|
||||
(np.ndarray): The result image with overlay.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
overlay = np.zeros((400, 400, 3), dtype=np.uint8)
|
||||
result_image = sv.overlay_image(image=image, overlay=overlay, anchor=(200, 400))
|
||||
```
|
||||
|
||||
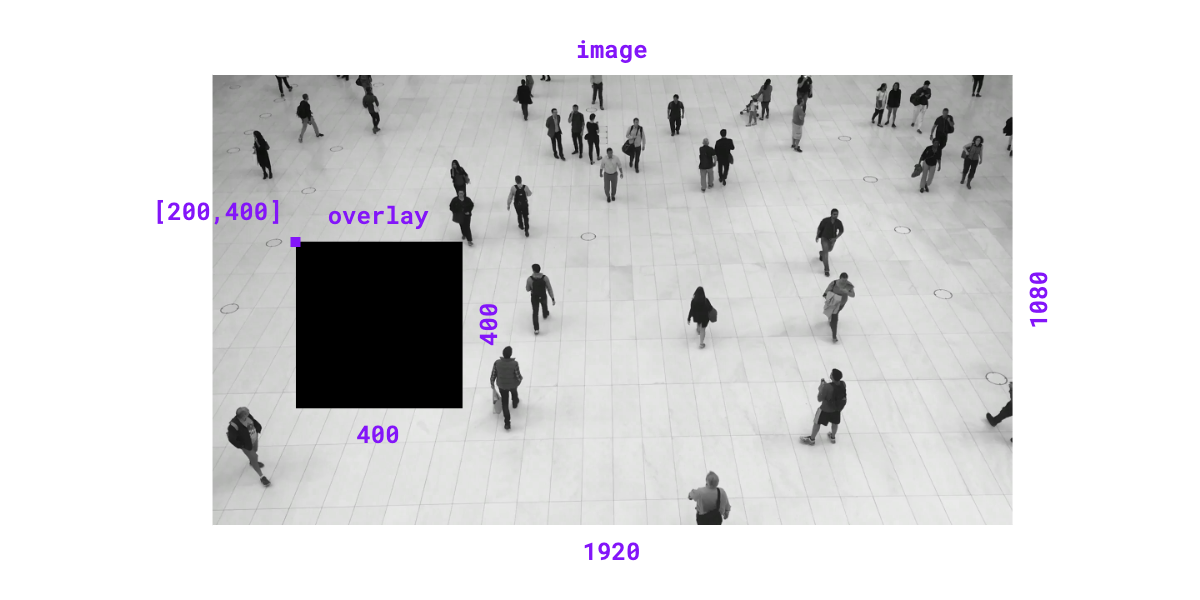{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
scene_height, scene_width = image.shape[:2]
|
||||
image_height, image_width = overlay.shape[:2]
|
||||
anchor_x, anchor_y = anchor
|
||||
|
||||
is_out_horizontally = anchor_x + image_width <= 0 or anchor_x >= scene_width
|
||||
is_out_vertically = anchor_y + image_height <= 0 or anchor_y >= scene_height
|
||||
|
||||
if is_out_horizontally or is_out_vertically:
|
||||
return scene
|
||||
return image
|
||||
|
||||
start_y = max(anchor_y, 0)
|
||||
start_x = max(anchor_x, 0)
|
||||
end_y = min(scene_height, anchor_y + image_height)
|
||||
end_x = min(scene_width, anchor_x + image_width)
|
||||
x_min = max(anchor_x, 0)
|
||||
y_min = max(anchor_y, 0)
|
||||
x_max = min(scene_width, anchor_x + image_width)
|
||||
y_max = min(scene_height, anchor_y + image_height)
|
||||
|
||||
crop_start_y = max(-anchor_y, 0)
|
||||
crop_start_x = max(-anchor_x, 0)
|
||||
crop_end_y = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
crop_end_x = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_x_min = max(-anchor_x, 0)
|
||||
crop_y_min = max(-anchor_y, 0)
|
||||
crop_x_max = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_y_max = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
|
||||
scene[start_y:end_y, start_x:end_x] = image[
|
||||
crop_start_y:crop_end_y, crop_start_x:crop_end_x
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
|
||||
return scene
|
||||
return image
|
||||
|
||||
|
||||
class ImageSink:
|
||||
@@ -145,13 +369,13 @@ class ImageSink:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
with sv.ImageSink(target_dir_path='target/directory/path',
|
||||
overwrite=True) as sink:
|
||||
for image in sv.get_video_frames_generator(
|
||||
source_path='source_video.mp4', stride=2):
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>, stride=2)
|
||||
|
||||
with sv.ImageSink(target_dir_path=<TARGET_CROPS_DIRECTORY>) as sink:
|
||||
for image in frames_generator:
|
||||
sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
""" # noqa E501 // docs
|
||||
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
@@ -285,14 +509,14 @@ def create_tiles(
|
||||
raise ValueError("Could not create image tiles from empty list of images.")
|
||||
if return_type == "auto":
|
||||
return_type = _negotiate_tiles_format(images=images)
|
||||
tile_padding_color = _color_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = _color_to_bgr(color=tile_margin_color)
|
||||
tile_padding_color = unify_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = unify_to_bgr(color=tile_margin_color)
|
||||
images = images_to_cv2(images=images)
|
||||
if single_tile_size is None:
|
||||
single_tile_size = _aggregate_images_shape(images=images, mode=tile_scaling)
|
||||
resized_images = [
|
||||
letterbox_image(
|
||||
image=i, desired_size=single_tile_size, color=tile_padding_color
|
||||
image=i, resolution_wh=single_tile_size, color=tile_padding_color
|
||||
)
|
||||
for i in images
|
||||
]
|
||||
@@ -311,8 +535,8 @@ def create_tiles(
|
||||
titles_anchors = fill(
|
||||
sequence=titles_anchors, desired_size=len(images), content=None
|
||||
)
|
||||
titles_color = _color_to_bgr(color=titles_color)
|
||||
titles_background_color = _color_to_bgr(color=titles_background_color)
|
||||
titles_color = unify_to_bgr(color=titles_color)
|
||||
titles_background_color = unify_to_bgr(color=titles_background_color)
|
||||
tiles = _generate_tiles(
|
||||
images=resized_images,
|
||||
grid_size=grid_size,
|
||||
@@ -542,92 +766,3 @@ def _generate_color_image(
|
||||
shape: Tuple[int, int], color: Tuple[int, int, int]
|
||||
) -> np.ndarray:
|
||||
return np.ones(shape[::-1] + (3,), dtype=np.uint8) * color
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = (0, 0, 0),
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image to fit the desired size, preserving its aspect
|
||||
ratio, adding padding of given color if needed to maintain aspect ratio.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
desired_size (Tuple[int, int]): image size (width, height) representing
|
||||
the target dimensions.
|
||||
color (Union[Tuple[int, int, int], Color]): the color to pad with - If
|
||||
tuple provided - should be BGR.
|
||||
|
||||
Returns:
|
||||
np.ndarray: letterboxed image (type may be adjusted to PIL.Image by
|
||||
decorator if function was called with PIL.Image)
|
||||
"""
|
||||
color = _color_to_bgr(color=color)
|
||||
resized_img = resize_image_keeping_aspect_ratio(
|
||||
image=image,
|
||||
desired_size=desired_size,
|
||||
)
|
||||
new_height, new_width = resized_img.shape[:2]
|
||||
top_padding = (desired_size[1] - new_height) // 2
|
||||
bottom_padding = desired_size[1] - new_height - top_padding
|
||||
left_padding = (desired_size[0] - new_width) // 2
|
||||
right_padding = desired_size[0] - new_width - left_padding
|
||||
return cv2.copyMakeBorder(
|
||||
resized_img,
|
||||
top_padding,
|
||||
bottom_padding,
|
||||
left_padding,
|
||||
right_padding,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image_keeping_aspect_ratio(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image preserving its aspect ratio.
|
||||
|
||||
For example: input image is (640, 480) and we want to resize into
|
||||
(1024, 1024). If this rectangular image is just resized naively
|
||||
to square-shape output - aspect ratio would be altered. If we do not
|
||||
want this to happen - we may resize bigger dimension (640) to 1024.
|
||||
Ratio of change is 1.6. This ratio is later on used to calculate scaling
|
||||
in the other dimension. As a result we have (1024, 768) image.
|
||||
|
||||
Parameters:
|
||||
- image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
- desired_size (Tuple[int, int]): image size (width, height) representing the
|
||||
target dimensions. Parameter will be used to dictate maximum size of
|
||||
output image. Output size may be smaller - to preserve aspect ratio of original
|
||||
image.
|
||||
|
||||
Returns:
|
||||
np.ndarray: resized image (type may be adjusted to PIL.Image by decorator
|
||||
if function was called with PIL.Image)
|
||||
"""
|
||||
if image.shape[:2] == desired_size[::-1]:
|
||||
return image
|
||||
img_ratio = image.shape[1] / image.shape[0]
|
||||
desired_ratio = desired_size[0] / desired_size[1]
|
||||
if img_ratio >= desired_ratio:
|
||||
new_width = desired_size[0]
|
||||
new_height = int(desired_size[0] / img_ratio)
|
||||
else:
|
||||
new_height = desired_size[1]
|
||||
new_width = int(desired_size[1] * img_ratio)
|
||||
return cv2.resize(image, (new_width, new_height))
|
||||
|
||||
|
||||
def _color_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
@@ -16,7 +16,7 @@ def create_batches(
|
||||
batch_size (int): The expected size of a batch.
|
||||
|
||||
Returns:
|
||||
Generator[List[V], None, None]: A generator that yields chunks
|
||||
(Generator[List[V], None, None]): A generator that yields chunks
|
||||
of `sequence` of size `batch_size`, up to the length of
|
||||
the input `sequence`.
|
||||
|
||||
@@ -54,7 +54,7 @@ def fill(sequence: List[V], desired_size: int, content: V) -> List[V]:
|
||||
`sequence` as padding.
|
||||
|
||||
Returns:
|
||||
List[V]: A padded version of the input `sequence` (if needed).
|
||||
(List[V]): A padded version of the input `sequence` (if needed).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
|
||||
+11
-13
@@ -5,22 +5,19 @@ import pytest
|
||||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision import Color, Point
|
||||
from supervision.utils.image import (
|
||||
create_tiles,
|
||||
letterbox_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
)
|
||||
from supervision.utils.image import create_tiles, letterbox_image, resize_image
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
||||
def test_resize_image_for_opencv_image() -> None:
|
||||
# given
|
||||
image = np.zeros((480, 640, 3), dtype=np.uint8)
|
||||
expected_result = np.zeros((768, 1024, 3), dtype=np.uint8)
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -29,15 +26,16 @@ def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
||||
), "Expected output shape to be (w, h): (1024, 768)"
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_pillow_image() -> None:
|
||||
def test_resize_image_for_pillow_image() -> None:
|
||||
# given
|
||||
image = Image.new(mode="RGB", size=(640, 480), color=(0, 0, 0))
|
||||
expected_result = Image.new(mode="RGB", size=(1024, 768), color=(0, 0, 0))
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -62,7 +60,7 @@ def test_letterbox_image_for_opencv_image() -> None:
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -88,7 +86,7 @@ def test_letterbox_image_for_pillow_image() -> None:
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
|
||||
Reference in new issue
Block a user