How To: Benchmark Model
* Initial version of model benchmarking guide
This commit is contained in:
 LinasKo committed
1 parent
60b9b716e9
commit
d1c8adb33a
2 files changed
+335
No files matched your search
@@ -0,0 +1,334 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Benchmark a Model
|
||||
|
||||
## Overview
|
||||
|
||||
Have you ever trained multiple object detection models and wondered which one performs best on your specific use case? Or maybe you've downloaded a pre-trained model and want to verify its performance on your dataset? Model benchmarking is essential for making informed decisions about which model to deploy in production.
|
||||
|
||||
This guide will show an easy way to benchmark your results using `supervision`. It will go over:
|
||||
|
||||
1. [Loading a dataset](#loading-a-dataset)
|
||||
2. [Loading a model](#loading-a-model)
|
||||
3. [Benchmarking Basics](#benchmarking-basics)
|
||||
4. [Visual Benchmarking](#visual-benchmarking)
|
||||
5. [Metric: Mean Average Precision (mAP)](#metric-mean-average-precision-map)
|
||||
6. [Metric: F1 Score](#metric-f1-score)
|
||||
7. [Bonus: Model Leaderboard](#model-leaderboard)
|
||||
|
||||
This guide applies to object detection, instance segmentation, and oriented bounding box models (OBB).
|
||||
|
||||
## Loading a Dataset
|
||||
|
||||
Suppose you start with a dataset. Perhaps you found it on [Universe](https://universe.roboflow.com/); perhaps you [labeled your own](https://roboflow.com/how-to-label/yolo11). In either case, this guide assumes you have a dataset with labels in your [Roboflow Workspace](https://app.roboflow.com/).
|
||||
|
||||
Let's use the following libraries:
|
||||
|
||||
- `roboflow` to manage the dataset and deploy models
|
||||
- `inference` to run the models
|
||||
- `supervision` to evaluate the model results
|
||||
|
||||
```bash
|
||||
pip install roboflow inference supervision
|
||||
```
|
||||
|
||||
Here's how you can download a dataset:
|
||||
|
||||
```python
|
||||
from roboflow import Roboflow
|
||||
|
||||
rf = Roboflow(api_key="<YOUR_API_KEY>")
|
||||
project = rf.workspace("<WORKSPACE_NAME>").project("<PROJECT_NAME>")
|
||||
dataset = project.version(<DATASET_VERSION_NUMBER>).download("<FORMAT>")
|
||||
```
|
||||
|
||||
In this guide, we shall use the [car part segmentation dataset](https://universe.roboflow.com/alpaco5-f3woi/part-autolabeld).
|
||||
|
||||
```python
|
||||
from roboflow import Roboflow
|
||||
|
||||
rf = Roboflow(api_key="<YOUR_API_KEY>")
|
||||
project = rf.workspace("alpaco5-f3woi").project("part-autolabeld")
|
||||
dataset = project.version(5).download("yolov11")
|
||||
```
|
||||
|
||||
This will create a folder called `part-autolabeld` with the dataset in the current working directory, with `train`, `test`, and `valid` folders and `data.yaml` file.
|
||||
|
||||
## Loading a Model
|
||||
|
||||
Let's load a single model, and see how to evaluate it. To evaluate another, simply return to this step.
|
||||
|
||||
=== "Pretrained Model"
|
||||
|
||||
Roboflow supports a range of state-of-the-art [pre-trained models](https://inference.roboflow.com/quickstart/aliases/) for object detection, instance segmentation, and pose tracking. You don't even need an API key!
|
||||
|
||||
Let's load such a model with inference [`inference`](https://inference.roboflow.com/).
|
||||
|
||||
```python
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov11s-640")
|
||||
```
|
||||
|
||||
=== "Trained on Roboflow Platform"
|
||||
|
||||
You can train and deploy a model without leaving the Roboflow platform. See this [guide](https://docs.roboflow.com/train/train/train-from-scratch) for more details.
|
||||
|
||||
To load a model, you can use inference:
|
||||
|
||||
```python
|
||||
from inference import get_model
|
||||
|
||||
model_id = "<PROJECT_NAME>/<MODEL_VERSION>"
|
||||
model = get_model(model_id=model_id)
|
||||
```
|
||||
|
||||
=== "Locally Trained Model"
|
||||
|
||||
To train a model locally, we can use ultralytics. Run the following code in your terminal. Note that it applies to segmentation, but can also be used for object detection and oriented bounding box models, if you change `task` and `model` arguments.
|
||||
|
||||
```bash
|
||||
pip install ultralytics
|
||||
yolo task=segment mode=train model=yolo11s-seg.pt data=part-autolabeld/data.yaml epochs=10 imgsz=640
|
||||
```
|
||||
|
||||
Once the model is trained, you can deploy it to Roboflow, making it available anywhere.
|
||||
|
||||
Note: if using other model types, change to `-obb` or remove suffix in `model_type` and replace `segment` with `obb`or `detect`. Multiple runs also produce multiple folders such as `segment`, `segment1`, `segment2`, etc.
|
||||
|
||||
```python
|
||||
project.version(dataset.version).deploy(
|
||||
model_type="yolov11-seg", model_path=f"runs/segment/train/weights/best.pt"
|
||||
)
|
||||
|
||||
from inference import get_model
|
||||
model_id = project.id.split("/")[1] + "/" + dataset.version
|
||||
model = get_model(model_id=model_id)
|
||||
```
|
||||
|
||||
## Benchmarking Basics
|
||||
|
||||
Evaluating your model requires careful selection of the dataset. Which images should you use?Let's go over the different subsets of a dataset.
|
||||
|
||||
- **Training Set**: This is the set of images used to train the model. Since the model learns to maximize its accuracy on this set, it should **never** be used for validation - the results will seem unrealistically good.
|
||||
- **Validation Set**: This is the set of images used to validate the model during training. Every Nth training epoch, the model is evaluated on the validation set. Often the training is stopped once the validation loss stops improving. Therefore, even while the images aren't used to train the model, it still influences the training outcome.
|
||||
- **Test Set**: This is the set of images kept aside for model testing. It is exactly the set you should use for benchmarking. If the dataset was split correctly, none of these images would be shown to the model during training.
|
||||
|
||||
Therefore, the `test` set is the best choice for benchmarking.
|
||||
Several other problems may arise:
|
||||
|
||||
- **Data Contamination**: It's possible that the dataset was not split correctly and some images from the test set were used during training. In this case, the results will be overly optimistic. It also covers the case where **very similar** images were used for training and testing - e.g. those taken in the same environment.
|
||||
- **Missing Test Set**: Some datasets do not come with a test set. In this case, you should collect and [label](https://roboflow.com/annotate) your own data. Alternatively, a validation set could be used, but the results could be overly optimistic. Make sure to test in the real world asap.
|
||||
|
||||
## Running a Model
|
||||
|
||||
At this stage, we should have:
|
||||
|
||||
- A set of labeled images we'll use to evaluate the model.
|
||||
- The model we wish to benchmark.
|
||||
|
||||
Let's run the model and obtain the predictions.
|
||||
We'll use `supervision` to iterate over the images.
|
||||
|
||||
=== "Roboflow Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model.infer(image)[0]
|
||||
predictions = sv.Detections.from_inference(result)
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model(image)[0]
|
||||
predictions = sv.Detections.from_ultralytics(result)
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
## Visualizing Predictions
|
||||
|
||||
The first step in evaluating your model’s performance is to visualize its predictions.
|
||||
This gives an intuitive sense of how well your model is detecting objects and where it might be failing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
N = 9
|
||||
GRID_SIZE = (3, 3)
|
||||
|
||||
box_annotator_predictions = sv.BoxAnnotator(color=sv.Color.BLUE)
|
||||
box_annotator_targets = sv.BoxAnnotator(color=sv.Color.GREEN)
|
||||
|
||||
annotated_images = []
|
||||
for image_path, predictions, targets in zip(
|
||||
image_paths[:N], predictions_list[:N], targets_list[:N]
|
||||
):
|
||||
annotated_image = cv2.imread(image_path)
|
||||
annotated_image = box_annotator_targets.annotate(
|
||||
scene=annotated_image, detections=targets
|
||||
)
|
||||
annotated_image = box_annotator_predictions.annotate(
|
||||
scene=annotated_image, detections=predictions
|
||||
)
|
||||
|
||||
sv.plot_images_grid(images=annotated_images, grid_size=GRID_SIZE)
|
||||
```
|
||||
|
||||
<!-- TODO: grid example -->
|
||||
|
||||
!!! tip
|
||||
|
||||
Use `sv.MaskAnnotator` for segmentation and `sv.OrientedBoxAnnotator` for OBB.
|
||||
|
||||
See [annotator documentation](https://supervision.roboflow.com/latest/detection/annotators/) for more details.
|
||||
|
||||
## Benchmarking Metrics
|
||||
|
||||
With multiple models, fine details matter. Visual inspection may not be enough. `supervision` provides a collection of metrics that help obtain precise numerical results of model performance.
|
||||
|
||||
### Mean Average Precision (mAP)
|
||||
|
||||
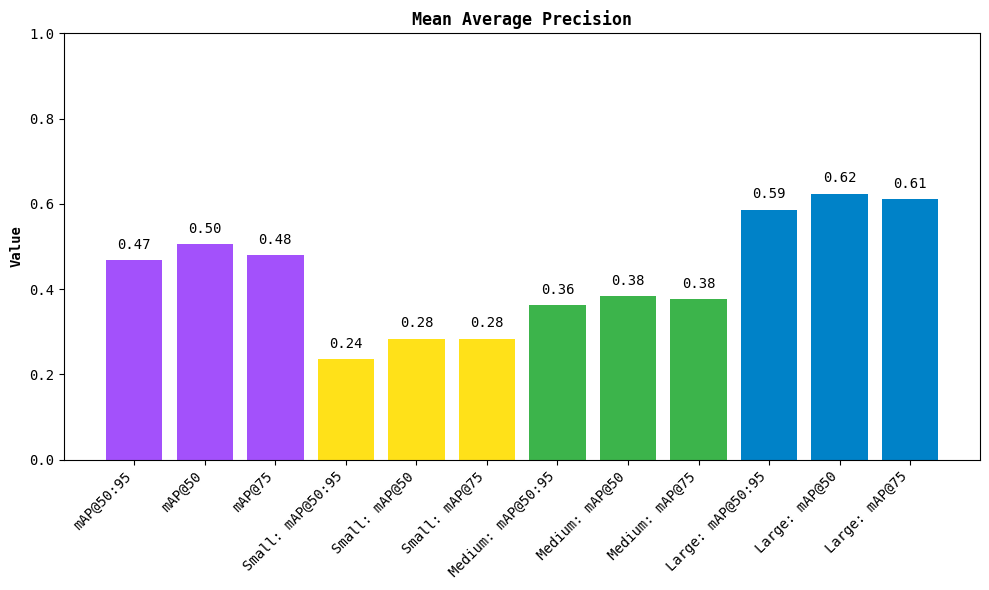
We'll start with [MeanAveragePrecision (mAP)](https://supervision.roboflow.com/latest/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision), which is the most commonly used metric for object detection. It measures the average precision across all classes and IoU thresholds.
|
||||
|
||||
For a thorough explanation, check out our [blog](https://blog.roboflow.com/mean-average-precision/) or [Youtube video](https://www.youtube.com/watch?v=oqXDdxF_Wuw).
|
||||
|
||||
Here, the most important value is `mAP 50:95`. It represents the average precision across all classes and IoU thresholds (`0.5` to `0.95`), whereas other values such as `mAP 50` or `mAP 75` only consider a single IoU threshold (`0.5` and `0.75` respectively).
|
||||
|
||||
Let's compute the mAP:
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
map_metric = sv.metrics.MeanAveragePrecision()
|
||||
map_result = map_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
Try printing the result to see it at a glance:
|
||||
|
||||
```python
|
||||
print(map_result)
|
||||
```
|
||||
|
||||
```
|
||||
MeanAveragePrecisionResult:
|
||||
Metric target: MetricTarget.BOXES
|
||||
Class agnostic: False
|
||||
mAP @ 50:95: 0.4674
|
||||
mAP @ 50: 0.5048
|
||||
mAP @ 75: 0.4796
|
||||
mAP scores: [0.50485 0.50377 0.50377 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
AP per class:
|
||||
0: [0.67699 0.67699 0.67699 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
Large objects: ...
|
||||
```
|
||||
|
||||
You can also plot the results:
|
||||
|
||||
```python
|
||||
map_result.plot()
|
||||
```
|
||||
|
||||
|
||||
|
||||
The metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
### F1 Score
|
||||
|
||||
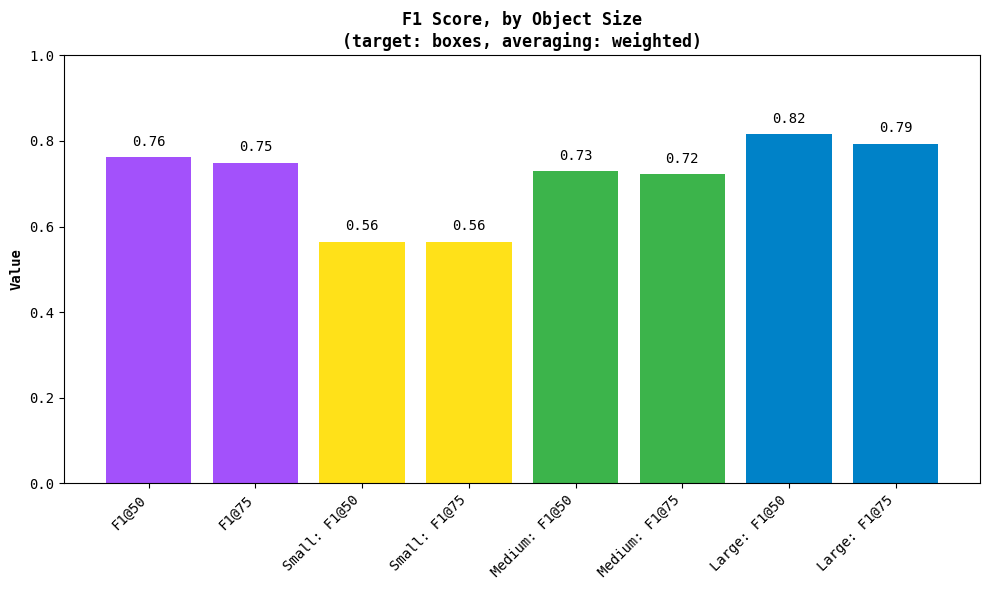
The [F1 Score](https://supervision.roboflow.com/latest/metrics/f1_score/) is another useful metric, especially when dealing with an imbalance between false positives and false negatives. It’s the harmonic mean of **precision** (how many predictions are correct) and **recall** (how many actual instances were detected).
|
||||
|
||||
Here's how you can compute the F1 score:
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
f1_metric = sv.metrics.F1Score()
|
||||
f1_result = f1_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
As with mAP, you can also print the result:
|
||||
|
||||
```python
|
||||
print(f1_result)
|
||||
```
|
||||
|
||||
```
|
||||
F1ScoreResult:
|
||||
Metric target: MetricTarget.BOXES
|
||||
Averaging method: AveragingMethod.WEIGHTED
|
||||
F1 @ 50: 0.7618
|
||||
F1 @ 75: 0.7487
|
||||
F1 @ thresh: [0.76175 0.76068 0.76068]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
F1 per class:
|
||||
0: [0.70968 0.70968 0.70968 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
Large objects: ...
|
||||
```
|
||||
|
||||
Similarly, you can plot the results:
|
||||
|
||||
```python
|
||||
f1_result.plot()
|
||||
```
|
||||
|
||||
|
||||
|
||||
As with mAP, the metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
## Model Leaderboard
|
||||
|
||||
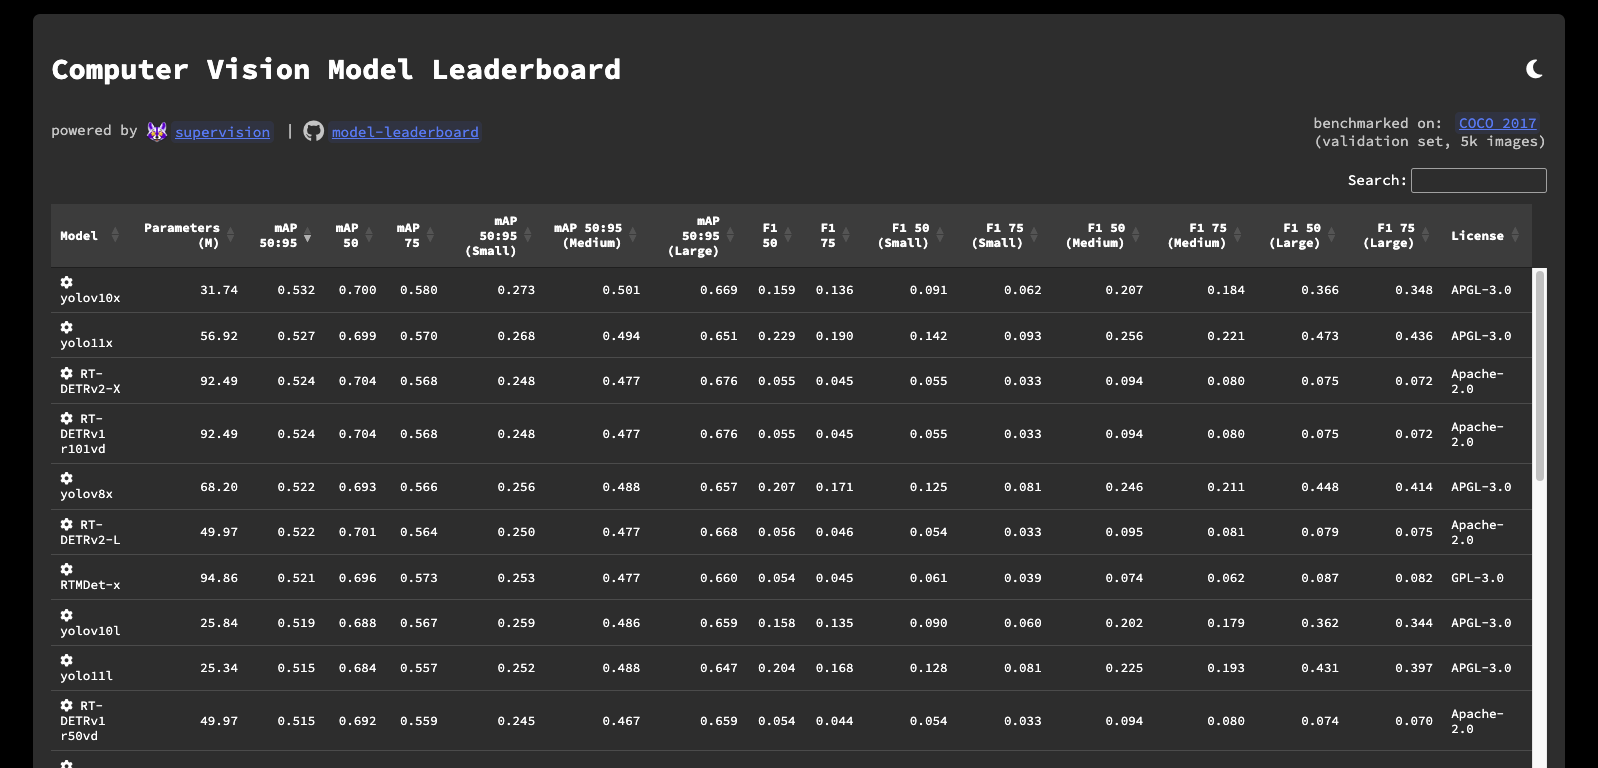
Here to compare the basic models? We've got you covered. Check out our [Model Leaderboard](https://leaderboard.roboflow.com/) to see how different models perform and to get a sense of the state-of-the-art results. It's a great place to understand what the leading models can achieve and to compare your own results.
|
||||
|
||||
Even better, the repository is open source! You can see how the models were benchmarked, run the evaluation yourself, and even add your own models to the leaderboard. Check it out on [GitHub](https://github.com/roboflow/model-leaderboard)!
|
||||
|
||||
|
||||
|
||||
## Conclusion
|
||||
|
||||
In this guide, you've learned how to set up your environment, train or use pre-trained models, visualize predictions, and evaluate model performance with metrics like [mAP](https://supervision.roboflow.com/latest/metrics/mean_average_precision/), [F1 score](https://supervision.roboflow.com/latest/metrics/f1_score/), and got to know our Model Leaderboard.
|
||||
|
||||
For more details, be sure to check out our [documentation](https://supervision.roboflow.com/latest/) and join our community discussions. If you find any issues, please let us know on [GitHub](https://github.com/roboflow/supervision/issues).
|
||||
|
||||
Best of luck with your benchmarking!
|
||||
@@ -42,6 +42,7 @@ nav:
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
- Process Datasets: how_to/process_datasets.md
|
||||
- Benchmark a Model: how_to/benchmark_a_model.md
|
||||
|
||||
- Reference - Code API:
|
||||
- Detection and Segmentation:
|
||||
|
||||
Reference in new issue
Block a user