utils split across multiple files; internal and external imports working; utils tests split across multiple files; tests working locally
This commit is contained in:
 SkalskiP committed
1 parent
9dc2785762
commit
fa5fcbb264
39 files changed
+3821
-3813
No files matched your search
+37
-27
@@ -46,43 +46,51 @@ from supervision.detection.line_zone import (
|
||||
LineZoneAnnotator,
|
||||
LineZoneAnnotatorMulticlass,
|
||||
)
|
||||
from supervision.detection.overlap_filter import (
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
box_iou,
|
||||
box_iou_batch,
|
||||
box_iou_batch_with_jaccard,
|
||||
oriented_box_iou_batch,
|
||||
mask_iou_batch,
|
||||
OverlapFilter,
|
||||
OverlapMetric,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils.masks import (
|
||||
move_masks,
|
||||
calculate_masks_centroids,
|
||||
contains_holes,
|
||||
contains_multiple_segments
|
||||
)
|
||||
from supervision.detection.utils.converters import (
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_polygons,
|
||||
xyxy_to_xcycarh,
|
||||
xyxy_to_xywh,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
)
|
||||
from supervision.detection.utils.boxes import (
|
||||
clip_boxes,
|
||||
denormalize_boxes,
|
||||
move_boxes,
|
||||
pad_boxes,
|
||||
scale_boxes,
|
||||
)
|
||||
from supervision.detection.utils.polygons import (
|
||||
filter_polygons_by_area,
|
||||
approximate_polygon
|
||||
)
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.json_sink import JSONSink
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.detection.utils import (
|
||||
box_iou,
|
||||
box_iou_batch,
|
||||
box_iou_batch_with_jaccard,
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
denormalize_boxes,
|
||||
filter_polygons_by_area,
|
||||
mask_iou_batch,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
move_masks,
|
||||
oriented_box_iou_batch,
|
||||
pad_boxes,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
scale_boxes,
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_polygons,
|
||||
xyxy_to_xcycarh,
|
||||
xyxy_to_xywh,
|
||||
)
|
||||
from supervision.detection.vlm import LMM, VLM
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
@@ -167,6 +175,7 @@ __all__ = [
|
||||
"MeanAveragePrecision",
|
||||
"OrientedBoxAnnotator",
|
||||
"OverlapFilter",
|
||||
"OverlapMetric",
|
||||
"PercentageBarAnnotator",
|
||||
"PixelateAnnotator",
|
||||
"Point",
|
||||
@@ -235,4 +244,5 @@ __all__ = [
|
||||
"xyxy_to_polygons",
|
||||
"xyxy_to_xcycarh",
|
||||
"xyxy_to_xywh",
|
||||
"approximate_polygon"
|
||||
]
|
||||
@@ -22,13 +22,10 @@ from supervision.annotators.utils import (
|
||||
)
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
clip_boxes,
|
||||
mask_to_polygons,
|
||||
polygon_to_mask,
|
||||
spread_out_boxes,
|
||||
xyxy_to_polygons,
|
||||
)
|
||||
from supervision.detection.utils.boxes import spread_out_boxes, clip_boxes
|
||||
from supervision.detection.utils.converters import mask_to_polygons, xyxy_to_polygons, \
|
||||
polygon_to_mask
|
||||
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon, draw_rounded_rectangle, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
|
||||
@@ -13,11 +13,9 @@ from supervision.dataset.utils import (
|
||||
rle_to_mask,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
polygon_to_mask,
|
||||
)
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.detection.utils.masks import contains_holes, contains_multiple_segments
|
||||
|
||||
from supervision.utils.file import read_json_file, save_json_file
|
||||
|
||||
if TYPE_CHECKING:
|
||||
|
||||
@@ -11,7 +11,7 @@ from defusedxml.minidom import parseString
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
|
||||
|
||||
|
||||
@@ -10,7 +10,7 @@ from PIL import Image
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.file import (
|
||||
list_files_with_extensions,
|
||||
read_txt_file,
|
||||
|
||||
@@ -12,11 +12,9 @@ import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
approximate_polygon,
|
||||
filter_polygons_by_area,
|
||||
mask_to_polygons,
|
||||
)
|
||||
from supervision.detection.utils.converters import mask_to_polygons
|
||||
from supervision.detection.utils.polygons import filter_polygons_by_area, \
|
||||
approximate_polygon
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
|
||||
@@ -12,32 +12,23 @@ from supervision.config import (
|
||||
CLASS_NAME_DATA_FIELD,
|
||||
ORIENTED_BOX_COORDINATES,
|
||||
)
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.transformers import (
|
||||
process_transformers_detection_result,
|
||||
process_transformers_v4_segmentation_result,
|
||||
process_transformers_v5_segmentation_result,
|
||||
)
|
||||
from supervision.detection.utils import (
|
||||
from supervision.detection.utils.converters import mask_to_xyxy, xywh_to_xyxy
|
||||
from supervision.detection.utils.internal import get_data_item, is_data_equal, \
|
||||
is_metadata_equal, extract_ultralytics_masks, process_roboflow_result, merge_data, \
|
||||
merge_metadata
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
OverlapMetric,
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
is_metadata_equal,
|
||||
mask_iou_batch,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
merge_metadata,
|
||||
process_roboflow_result,
|
||||
xywh_to_xyxy,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression, mask_iou_batch, box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.masks import calculate_masks_centroids
|
||||
from supervision.detection.vlm import (
|
||||
LMM,
|
||||
VLM,
|
||||
|
||||
@@ -13,7 +13,7 @@ import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import cross_product
|
||||
from supervision.detection.utils.internal import cross_product
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rectangle, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect, Vector
|
||||
|
||||
@@ -1,396 +0,0 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils import OverlapMetric, box_iou_batch, mask_iou_batch
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
return resized_masks
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized, overlap_metric)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes, overlap_metric)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(
|
||||
predictions[order][:, :4], merge_candidate[:, :4], overlap_metric
|
||||
)
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def mask_non_max_merge(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Perform Non-Maximum Merging (NMM) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
if predictions.shape[1] == 5:
|
||||
return group_overlapping_masks(
|
||||
predictions, masks_resized, iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = group_overlapping_masks(
|
||||
predictions[curr_indices],
|
||||
masks_resized[curr_indices],
|
||||
iou_threshold,
|
||||
overlap_metric,
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return group_overlapping_boxes(predictions, iou_threshold, overlap_metric)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def group_overlapping_masks(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
masks: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
masks (npt.NDArray[np.float64]): A 3D array of binary masks corresponding to
|
||||
the predictions.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = masks[idx][None, ...]
|
||||
candidate_groups = [idx]
|
||||
while len(order) > 0:
|
||||
ious = mask_iou_batch(masks[order], merge_candidate, overlap_metric)
|
||||
above_threshold: np.ndarray = ious.flatten() >= iou_threshold
|
||||
if not above_threshold.any():
|
||||
break
|
||||
above_idx = order[above_threshold]
|
||||
merge_candidate = np.logical_or.reduce(
|
||||
np.concatenate([masks[above_idx], merge_candidate]),
|
||||
axis=0,
|
||||
keepdims=True,
|
||||
)
|
||||
candidate_groups.extend(np.flip(above_idx).tolist())
|
||||
order = order[~above_threshold]
|
||||
|
||||
merge_groups.append(candidate_groups)
|
||||
return merge_groups
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: OverlapFilter | str) -> OverlapFilter:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
@@ -8,8 +8,9 @@ import numpy as np
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.overlap_filter import OverlapFilter
|
||||
from supervision.detection.utils import move_boxes, move_masks, move_oriented_boxes
|
||||
from supervision.detection.utils.boxes import move_boxes, move_oriented_boxes
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter
|
||||
from supervision.detection.utils.masks import move_masks
|
||||
from supervision.utils.image import crop_image
|
||||
from supervision.utils.internal import (
|
||||
SupervisionWarnings,
|
||||
|
||||
@@ -8,7 +8,8 @@ import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import clip_boxes, polygon_to_mask
|
||||
from supervision.detection.utils.boxes import clip_boxes
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_filled_polygon, draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
@@ -7,7 +7,7 @@ import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import mask_to_xyxy
|
||||
from supervision.detection.utils.converters import mask_to_xyxy
|
||||
|
||||
|
||||
def process_transformers_detection_result(
|
||||
|
||||
File diff suppressed because it is too large.
Load diff
Whitespace-only changes.
@@ -0,0 +1,333 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
|
||||
def clip_boxes(xyxy: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Clips bounding boxes coordinates to fit within the frame resolution.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in
|
||||
the format `(x_min, y_min, x_max, y_max)`.
|
||||
resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)`
|
||||
representing the resolution of the frame.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box with coordinates clipped to fit
|
||||
within the frame resolution.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 300, 200],
|
||||
[15, 25, 350, 450],
|
||||
[-10, -20, 30, 40]
|
||||
])
|
||||
|
||||
sv.clip_boxes(xyxy=xyxy, resolution_wh=(320, 240))
|
||||
# array([
|
||||
# [ 10, 20, 300, 200],
|
||||
# [ 15, 25, 320, 240],
|
||||
# [ 0, 0, 30, 40]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
result = np.copy(xyxy)
|
||||
width, height = resolution_wh
|
||||
result[:, [0, 2]] = result[:, [0, 2]].clip(0, width)
|
||||
result[:, [1, 3]] = result[:, [1, 3]].clip(0, height)
|
||||
return result
|
||||
|
||||
|
||||
def pad_boxes(xyxy: np.ndarray, px: int, py: int | None = None) -> np.ndarray:
|
||||
"""
|
||||
Pads bounding boxes coordinates with a constant padding.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in the format
|
||||
`(x_min, y_min, x_max, y_max)`.
|
||||
px (int): The padding value to be added to both the left and right sides of
|
||||
each bounding box.
|
||||
py (Optional[int]): The padding value to be added to both the top and bottom
|
||||
sides of each bounding box. If not provided, `px` will be used for both
|
||||
dimensions.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a
|
||||
bounding box with coordinates padded according to the provided padding
|
||||
values.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 30, 40],
|
||||
[15, 25, 35, 45]
|
||||
])
|
||||
|
||||
sv.pad_boxes(xyxy=xyxy, px=5, py=10)
|
||||
# array([
|
||||
# [ 5, 10, 35, 50],
|
||||
# [10, 15, 40, 55]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
if py is None:
|
||||
py = px
|
||||
|
||||
result = xyxy.copy()
|
||||
result[:, [0, 1]] -= [px, py]
|
||||
result[:, [2, 3]] += [px, py]
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def denormalize_boxes(
|
||||
normalized_xyxy: np.ndarray,
|
||||
resolution_wh: tuple[int, int],
|
||||
normalization_factor: float = 1.0,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Convert normalized xyxy coordinates to absolute XYXY coordinates. By default, assumes
|
||||
normalized values are between 0 and 1, but supports custom ranges via normalization_factor parameter.
|
||||
Args:
|
||||
normalized_xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each row contains
|
||||
normalized coordinates in format `(x1, y1, x2, y2)` with values between 0 and normalization_factor.
|
||||
resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)` representing
|
||||
the target resolution.
|
||||
normalization_factor (float): The maximum value of the normalization range. For example:
|
||||
- normalization_factor=1.0 means input coordinates are normalized between 0 and 1
|
||||
- normalization_factor=100.0 means input coordinates are normalized between 0 and 100
|
||||
- normalization_factor=1000.0 means input coordinates are normalized between 0 and 1000
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` containing the absolute coordinates
|
||||
in format `(x1, y1, x2, y2)`.
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
# Example with default normalization (0-1)
|
||||
normalized_xyxy = np.array([
|
||||
[0.1, 0.2, 0.5, 0.6],
|
||||
[0.3, 0.4, 0.7, 0.8]
|
||||
])
|
||||
resolution_wh = (100, 200)
|
||||
sv.denormalize_boxes(normalized_xyxy, resolution_wh)
|
||||
# array([
|
||||
# [ 10., 40., 50., 120.],
|
||||
# [ 30., 80., 70., 160.]
|
||||
# ])
|
||||
# Example with custom normalization (0-100)
|
||||
normalized_xyxy = np.array([
|
||||
[10., 20., 50., 60.],
|
||||
[30., 40., 70., 80.]
|
||||
])
|
||||
sv.denormalize_boxes(normalized_xyxy, resolution_wh, max_value=100.0)
|
||||
# array([
|
||||
# [ 10., 40., 50., 120.],
|
||||
# [ 30., 80., 70., 160.]
|
||||
# ])
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
width, height = resolution_wh
|
||||
result = normalized_xyxy.copy()
|
||||
|
||||
result[[0, 2]] = (result[[0, 2]] * width) / normalization_factor
|
||||
result[[1, 3]] = (result[[1, 3]] * height) / normalization_factor
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def move_boxes(
|
||||
xyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
|
||||
sv.move_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [15, 15, 25, 25],
|
||||
# [35, 35, 45, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
|
||||
|
||||
def move_oriented_boxes(
|
||||
xyxyxyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxyxyxy (npt.NDArray[np.float64]): An array of shape `(n, 4, 2)` containing the
|
||||
oriented bounding boxes coordinates in format
|
||||
`[[x1, y1], [x2, y2], [x3, y3], [x3, y3]]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxyxyxy = np.array([
|
||||
[
|
||||
[20, 10],
|
||||
[10, 20],
|
||||
[20, 30],
|
||||
[30, 20]
|
||||
],
|
||||
[
|
||||
[30 ,30],
|
||||
[20, 40],
|
||||
[30, 50],
|
||||
[40, 40]
|
||||
]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
|
||||
sv.move_oriented_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [
|
||||
# [25, 15],
|
||||
# [15, 25],
|
||||
# [25, 35],
|
||||
# [35, 25]
|
||||
# ],
|
||||
# [
|
||||
# [35, 35],
|
||||
# [25, 45],
|
||||
# [35, 55],
|
||||
# [45, 45]
|
||||
# ]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxyxyxy + offset
|
||||
|
||||
|
||||
def scale_boxes(
|
||||
xyxy: npt.NDArray[np.float64], factor: float
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Scale the dimensions of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
factor (float): A float value representing the factor by which the box
|
||||
dimensions are scaled. A factor greater than 1 enlarges the boxes, while a
|
||||
factor less than 1 shrinks them.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Scaled bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
|
||||
sv.scale_boxes(xyxy=xyxy, factor=1.5)
|
||||
# array([
|
||||
# [ 7.5, 7.5, 22.5, 22.5],
|
||||
# [27.5, 27.5, 42.5, 42.5]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
centers = (xyxy[:, :2] + xyxy[:, 2:]) / 2
|
||||
new_sizes = (xyxy[:, 2:] - xyxy[:, :2]) * factor
|
||||
return np.concatenate((centers - new_sizes / 2, centers + new_sizes / 2), axis=1)
|
||||
|
||||
|
||||
def spread_out_boxes(
|
||||
xyxy: np.ndarray,
|
||||
max_iterations: int = 100,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Spread out boxes that overlap with each other.
|
||||
|
||||
Args:
|
||||
xyxy: Numpy array of shape (N, 4) where N is the number of boxes.
|
||||
max_iterations: Maximum number of iterations to run the algorithm for.
|
||||
"""
|
||||
if len(xyxy) == 0:
|
||||
return xyxy
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy, px=1)
|
||||
for _ in range(max_iterations):
|
||||
# NxN
|
||||
iou = box_iou_batch(xyxy_padded, xyxy_padded)
|
||||
np.fill_diagonal(iou, 0)
|
||||
if np.all(iou == 0):
|
||||
break
|
||||
|
||||
overlap_mask = iou > 0
|
||||
|
||||
# Nx2
|
||||
centers = (xyxy_padded[:, :2] + xyxy_padded[:, 2:]) / 2
|
||||
|
||||
# NxNx2
|
||||
delta_centers = centers[:, np.newaxis, :] - centers[np.newaxis, :, :]
|
||||
delta_centers *= overlap_mask[:, :, np.newaxis]
|
||||
|
||||
# Nx2
|
||||
delta_sum = np.sum(delta_centers, axis=1)
|
||||
delta_magnitude = np.linalg.norm(delta_sum, axis=1, keepdims=True)
|
||||
direction_vectors = np.divide(
|
||||
delta_sum,
|
||||
delta_magnitude,
|
||||
out=np.zeros_like(delta_sum),
|
||||
where=delta_magnitude != 0,
|
||||
)
|
||||
|
||||
force_vectors = np.sum(iou, axis=1)
|
||||
force_vectors = force_vectors[:, np.newaxis] * direction_vectors
|
||||
|
||||
force_vectors *= 10
|
||||
force_vectors[(force_vectors > 0) & (force_vectors < 2)] = 2
|
||||
force_vectors[(force_vectors < 0) & (force_vectors > -2)] = -2
|
||||
|
||||
force_vectors = force_vectors.astype(int)
|
||||
|
||||
xyxy_padded[:, [0, 1]] += force_vectors
|
||||
xyxy_padded[:, [2, 3]] += force_vectors
|
||||
|
||||
return pad_boxes(xyxy_padded, px=-1)
|
||||
@@ -0,0 +1,272 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
|
||||
def xyxy_to_polygons(box: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Convert an array of boxes to an array of polygons.
|
||||
Retains the input datatype.
|
||||
|
||||
Args:
|
||||
box (np.ndarray): An array of boxes (N, 4), where each box is represented as a
|
||||
list of four coordinates in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of polygons (N, 4, 2), where each polygon is
|
||||
represented as a list of four coordinates in the format `(x, y)`.
|
||||
"""
|
||||
polygon = np.zeros((box.shape[0], 4, 2), dtype=box.dtype)
|
||||
polygon[:, :, 0] = box[:, [0, 2, 2, 0]]
|
||||
polygon[:, :, 1] = box[:, [1, 1, 3, 3]]
|
||||
return polygon
|
||||
|
||||
|
||||
def polygon_to_mask(polygon: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""Generate a mask from a polygon.
|
||||
|
||||
Args:
|
||||
polygon (np.ndarray): The polygon for which the mask should be generated,
|
||||
given as a list of vertices.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired resolution.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The generated 2D mask, where the polygon is marked with
|
||||
`1`'s and the rest is filled with `0`'s.
|
||||
"""
|
||||
width, height = map(int, resolution_wh)
|
||||
mask = np.zeros((height, width), dtype=np.uint8)
|
||||
cv2.fillPoly(mask, [polygon.astype(np.int32)], color=1)
|
||||
return mask
|
||||
|
||||
|
||||
def xywh_to_xyxy(xywh: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x, y, width, height)`
|
||||
format to `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Args:
|
||||
xywh (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(x, y, width, height)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xywh = np.array([
|
||||
[10, 20, 30, 40],
|
||||
[15, 25, 35, 45]
|
||||
])
|
||||
|
||||
sv.xywh_to_xyxy(xywh=xywh)
|
||||
# array([
|
||||
# [10, 20, 40, 60],
|
||||
# [15, 25, 50, 70]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xyxy = xywh.copy()
|
||||
xyxy[:, 2] = xywh[:, 0] + xywh[:, 2]
|
||||
xyxy[:, 3] = xywh[:, 1] + xywh[:, 3]
|
||||
return xyxy
|
||||
|
||||
|
||||
def xyxy_to_xywh(xyxy: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x_min, y_min, x_max, y_max)`
|
||||
format to `(x, y, width, height)` format.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(x_min, y_min, x_max,
|
||||
y_max)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x, y, width, height)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 40, 60],
|
||||
[15, 25, 50, 70]
|
||||
])
|
||||
|
||||
sv.xyxy_to_xywh(xyxy=xyxy)
|
||||
# array([
|
||||
# [10, 20, 30, 40],
|
||||
# [15, 25, 35, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xywh = xyxy.copy()
|
||||
xywh[:, 2] = xyxy[:, 2] - xyxy[:, 0]
|
||||
xywh[:, 3] = xyxy[:, 3] - xyxy[:, 1]
|
||||
return xywh
|
||||
|
||||
|
||||
def xcycwh_to_xyxy(xcycwh: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(center_x, center_y, width, height)`
|
||||
format to `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Args:
|
||||
xcycwh (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(center_x, center_y, width,
|
||||
height)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xcycwh = np.array([
|
||||
[50, 50, 20, 30],
|
||||
[30, 40, 10, 15]
|
||||
])
|
||||
|
||||
sv.xcycwh_to_xyxy(xcycwh=xcycwh)
|
||||
# array([
|
||||
# [40, 35, 60, 65],
|
||||
# [25, 32.5, 35, 47.5]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xyxy = xcycwh.copy()
|
||||
xyxy[:, 0] = xcycwh[:, 0] - xcycwh[:, 2] / 2
|
||||
xyxy[:, 1] = xcycwh[:, 1] - xcycwh[:, 3] / 2
|
||||
xyxy[:, 2] = xcycwh[:, 0] + xcycwh[:, 2] / 2
|
||||
xyxy[:, 3] = xcycwh[:, 1] + xcycwh[:, 3] / 2
|
||||
return xyxy
|
||||
|
||||
|
||||
def xyxy_to_xcycarh(xyxy: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x_min, y_min, x_max, y_max)`
|
||||
into measurement space to format `(center x, center y, aspect ratio, height)`,
|
||||
where the aspect ratio is `width / height`.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): Bounding box in format `(x1, y1, x2, y2)`.
|
||||
Expected shape is `(N, 4)`.
|
||||
Returns:
|
||||
np.ndarray: Bounding box in format
|
||||
`(center x, center y, aspect ratio, height)`. Shape `(N, 4)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 40, 60],
|
||||
[15, 25, 50, 70]
|
||||
])
|
||||
|
||||
sv.xyxy_to_xcycarh(xyxy=xyxy)
|
||||
# array([
|
||||
# [25. , 40. , 0.75, 40. ],
|
||||
# [32.5 , 47.5 , 0.77777778, 45. ]
|
||||
# ])
|
||||
```
|
||||
|
||||
"""
|
||||
if xyxy.size == 0:
|
||||
return np.empty((0, 4), dtype=float)
|
||||
|
||||
x1, y1, x2, y2 = xyxy.T
|
||||
width = x2 - x1
|
||||
height = y2 - y1
|
||||
center_x = x1 + width / 2
|
||||
center_y = y1 + height / 2
|
||||
|
||||
aspect_ratio = np.divide(
|
||||
width,
|
||||
height,
|
||||
out=np.zeros_like(width, dtype=float),
|
||||
where=height != 0,
|
||||
)
|
||||
result = np.column_stack((center_x, center_y, aspect_ratio, height))
|
||||
return result.astype(float)
|
||||
|
||||
|
||||
def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a 3D `np.array` of 2D bool masks into a 2D `np.array` of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D `np.array` of shape `(N, W, H)`
|
||||
containing 2D bool masks
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 2D `np.array` of shape `(N, 4)` containing the bounding boxes
|
||||
`(x_min, y_min, x_max, y_max)` for each mask
|
||||
"""
|
||||
n = masks.shape[0]
|
||||
xyxy = np.zeros((n, 4), dtype=int)
|
||||
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
x_min, x_max = np.min(cols), np.max(cols)
|
||||
y_min, y_max = np.min(rows), np.max(rows)
|
||||
xyxy[i, :] = [x_min, y_min, x_max, y_max]
|
||||
|
||||
return xyxy
|
||||
|
||||
|
||||
def mask_to_polygons(mask: np.ndarray) -> list[np.ndarray]:
|
||||
"""
|
||||
Converts a binary mask to a list of polygons.
|
||||
|
||||
Parameters:
|
||||
mask (np.ndarray): A binary mask represented as a 2D NumPy array of
|
||||
shape `(H, W)`, where H and W are the height and width of
|
||||
the mask, respectively.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, where each polygon is represented by a
|
||||
NumPy array of shape `(N, 2)`, containing the `x`, `y` coordinates
|
||||
of the points. Polygons with fewer points than `MIN_POLYGON_POINT_COUNT = 3`
|
||||
are excluded from the output.
|
||||
"""
|
||||
|
||||
contours, _ = cv2.findContours(
|
||||
mask.astype(np.uint8), cv2.RETR_TREE, cv2.CHAIN_APPROX_SIMPLE
|
||||
)
|
||||
return [
|
||||
np.squeeze(contour, axis=1)
|
||||
for contour in contours
|
||||
if contour.shape[0] >= MIN_POLYGON_POINT_COUNT
|
||||
]
|
||||
|
||||
|
||||
def polygon_to_xyxy(polygon: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a polygon represented by a NumPy array into a bounding box.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A polygon represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 1D NumPy array containing the bounding box
|
||||
`(x_min, y_min, x_max, y_max)` of the input polygon.
|
||||
"""
|
||||
x_min, y_min = np.min(polygon, axis=0)
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
return np.array([x_min, y_min, x_max, y_max])
|
||||
@@ -0,0 +1,331 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from itertools import chain
|
||||
from typing import Any
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.geometry.core import Vector
|
||||
|
||||
|
||||
def extract_ultralytics_masks(yolov8_results) -> np.ndarray | None:
|
||||
if not yolov8_results.masks:
|
||||
return None
|
||||
|
||||
orig_shape = yolov8_results.orig_shape
|
||||
inference_shape = tuple(yolov8_results.masks.data.shape[1:])
|
||||
|
||||
pad = (0, 0)
|
||||
|
||||
if inference_shape != orig_shape:
|
||||
gain = min(
|
||||
inference_shape[0] / orig_shape[0],
|
||||
inference_shape[1] / orig_shape[1],
|
||||
)
|
||||
pad = (
|
||||
(inference_shape[1] - orig_shape[1] * gain) / 2,
|
||||
(inference_shape[0] - orig_shape[0] * gain) / 2,
|
||||
)
|
||||
|
||||
top, left = int(pad[1]), int(pad[0])
|
||||
bottom, right = int(inference_shape[0] - pad[1]), int(inference_shape[1] - pad[0])
|
||||
|
||||
mask_maps = []
|
||||
masks = yolov8_results.masks.data.cpu().numpy()
|
||||
for i in range(masks.shape[0]):
|
||||
mask = masks[i]
|
||||
mask = mask[top:bottom, left:right]
|
||||
|
||||
if mask.shape != orig_shape:
|
||||
mask = cv2.resize(mask, (orig_shape[1], orig_shape[0]))
|
||||
|
||||
mask_maps.append(mask)
|
||||
|
||||
return np.asarray(mask_maps, dtype=bool)
|
||||
|
||||
|
||||
def process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
) -> tuple[
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray | None,
|
||||
np.ndarray | None,
|
||||
dict[str, list[np.ndarray] | np.ndarray],
|
||||
]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
)
|
||||
|
||||
xyxy = []
|
||||
confidence = []
|
||||
class_id = []
|
||||
class_name = []
|
||||
masks = []
|
||||
tracker_ids = []
|
||||
|
||||
image_width = int(roboflow_result["image"]["width"])
|
||||
image_height = int(roboflow_result["image"]["height"])
|
||||
|
||||
for prediction in roboflow_result["predictions"]:
|
||||
x = prediction["x"]
|
||||
y = prediction["y"]
|
||||
width = prediction["width"]
|
||||
height = prediction["height"]
|
||||
x_min = x - width / 2
|
||||
y_min = y - height / 2
|
||||
x_max = x_min + width
|
||||
y_max = y_min + height
|
||||
|
||||
if "points" not in prediction:
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
elif len(prediction["points"]) >= 3:
|
||||
polygon = np.array(
|
||||
[[point["x"], point["y"]] for point in prediction["points"]], dtype=int
|
||||
)
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
masks.append(mask)
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
|
||||
xyxy = np.array(xyxy) if len(xyxy) > 0 else np.empty((0, 4))
|
||||
confidence = np.array(confidence) if len(confidence) > 0 else np.empty(0)
|
||||
class_id = np.array(class_id).astype(int) if len(class_id) > 0 else np.empty(0)
|
||||
class_name = np.array(class_name) if len(class_name) > 0 else np.empty(0)
|
||||
masks = np.array(masks, dtype=bool) if len(masks) > 0 else None
|
||||
tracker_id = np.array(tracker_ids).astype(int) if len(tracker_ids) > 0 else None
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
|
||||
return xyxy, confidence, class_id, masks, tracker_id, data
|
||||
|
||||
|
||||
def is_data_equal(data_a: dict[str, np.ndarray], data_b: dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
data_a, data_b: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the data payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(data_a.keys()) == set(data_b.keys()) and all(
|
||||
np.array_equal(data_a[key], data_b[key]) for key in data_a
|
||||
)
|
||||
|
||||
|
||||
def is_metadata_equal(metadata_a: dict[str, Any], metadata_b: dict[str, Any]) -> bool:
|
||||
"""
|
||||
Compares the metadata payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
metadata_a, metadata_b: The metadata payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the metadata payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(metadata_a.keys()) == set(metadata_b.keys()) and all(
|
||||
np.array_equal(metadata_a[key], metadata_b[key])
|
||||
if (
|
||||
isinstance(metadata_a[key], np.ndarray)
|
||||
and isinstance(metadata_b[key], np.ndarray)
|
||||
)
|
||||
else metadata_a[key] == metadata_b[key]
|
||||
for key in metadata_a
|
||||
)
|
||||
|
||||
|
||||
def merge_data(
|
||||
data_list: list[dict[str, npt.NDArray[np.generic] | list]],
|
||||
) -> dict[str, npt.NDArray[np.generic] | list]:
|
||||
"""
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Warning: Assumes that empty detections were filtered-out before passing data to
|
||||
this function.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the Detections instances. Each data payload
|
||||
is a dictionary with the same keys, and the values are either lists or
|
||||
npt.NDArray[np.generic].
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
types (list or npt.NDArray[np.generic]).
|
||||
|
||||
Raises:
|
||||
ValueError: If data values within a single object have different lengths or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
raise ValueError(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
for data in data_list:
|
||||
for key in data:
|
||||
merged_data[key].append(data[key])
|
||||
|
||||
for key in merged_data:
|
||||
if all(isinstance(item, list) for item in merged_data[key]):
|
||||
merged_data[key] = list(chain.from_iterable(merged_data[key]))
|
||||
elif all(isinstance(item, np.ndarray) for item in merged_data[key]):
|
||||
ndim = merged_data[key][0].ndim
|
||||
if ndim == 1:
|
||||
merged_data[key] = np.hstack(merged_data[key])
|
||||
elif ndim > 1:
|
||||
merged_data[key] = np.vstack(merged_data[key])
|
||||
else:
|
||||
raise ValueError(f"Unexpected array dimension for key '{key}'.")
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Inconsistent data types for key '{key}'. Only np.ndarray and list "
|
||||
f"types are allowed."
|
||||
)
|
||||
|
||||
return merged_data
|
||||
|
||||
|
||||
def merge_metadata(metadata_list: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
"""
|
||||
Merge metadata from a list of metadata dictionaries.
|
||||
|
||||
This function combines the metadata dictionaries. If a key appears in more than one
|
||||
dictionary, the values must be identical for the merge to succeed.
|
||||
|
||||
Warning: Assumes that empty detections were filtered-out before passing metadata to
|
||||
this function.
|
||||
|
||||
Args:
|
||||
metadata_list (List[Dict[str, Any]]): A list of metadata dictionaries to merge.
|
||||
|
||||
Returns:
|
||||
Dict[str, Any]: A single merged metadata dictionary.
|
||||
|
||||
Raises:
|
||||
ValueError: If there are conflicting values for the same key or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not metadata_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(metadata.keys()) for metadata in metadata_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All metadata dictionaries must have the same keys to merge.")
|
||||
|
||||
merged_metadata: dict[str, Any] = {}
|
||||
for metadata in metadata_list:
|
||||
for key, value in metadata.items():
|
||||
if key not in merged_metadata:
|
||||
merged_metadata[key] = value
|
||||
continue
|
||||
|
||||
other_value = merged_metadata[key]
|
||||
if isinstance(value, np.ndarray) and isinstance(other_value, np.ndarray):
|
||||
if not np.array_equal(merged_metadata[key], value):
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
elif isinstance(value, np.ndarray) or isinstance(other_value, np.ndarray):
|
||||
# Since [] == np.array([]).
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
else:
|
||||
print("hm")
|
||||
if merged_metadata[key] != value:
|
||||
raise ValueError(f"Conflicting metadata for key: '{key}'.")
|
||||
|
||||
return merged_metadata
|
||||
|
||||
|
||||
def get_data_item(
|
||||
data: dict[str, np.ndarray | list],
|
||||
index: int | slice | list[int] | np.ndarray,
|
||||
) -> dict[str, np.ndarray | list]:
|
||||
"""
|
||||
Retrieve a subset of the data dictionary based on the given index.
|
||||
|
||||
Args:
|
||||
data: The data dictionary of the Detections object.
|
||||
index: The index or indices specifying the subset to retrieve.
|
||||
|
||||
Returns:
|
||||
A subset of the data dictionary corresponding to the specified index.
|
||||
"""
|
||||
subset_data = {}
|
||||
for key, value in data.items():
|
||||
if isinstance(value, np.ndarray):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, list):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, np.ndarray):
|
||||
if index.dtype == bool:
|
||||
subset_data[key] = [
|
||||
value[i] for i, index_value in enumerate(index) if index_value
|
||||
]
|
||||
else:
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
raise TypeError(f"Unsupported index type: {type(index)}")
|
||||
else:
|
||||
raise TypeError(f"Unsupported data type for key '{key}': {type(value)}")
|
||||
|
||||
return subset_data
|
||||
|
||||
|
||||
def cross_product(anchors: np.ndarray, vector: Vector) -> np.ndarray:
|
||||
"""
|
||||
Get array of cross products of each anchor with a vector.
|
||||
Args:
|
||||
anchors: Array of anchors of shape (number of anchors, detections, 2)
|
||||
vector: Vector to calculate cross product with
|
||||
|
||||
Returns:
|
||||
Array of cross products of shape (number of anchors, detections)
|
||||
"""
|
||||
vector_at_zero = np.array(
|
||||
[
|
||||
vector.end.x - vector.start.x,
|
||||
vector.end.y - vector.start.y,
|
||||
]
|
||||
)
|
||||
vector_start = np.array([vector.start.x, vector.start.y])
|
||||
return np.cross(vector_at_zero, anchors - vector_start)
|
||||
@@ -0,0 +1,795 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.detection.utils.masks import resize_masks
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: OverlapFilter | str) -> OverlapFilter:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
class OverlapMetric(Enum):
|
||||
"""
|
||||
Enum specifying the metric for measuring overlap between detections.
|
||||
|
||||
Attributes:
|
||||
IOU: Intersection over Union. A region-overlap metric that compares
|
||||
two shapes (usually bounding boxes or masks) by normalising the
|
||||
shared area with the area of their union.
|
||||
IOS: Intersection over Smaller, a region-overlap metric that compares
|
||||
two shapes (usually bounding boxes or masks) by normalising the
|
||||
shared area with the smaller of the two shapes.
|
||||
"""
|
||||
|
||||
IOU = "IOU"
|
||||
IOS = "IOS"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: OverlapMetric | str) -> OverlapMetric:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
def box_iou(
|
||||
box_true: list[float] | np.ndarray,
|
||||
box_detection: list[float] | np.ndarray,
|
||||
) -> float:
|
||||
"""
|
||||
Compute the Intersection over Union (IoU) between two bounding boxes.
|
||||
|
||||
Mathematically, it is defined as:
|
||||
|
||||
\\[
|
||||
\text{IoU} = \frac{|\text{box}_{\text{true}} \\cap \text{box}_{\text{detection}}|}{|\text{box}_{\text{true}} \\cup \text{box}_{\text{detection}}|}
|
||||
\\]
|
||||
|
||||
Note:
|
||||
Use `box_iou` when computing IoU between two individual boxes.
|
||||
For comparing multiple boxes (arrays of boxes), use `box_iou_batch` for better
|
||||
performance.
|
||||
|
||||
Args:
|
||||
box_true (Union[List[float], np.ndarray]): A single bounding box represented as
|
||||
[x_min, y_min, x_max, y_max].
|
||||
box_detection (Union[List[float], np.ndarray]):
|
||||
A single bounding box represented as [x_min, y_min, x_max, y_max].
|
||||
|
||||
Returns:
|
||||
IoU (float): IoU score between the two boxes. Ranges from 0.0 (no overlap)
|
||||
to 1.0 (perfect overlap).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
box_true = np.array([100, 100, 200, 200])
|
||||
box_detection = np.array([150, 150, 250, 250])
|
||||
|
||||
sv.box_iou(box_true=box_true, box_detection=box_detection)
|
||||
# 0.14285814285714285
|
||||
```
|
||||
""" # noqa: E501
|
||||
box_true = np.array(box_true)
|
||||
box_detection = np.array(box_detection)
|
||||
|
||||
inter_x1 = max(box_true[0], box_detection[0])
|
||||
inter_y1 = max(box_true[1], box_detection[1])
|
||||
inter_x2 = min(box_true[2], box_detection[2])
|
||||
inter_y2 = min(box_true[3], box_detection[3])
|
||||
|
||||
inter_w = max(0, inter_x2 - inter_x1)
|
||||
inter_h = max(0, inter_y2 - inter_y1)
|
||||
|
||||
inter_area = inter_w * inter_h
|
||||
|
||||
area_true = (box_true[2] - box_true[0]) * (box_true[3] - box_true[1])
|
||||
area_detection = (box_detection[2] - box_detection[0]) * (
|
||||
box_detection[3] - box_detection[1]
|
||||
)
|
||||
|
||||
union_area = area_true + area_detection - inter_area
|
||||
|
||||
return inter_area / union_area + 1e-6
|
||||
|
||||
|
||||
def box_iou_batch(
|
||||
boxes_true: np.ndarray,
|
||||
boxes_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of bounding boxes -
|
||||
`boxes_true` and `boxes_detection`. Both sets
|
||||
of boxes are expected to be in `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Note:
|
||||
Use `box_iou` when computing IoU between two individual boxes.
|
||||
For comparing multiple boxes (arrays of boxes), use `box_iou_batch` for better
|
||||
performance.
|
||||
|
||||
Args:
|
||||
boxes_true (np.ndarray): 2D `np.ndarray` representing ground-truth boxes.
|
||||
`shape = (N, 4)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): 2D `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4)` where `M` is number of detected objects.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
`shape = (N, M)` where `N` is number of true objects and
|
||||
`M` is number of detected objects.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes_true = np.array([
|
||||
[100, 100, 200, 200],
|
||||
[300, 300, 400, 400]
|
||||
])
|
||||
boxes_detection = np.array([
|
||||
[150, 150, 250, 250],
|
||||
[320, 320, 420, 420]
|
||||
])
|
||||
|
||||
sv.box_iou_batch(boxes_true=boxes_true, boxes_detection=boxes_detection)
|
||||
# array([
|
||||
# [0.14285714, 0. ],
|
||||
# [0. , 0.47058824]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
|
||||
def box_area(box):
|
||||
return (box[2] - box[0]) * (box[3] - box[1])
|
||||
|
||||
area_true = box_area(boxes_true.T)
|
||||
area_detection = box_area(boxes_detection.T)
|
||||
|
||||
top_left = np.maximum(boxes_true[:, None, :2], boxes_detection[:, :2])
|
||||
bottom_right = np.minimum(boxes_true[:, None, 2:], boxes_detection[:, 2:])
|
||||
|
||||
area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2)
|
||||
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
union_area = area_true[:, None] + area_detection - area_inter
|
||||
ious = np.divide(
|
||||
area_inter,
|
||||
union_area,
|
||||
out=np.zeros_like(area_inter, dtype=float),
|
||||
where=union_area != 0,
|
||||
)
|
||||
elif overlap_metric == OverlapMetric.IOS:
|
||||
small_area = np.minimum(area_true[:, None], area_detection)
|
||||
ious = np.divide(
|
||||
area_inter,
|
||||
small_area,
|
||||
out=np.zeros_like(area_inter, dtype=float),
|
||||
where=small_area != 0,
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"overlap_metric {overlap_metric} is not supported, "
|
||||
"only 'IOU' and 'IOS' are supported"
|
||||
)
|
||||
|
||||
ious = np.nan_to_num(ious)
|
||||
return ious
|
||||
|
||||
|
||||
def _jaccard(box_a: list[float], box_b: list[float], is_crowd: bool) -> float:
|
||||
"""
|
||||
Calculate the Jaccard index (intersection over union) between two bounding boxes.
|
||||
If a gt object is marked as "iscrowd", a dt is allowed to match any subregion
|
||||
of the gt. Choosing gt'=intersect(dt,gt). Since by definition union(gt',dt)=dt, computing
|
||||
iou(gt,dt,iscrowd) = iou(gt',dt) = area(intersect(gt,dt)) / area(dt)
|
||||
|
||||
Args:
|
||||
box_a (List[float]): Box coordinates in the format [x, y, width, height].
|
||||
box_b (List[float]): Box coordinates in the format [x, y, width, height].
|
||||
iscrowd (bool): Flag indicating if the second box is a crowd region or not.
|
||||
|
||||
Returns:
|
||||
float: Jaccard index between the two bounding boxes.
|
||||
""" # noqa: E501
|
||||
# Smallest number to avoid division by zero
|
||||
EPS = np.spacing(1)
|
||||
|
||||
xa, ya, x2a, y2a = box_a[0], box_a[1], box_a[0] + box_a[2], box_a[1] + box_a[3]
|
||||
xb, yb, x2b, y2b = box_b[0], box_b[1], box_b[0] + box_b[2], box_b[1] + box_b[3]
|
||||
|
||||
# Innermost left x
|
||||
xi = max(xa, xb)
|
||||
# Innermost right x
|
||||
x2i = min(x2a, x2b)
|
||||
# Same for y
|
||||
yi = max(ya, yb)
|
||||
y2i = min(y2a, y2b)
|
||||
|
||||
# Calculate areas
|
||||
Aa = max(x2a - xa, 0.0) * max(y2a - ya, 0.0)
|
||||
Ab = max(x2b - xb, 0.0) * max(y2b - yb, 0.0)
|
||||
Ai = max(x2i - xi, 0.0) * max(y2i - yi, 0.0)
|
||||
|
||||
if is_crowd:
|
||||
return Ai / (Aa + EPS)
|
||||
|
||||
return Ai / (Aa + Ab - Ai + EPS)
|
||||
|
||||
|
||||
def box_iou_batch_with_jaccard(
|
||||
boxes_true: list[list[float]],
|
||||
boxes_detection: list[list[float]],
|
||||
is_crowd: list[bool],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Calculate the intersection over union (IoU) between detection bounding boxes (dt)
|
||||
and ground-truth bounding boxes (gt).
|
||||
Reference: https://github.com/rafaelpadilla/review_object_detection_metrics
|
||||
|
||||
Args:
|
||||
boxes_true (List[List[float]]): List of ground-truth bounding boxes in the \
|
||||
format [x, y, width, height].
|
||||
boxes_detection (List[List[float]]): List of detection bounding boxes in the \
|
||||
format [x, y, width, height].
|
||||
is_crowd (List[bool]): List indicating if each ground-truth bounding box \
|
||||
is a crowd region or not.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of IoU values of shape (len(dt), len(gt)).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes_true = [
|
||||
[10, 20, 30, 40], # x, y, w, h
|
||||
[15, 25, 35, 45]
|
||||
]
|
||||
boxes_detection = [
|
||||
[12, 22, 28, 38],
|
||||
[16, 26, 36, 46]
|
||||
]
|
||||
is_crowd = [False, False]
|
||||
|
||||
ious = sv.box_iou_batch_with_jaccard(
|
||||
boxes_true=boxes_true,
|
||||
boxes_detection=boxes_detection,
|
||||
is_crowd=is_crowd
|
||||
)
|
||||
# array([
|
||||
# [0.8866..., 0.4960...],
|
||||
# [0.4000..., 0.8622...]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
assert len(is_crowd) == len(boxes_true), (
|
||||
"`is_crowd` must have the same length as `boxes_true`"
|
||||
)
|
||||
if len(boxes_detection) == 0 or len(boxes_true) == 0:
|
||||
return np.array([])
|
||||
ious = np.zeros((len(boxes_detection), len(boxes_true)), dtype=np.float64)
|
||||
for g_idx, g in enumerate(boxes_true):
|
||||
for d_idx, d in enumerate(boxes_detection):
|
||||
ious[d_idx, g_idx] = _jaccard(d, g, is_crowd[g_idx])
|
||||
return ious
|
||||
|
||||
|
||||
def oriented_box_iou_batch(
|
||||
boxes_true: np.ndarray, boxes_detection: np.ndarray
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of oriented bounding boxes -
|
||||
`boxes_true` and `boxes_detection`. Both sets of boxes are expected to be in
|
||||
`((x1, y1), (x2, y2), (x3, y3), (x4, y4))` format.
|
||||
|
||||
Args:
|
||||
boxes_true (np.ndarray): a `np.ndarray` representing ground-truth boxes.
|
||||
`shape = (N, 4, 2)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): a `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4, 2)` where `M` is number of detected objects.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
`shape = (N, M)` where `N` is number of true objects and
|
||||
`M` is number of detected objects.
|
||||
"""
|
||||
|
||||
boxes_true = boxes_true.reshape(-1, 4, 2)
|
||||
boxes_detection = boxes_detection.reshape(-1, 4, 2)
|
||||
|
||||
max_height = int(max(boxes_true[:, :, 0].max(), boxes_detection[:, :, 0].max()) + 1)
|
||||
# adding 1 because we are 0-indexed
|
||||
max_width = int(max(boxes_true[:, :, 1].max(), boxes_detection[:, :, 1].max()) + 1)
|
||||
|
||||
mask_true = np.zeros((boxes_true.shape[0], max_height, max_width))
|
||||
for i, box_true in enumerate(boxes_true):
|
||||
mask_true[i] = polygon_to_mask(box_true, (max_width, max_height))
|
||||
|
||||
mask_detection = np.zeros((boxes_detection.shape[0], max_height, max_width))
|
||||
for i, box_detection in enumerate(boxes_detection):
|
||||
mask_detection[i] = polygon_to_mask(box_detection, (max_width, max_height))
|
||||
|
||||
ious = mask_iou_batch(mask_true, mask_detection)
|
||||
return ious
|
||||
|
||||
|
||||
def _mask_iou_batch_split(
|
||||
masks_true: np.ndarray,
|
||||
masks_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Internal function.
|
||||
Compute Intersection over Union (IoU) of two sets of masks -
|
||||
`masks_true` and `masks_detection`.
|
||||
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
"""
|
||||
intersection_area = np.logical_and(masks_true[:, None], masks_detection).sum(
|
||||
axis=(2, 3)
|
||||
)
|
||||
|
||||
masks_true_area = masks_true.sum(axis=(1, 2)) # (area1, area2, ...)
|
||||
masks_detection_area = masks_detection.sum(axis=(1, 2)) # (area1)
|
||||
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
union_area = masks_true_area[:, None] + masks_detection_area - intersection_area
|
||||
ious = np.divide(
|
||||
intersection_area,
|
||||
union_area,
|
||||
out=np.zeros_like(intersection_area, dtype=float),
|
||||
where=union_area != 0,
|
||||
)
|
||||
elif overlap_metric == OverlapMetric.IOS:
|
||||
# ios = intersection_area / min(area1, area2)
|
||||
small_area = np.minimum(masks_true_area[:, None], masks_detection_area)
|
||||
ious = np.divide(
|
||||
intersection_area,
|
||||
small_area,
|
||||
out=np.zeros_like(intersection_area, dtype=float),
|
||||
where=small_area != 0,
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"overlap_metric {overlap_metric} is not supported, "
|
||||
"only 'IOU' and 'IOS' are supported"
|
||||
)
|
||||
|
||||
ious = np.nan_to_num(ious)
|
||||
return ious
|
||||
|
||||
|
||||
def mask_iou_batch(
|
||||
masks_true: np.ndarray,
|
||||
masks_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
memory_limit: int = 1024 * 5,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of masks -
|
||||
`masks_true` and `masks_detection`.
|
||||
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
memory_limit (int): memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
"""
|
||||
memory = (
|
||||
masks_true.shape[0]
|
||||
* masks_true.shape[1]
|
||||
* masks_true.shape[2]
|
||||
* masks_detection.shape[0]
|
||||
/ 1024
|
||||
/ 1024
|
||||
)
|
||||
if memory <= memory_limit:
|
||||
return _mask_iou_batch_split(masks_true, masks_detection, overlap_metric)
|
||||
|
||||
ious = []
|
||||
step = max(
|
||||
memory_limit
|
||||
* 1024
|
||||
* 1024
|
||||
// (
|
||||
masks_detection.shape[0]
|
||||
* masks_detection.shape[1]
|
||||
* masks_detection.shape[2]
|
||||
),
|
||||
1,
|
||||
)
|
||||
for i in range(0, masks_true.shape[0], step):
|
||||
ious.append(
|
||||
_mask_iou_batch_split(
|
||||
masks_true[i : i + step], masks_detection, overlap_metric
|
||||
)
|
||||
)
|
||||
|
||||
return np.vstack(ious)
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized, overlap_metric)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes, overlap_metric)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def _group_overlapping_masks(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
masks: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
masks (npt.NDArray[np.float64]): A 3D array of binary masks corresponding to
|
||||
the predictions.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = masks[idx][None, ...]
|
||||
candidate_groups = [idx]
|
||||
while len(order) > 0:
|
||||
ious = mask_iou_batch(masks[order], merge_candidate, overlap_metric)
|
||||
above_threshold: np.ndarray = ious.flatten() >= iou_threshold
|
||||
if not above_threshold.any():
|
||||
break
|
||||
above_idx = order[above_threshold]
|
||||
merge_candidate = np.logical_or.reduce(
|
||||
np.concatenate([masks[above_idx], merge_candidate]),
|
||||
axis=0,
|
||||
keepdims=True,
|
||||
)
|
||||
candidate_groups.extend(np.flip(above_idx).tolist())
|
||||
order = order[~above_threshold]
|
||||
|
||||
merge_groups.append(candidate_groups)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def mask_non_max_merge(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Perform Non-Maximum Merging (NMM) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
if predictions.shape[1] == 5:
|
||||
return _group_overlapping_masks(
|
||||
predictions, masks_resized, iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = _group_overlapping_masks(
|
||||
predictions[curr_indices],
|
||||
masks_resized[curr_indices],
|
||||
iou_threshold,
|
||||
overlap_metric,
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def _group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(
|
||||
predictions[order][:, :4], merge_candidate[:, :4], overlap_metric
|
||||
)
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return _group_overlapping_boxes(predictions, iou_threshold, overlap_metric)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = _group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
@@ -0,0 +1,260 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
|
||||
def move_masks(
|
||||
masks: npt.NDArray[np.bool_],
|
||||
offset: npt.NDArray[np.int32],
|
||||
resolution_wh: tuple[int, int],
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Offset the masks in an array by the specified (x, y) amount.
|
||||
|
||||
Args:
|
||||
masks (npt.NDArray[np.bool_]): A 3D array of binary masks corresponding to the
|
||||
predictions. Shape: `(N, H, W)`, where N is the number of predictions, and
|
||||
H, W are the dimensions of each mask.
|
||||
offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing int values
|
||||
`[dx, dy]`. Supports both positive and negative values for bidirectional
|
||||
movement.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution.
|
||||
|
||||
Returns:
|
||||
(npt.NDArray[np.bool_]) repositioned masks, optionally padded to the specified
|
||||
shape.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([[[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False]]], dtype=bool)
|
||||
|
||||
offset = np.array([1, 1])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, True, True],
|
||||
# [False, False, True, True]]], dtype=bool)
|
||||
|
||||
offset = np.array([-2, 2])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [True, False, False, False]]], dtype=bool)
|
||||
```
|
||||
"""
|
||||
mask_array = np.full((masks.shape[0], resolution_wh[1], resolution_wh[0]), False)
|
||||
|
||||
if offset[0] < 0:
|
||||
source_x_start = -offset[0]
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = 0
|
||||
destination_x_end = min(resolution_wh[0], masks.shape[2] + offset[0])
|
||||
else:
|
||||
source_x_start = 0
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = offset[0]
|
||||
destination_x_end = offset[0] + source_x_end - source_x_start
|
||||
|
||||
if offset[1] < 0:
|
||||
source_y_start = -offset[1]
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = 0
|
||||
destination_y_end = min(resolution_wh[1], masks.shape[1] + offset[1])
|
||||
else:
|
||||
source_y_start = 0
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = offset[1]
|
||||
destination_y_end = offset[1] + source_y_end - source_y_start
|
||||
|
||||
if source_x_end > source_x_start and source_y_end > source_y_start:
|
||||
mask_array[
|
||||
:,
|
||||
destination_y_start:destination_y_end,
|
||||
destination_x_start:destination_x_end,
|
||||
] = masks[:, source_y_start:source_y_end, source_x_start:source_x_end]
|
||||
|
||||
return mask_array
|
||||
|
||||
|
||||
def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Calculate the centroids of binary masks in a tensor.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D NumPy array of shape (num_masks, height, width).
|
||||
Each 2D array in the tensor represents a binary mask.
|
||||
|
||||
Returns:
|
||||
A 2D NumPy array of shape (num_masks, 2), where each row contains the x and y
|
||||
coordinates (in that order) of the centroid of the corresponding mask.
|
||||
"""
|
||||
num_masks, height, width = masks.shape
|
||||
total_pixels = masks.sum(axis=(1, 2))
|
||||
|
||||
# offset for 1-based indexing
|
||||
vertical_indices, horizontal_indices = np.indices((height, width)) + 0.5
|
||||
# avoid division by zero for empty masks
|
||||
total_pixels[total_pixels == 0] = 1
|
||||
|
||||
def sum_over_mask(indices: np.ndarray, axis: tuple) -> np.ndarray:
|
||||
return np.tensordot(masks, indices, axes=axis)
|
||||
|
||||
aggregation_axis = ([1, 2], [0, 1])
|
||||
centroid_x = sum_over_mask(horizontal_indices, aggregation_axis) / total_pixels
|
||||
centroid_y = sum_over_mask(vertical_indices, aggregation_axis) / total_pixels
|
||||
|
||||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def contains_holes(mask: npt.NDArray[np.bool_]) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains holes (background pixels fully enclosed by
|
||||
foreground pixels).
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
|
||||
Returns:
|
||||
True if holes are detected, False otherwise.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 0, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# False
|
||||
```
|
||||
|
||||
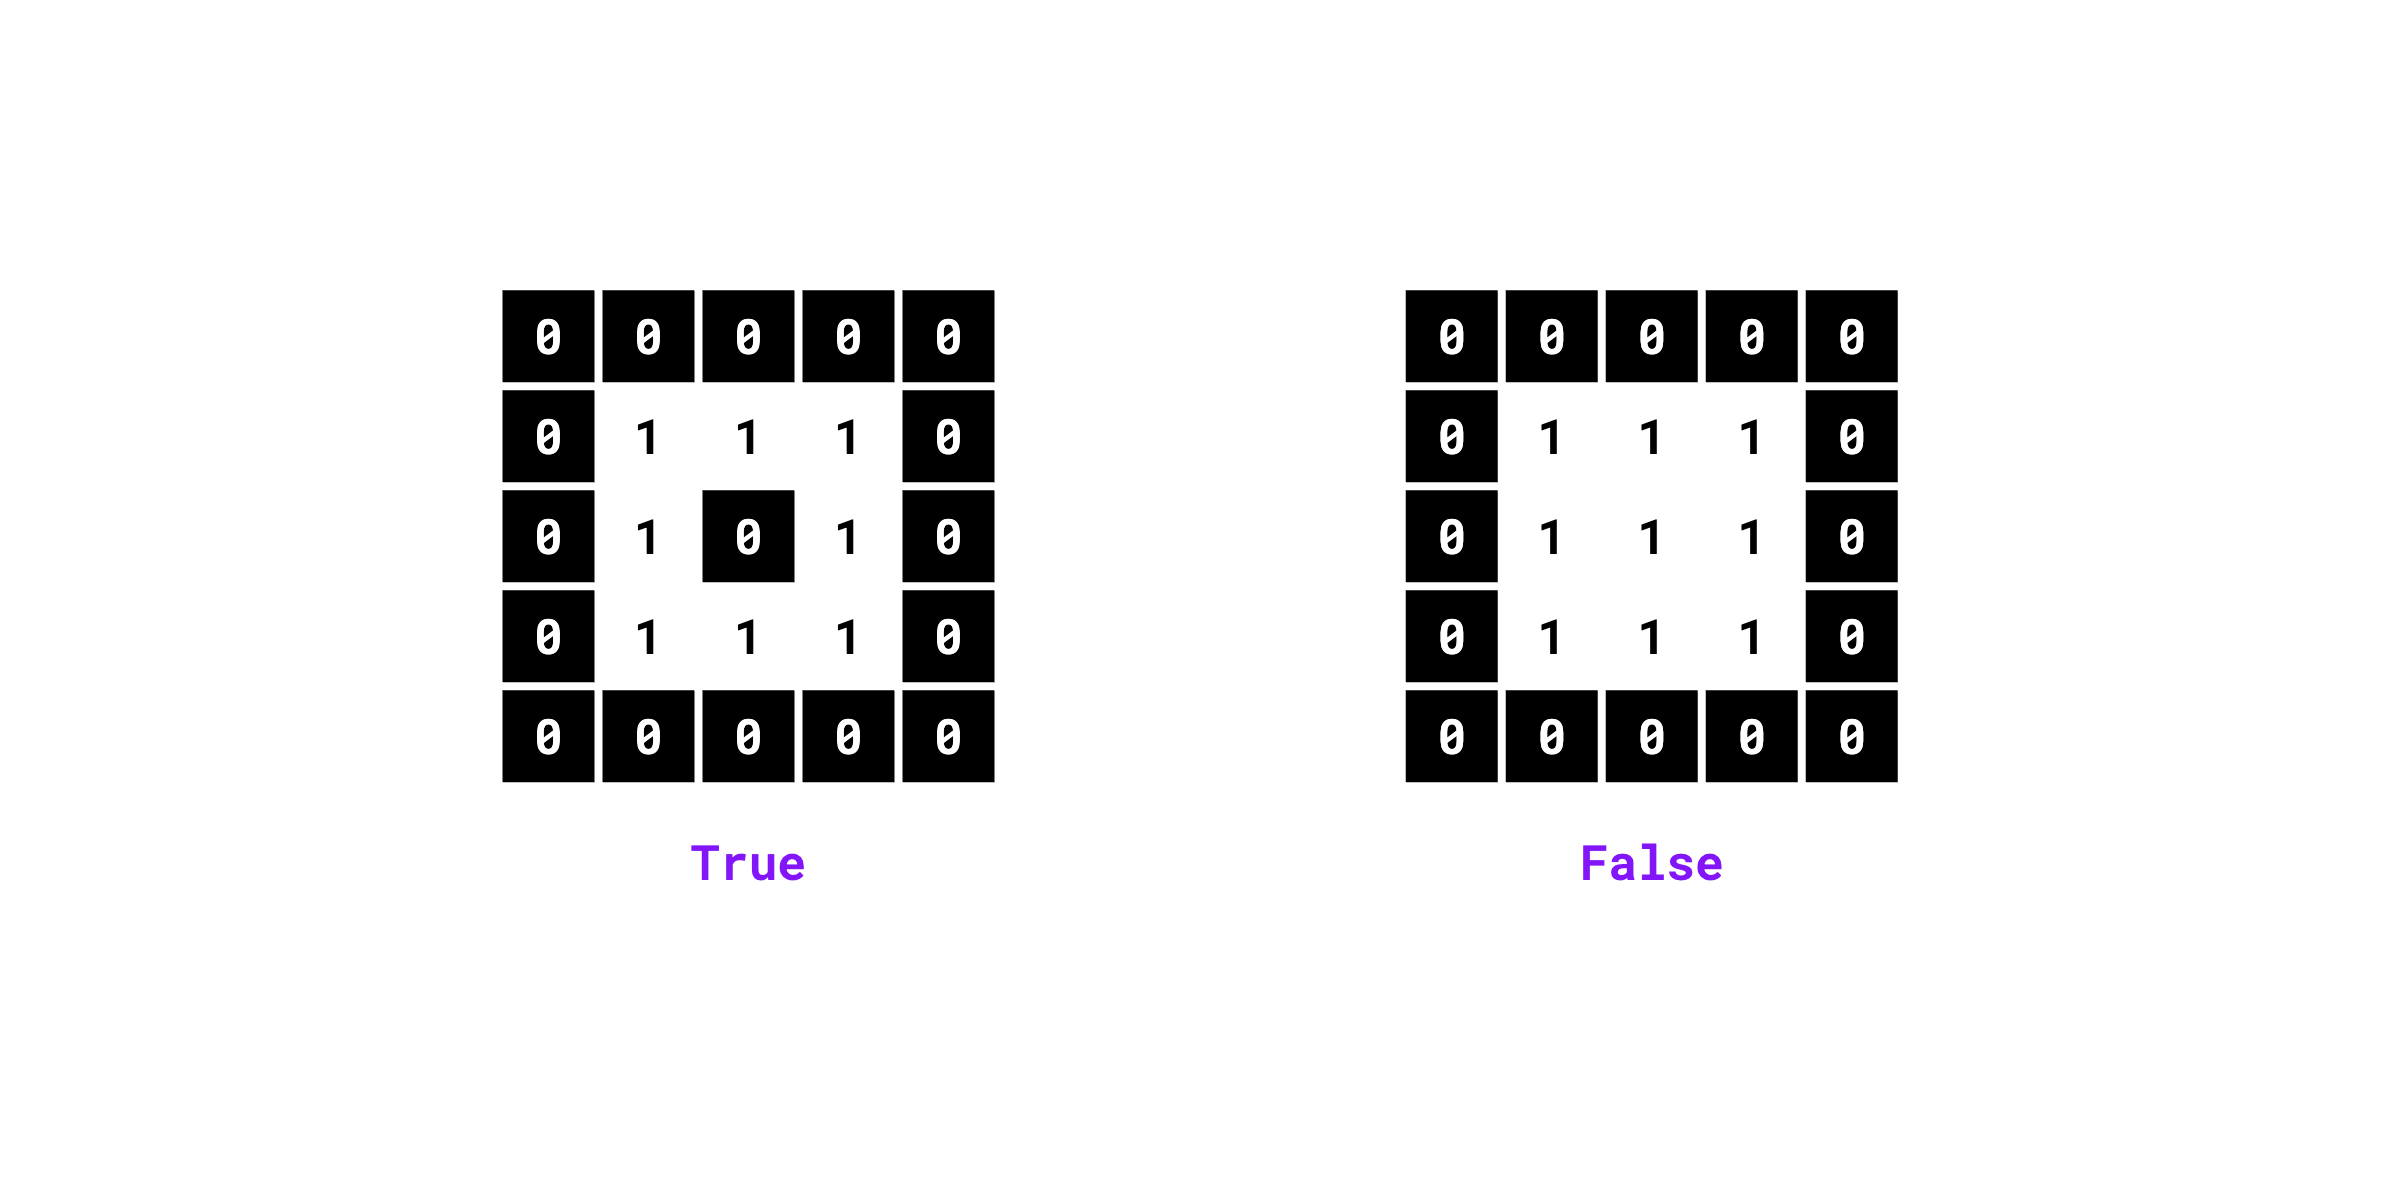{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
_, hierarchy = cv2.findContours(mask_uint8, cv2.RETR_CCOMP, cv2.CHAIN_APPROX_SIMPLE)
|
||||
|
||||
if hierarchy is not None:
|
||||
parent_contour_index = 3
|
||||
for h in hierarchy[0]:
|
||||
if h[parent_contour_index] != -1:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def contains_multiple_segments(
|
||||
mask: npt.NDArray[np.bool_], connectivity: int = 4
|
||||
) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains multiple unconnected foreground segments.
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
connectivity (int) : Default: 4 is 4-way connectivity, which means that
|
||||
foreground pixels are the part of the same segment/component
|
||||
if their edges touch.
|
||||
Alternatively: 8 for 8-way connectivity, when foreground pixels are
|
||||
connected by their edges or corners touch.
|
||||
|
||||
Returns:
|
||||
True when the mask contains multiple not connected components, False otherwise.
|
||||
|
||||
Raises:
|
||||
ValueError: If connectivity(int) parameter value is not 4 or 8.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# False
|
||||
```
|
||||
|
||||
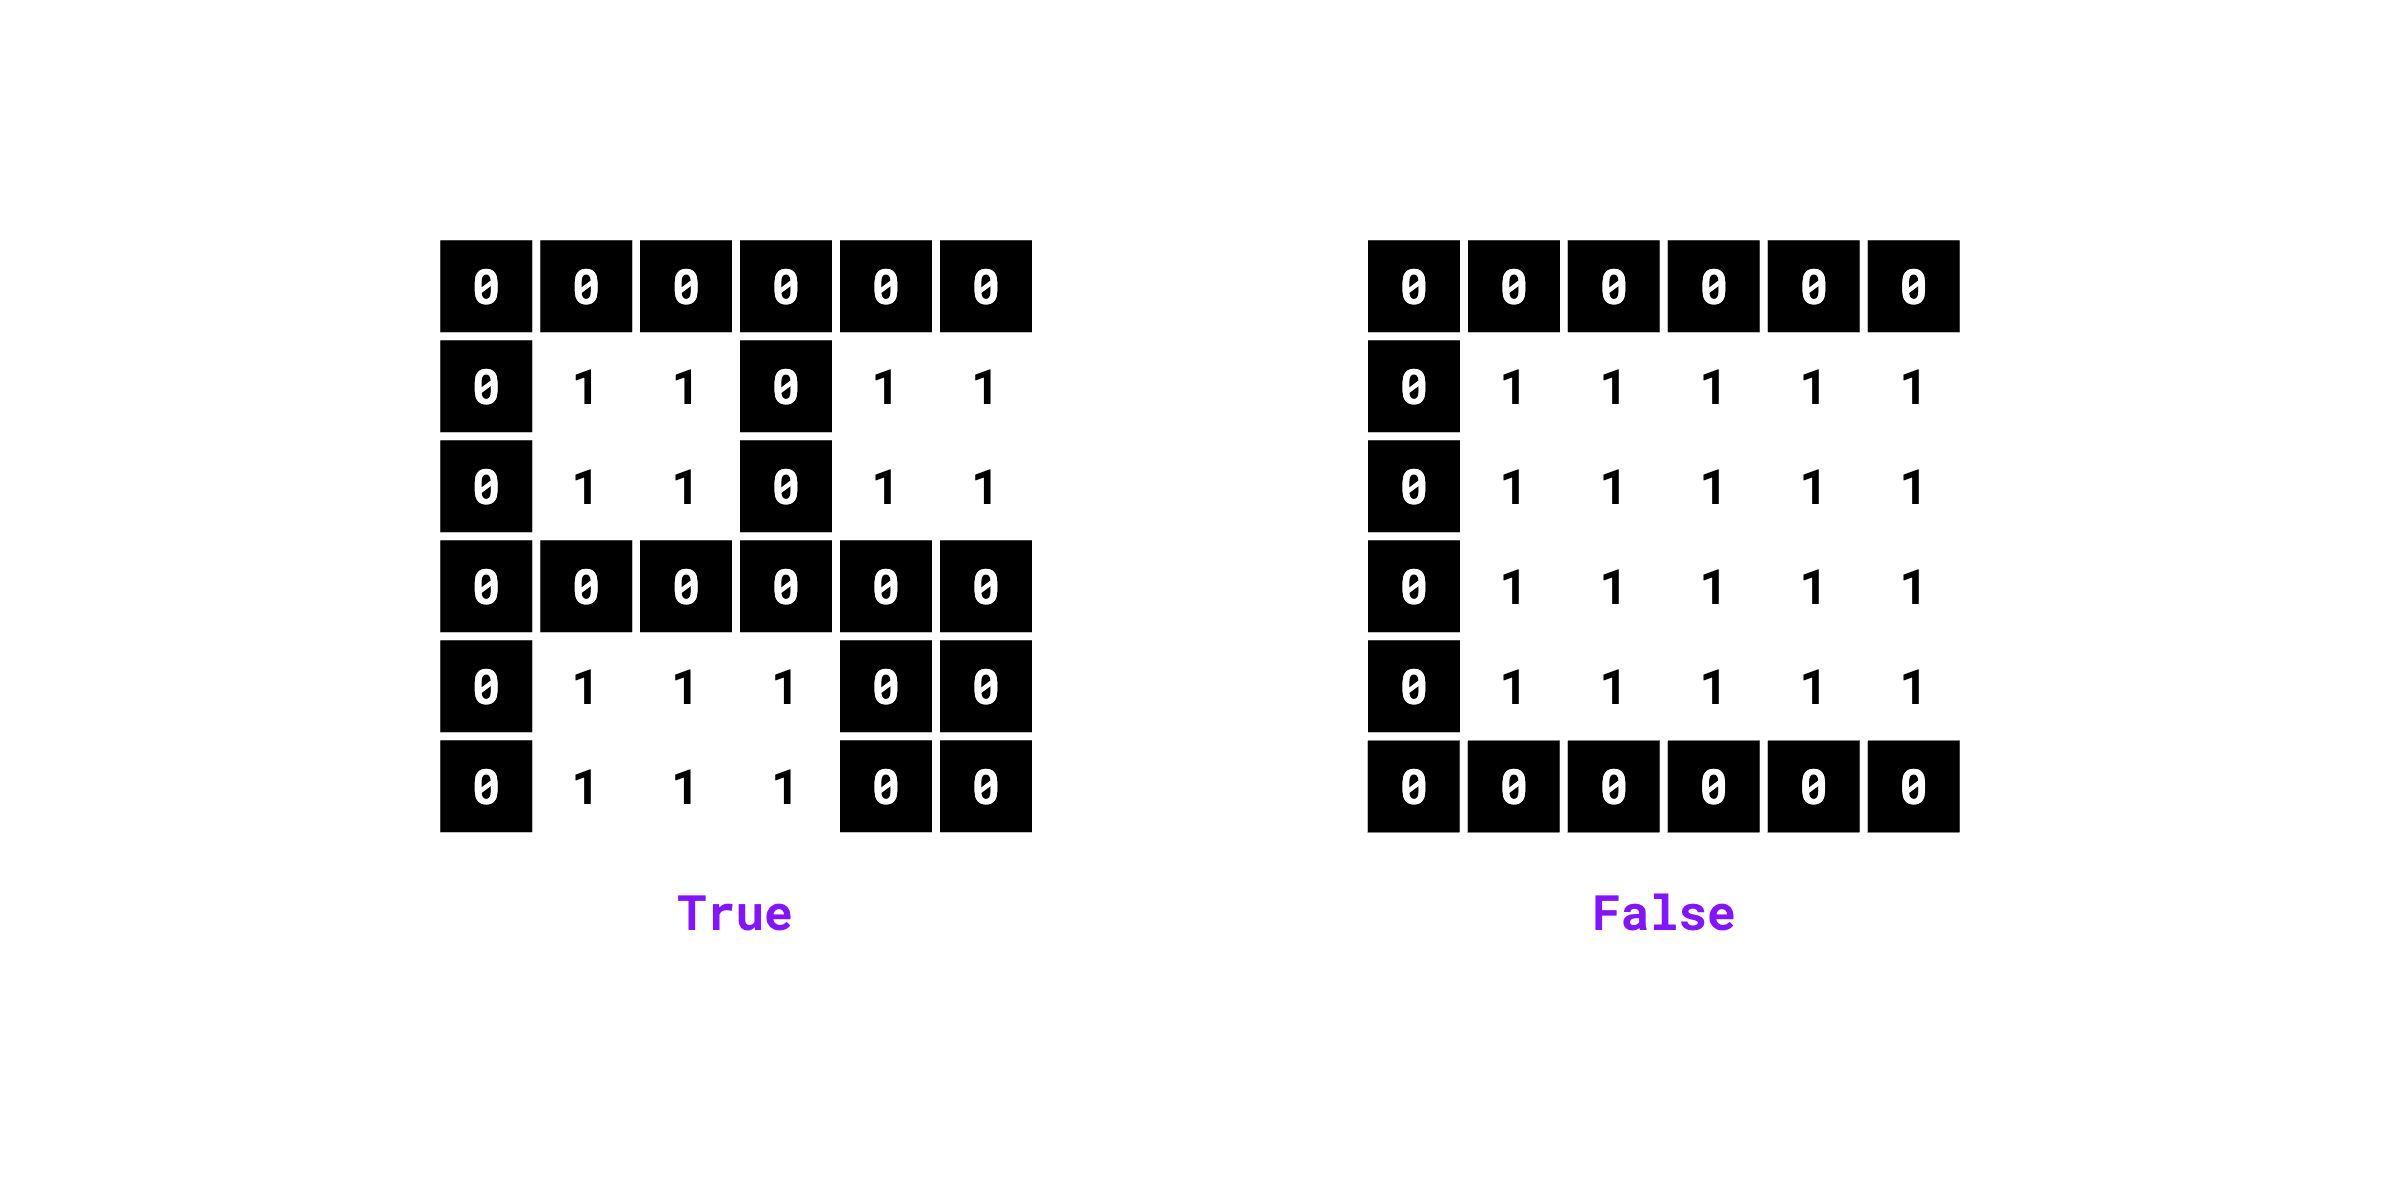{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if connectivity != 4 and connectivity != 8:
|
||||
raise ValueError(
|
||||
"Incorrect connectivity value. Possible connectivity values: 4 or 8."
|
||||
)
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
labels = np.zeros_like(mask_uint8, dtype=np.int32)
|
||||
number_of_labels, _ = cv2.connectedComponents(
|
||||
mask_uint8, labels, connectivity=connectivity
|
||||
)
|
||||
return number_of_labels > 2
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
return resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
@@ -0,0 +1,85 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def filter_polygons_by_area(
|
||||
polygons: list[np.ndarray],
|
||||
min_area: float | None = None,
|
||||
max_area: float | None = None,
|
||||
) -> list[np.ndarray]:
|
||||
"""
|
||||
Filters a list of polygons based on their area.
|
||||
|
||||
Parameters:
|
||||
polygons (List[np.ndarray]): A list of polygons, where each polygon is
|
||||
represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
min_area (Optional[float]): The minimum area threshold.
|
||||
Only polygons with an area greater than or equal to this value
|
||||
will be included in the output. If set to None,
|
||||
no minimum area constraint will be applied.
|
||||
max_area (Optional[float]): The maximum area threshold.
|
||||
Only polygons with an area less than or equal to this value
|
||||
will be included in the output. If set to None,
|
||||
no maximum area constraint will be applied.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A new list of polygons containing only those with
|
||||
areas within the specified thresholds.
|
||||
"""
|
||||
if min_area is None and max_area is None:
|
||||
return polygons
|
||||
ares = [cv2.contourArea(polygon) for polygon in polygons]
|
||||
return [
|
||||
polygon
|
||||
for polygon, area in zip(polygons, ares)
|
||||
if (min_area is None or area >= min_area)
|
||||
and (max_area is None or area <= max_area)
|
||||
]
|
||||
|
||||
|
||||
def approximate_polygon(
|
||||
polygon: np.ndarray, percentage: float, epsilon_step: float = 0.05
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Approximates a given polygon by reducing a certain percentage of points.
|
||||
|
||||
This function uses the Ramer-Douglas-Peucker algorithm to simplify the input
|
||||
polygon by reducing the number of points
|
||||
while preserving the general shape.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A 2D NumPy array of shape `(N, 2)` containing
|
||||
the `x`, `y` coordinates of the input polygon's points.
|
||||
percentage (float): The percentage of points to be removed from the
|
||||
input polygon, in the range `[0, 1)`.
|
||||
epsilon_step (float): Approximation accuracy step.
|
||||
Epsilon is the maximum distance between the original curve
|
||||
and its approximation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A new 2D NumPy array of shape `(M, 2)`,
|
||||
where `M <= N * (1 - percentage)`, containing
|
||||
the `x`, `y` coordinates of the
|
||||
approximated polygon's points.
|
||||
"""
|
||||
|
||||
if percentage < 0 or percentage >= 1:
|
||||
raise ValueError("Percentage must be in the range [0, 1).")
|
||||
|
||||
target_points = max(int(len(polygon) * (1 - percentage)), 3)
|
||||
|
||||
if len(polygon) <= target_points:
|
||||
return polygon
|
||||
|
||||
epsilon = 0
|
||||
approximated_points = polygon
|
||||
while True:
|
||||
epsilon += epsilon_step
|
||||
new_approximated_points = cv2.approxPolyDP(polygon, epsilon, closed=True)
|
||||
if len(new_approximated_points) > target_points:
|
||||
approximated_points = new_approximated_points
|
||||
else:
|
||||
break
|
||||
|
||||
return np.squeeze(approximated_points, axis=1)
|
||||
@@ -10,11 +10,8 @@ from typing import Any
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.detection.utils import (
|
||||
denormalize_boxes,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
)
|
||||
from supervision.detection.utils.boxes import denormalize_boxes
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.validators import validate_resolution
|
||||
|
||||
|
||||
@@ -7,7 +7,7 @@ import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.utils import pad_boxes, spread_out_boxes
|
||||
from supervision.detection.utils.boxes import pad_boxes, spread_out_boxes
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rounded_rectangle
|
||||
from supervision.geometry.core import Rect
|
||||
|
||||
@@ -9,7 +9,7 @@ import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import get_data_item, is_data_equal
|
||||
from supervision.detection.utils.internal import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_keypoints_fields
|
||||
|
||||
|
||||
|
||||
@@ -9,7 +9,7 @@ import numpy as np
|
||||
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import box_iou_batch
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
|
||||
def detections_to_tensor(
|
||||
|
||||
@@ -9,11 +9,9 @@ from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
mask_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch, mask_iou_batch, \
|
||||
oriented_box_iou_batch
|
||||
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import AveragingMethod, Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
|
||||
@@ -9,11 +9,9 @@ from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
mask_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch, mask_iou_batch, \
|
||||
oriented_box_iou_batch
|
||||
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
|
||||
@@ -9,11 +9,8 @@ from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
mask_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch, mask_iou_batch, \
|
||||
oriented_box_iou_batch
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import AveragingMethod, Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
|
||||
@@ -9,11 +9,9 @@ from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
mask_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch, mask_iou_batch, \
|
||||
oriented_box_iou_batch
|
||||
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import AveragingMethod, Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import box_iou_batch
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
from supervision.tracker.byte_tracker import matching
|
||||
from supervision.tracker.byte_tracker.kalman_filter import KalmanFilter
|
||||
from supervision.tracker.byte_tracker.single_object_track import STrack, TrackState
|
||||
|
||||
@@ -5,7 +5,7 @@ from typing import TYPE_CHECKING
|
||||
import numpy as np
|
||||
from scipy.optimize import linear_sum_assignment
|
||||
|
||||
from supervision.detection.utils import box_iou_batch
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from supervision.tracker.byte_tracker.core import STrack
|
||||
|
||||
File diff suppressed because it is too large.
Load diff
@@ -6,7 +6,7 @@ import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.overlap_filter import OverlapFilter
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
|
||||
|
||||
|
||||
Whitespace-only changes.
@@ -0,0 +1,144 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.boxes import clip_boxes, move_boxes, scale_boxes
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, resolution_wh, expected_result",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
(1280, 720),
|
||||
np.empty(shape=(0, 4)),
|
||||
),
|
||||
(
|
||||
np.array([[1.0, 1.0, 1279.0, 719.0]]),
|
||||
(1280, 720),
|
||||
np.array([[1.0, 1.0, 1279.0, 719.0]]),
|
||||
),
|
||||
(
|
||||
np.array([[-1.0, 1.0, 1279.0, 719.0]]),
|
||||
(1280, 720),
|
||||
np.array([[0.0, 1.0, 1279.0, 719.0]]),
|
||||
),
|
||||
(
|
||||
np.array([[1.0, -1.0, 1279.0, 719.0]]),
|
||||
(1280, 720),
|
||||
np.array([[1.0, 0.0, 1279.0, 719.0]]),
|
||||
),
|
||||
(
|
||||
np.array([[1.0, 1.0, 1281.0, 719.0]]),
|
||||
(1280, 720),
|
||||
np.array([[1.0, 1.0, 1280.0, 719.0]]),
|
||||
),
|
||||
(
|
||||
np.array([[1.0, 1.0, 1279.0, 721.0]]),
|
||||
(1280, 720),
|
||||
np.array([[1.0, 1.0, 1279.0, 720.0]]),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_clip_boxes(
|
||||
xyxy: np.ndarray,
|
||||
resolution_wh: tuple[int, int],
|
||||
expected_result: np.ndarray,
|
||||
) -> None:
|
||||
result = clip_boxes(xyxy=xyxy, resolution_wh=resolution_wh)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, offset, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
np.array([0, 0]),
|
||||
np.empty(shape=(0, 4)),
|
||||
DoesNotRaise(),
|
||||
), # empty xyxy array
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
np.array([0, 0]),
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with zero offset
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
np.array([10, 10]),
|
||||
np.array([[10, 10, 20, 20]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with non-zero offset
|
||||
(
|
||||
np.array([[0, 0, 10, 10], [0, 0, 10, 10]]),
|
||||
np.array([10, 10]),
|
||||
np.array([[10, 10, 20, 20], [10, 10, 20, 20]]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with non-zero offset
|
||||
(
|
||||
np.array([[0, 0, 10, 10], [0, 0, 10, 10]]),
|
||||
np.array([-10, -10]),
|
||||
np.array([[-10, -10, 0, 0], [-10, -10, 0, 0]]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with negative offset
|
||||
],
|
||||
)
|
||||
def test_move_boxes(
|
||||
xyxy: np.ndarray,
|
||||
offset: np.ndarray,
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = move_boxes(xyxy=xyxy, offset=offset)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, factor, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
2.0,
|
||||
np.empty(shape=(0, 4)),
|
||||
DoesNotRaise(),
|
||||
), # empty xyxy array
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
1.0,
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 1.0
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
2.0,
|
||||
np.array([[-5, -5, 15, 15]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 2.0
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
0.5,
|
||||
np.array([[2.5, 2.5, 7.5, 7.5]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 0.5
|
||||
(
|
||||
np.array([[0, 0, 10, 10], [10, 10, 30, 30]]),
|
||||
2.0,
|
||||
np.array([[-5, -5, 15, 15], [0, 0, 40, 40]]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with factor equal to 2.0
|
||||
],
|
||||
)
|
||||
def test_scale_boxes(
|
||||
xyxy: np.ndarray,
|
||||
factor: float,
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = scale_boxes(xyxy=xyxy, factor=factor)
|
||||
assert np.array_equal(result, expected_result)
|
||||
@@ -0,0 +1,127 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.converters import xywh_to_xyxy, xyxy_to_xywh, \
|
||||
xyxy_to_xcycarh, xcycwh_to_xyxy
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xywh, expected_result",
|
||||
[
|
||||
(np.array([[10, 20, 30, 40]]), np.array([[10, 20, 40, 60]])), # standard case
|
||||
(np.array([[0, 0, 0, 0]]), np.array([[0, 0, 0, 0]])), # zero size bounding box
|
||||
(
|
||||
np.array([[50, 50, 100, 100]]),
|
||||
np.array([[50, 50, 150, 150]]),
|
||||
), # large bounding box
|
||||
(
|
||||
np.array([[-10, -20, 30, 40]]),
|
||||
np.array([[-10, -20, 20, 20]]),
|
||||
), # negative coordinates
|
||||
(np.array([[50, 50, 0, 30]]), np.array([[50, 50, 50, 80]])), # zero width
|
||||
(np.array([[50, 50, 20, 0]]), np.array([[50, 50, 70, 50]])), # zero height
|
||||
(np.array([]).reshape(0, 4), np.array([]).reshape(0, 4)), # empty array
|
||||
],
|
||||
)
|
||||
def test_xywh_to_xyxy(xywh: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xywh_to_xyxy(xywh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, expected_result",
|
||||
[
|
||||
(np.array([[10, 20, 40, 60]]), np.array([[10, 20, 30, 40]])), # standard case
|
||||
(np.array([[0, 0, 0, 0]]), np.array([[0, 0, 0, 0]])), # zero size bounding box
|
||||
(
|
||||
np.array([[50, 50, 150, 150]]),
|
||||
np.array([[50, 50, 100, 100]]),
|
||||
), # large bounding box
|
||||
(
|
||||
np.array([[-10, -20, 20, 20]]),
|
||||
np.array([[-10, -20, 30, 40]]),
|
||||
), # negative coordinates
|
||||
(np.array([[50, 50, 50, 80]]), np.array([[50, 50, 0, 30]])), # zero width
|
||||
(np.array([[50, 50, 70, 50]]), np.array([[50, 50, 20, 0]])), # zero height
|
||||
(np.array([]).reshape(0, 4), np.array([]).reshape(0, 4)), # empty array
|
||||
],
|
||||
)
|
||||
def test_xyxy_to_xywh(xyxy: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xyxy_to_xywh(xyxy)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, expected_result",
|
||||
[
|
||||
# Empty and zero cases
|
||||
(np.array([]).reshape(0, 4), np.array([]).reshape(0, 4)), # empty array
|
||||
(
|
||||
np.array([[0, 0, 0, 0]]),
|
||||
np.array([[0, 0, 0.0, 0]]),
|
||||
), # zero size bounding box
|
||||
(
|
||||
np.array([[10, 10, 10, 10]]),
|
||||
np.array([[10, 10, 0.0, 0]]),
|
||||
), # point (x1=x2, y1=y2)
|
||||
# Zero width/height cases
|
||||
(np.array([[50, 50, 80, 50]]), np.array([[65, 50, 0.0, 0]])), # zero height
|
||||
(np.array([[50, 50, 50, 80]]), np.array([[50, 65, 0.0, 30]])), # zero width
|
||||
# Standard cases
|
||||
(np.array([[10, 20, 40, 60]]), np.array([[25, 40, 0.75, 40]])), # standard case
|
||||
(
|
||||
np.array([[-30, -40, -10, -20]]),
|
||||
np.array([[-20, -30, 1.0, 20]]),
|
||||
), # all negative values
|
||||
(
|
||||
np.array([[0.1, 0.2, 0.4, 0.6]]),
|
||||
np.array([[0.25, 0.4, 0.75, 0.4]]),
|
||||
), # values between 0-1
|
||||
# Different aspect ratios
|
||||
(
|
||||
np.array([[10, 20, 50, 100]]),
|
||||
np.array([[30, 60, 0.5, 80]]),
|
||||
), # tall rectangle (height > width)
|
||||
(
|
||||
np.array([[20, 10, 100, 50]]),
|
||||
np.array([[60, 30, 2.0, 40]]),
|
||||
), # wide rectangle (width > height)
|
||||
(
|
||||
np.array([[50, 50, 150, 150]]),
|
||||
np.array([[100, 100, 1.0, 100]]),
|
||||
), # height == width
|
||||
# Multiple boxes in one array
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [10, 20, 40, 60]]),
|
||||
np.array([[0, 0, 0.0, 0], [25, 40, 0.75, 40]]),
|
||||
), # one zero-sized box and one normal box
|
||||
],
|
||||
)
|
||||
def test_xyxy_to_xcycarh(xyxy: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xyxy_to_xcycarh(xyxy)
|
||||
np.testing.assert_allclose(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xcycwh, expected_result",
|
||||
[
|
||||
(np.array([[50, 50, 20, 30]]), np.array([[40, 35, 60, 65]])), # standard case
|
||||
(np.array([[0, 0, 0, 0]]), np.array([[0, 0, 0, 0]])), # zero size bounding box
|
||||
(
|
||||
np.array([[50, 50, 100, 100]]),
|
||||
np.array([[0, 0, 100, 100]]),
|
||||
), # large bounding box centered at (50, 50)
|
||||
(
|
||||
np.array([[-10, -10, 20, 30]]),
|
||||
np.array([[-20, -25, 0, 5]]),
|
||||
), # negative coordinates
|
||||
(np.array([[50, 50, 0, 30]]), np.array([[50, 35, 50, 65]])), # zero width
|
||||
(np.array([[50, 50, 20, 0]]), np.array([[40, 50, 60, 50]])), # zero height
|
||||
(np.array([]).reshape(0, 4), np.array([]).reshape(0, 4)), # empty array
|
||||
],
|
||||
)
|
||||
def test_xcycwh_to_xyxy(xcycwh: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xcycwh_to_xyxy(xcycwh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
@@ -0,0 +1,786 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils.internal import process_roboflow_result, merge_data, \
|
||||
get_data_item, merge_metadata
|
||||
|
||||
TEST_MASK = np.zeros((1, 1000, 1000), dtype=bool)
|
||||
TEST_MASK[:, 300:351, 200:251] = True
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"roboflow_result, expected_result, exception",
|
||||
[
|
||||
(
|
||||
{"predictions": [], "image": {"width": 1000, "height": 1000}},
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # empty result
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
}
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.array([[175.0, 275.0, 225.0, 325.0]]),
|
||||
np.array([0.9]),
|
||||
np.array([0]),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single correct object detection result
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
"tracker_id": 1,
|
||||
},
|
||||
{
|
||||
"x": 500.0,
|
||||
"y": 500.0,
|
||||
"width": 100.0,
|
||||
"height": 100.0,
|
||||
"confidence": 0.8,
|
||||
"class_id": 7,
|
||||
"class": "truck",
|
||||
"tracker_id": 2,
|
||||
},
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.array([[175.0, 275.0, 225.0, 325.0], [450.0, 450.0, 550.0, 550.0]]),
|
||||
np.array([0.9, 0.8]),
|
||||
np.array([0, 7]),
|
||||
None,
|
||||
np.array([1, 2]),
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person", "truck"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two correct object detection result
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
"points": [],
|
||||
"tracker_id": None,
|
||||
}
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no points
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
"points": [{"x": 200.0, "y": 300.0}, {"x": 250.0, "y": 300.0}],
|
||||
}
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no enough points
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
"points": [
|
||||
{"x": 200.0, "y": 300.0},
|
||||
{"x": 250.0, "y": 300.0},
|
||||
{"x": 250.0, "y": 350.0},
|
||||
{"x": 200.0, "y": 350.0},
|
||||
],
|
||||
}
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.array([[175.0, 275.0, 225.0, 325.0]]),
|
||||
np.array([0.9]),
|
||||
np.array([0]),
|
||||
TEST_MASK,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no enough points
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class_id": 0,
|
||||
"class": "person",
|
||||
"points": [
|
||||
{"x": 200.0, "y": 300.0},
|
||||
{"x": 250.0, "y": 300.0},
|
||||
{"x": 250.0, "y": 350.0},
|
||||
{"x": 200.0, "y": 350.0},
|
||||
],
|
||||
},
|
||||
{
|
||||
"x": 500.0,
|
||||
"y": 500.0,
|
||||
"width": 100.0,
|
||||
"height": 100.0,
|
||||
"confidence": 0.8,
|
||||
"class_id": 7,
|
||||
"class": "truck",
|
||||
"points": [],
|
||||
},
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(
|
||||
np.array([[175.0, 275.0, 225.0, 325.0]]),
|
||||
np.array([0.9]),
|
||||
np.array([0]),
|
||||
TEST_MASK,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two instance segmentation results - one correct, one incorrect
|
||||
],
|
||||
)
|
||||
def test_process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
expected_result: tuple[
|
||||
np.ndarray, np.ndarray, np.ndarray, np.ndarray | None, np.ndarray
|
||||
],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = process_roboflow_result(roboflow_result=roboflow_result)
|
||||
assert np.array_equal(result[0], expected_result[0])
|
||||
assert np.array_equal(result[1], expected_result[1])
|
||||
assert np.array_equal(result[2], expected_result[2])
|
||||
assert (result[3] is None and expected_result[3] is None) or (
|
||||
np.array_equal(result[3], expected_result[3])
|
||||
)
|
||||
assert (result[4] is None and expected_result[4] is None) or (
|
||||
np.array_equal(result[4], expected_result[4])
|
||||
)
|
||||
for key in result[5]:
|
||||
if isinstance(result[5][key], np.ndarray):
|
||||
assert np.array_equal(result[5][key], expected_result[5][key]), (
|
||||
f"Mismatch in arrays for key {key}"
|
||||
)
|
||||
else:
|
||||
assert result[5][key] == expected_result[5][key], (
|
||||
f"Mismatch in non-array data for key {key}"
|
||||
)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"data_list, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # empty data list
|
||||
(
|
||||
[{}],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # single empty data dict
|
||||
(
|
||||
[{}, {}],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # two empty data dicts
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
],
|
||||
{"test_1": []},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty list values
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
{"test_1": []},
|
||||
],
|
||||
{"test_1": []},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty list values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([])},
|
||||
],
|
||||
{"test_1": np.array([])},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([])},
|
||||
{"test_1": np.array([])},
|
||||
],
|
||||
{"test_1": np.array([])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
],
|
||||
{"test_1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
{"test_1": [3, 2, 1]},
|
||||
],
|
||||
{"test_1": [3, 2, 1]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name; one of with empty list as value
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [3, 2, 1]},
|
||||
],
|
||||
{"test_1": [1, 2, 3, 3, 2, 1]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [3, 2, 1]},
|
||||
{"test_1": [1, 2, 3]},
|
||||
],
|
||||
{"test_1": [1, 2, 3, 3, 2, 1, 1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # three data dicts with the same field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_2": [3, 2, 1]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with different field names
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3])},
|
||||
{"test_1": np.array([3, 2, 1])},
|
||||
],
|
||||
{"test_1": np.array([1, 2, 3, 3, 2, 1])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and np.array values as 1D arrays
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([[1, 2, 3]])},
|
||||
{"test_1": np.array([[3, 2, 1]])},
|
||||
],
|
||||
{"test_1": np.array([[1, 2, 3], [3, 2, 1]])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and np.array values as 2D arrays
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": np.array(["a", "b", "c"])},
|
||||
{"test_1": np.array([3, 2, 1]), "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
{
|
||||
"test_1": np.array([1, 2, 3, 3, 2, 1]),
|
||||
"test_2": np.array(["a", "b", "c", "c", "b", "a"]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field names and np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3], "test_2": np.array(["a", "b", "c"])},
|
||||
{"test_1": [3, 2, 1], "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
{
|
||||
"test_1": [1, 2, 3, 3, 2, 1],
|
||||
"test_2": np.array(["a", "b", "c", "c", "b", "a"]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field names and mixed values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3])},
|
||||
{"test_1": np.array([[3, 2, 1]])},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with the same field name and 1D and 2D arrays values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": np.array(["a", "b"])},
|
||||
{"test_1": np.array([3, 2, 1]), "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with the same field name and different length arrays values
|
||||
(
|
||||
[{}, {"test_1": [1, 2, 3]}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one empty and one non-empty dict
|
||||
(
|
||||
[{"test_1": [], "test_2": []}, {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}],
|
||||
{"test_1": [1, 2, 3], "test_2": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts; one empty and one non-empty dict; same keys
|
||||
(
|
||||
[{"test_1": []}, {"test_1": [1, 2, 3], "test_2": [4, 5, 6]}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one empty and one non-empty dict; different keys
|
||||
(
|
||||
[
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
"test_2": [4, 5, 6],
|
||||
"test_3": [7, 8, 9],
|
||||
},
|
||||
{"test_1": [1, 2, 3], "test_2": [4, 5, 6]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts; one with three keys, one with two keys
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [1, 2, 3], "test_2": [1, 2, 3]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # some keys missing in one dict
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3], "test_2": ["a", "b"]},
|
||||
{"test_1": [4, 5], "test_2": ["c", "d", "e"]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # different value lengths for the same key
|
||||
],
|
||||
)
|
||||
def test_merge_data(
|
||||
data_list: list[dict[str, Any]],
|
||||
expected_result: dict[str, Any] | None,
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = merge_data(data_list=data_list)
|
||||
if expected_result is None:
|
||||
assert False, f"Expected an error, but got result {result}"
|
||||
|
||||
for key in result:
|
||||
if isinstance(result[key], np.ndarray):
|
||||
assert np.array_equal(result[key], expected_result[key]), (
|
||||
f"Mismatch in arrays for key {key}"
|
||||
)
|
||||
else:
|
||||
assert result[key] == expected_result[key], (
|
||||
f"Mismatch in non-array data for key {key}"
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"data, index, expected_result, exception",
|
||||
[
|
||||
({}, 0, {}, DoesNotRaise()), # empty data dict
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
0,
|
||||
{
|
||||
"test_1": [1],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single list field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
0,
|
||||
{
|
||||
"test_1": np.array([1]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
slice(0, 2),
|
||||
{
|
||||
"test_1": [1, 2],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single list field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
slice(0, 2),
|
||||
{
|
||||
"test_1": np.array([1, 2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
-1,
|
||||
{
|
||||
"test_1": [3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single list field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
-1,
|
||||
{
|
||||
"test_1": np.array([3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
[0, 2],
|
||||
{
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single list field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
[0, 2],
|
||||
{
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
np.array([0, 2]),
|
||||
{
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single list field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([0, 2]),
|
||||
{
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([True, True, True]),
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-true bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, False, False]),
|
||||
{
|
||||
"test_1": np.array([]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-false bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, True, False]),
|
||||
{
|
||||
"test_1": np.array([2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and mixed bool np.array index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
0,
|
||||
{"test_1": np.array([1]), "test_2": ["a"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
-1,
|
||||
{"test_1": np.array([3]), "test_2": ["c"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and negative integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
np.array([False, True, False]),
|
||||
{"test_1": np.array([2]), "test_2": ["b"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and mixed bool np.array index
|
||||
],
|
||||
)
|
||||
def test_get_data_item(
|
||||
data: dict[str, Any],
|
||||
index: Any,
|
||||
expected_result: dict[str, Any] | None,
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = get_data_item(data=data, index=index)
|
||||
for key in result:
|
||||
if isinstance(result[key], np.ndarray):
|
||||
assert np.array_equal(result[key], expected_result[key]), (
|
||||
f"Mismatch in arrays for key {key}"
|
||||
)
|
||||
else:
|
||||
assert result[key] == expected_result[key], (
|
||||
f"Mismatch in non-array data for key {key}"
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"metadata_list, expected_result, exception",
|
||||
[
|
||||
# Identical metadata with a single key
|
||||
([{"key1": "value1"}, {"key1": "value1"}], {"key1": "value1"}, DoesNotRaise()),
|
||||
# Identical metadata with multiple keys
|
||||
(
|
||||
[
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
],
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting values for the same key
|
||||
([{"key1": "value1"}, {"key1": "value2"}], None, pytest.raises(ValueError)),
|
||||
# Different sets of keys across dictionaries
|
||||
([{"key1": "value1"}, {"key2": "value2"}], None, pytest.raises(ValueError)),
|
||||
# Empty metadata list
|
||||
([], {}, DoesNotRaise()),
|
||||
# Empty metadata dictionaries
|
||||
([{}, {}], {}, DoesNotRaise()),
|
||||
# Different declaration order for keys
|
||||
(
|
||||
[
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
{"key2": "value2", "key1": "value1"},
|
||||
],
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Nested metadata dictionaries
|
||||
(
|
||||
[{"key1": {"sub_key": "sub_value"}}, {"key1": {"sub_key": "sub_value"}}],
|
||||
{"key1": {"sub_key": "sub_value"}},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Large metadata dictionaries with many keys
|
||||
(
|
||||
[
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
],
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Mixed types in list metadata values
|
||||
(
|
||||
[{"key1": ["value1", 2, True]}, {"key1": ["value1", 2, True]}],
|
||||
{"key1": ["value1", 2, True]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical lists across metadata dictionaries
|
||||
(
|
||||
[{"key1": [1, 2, 3]}, {"key1": [1, 2, 3]}],
|
||||
{"key1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical numpy arrays across metadata dictionaries
|
||||
(
|
||||
[{"key1": np.array([1, 2, 3])}, {"key1": np.array([1, 2, 3])}],
|
||||
{"key1": np.array([1, 2, 3])},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical numpy arrays across metadata dictionaries, different datatype
|
||||
(
|
||||
[
|
||||
{"key1": np.array([1, 2, 3], dtype=np.int32)},
|
||||
{"key1": np.array([1, 2, 3], dtype=np.int64)},
|
||||
],
|
||||
{"key1": np.array([1, 2, 3])},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting lists for the same key
|
||||
([{"key1": [1, 2, 3]}, {"key1": [4, 5, 6]}], None, pytest.raises(ValueError)),
|
||||
# Conflicting numpy arrays for the same key
|
||||
(
|
||||
[{"key1": np.array([1, 2, 3])}, {"key1": np.array([4, 5, 6])}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Mixed data types: list and numpy array for the same key
|
||||
(
|
||||
[{"key1": [1, 2, 3]}, {"key1": np.array([1, 2, 3])}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Empty lists and numpy arrays for the same key
|
||||
([{"key1": []}, {"key1": np.array([])}], None, pytest.raises(ValueError)),
|
||||
# Identical multi-dimensional lists across metadata dictionaries
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": [[1, 2], [3, 4]]}],
|
||||
{"key1": [[1, 2], [3, 4]]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical multi-dimensional numpy arrays across metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
],
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting multi-dimensional lists for the same key
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": [[5, 6], [7, 8]]}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Conflicting multi-dimensional numpy arrays for the same key
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
{"key1": np.arange(4, 8).reshape(2, 2)},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Mixed types with multi-dimensional list and array for the same key
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": np.arange(4).reshape(2, 2)}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Identical higher-dimensional (3D) numpy arrays across
|
||||
# metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
],
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Differently-shaped higher-dimensional (3D) numpy arrays
|
||||
# across metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
{"key1": np.arange(8).reshape(4, 1, 2)},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_merge_metadata(metadata_list, expected_result, exception):
|
||||
with exception:
|
||||
result = merge_metadata(metadata_list)
|
||||
if expected_result is None:
|
||||
assert result is None, f"Expected an error, but got a result {result}"
|
||||
for key, value in result.items():
|
||||
assert key in expected_result
|
||||
if isinstance(value, np.ndarray):
|
||||
np.testing.assert_array_equal(value, expected_result[key])
|
||||
else:
|
||||
assert value == expected_result[key]
|
||||
@@ -5,12 +5,8 @@ from contextlib import ExitStack as DoesNotRaise
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_suppression,
|
||||
group_overlapping_boxes,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import box_non_max_suppression, \
|
||||
mask_non_max_suppression, mask_non_max_merge, _group_overlapping_boxes
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
@@ -133,7 +129,7 @@ def test_group_overlapping_boxes(
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = group_overlapping_boxes(
|
||||
result = _group_overlapping_boxes(
|
||||
predictions=predictions, iou_threshold=iou_threshold
|
||||
)
|
||||
|
||||
@@ -0,0 +1,498 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.masks import move_masks, calculate_masks_centroids, \
|
||||
contains_holes, contains_multiple_segments
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"masks, offset, resolution_wh, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([0, 0]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-1, -1]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, False, False],
|
||||
[True, True, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, -2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-3, -3]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, -1]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, False, False, False],
|
||||
[True, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-1, -2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, 2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[True, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([3, 3]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([3, 3]),
|
||||
(6, 6),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, True, True],
|
||||
[False, False, False, False, True, True],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_move_masks(
|
||||
masks: np.ndarray,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: tuple[int, int],
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = move_masks(masks=masks, offset=offset, resolution_wh=resolution_wh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"masks, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[0, 0]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with all zeros
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[2, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with all ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 1, 1, 0],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[0, 1, 1, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[2, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with symmetric ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 0, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[3, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with asymmetric ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 1, 1, 0],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[0, 1, 1, 0],
|
||||
],
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 0, 0],
|
||||
],
|
||||
]
|
||||
),
|
||||
np.array([[2, 2], [3, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # two masks
|
||||
],
|
||||
)
|
||||
def test_calculate_masks_centroids(
|
||||
masks: np.ndarray,
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = calculate_masks_centroids(masks=masks)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in one continuous piece
|
||||
(
|
||||
np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 separate elements
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # no foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # only foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 0], [1, 1, 1, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 1 hole
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 2 holes
|
||||
],
|
||||
)
|
||||
def test_contains_holes(
|
||||
mask: npt.NDArray[np.bool_], expected_result: bool, exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = contains_holes(mask)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, connectivity, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in one continuous piece
|
||||
(
|
||||
np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 separate elements
|
||||
(
|
||||
np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # no foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # only foreground pixels in mask
|
||||
(
|
||||
np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object has 2 holes, but is in single piece
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
4,
|
||||
True,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in 2 elements with respect to 4-way connectivity
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
8,
|
||||
False,
|
||||
DoesNotRaise(),
|
||||
), # foreground object in single piece with respect to 8-way connectivity
|
||||
(
|
||||
np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype(
|
||||
bool
|
||||
),
|
||||
5,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Incorrect connectivity parameter value, raises ValueError
|
||||
],
|
||||
)
|
||||
def test_contains_multiple_segments(
|
||||
mask: npt.NDArray[np.bool_],
|
||||
connectivity: int,
|
||||
expected_result: bool,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = contains_multiple_segments(mask=mask, connectivity=connectivity)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,102 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.polygons import filter_polygons_by_area
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"polygons, min_area, max_area, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
None,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # single polygon without area constraints
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
50,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # single polygon with min_area constraint
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
None,
|
||||
50,
|
||||
[],
|
||||
DoesNotRaise(),
|
||||
), # single polygon with max_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]]),
|
||||
],
|
||||
200,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 20], [20, 20], [20, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # two polygons with min_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]]),
|
||||
],
|
||||
None,
|
||||
200,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # two polygons with max_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]]),
|
||||
],
|
||||
200,
|
||||
200,
|
||||
[],
|
||||
DoesNotRaise(),
|
||||
), # two polygons with both area constraints
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]]),
|
||||
],
|
||||
100,
|
||||
100,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # two polygons with min_area and
|
||||
# max_area equal to the area of the first polygon
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]]),
|
||||
],
|
||||
400,
|
||||
400,
|
||||
[np.array([[0, 0], [0, 20], [20, 20], [20, 0]])],
|
||||
DoesNotRaise(),
|
||||
), # two polygons with min_area and
|
||||
# max_area equal to the area of the second polygon
|
||||
],
|
||||
)
|
||||
def test_filter_polygons_by_area(
|
||||
polygons: list[np.ndarray],
|
||||
min_area: float | None,
|
||||
max_area: float | None,
|
||||
expected_result: list[np.ndarray],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = filter_polygons_by_area(
|
||||
polygons=polygons, min_area=min_area, max_area=max_area
|
||||
)
|
||||
assert len(result) == len(expected_result)
|
||||
for result_polygon, expected_result_polygon in zip(result, expected_result):
|
||||
assert np.array_equal(result_polygon, expected_result_polygon)
|
||||
Reference in new issue
Block a user