Merge remote-tracking branch 'upstream/develop' into add_nmm_to_detections
This commit is contained in:
 Linas Kondrackis committed
commit
b1598733c2
70 files changed
+2104
-776
No files matched your search
File renamed without changes.
@@ -0,0 +1,55 @@
|
||||
name: Supervision Release Documentation Workflow 📚
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
doc-build-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.head_ref }}
|
||||
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions 👷
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material 📚
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push --update-aliases $latest_tag latest
|
||||
@@ -45,7 +45,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.3.5
|
||||
rev: v0.4.2
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
@@ -71,16 +71,15 @@ len(detections)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
model = get_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
# 5
|
||||
```
|
||||
|
||||
</details>
|
||||
@@ -217,19 +216,23 @@ len(dataset)
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
Want to learn how to use Supervision? Explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/), [end-to-end examples](https://github.com/roboflow/supervision/tree/develop/examples), and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/)!
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/a742823d-c158-407d-b30f-063a5d11b4e1" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><strong>Dwell Time Analysis with Computer Vision | Real-Time Stream Processing</strong></a>
|
||||
<div><strong>Created: 5 Apr 2024</strong></div>
|
||||
<br/>Learn how to use computer vision to analyze wait times and optimize processes. This tutorial covers object detection, tracking, and calculating time spent in designated zones. Use these techniques to improve customer experience in retail, traffic management, or other scenarios.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
|
||||
+2
-2
@@ -19,13 +19,13 @@ as an extra within the Supervision package.
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.VideoAssets">VideoAssets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
@@ -1,3 +1,68 @@
|
||||
### 0.20.0 <small>April 24, 2024</small>
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models.
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.EdgeAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`sv.VertexAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator) to enable rendering of results from keypoint detection models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8l-pose')
|
||||
|
||||
result = model(image, verbose=False)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
edge_annotators = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_image = edge_annotators.annotate(image.copy(), keypoints)
|
||||
```
|
||||
|
||||
- Changed [#1037](https://github.com/roboflow/supervision/pull/1037): [`sv.LabelAnnotator`](/0.20.0/annotators/#supervision.annotators.core.LabelAnnotator) by adding an additional `corner_radius` argument that allows for rounding the corners of the bounding box.
|
||||
|
||||
- Changed [#1109](https://github.com/roboflow/supervision/pull/1109): [`sv.PolygonZone`](/0.20.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) such that the `frame_resolution_wh` argument is no longer required to initialize `sv.PolygonZone`.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `frame_resolution_wh` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
||||
- Changed [#1084](https://github.com/roboflow/supervision/pull/1084): [`sv.get_polygon_center`](/0.20.0/utils/geometry/#supervision.geometry.core.utils.get_polygon_center) to calculate a more accurate polygon centroid.
|
||||
|
||||
- Changed [#1069](https://github.com/roboflow/supervision/pull/1069): [`sv.Detections.from_transformers`](/0.20.0/detection/core/#supervision.detection.core.Detections.from_transformers) by adding support for Transformers segmentation models and extract class names values.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results, id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Fixed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack.update_with_detections`](/0.20.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack.update_with_detections) which was removing segmentation masks while tracking. Now, `ByteTrack` can be used alongside segmentation models.
|
||||
|
||||
### 0.19.0 <small>March 15, 2024</small>
|
||||
|
||||
- Added [#818](https://github.com/roboflow/supervision/pull/818): [`sv.CSVSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) allowing for the straightforward saving of image, video, or stream inference results in a `.csv` file.
|
||||
|
||||
+2
-1
@@ -12,7 +12,8 @@ These features are phased out due to better alternatives or potential issues in
|
||||
- The method `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.24.0`.
|
||||
File renamed without changes.
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
+11
-11
@@ -6,67 +6,67 @@ status: new
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
@@ -1,13 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
@@ -1,53 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
@@ -1,7 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
@@ -15,7 +15,7 @@ source image.
|
||||
|
||||
|
||||
|
||||
## Run Inference
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
@@ -27,7 +27,7 @@ model.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
@@ -38,7 +38,7 @@ model.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
@@ -52,7 +52,7 @@ model.
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -78,7 +78,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
@@ -93,7 +93,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
@@ -111,7 +111,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -146,7 +146,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -167,7 +167,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -191,7 +191,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -230,7 +230,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -257,7 +257,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -287,7 +287,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -334,7 +334,7 @@ that will allow you to draw masks instead of boxes.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -355,7 +355,7 @@ that will allow you to draw masks instead of boxes.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
||||
@@ -28,7 +28,7 @@ size relative to the image resolution.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -49,7 +49,7 @@ size relative to the image resolution.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -73,7 +73,7 @@ size relative to the image resolution.
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -116,7 +116,7 @@ is less effective for ultra-high-resolution images (4K and above).
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -137,7 +137,7 @@ is less effective for ultra-high-resolution images (4K and above).
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -171,7 +171,7 @@ objects within each, and aggregating the results.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
@@ -198,7 +198,7 @@ objects within each, and aggregating the results.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
@@ -229,7 +229,7 @@ objects within each, and aggregating the results.
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
|
||||
@@ -0,0 +1,299 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
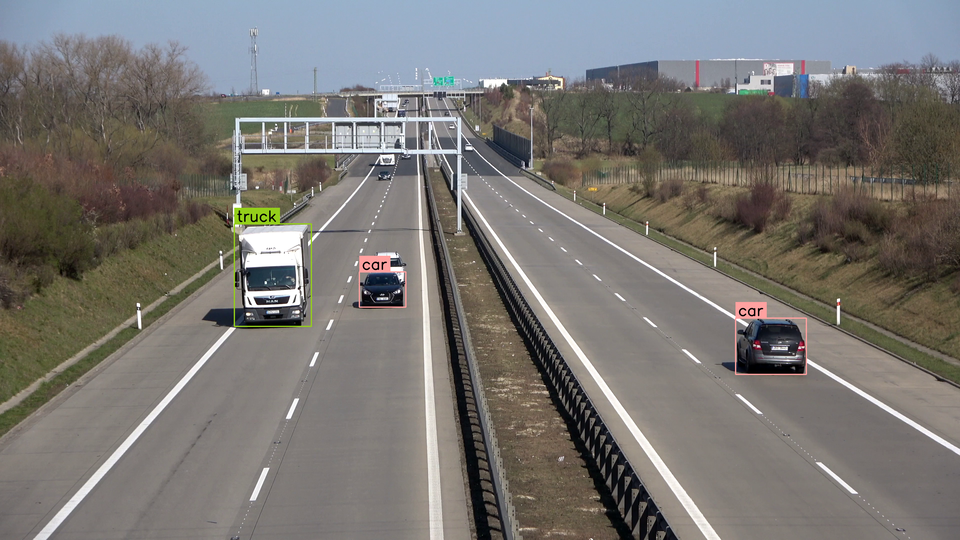
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
@@ -0,0 +1,60 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
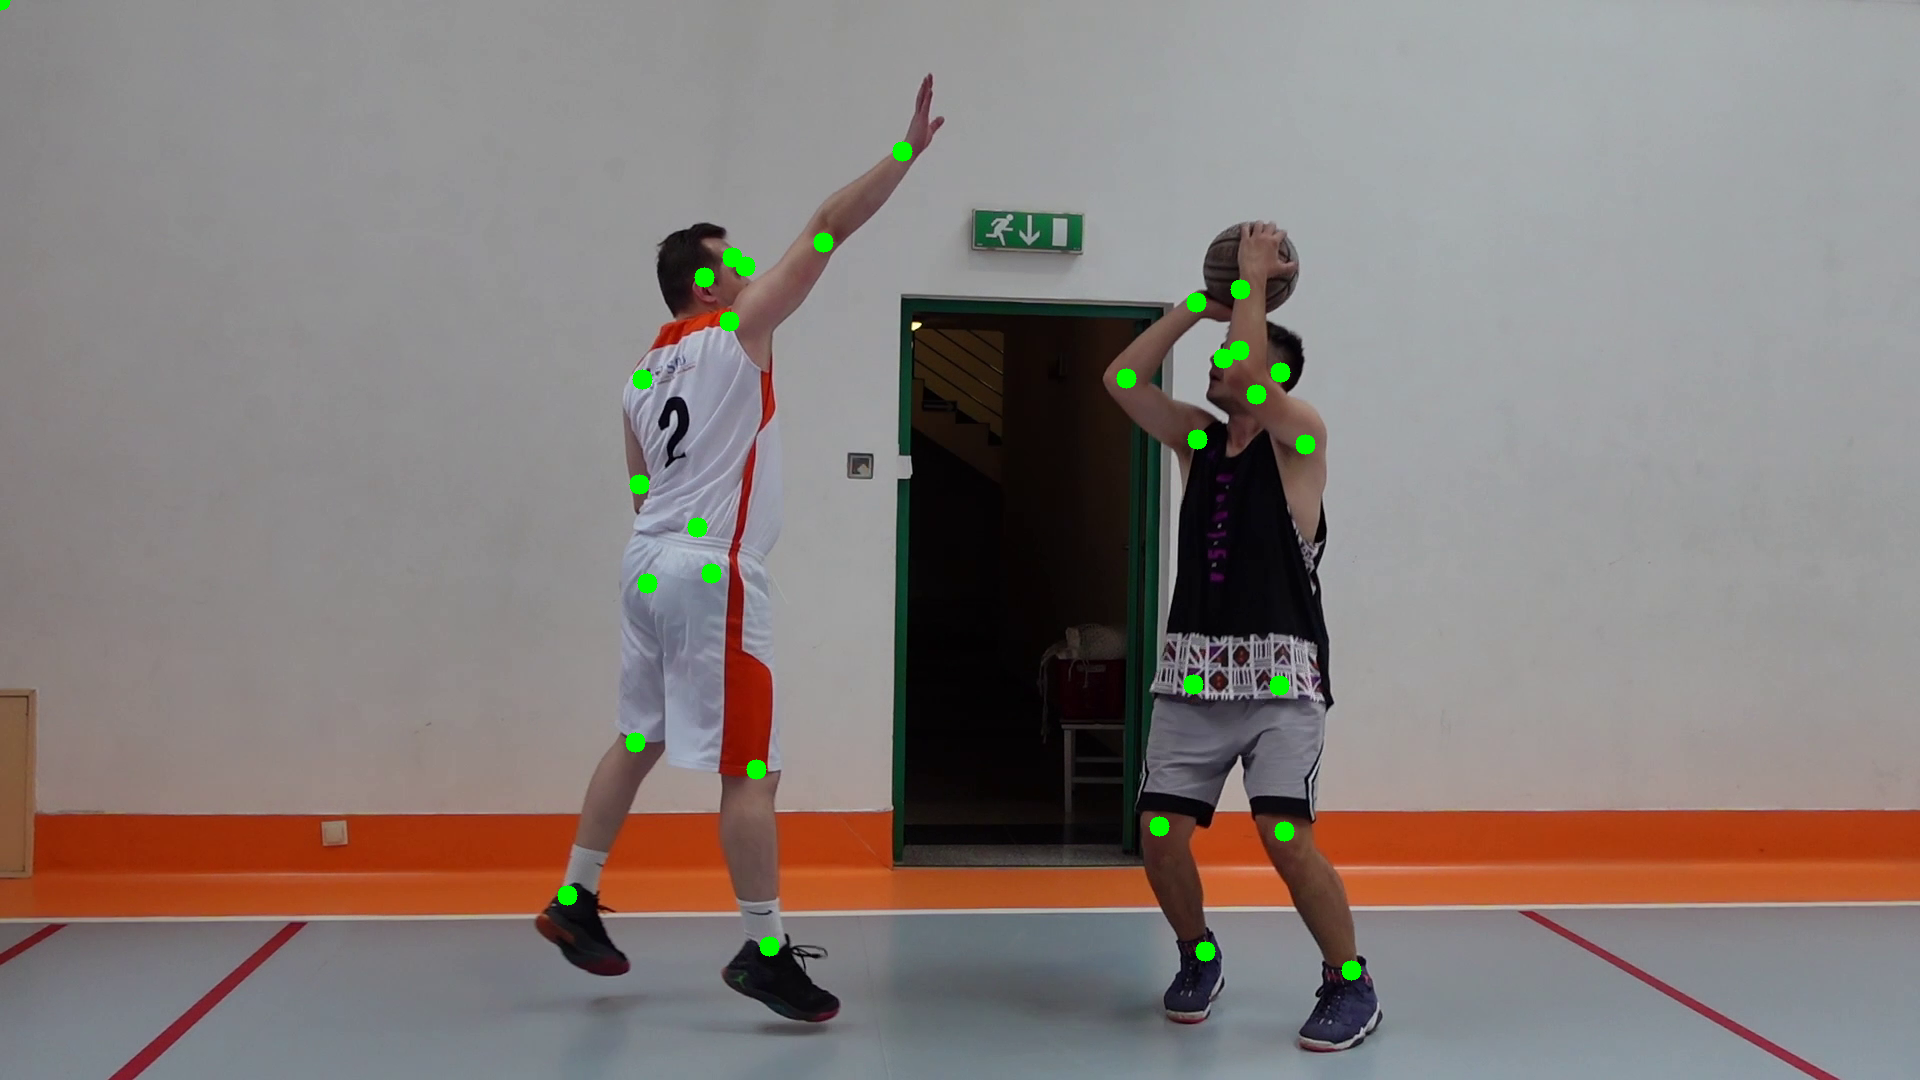
=== "VertexAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
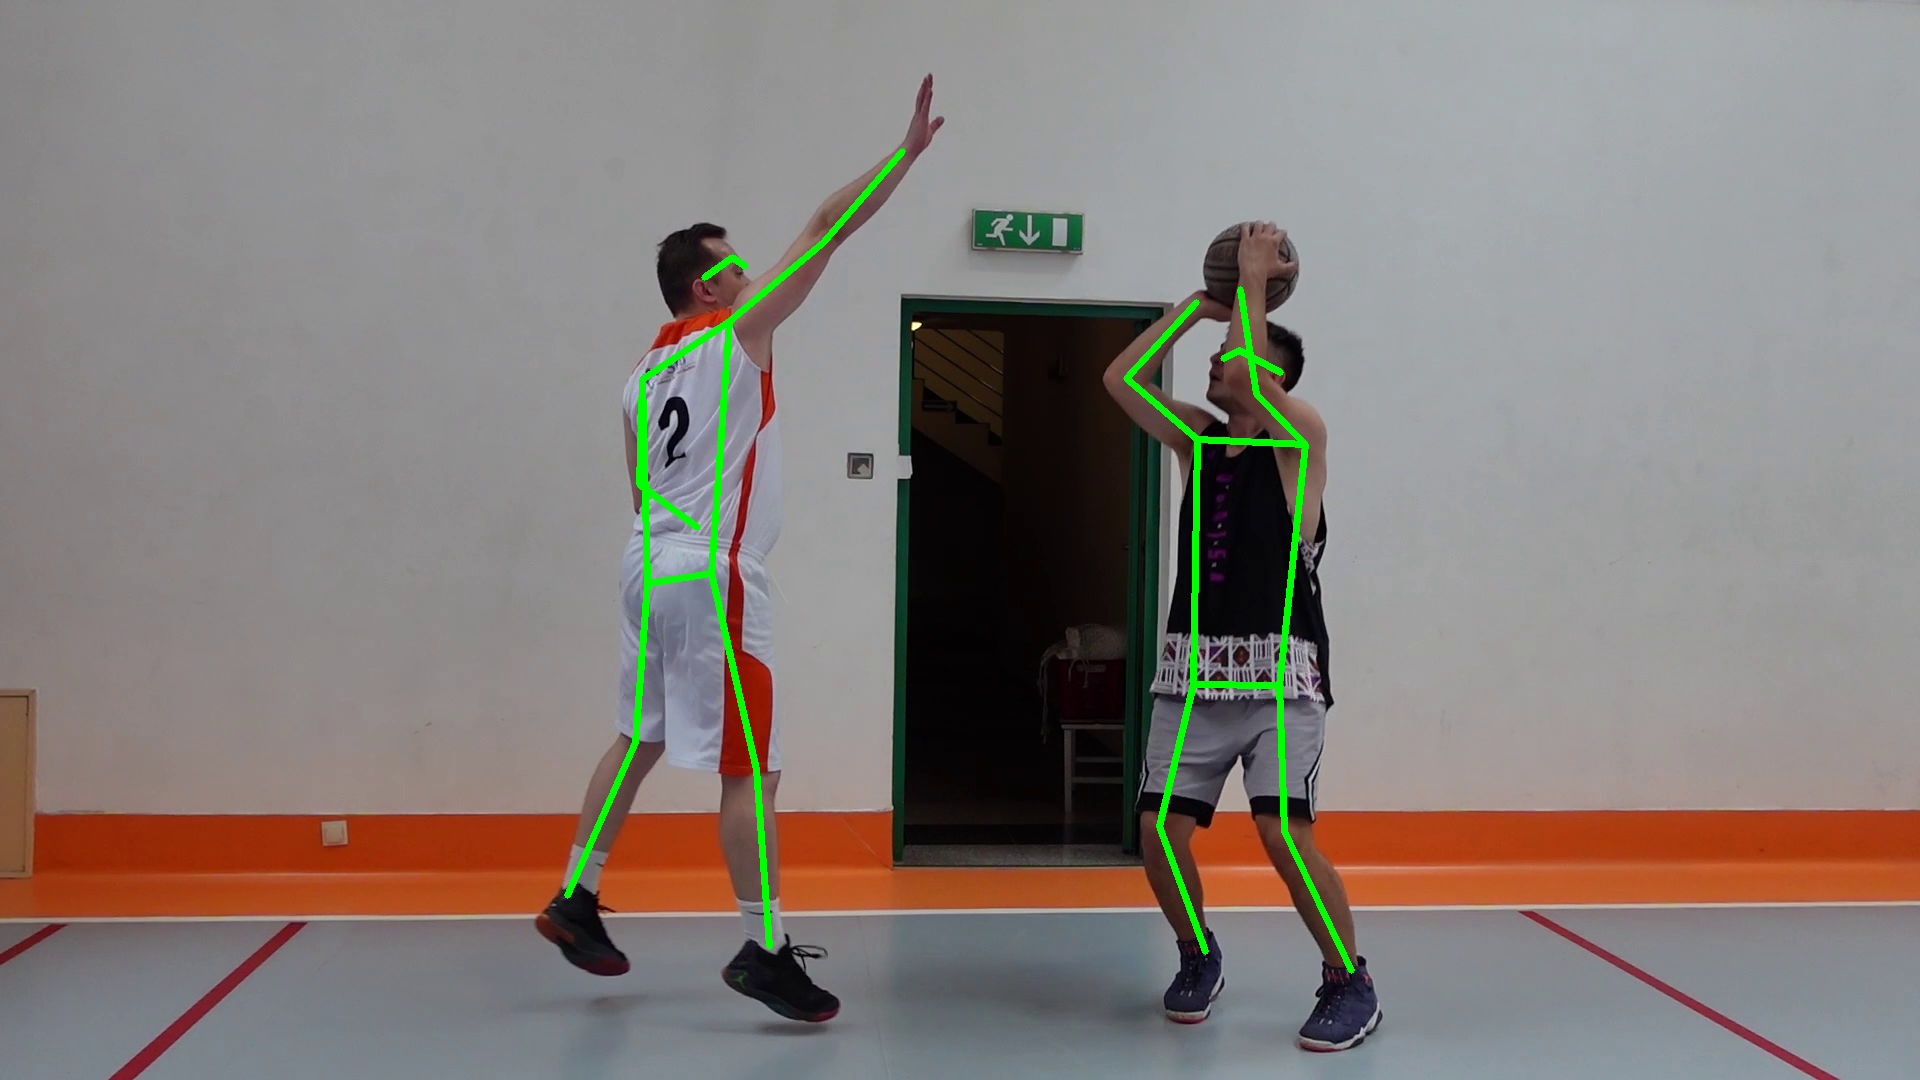
=== "EdgeAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
:::supervision.keypoint.core.KeyPoints
|
||||
@@ -1,22 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
@@ -0,0 +1,65 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_line">draw_line</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_rectangle">draw_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_filled_rectangle">draw_filled_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_polygon">draw_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_text">draw_text</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_image">draw_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_font_scale">calculate_optimal_font_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_line_thickness">calculate_optimal_line_thickness</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.Color">Color</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.ColorPalette">ColorPalette</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
+1
-1
@@ -5,7 +5,7 @@ comments: true
|
||||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
<h2><a href="#supervision.utils.file.list_files_with_extensions">list_files_with_extensions</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.utils.get_polygon_center">get_polygon_center</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.utils.get_polygon_center
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.Position">Position</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
+18
-12
@@ -6,31 +6,37 @@ status: new
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
<h2><a href="#supervision.utils.image.crop_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>letterbox_image</h2>
|
||||
<h2><a href="#supervision.utils.image.scale_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
<h2><a href="#supervision.utils.image.resize_image">resize_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>place_image</h2>
|
||||
<h2><a href="#supervision.utils.image.letterbox_image">letterbox_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.place_image
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
@@ -6,13 +6,13 @@ status: new
|
||||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>create_batches</h2>
|
||||
<h2><a href="#supervision.utils.iterables.create_batches">create_batches</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>fill</h2>
|
||||
<h2><a href="#supervision.utils.iterables.fill">fill</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
@@ -5,14 +5,13 @@ comments: true
|
||||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_image">plot_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_images_grid
|
||||
</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_images_grid">plot_images_grid</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
+5
-5
@@ -5,31 +5,31 @@ comments: true
|
||||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoInfo">VideoInfo</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoSink">VideoSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
<h2><a href="#supervision.utils.video.FPSMonitor">FPSMonitor</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
<h2><a href="#supervision.utils.video.get_video_frames_generator">get_video_frames_generator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
<h2><a href="#supervision.utils.video.process_video">process_video</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
+3
-23
@@ -1,8 +1,8 @@
|
||||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
Here, you'll find end-to-end examples that show how to solve common computer vision problems using Supervision.
|
||||
|
||||
For more information and examples, visit our [documentation](https://supervision.roboflow.com/develop/annotators/) and explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/) and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/). Join our [Discord](https://discord.com/invite/GbfgXGJ8Bk) and meet other Supervision power users!
|
||||
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
@@ -10,23 +10,3 @@ interfaces with diverse applications.
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
1. Create a pull request (PR) with the `[Example]` prefix in the title, adding your
|
||||
project folder to the `examples/` directory in the repository.
|
||||
2. Confirm your project aligns with the following standards:
|
||||
- Incorporates the `supervision` package.
|
||||
- Provides a `README.md` file, detailing the instructions to execute the project.
|
||||
- Showcases visual results, demonstrating the app's functionality.
|
||||
- Avoids adding large assets or dependencies unless absolutely necessary.
|
||||
- The contributor is expected to provide support for issues related to their
|
||||
examples.
|
||||
- In case the presented model has licensing complications, kindly specify them to
|
||||
circumvent potential misunderstandings.
|
||||
|
||||
For inquiries or concerns about these prerequisites, feel free to raise a PR. We are
|
||||
committed to assist and guide you.
|
||||
@@ -1,5 +1,8 @@
|
||||
# count people in zone
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb)
|
||||
[](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
|
||||
@@ -38,15 +38,15 @@ def initiate_annotators(
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone = sv.PolygonZone(polygon=polygon)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision==0.19.0
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
@@ -36,15 +36,15 @@ def initiate_annotators(
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone = sv.PolygonZone(polygon=polygon)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
|
||||
@@ -98,10 +98,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -116,9 +116,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
supervision==0.19.0
|
||||
tqdm==4.66.1
|
||||
supervision>=0.20.0
|
||||
tqdm==4.66.3
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
super-gradients==3.5.0
|
||||
inference==0.9.8
|
||||
inference==0.9.17
|
||||
@@ -76,10 +76,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -94,9 +94,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -77,10 +77,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -95,9 +95,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -1,5 +1,7 @@
|
||||
# time in zone
|
||||
|
||||
[](https://www.youtube.com/watch?v=hAWpsIuem10)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
|
||||
@@ -29,14 +29,10 @@ def main(
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
|
||||
@@ -29,14 +29,10 @@ def main(
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
|
||||
@@ -24,20 +24,15 @@ class CustomSink:
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
def on_prediction(self, result: dict, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
opencv-python
|
||||
supervision
|
||||
supervision>=0.20.0
|
||||
ultralytics
|
||||
inference
|
||||
inference==0.9.17
|
||||
pytube
|
||||
@@ -30,14 +30,10 @@ def main(
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
|
||||
@@ -30,14 +30,10 @@ def main(
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
|
||||
@@ -25,20 +25,15 @@ class CustomSink:
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
inference
|
||||
inference==0.9.17
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
@@ -1,6 +1,6 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Dict, Iterable, List, Set, Tuple
|
||||
from typing import Dict, Iterable, List, Set
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -60,13 +60,11 @@ class DetectionsManager:
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_anchors=triggering_anchors,
|
||||
)
|
||||
for polygon in polygons
|
||||
@@ -92,12 +90,8 @@ class VideoProcessor:
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER]
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER]
|
||||
)
|
||||
self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER])
|
||||
self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER])
|
||||
|
||||
self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS)
|
||||
self.label_annotator = sv.LabelAnnotator(
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision>=0.19.0
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
@@ -1,5 +1,5 @@
|
||||
import argparse
|
||||
from typing import Dict, Iterable, List, Set, Tuple
|
||||
from typing import Dict, Iterable, List, Set
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -58,13 +58,11 @@ class DetectionsManager:
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_anchors=triggering_anchors,
|
||||
)
|
||||
for polygon in polygons
|
||||
@@ -89,12 +87,8 @@ class VideoProcessor:
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER]
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER]
|
||||
)
|
||||
self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER])
|
||||
self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER])
|
||||
|
||||
self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS)
|
||||
self.label_annotator = sv.LabelAnnotator(
|
||||
|
||||
+13
-12
@@ -38,16 +38,22 @@ nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
- Detections:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
@@ -56,19 +62,14 @@ nav:
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
- Metrics:
|
||||
- Object Detection: metrics/detection.md
|
||||
- Draw:
|
||||
- Color: draw/color.md
|
||||
- Utils: draw/utils.md
|
||||
- Geometry:
|
||||
- Position: geometry/core.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Contribute:
|
||||
|
||||
Generated
+123
-120
@@ -1122,13 +1122,13 @@ license = ["ukkonen"]
|
||||
|
||||
[[package]]
|
||||
name = "idna"
|
||||
version = "3.6"
|
||||
version = "3.7"
|
||||
description = "Internationalized Domain Names in Applications (IDNA)"
|
||||
optional = false
|
||||
python-versions = ">=3.5"
|
||||
files = [
|
||||
{file = "idna-3.6-py3-none-any.whl", hash = "sha256:c05567e9c24a6b9faaa835c4821bad0590fbb9d5779e7caa6e1cc4978e7eb24f"},
|
||||
{file = "idna-3.6.tar.gz", hash = "sha256:9ecdbbd083b06798ae1e86adcbfe8ab1479cf864e4ee30fe4e46a003d12491ca"},
|
||||
{file = "idna-3.7-py3-none-any.whl", hash = "sha256:82fee1fc78add43492d3a1898bfa6d8a904cc97d8427f683ed8e798d07761aa0"},
|
||||
{file = "idna-3.7.tar.gz", hash = "sha256:028ff3aadf0609c1fd278d8ea3089299412a7a8b9bd005dd08b9f8285bcb5cfc"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -1648,13 +1648,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "jupytext"
|
||||
version = "1.16.1"
|
||||
version = "1.16.2"
|
||||
description = "Jupyter notebooks as Markdown documents, Julia, Python or R scripts"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "jupytext-1.16.1-py3-none-any.whl", hash = "sha256:796ec4f68ada663569e5d38d4ef03738a01284bfe21c943c485bc36433898bd0"},
|
||||
{file = "jupytext-1.16.1.tar.gz", hash = "sha256:68c7b68685e870e80e60fda8286fbd6269e9c74dc1df4316df6fe46eabc94c99"},
|
||||
{file = "jupytext-1.16.2-py3-none-any.whl", hash = "sha256:197a43fef31dca612b68b311e01b8abd54441c7e637810b16b6cb8f2ab66065e"},
|
||||
{file = "jupytext-1.16.2.tar.gz", hash = "sha256:8627dd9becbbebd79cc4a4ed4727d89d78e606b4b464eab72357b3b029023a14"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -1663,16 +1663,16 @@ mdit-py-plugins = "*"
|
||||
nbformat = "*"
|
||||
packaging = "*"
|
||||
pyyaml = "*"
|
||||
toml = "*"
|
||||
tomli = {version = "*", markers = "python_version < \"3.11\""}
|
||||
|
||||
[package.extras]
|
||||
dev = ["jupytext[test-cov,test-external]"]
|
||||
dev = ["autopep8", "black", "flake8", "gitpython", "ipykernel", "isort", "jupyter-fs (<0.4.0)", "jupyter-server (!=2.11)", "nbconvert", "pre-commit", "pytest", "pytest-cov (>=2.6.1)", "pytest-randomly", "pytest-xdist", "sphinx-gallery (<0.8)"]
|
||||
docs = ["myst-parser", "sphinx", "sphinx-copybutton", "sphinx-rtd-theme"]
|
||||
test = ["pytest", "pytest-randomly", "pytest-xdist"]
|
||||
test-cov = ["jupytext[test-integration]", "pytest-cov (>=2.6.1)"]
|
||||
test-external = ["autopep8", "black", "flake8", "gitpython", "isort", "jupyter-fs (<0.4.0)", "jupytext[test-integration]", "pre-commit", "sphinx-gallery (<0.8)"]
|
||||
test-functional = ["jupytext[test]"]
|
||||
test-integration = ["ipykernel", "jupyter-server (!=2.11)", "jupytext[test-functional]", "nbconvert"]
|
||||
test-cov = ["ipykernel", "jupyter-server (!=2.11)", "nbconvert", "pytest", "pytest-cov (>=2.6.1)", "pytest-randomly", "pytest-xdist"]
|
||||
test-external = ["autopep8", "black", "flake8", "gitpython", "ipykernel", "isort", "jupyter-fs (<0.4.0)", "jupyter-server (!=2.11)", "nbconvert", "pre-commit", "pytest", "pytest-randomly", "pytest-xdist", "sphinx-gallery (<0.8)"]
|
||||
test-functional = ["pytest", "pytest-randomly", "pytest-xdist"]
|
||||
test-integration = ["ipykernel", "jupyter-server (!=2.11)", "nbconvert", "pytest", "pytest-randomly", "pytest-xdist"]
|
||||
test-ui = ["calysto-bash"]
|
||||
|
||||
[[package]]
|
||||
@@ -2048,13 +2048,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "mike"
|
||||
version = "2.0.0"
|
||||
version = "2.1.1"
|
||||
description = "Manage multiple versions of your MkDocs-powered documentation"
|
||||
optional = false
|
||||
python-versions = "*"
|
||||
files = [
|
||||
{file = "mike-2.0.0-py3-none-any.whl", hash = "sha256:87f496a65900f93ba92d72940242b65c86f3f2f82871bc60ebdcffc91fad1d9e"},
|
||||
{file = "mike-2.0.0.tar.gz", hash = "sha256:566f1cab1a58cc50b106fb79ea2f1f56e7bfc8b25a051e95e6eaee9fba0922de"},
|
||||
{file = "mike-2.1.1-py3-none-any.whl", hash = "sha256:0b1d01a397a423284593eeb1b5f3194e37169488f929b860c9bfe95c0d5efb79"},
|
||||
{file = "mike-2.1.1.tar.gz", hash = "sha256:f39ed39f3737da83ad0adc33e9f885092ed27f8c9e7ff0523add0480352a2c22"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2064,6 +2064,7 @@ jinja2 = ">=2.7"
|
||||
mkdocs = ">=1.0"
|
||||
pyparsing = ">=3.0"
|
||||
pyyaml = ">=5.1"
|
||||
pyyaml-env-tag = "*"
|
||||
verspec = "*"
|
||||
|
||||
[package.extras]
|
||||
@@ -2083,34 +2084,34 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs"
|
||||
version = "1.5.3"
|
||||
version = "1.6.0"
|
||||
description = "Project documentation with Markdown."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs-1.5.3-py3-none-any.whl", hash = "sha256:3b3a78e736b31158d64dbb2f8ba29bd46a379d0c6e324c2246c3bc3d2189cfc1"},
|
||||
{file = "mkdocs-1.5.3.tar.gz", hash = "sha256:eb7c99214dcb945313ba30426c2451b735992c73c2e10838f76d09e39ff4d0e2"},
|
||||
{file = "mkdocs-1.6.0-py3-none-any.whl", hash = "sha256:1eb5cb7676b7d89323e62b56235010216319217d4af5ddc543a91beb8d125ea7"},
|
||||
{file = "mkdocs-1.6.0.tar.gz", hash = "sha256:a73f735824ef83a4f3bcb7a231dcab23f5a838f88b7efc54a0eef5fbdbc3c512"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
click = ">=7.0"
|
||||
colorama = {version = ">=0.4", markers = "platform_system == \"Windows\""}
|
||||
ghp-import = ">=1.0"
|
||||
importlib-metadata = {version = ">=4.3", markers = "python_version < \"3.10\""}
|
||||
importlib-metadata = {version = ">=4.4", markers = "python_version < \"3.10\""}
|
||||
jinja2 = ">=2.11.1"
|
||||
markdown = ">=3.2.1"
|
||||
markdown = ">=3.3.6"
|
||||
markupsafe = ">=2.0.1"
|
||||
mergedeep = ">=1.3.4"
|
||||
mkdocs-get-deps = ">=0.2.0"
|
||||
packaging = ">=20.5"
|
||||
pathspec = ">=0.11.1"
|
||||
platformdirs = ">=2.2.0"
|
||||
pyyaml = ">=5.1"
|
||||
pyyaml-env-tag = ">=0.1"
|
||||
watchdog = ">=2.0"
|
||||
|
||||
[package.extras]
|
||||
i18n = ["babel (>=2.9.0)"]
|
||||
min-versions = ["babel (==2.9.0)", "click (==7.0)", "colorama (==0.4)", "ghp-import (==1.0)", "importlib-metadata (==4.3)", "jinja2 (==2.11.1)", "markdown (==3.2.1)", "markupsafe (==2.0.1)", "mergedeep (==1.3.4)", "packaging (==20.5)", "pathspec (==0.11.1)", "platformdirs (==2.2.0)", "pyyaml (==5.1)", "pyyaml-env-tag (==0.1)", "typing-extensions (==3.10)", "watchdog (==2.0)"]
|
||||
min-versions = ["babel (==2.9.0)", "click (==7.0)", "colorama (==0.4)", "ghp-import (==1.0)", "importlib-metadata (==4.4)", "jinja2 (==2.11.1)", "markdown (==3.3.6)", "markupsafe (==2.0.1)", "mergedeep (==1.3.4)", "mkdocs-get-deps (==0.2.0)", "packaging (==20.5)", "pathspec (==0.11.1)", "pyyaml (==5.1)", "pyyaml-env-tag (==0.1)", "watchdog (==2.0)"]
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-autorefs"
|
||||
@@ -2127,6 +2128,23 @@ files = [
|
||||
Markdown = ">=3.3"
|
||||
mkdocs = ">=1.1"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-get-deps"
|
||||
version = "0.2.0"
|
||||
description = "MkDocs extension that lists all dependencies according to a mkdocs.yml file"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_get_deps-0.2.0-py3-none-any.whl", hash = "sha256:2bf11d0b133e77a0dd036abeeb06dec8775e46efa526dc70667d8863eefc6134"},
|
||||
{file = "mkdocs_get_deps-0.2.0.tar.gz", hash = "sha256:162b3d129c7fad9b19abfdcb9c1458a651628e4b1dea628ac68790fb3061c60c"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
importlib-metadata = {version = ">=4.3", markers = "python_version < \"3.10\""}
|
||||
mergedeep = ">=1.3.4"
|
||||
platformdirs = ">=2.2.0"
|
||||
pyyaml = ">=5.1"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-git-committers-plugin-2"
|
||||
version = "2.3.0"
|
||||
@@ -2145,13 +2163,13 @@ requests = "*"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-git-revision-date-localized-plugin"
|
||||
version = "1.2.4"
|
||||
version = "1.2.5"
|
||||
description = "Mkdocs plugin that enables displaying the localized date of the last git modification of a markdown file."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs-git-revision-date-localized-plugin-1.2.4.tar.gz", hash = "sha256:08fd0c6f33c8da9e00daf40f7865943113b3879a1c621b2bbf0fa794ffe997d3"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.4-py3-none-any.whl", hash = "sha256:1f94eb510862ef94e982a2910404fa17a1657ecf29f45a07b0f438c00767fc85"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.5-py3-none-any.whl", hash = "sha256:d796a18b07cfcdb154c133e3ec099d2bb5f38389e4fd54d3eb516a8a736815b8"},
|
||||
{file = "mkdocs_git_revision_date_localized_plugin-1.2.5.tar.gz", hash = "sha256:0c439816d9d0dba48e027d9d074b2b9f1d7cd179f74ba46b51e4da7bb3dc4b9b"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2162,13 +2180,12 @@ pytz = "*"
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-jupyter"
|
||||
version = "0.24.3"
|
||||
version = "0.24.7"
|
||||
description = "Use Jupyter in mkdocs websites"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_jupyter-0.24.3-py3-none-any.whl", hash = "sha256:904262a8678a5e5920b7c3c03b5010b36301a69d0a38f2fcbf430493adf6879e"},
|
||||
{file = "mkdocs_jupyter-0.24.3.tar.gz", hash = "sha256:3d81da9aea27480e93bab22438910c4f0b9630613e74f85b576590d78e0e8b14"},
|
||||
{file = "mkdocs_jupyter-0.24.7-py3-none-any.whl", hash = "sha256:893d04bea1e007479a46e4e72852cd4d280c4d358ce4a0445250f3f80c639723"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2179,18 +2196,15 @@ mkdocs-material = ">9.0.0"
|
||||
nbconvert = ">=7.2.9,<8"
|
||||
pygments = ">2.12.0"
|
||||
|
||||
[package.extras]
|
||||
test = ["coverage[toml]", "pymdown-extensions", "pytest", "pytest-cov"]
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.17"
|
||||
version = "9.5.21"
|
||||
description = "Documentation that simply works"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_material-9.5.17-py3-none-any.whl", hash = "sha256:14a2a60119a785e70e765dd033e6211367aca9fc70230e577c1cf6a326949571"},
|
||||
{file = "mkdocs_material-9.5.17.tar.gz", hash = "sha256:06ae1275a72db1989cf6209de9e9ecdfbcfdbc24c58353877b2bb927dbe413e4"},
|
||||
{file = "mkdocs_material-9.5.21-py3-none-any.whl", hash = "sha256:210e1f179682cd4be17d5c641b2f4559574b9dea2f589c3f0e7c17c5bd1959bc"},
|
||||
{file = "mkdocs_material-9.5.21.tar.gz", hash = "sha256:049f82770f40559d3c2aa2259c562ea7257dbb4aaa9624323b5ef27b2d95a450"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2199,7 +2213,7 @@ cairosvg = {version = ">=2.6,<3.0", optional = true, markers = "extra == \"imagi
|
||||
colorama = ">=0.4,<1.0"
|
||||
jinja2 = ">=3.0,<4.0"
|
||||
markdown = ">=3.2,<4.0"
|
||||
mkdocs = ">=1.5.3,<1.6.0"
|
||||
mkdocs = ">=1.6,<2.0"
|
||||
mkdocs-material-extensions = ">=1.3,<2.0"
|
||||
paginate = ">=0.5,<1.0"
|
||||
pillow = {version = ">=10.2,<11.0", optional = true, markers = "extra == \"imaging\""}
|
||||
@@ -2226,13 +2240,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "mkdocstrings"
|
||||
version = "0.24.3"
|
||||
version = "0.25.1"
|
||||
description = "Automatic documentation from sources, for MkDocs."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocstrings-0.24.3-py3-none-any.whl", hash = "sha256:5c9cf2a32958cd161d5428699b79c8b0988856b0d4a8c5baf8395fc1bf4087c3"},
|
||||
{file = "mkdocstrings-0.24.3.tar.gz", hash = "sha256:f327b234eb8d2551a306735436e157d0a22d45f79963c60a8b585d5f7a94c1d2"},
|
||||
{file = "mkdocstrings-0.25.1-py3-none-any.whl", hash = "sha256:da01fcc2670ad61888e8fe5b60afe9fee5781017d67431996832d63e887c2e51"},
|
||||
{file = "mkdocstrings-0.25.1.tar.gz", hash = "sha256:c3a2515f31577f311a9ee58d089e4c51fc6046dbd9e9b4c3de4c3194667fe9bf"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2281,38 +2295,38 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "mypy"
|
||||
version = "1.9.0"
|
||||
version = "1.10.0"
|
||||
description = "Optional static typing for Python"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mypy-1.9.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:f8a67616990062232ee4c3952f41c779afac41405806042a8126fe96e098419f"},
|
||||
{file = "mypy-1.9.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:d357423fa57a489e8c47b7c85dfb96698caba13d66e086b412298a1a0ea3b0ed"},
|
||||
{file = "mypy-1.9.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:49c87c15aed320de9b438ae7b00c1ac91cd393c1b854c2ce538e2a72d55df150"},
|
||||
{file = "mypy-1.9.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:48533cdd345c3c2e5ef48ba3b0d3880b257b423e7995dada04248725c6f77374"},
|
||||
{file = "mypy-1.9.0-cp310-cp310-win_amd64.whl", hash = "sha256:4d3dbd346cfec7cb98e6cbb6e0f3c23618af826316188d587d1c1bc34f0ede03"},
|
||||
{file = "mypy-1.9.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:653265f9a2784db65bfca694d1edd23093ce49740b2244cde583aeb134c008f3"},
|
||||
{file = "mypy-1.9.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:3a3c007ff3ee90f69cf0a15cbcdf0995749569b86b6d2f327af01fd1b8aee9dc"},
|
||||
{file = "mypy-1.9.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:2418488264eb41f69cc64a69a745fad4a8f86649af4b1041a4c64ee61fc61129"},
|
||||
{file = "mypy-1.9.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:68edad3dc7d70f2f17ae4c6c1b9471a56138ca22722487eebacfd1eb5321d612"},
|
||||
{file = "mypy-1.9.0-cp311-cp311-win_amd64.whl", hash = "sha256:85ca5fcc24f0b4aeedc1d02f93707bccc04733f21d41c88334c5482219b1ccb3"},
|
||||
{file = "mypy-1.9.0-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:aceb1db093b04db5cd390821464504111b8ec3e351eb85afd1433490163d60cd"},
|
||||
{file = "mypy-1.9.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:0235391f1c6f6ce487b23b9dbd1327b4ec33bb93934aa986efe8a9563d9349e6"},
|
||||
{file = "mypy-1.9.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:d4d5ddc13421ba3e2e082a6c2d74c2ddb3979c39b582dacd53dd5d9431237185"},
|
||||
{file = "mypy-1.9.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:190da1ee69b427d7efa8aa0d5e5ccd67a4fb04038c380237a0d96829cb157913"},
|
||||
{file = "mypy-1.9.0-cp312-cp312-win_amd64.whl", hash = "sha256:fe28657de3bfec596bbeef01cb219833ad9d38dd5393fc649f4b366840baefe6"},
|
||||
{file = "mypy-1.9.0-cp38-cp38-macosx_10_9_x86_64.whl", hash = "sha256:e54396d70be04b34f31d2edf3362c1edd023246c82f1730bbf8768c28db5361b"},
|
||||
{file = "mypy-1.9.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:5e6061f44f2313b94f920e91b204ec600982961e07a17e0f6cd83371cb23f5c2"},
|
||||
{file = "mypy-1.9.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:81a10926e5473c5fc3da8abb04119a1f5811a236dc3a38d92015cb1e6ba4cb9e"},
|
||||
{file = "mypy-1.9.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:b685154e22e4e9199fc95f298661deea28aaede5ae16ccc8cbb1045e716b3e04"},
|
||||
{file = "mypy-1.9.0-cp38-cp38-win_amd64.whl", hash = "sha256:5d741d3fc7c4da608764073089e5f58ef6352bedc223ff58f2f038c2c4698a89"},
|
||||
{file = "mypy-1.9.0-cp39-cp39-macosx_10_9_x86_64.whl", hash = "sha256:587ce887f75dd9700252a3abbc9c97bbe165a4a630597845c61279cf32dfbf02"},
|
||||
{file = "mypy-1.9.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:f88566144752999351725ac623471661c9d1cd8caa0134ff98cceeea181789f4"},
|
||||
{file = "mypy-1.9.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:61758fabd58ce4b0720ae1e2fea5cfd4431591d6d590b197775329264f86311d"},
|
||||
{file = "mypy-1.9.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:e49499be624dead83927e70c756970a0bc8240e9f769389cdf5714b0784ca6bf"},
|
||||
{file = "mypy-1.9.0-cp39-cp39-win_amd64.whl", hash = "sha256:571741dc4194b4f82d344b15e8837e8c5fcc462d66d076748142327626a1b6e9"},
|
||||
{file = "mypy-1.9.0-py3-none-any.whl", hash = "sha256:a260627a570559181a9ea5de61ac6297aa5af202f06fd7ab093ce74e7181e43e"},
|
||||
{file = "mypy-1.9.0.tar.gz", hash = "sha256:3cc5da0127e6a478cddd906068496a97a7618a21ce9b54bde5bf7e539c7af974"},
|
||||
{file = "mypy-1.10.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:da1cbf08fb3b851ab3b9523a884c232774008267b1f83371ace57f412fe308c2"},
|
||||
{file = "mypy-1.10.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:12b6bfc1b1a66095ab413160a6e520e1dc076a28f3e22f7fb25ba3b000b4ef99"},
|
||||
{file = "mypy-1.10.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9e36fb078cce9904c7989b9693e41cb9711e0600139ce3970c6ef814b6ebc2b2"},
|
||||
{file = "mypy-1.10.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:2b0695d605ddcd3eb2f736cd8b4e388288c21e7de85001e9f85df9187f2b50f9"},
|
||||
{file = "mypy-1.10.0-cp310-cp310-win_amd64.whl", hash = "sha256:cd777b780312ddb135bceb9bc8722a73ec95e042f911cc279e2ec3c667076051"},
|
||||
{file = "mypy-1.10.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:3be66771aa5c97602f382230165b856c231d1277c511c9a8dd058be4784472e1"},
|
||||
{file = "mypy-1.10.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:8b2cbaca148d0754a54d44121b5825ae71868c7592a53b7292eeb0f3fdae95ee"},
|
||||
{file = "mypy-1.10.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:1ec404a7cbe9fc0e92cb0e67f55ce0c025014e26d33e54d9e506a0f2d07fe5de"},
|
||||
{file = "mypy-1.10.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:e22e1527dc3d4aa94311d246b59e47f6455b8729f4968765ac1eacf9a4760bc7"},
|
||||
{file = "mypy-1.10.0-cp311-cp311-win_amd64.whl", hash = "sha256:a87dbfa85971e8d59c9cc1fcf534efe664d8949e4c0b6b44e8ca548e746a8d53"},
|
||||
{file = "mypy-1.10.0-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:a781f6ad4bab20eef8b65174a57e5203f4be627b46291f4589879bf4e257b97b"},
|
||||
{file = "mypy-1.10.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:b808e12113505b97d9023b0b5e0c0705a90571c6feefc6f215c1df9381256e30"},
|
||||
{file = "mypy-1.10.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:8f55583b12156c399dce2df7d16f8a5095291354f1e839c252ec6c0611e86e2e"},
|
||||
{file = "mypy-1.10.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:4cf18f9d0efa1b16478c4c129eabec36148032575391095f73cae2e722fcf9d5"},
|
||||
{file = "mypy-1.10.0-cp312-cp312-win_amd64.whl", hash = "sha256:bc6ac273b23c6b82da3bb25f4136c4fd42665f17f2cd850771cb600bdd2ebeda"},
|
||||
{file = "mypy-1.10.0-cp38-cp38-macosx_10_9_x86_64.whl", hash = "sha256:9fd50226364cd2737351c79807775136b0abe084433b55b2e29181a4c3c878c0"},
|
||||
{file = "mypy-1.10.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:f90cff89eea89273727d8783fef5d4a934be2fdca11b47def50cf5d311aff727"},
|
||||
{file = "mypy-1.10.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:fcfc70599efde5c67862a07a1aaf50e55bce629ace26bb19dc17cece5dd31ca4"},
|
||||
{file = "mypy-1.10.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:075cbf81f3e134eadaf247de187bd604748171d6b79736fa9b6c9685b4083061"},
|
||||
{file = "mypy-1.10.0-cp38-cp38-win_amd64.whl", hash = "sha256:3f298531bca95ff615b6e9f2fc0333aae27fa48052903a0ac90215021cdcfa4f"},
|
||||
{file = "mypy-1.10.0-cp39-cp39-macosx_10_9_x86_64.whl", hash = "sha256:fa7ef5244615a2523b56c034becde4e9e3f9b034854c93639adb667ec9ec2976"},
|
||||
{file = "mypy-1.10.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:3236a4c8f535a0631f85f5fcdffba71c7feeef76a6002fcba7c1a8e57c8be1ec"},
|
||||
{file = "mypy-1.10.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:4a2b5cdbb5dd35aa08ea9114436e0d79aceb2f38e32c21684dcf8e24e1e92821"},
|
||||
{file = "mypy-1.10.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:92f93b21c0fe73dc00abf91022234c79d793318b8a96faac147cd579c1671746"},
|
||||
{file = "mypy-1.10.0-cp39-cp39-win_amd64.whl", hash = "sha256:28d0e038361b45f099cc086d9dd99c15ff14d0188f44ac883010e172ce86c38a"},
|
||||
{file = "mypy-1.10.0-py3-none-any.whl", hash = "sha256:f8c083976eb530019175aabadb60921e73b4f45736760826aa1689dda8208aee"},
|
||||
{file = "mypy-1.10.0.tar.gz", hash = "sha256:3d087fcbec056c4ee34974da493a826ce316947485cef3901f511848e687c131"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2361,13 +2375,13 @@ test = ["flaky", "ipykernel (>=6.19.3)", "ipython", "ipywidgets", "nbconvert (>=
|
||||
|
||||
[[package]]
|
||||
name = "nbconvert"
|
||||
version = "7.16.3"
|
||||
version = "7.16.4"
|
||||
description = "Converting Jupyter Notebooks (.ipynb files) to other formats. Output formats include asciidoc, html, latex, markdown, pdf, py, rst, script. nbconvert can be used both as a Python library (`import nbconvert`) or as a command line tool (invoked as `jupyter nbconvert ...`)."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "nbconvert-7.16.3-py3-none-any.whl", hash = "sha256:ddeff14beeeedf3dd0bc506623e41e4507e551736de59df69a91f86700292b3b"},
|
||||
{file = "nbconvert-7.16.3.tar.gz", hash = "sha256:a6733b78ce3d47c3f85e504998495b07e6ea9cf9bf6ec1c98dda63ec6ad19142"},
|
||||
{file = "nbconvert-7.16.4-py3-none-any.whl", hash = "sha256:05873c620fe520b6322bf8a5ad562692343fe3452abda5765c7a34b7d1aa3eb3"},
|
||||
{file = "nbconvert-7.16.4.tar.gz", hash = "sha256:86ca91ba266b0a448dc96fa6c5b9d98affabde2867b363258703536807f9f7f4"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2389,9 +2403,9 @@ tinycss2 = "*"
|
||||
traitlets = ">=5.1"
|
||||
|
||||
[package.extras]
|
||||
all = ["nbconvert[docs,qtpdf,serve,test,webpdf]"]
|
||||
all = ["flaky", "ipykernel", "ipython", "ipywidgets (>=7.5)", "myst-parser", "nbsphinx (>=0.2.12)", "playwright", "pydata-sphinx-theme", "pyqtwebengine (>=5.15)", "pytest (>=7)", "sphinx (==5.0.2)", "sphinxcontrib-spelling", "tornado (>=6.1)"]
|
||||
docs = ["ipykernel", "ipython", "myst-parser", "nbsphinx (>=0.2.12)", "pydata-sphinx-theme", "sphinx (==5.0.2)", "sphinxcontrib-spelling"]
|
||||
qtpdf = ["nbconvert[qtpng]"]
|
||||
qtpdf = ["pyqtwebengine (>=5.15)"]
|
||||
qtpng = ["pyqtwebengine (>=5.15)"]
|
||||
serve = ["tornado (>=6.1)"]
|
||||
test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest (>=7)"]
|
||||
@@ -2470,13 +2484,13 @@ setuptools = "*"
|
||||
|
||||
[[package]]
|
||||
name = "notebook"
|
||||
version = "7.1.2"
|
||||
version = "7.1.3"
|
||||
description = "Jupyter Notebook - A web-based notebook environment for interactive computing"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "notebook-7.1.2-py3-none-any.whl", hash = "sha256:fc6c24b9aef18d0cd57157c9c47e95833b9b0bdc599652639acf0bdb61dc7d5f"},
|
||||
{file = "notebook-7.1.2.tar.gz", hash = "sha256:efc2c80043909e0faa17fce9e9b37c059c03af0ec99a4d4db84cb21d9d2e936a"},
|
||||
{file = "notebook-7.1.3-py3-none-any.whl", hash = "sha256:919b911e59f41f6e3857ce93c9d93535ba66bb090059712770e5968c07e1004d"},
|
||||
{file = "notebook-7.1.3.tar.gz", hash = "sha256:41fcebff44cf7bb9377180808bcbae066629b55d8c7722f1ebbe75ca44f9cfc1"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2819,13 +2833,13 @@ test = ["appdirs (==1.4.4)", "covdefaults (>=2.3)", "pytest (>=7.4.3)", "pytest-
|
||||
|
||||
[[package]]
|
||||
name = "pluggy"
|
||||
version = "1.4.0"
|
||||
version = "1.5.0"
|
||||
description = "plugin and hook calling mechanisms for python"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "pluggy-1.4.0-py3-none-any.whl", hash = "sha256:7db9f7b503d67d1c5b95f59773ebb58a8c1c288129a88665838012cfb07b8981"},
|
||||
{file = "pluggy-1.4.0.tar.gz", hash = "sha256:8c85c2876142a764e5b7548e7d9a0e0ddb46f5185161049a79b7e974454223be"},
|
||||
{file = "pluggy-1.5.0-py3-none-any.whl", hash = "sha256:44e1ad92c8ca002de6377e165f3e0f1be63266ab4d554740532335b9d75ea669"},
|
||||
{file = "pluggy-1.5.0.tar.gz", hash = "sha256:2cffa88e94fdc978c4c574f15f9e59b7f4201d439195c3715ca9e2486f1d0cf1"},
|
||||
]
|
||||
|
||||
[package.extras]
|
||||
@@ -3024,13 +3038,13 @@ tomli = {version = ">=1.1.0", markers = "python_version < \"3.11\""}
|
||||
|
||||
[[package]]
|
||||
name = "pytest"
|
||||
version = "8.1.1"
|
||||
version = "8.2.0"
|
||||
description = "pytest: simple powerful testing with Python"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "pytest-8.1.1-py3-none-any.whl", hash = "sha256:2a8386cfc11fa9d2c50ee7b2a57e7d898ef90470a7a34c4b949ff59662bb78b7"},
|
||||
{file = "pytest-8.1.1.tar.gz", hash = "sha256:ac978141a75948948817d360297b7aae0fcb9d6ff6bc9ec6d514b85d5a65c044"},
|
||||
{file = "pytest-8.2.0-py3-none-any.whl", hash = "sha256:1733f0620f6cda4095bbf0d9ff8022486e91892245bb9e7d5542c018f612f233"},
|
||||
{file = "pytest-8.2.0.tar.gz", hash = "sha256:d507d4482197eac0ba2bae2e9babf0672eb333017bcedaa5fb1a3d42c1174b3f"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -3038,11 +3052,11 @@ colorama = {version = "*", markers = "sys_platform == \"win32\""}
|
||||
exceptiongroup = {version = ">=1.0.0rc8", markers = "python_version < \"3.11\""}
|
||||
iniconfig = "*"
|
||||
packaging = "*"
|
||||
pluggy = ">=1.4,<2.0"
|
||||
pluggy = ">=1.5,<2.0"
|
||||
tomli = {version = ">=1", markers = "python_version < \"3.11\""}
|
||||
|
||||
[package.extras]
|
||||
testing = ["argcomplete", "attrs (>=19.2)", "hypothesis (>=3.56)", "mock", "pygments (>=2.7.2)", "requests", "setuptools", "xmlschema"]
|
||||
dev = ["argcomplete", "attrs (>=19.2)", "hypothesis (>=3.56)", "mock", "pygments (>=2.7.2)", "requests", "setuptools", "xmlschema"]
|
||||
|
||||
[[package]]
|
||||
name = "python-dateutil"
|
||||
@@ -3647,28 +3661,28 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.3.5"
|
||||
version = "0.4.3"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.3.5-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:aef5bd3b89e657007e1be6b16553c8813b221ff6d92c7526b7e0227450981eac"},
|
||||
{file = "ruff-0.3.5-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:89b1e92b3bd9fca249153a97d23f29bed3992cff414b222fcd361d763fc53f12"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:5e55771559c89272c3ebab23326dc23e7f813e492052391fe7950c1a5a139d89"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:dabc62195bf54b8a7876add6e789caae0268f34582333cda340497c886111c39"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:3a05f3793ba25f194f395578579c546ca5d83e0195f992edc32e5907d142bfa3"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:dfd3504e881082959b4160ab02f7a205f0fadc0a9619cc481982b6837b2fd4c0"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:87258e0d4b04046cf1d6cc1c56fadbf7a880cc3de1f7294938e923234cf9e498"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:712e71283fc7d9f95047ed5f793bc019b0b0a29849b14664a60fd66c23b96da1"},
|
||||
{file = "ruff-0.3.5-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:a532a90b4a18d3f722c124c513ffb5e5eaff0cc4f6d3aa4bda38e691b8600c9f"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:122de171a147c76ada00f76df533b54676f6e321e61bd8656ae54be326c10296"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:d80a6b18a6c3b6ed25b71b05eba183f37d9bc8b16ace9e3d700997f00b74660b"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_i686.whl", hash = "sha256:a7b6e63194c68bca8e71f81de30cfa6f58ff70393cf45aab4c20f158227d5936"},
|
||||
{file = "ruff-0.3.5-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:a759d33a20c72f2dfa54dae6e85e1225b8e302e8ac655773aff22e542a300985"},
|
||||
{file = "ruff-0.3.5-py3-none-win32.whl", hash = "sha256:9d8605aa990045517c911726d21293ef4baa64f87265896e491a05461cae078d"},
|
||||
{file = "ruff-0.3.5-py3-none-win_amd64.whl", hash = "sha256:dc56bb16a63c1303bd47563c60482a1512721053d93231cf7e9e1c6954395a0e"},
|
||||
{file = "ruff-0.3.5-py3-none-win_arm64.whl", hash = "sha256:faeeae9905446b975dcf6d4499dc93439b131f1443ee264055c5716dd947af55"},
|
||||
{file = "ruff-0.3.5.tar.gz", hash = "sha256:a067daaeb1dc2baf9b82a32dae67d154d95212080c80435eb052d95da647763d"},
|
||||
{file = "ruff-0.4.3-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:b70800c290f14ae6fcbb41bbe201cf62dfca024d124a1f373e76371a007454ce"},
|
||||
{file = "ruff-0.4.3-py3-none-macosx_11_0_arm64.whl", hash = "sha256:08a0d6a22918ab2552ace96adeaca308833873a4d7d1d587bb1d37bae8728eb3"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:eba1f14df3c758dd7de5b55fbae7e1c8af238597961e5fb628f3de446c3c40c5"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:819fb06d535cc76dfddbfe8d3068ff602ddeb40e3eacbc90e0d1272bb8d97113"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:0bfc9e955e6dc6359eb6f82ea150c4f4e82b660e5b58d9a20a0e42ec3bb6342b"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:510a67d232d2ebe983fddea324dbf9d69b71c4d2dfeb8a862f4a127536dd4cfb"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:dc9ff11cd9a092ee7680a56d21f302bdda14327772cd870d806610a3503d001f"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:29efff25bf9ee685c2c8390563a5b5c006a3fee5230d28ea39f4f75f9d0b6f2f"},
|
||||
{file = "ruff-0.4.3-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:18b00e0bcccf0fc8d7186ed21e311dffd19761cb632241a6e4fe4477cc80ef6e"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:262f5635e2c74d80b7507fbc2fac28fe0d4fef26373bbc62039526f7722bca1b"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:7363691198719c26459e08cc17c6a3dac6f592e9ea3d2fa772f4e561b5fe82a3"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_i686.whl", hash = "sha256:eeb039f8428fcb6725bb63cbae92ad67b0559e68b5d80f840f11914afd8ddf7f"},
|
||||
{file = "ruff-0.4.3-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:927b11c1e4d0727ce1a729eace61cee88a334623ec424c0b1c8fe3e5f9d3c865"},
|
||||
{file = "ruff-0.4.3-py3-none-win32.whl", hash = "sha256:25cacda2155778beb0d064e0ec5a3944dcca9c12715f7c4634fd9d93ac33fd30"},
|
||||
{file = "ruff-0.4.3-py3-none-win_amd64.whl", hash = "sha256:7a1c3a450bc6539ef00da6c819fb1b76b6b065dec585f91456e7c0d6a0bbc725"},
|
||||
{file = "ruff-0.4.3-py3-none-win_arm64.whl", hash = "sha256:71ca5f8ccf1121b95a59649482470c5601c60a416bf189d553955b0338e34614"},
|
||||
{file = "ruff-0.4.3.tar.gz", hash = "sha256:ff0a3ef2e3c4b6d133fbedcf9586abfbe38d076041f2dc18ffb2c7e0485d5a07"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -3900,17 +3914,6 @@ webencodings = ">=0.4"
|
||||
doc = ["sphinx", "sphinx_rtd_theme"]
|
||||
test = ["flake8", "isort", "pytest"]
|
||||
|
||||
[[package]]
|
||||
name = "toml"
|
||||
version = "0.10.2"
|
||||
description = "Python Library for Tom's Obvious, Minimal Language"
|
||||
optional = false
|
||||
python-versions = ">=2.6, !=3.0.*, !=3.1.*, !=3.2.*"
|
||||
files = [
|
||||
{file = "toml-0.10.2-py2.py3-none-any.whl", hash = "sha256:806143ae5bfb6a3c6e736a764057db0e6a0e05e338b5630894a5f779cabb4f9b"},
|
||||
{file = "toml-0.10.2.tar.gz", hash = "sha256:b3bda1d108d5dd99f4a20d24d9c348e91c4db7ab1b749200bded2f839ccbe68f"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "tomli"
|
||||
version = "2.0.1"
|
||||
@@ -3944,13 +3947,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "tox"
|
||||
version = "4.14.2"
|
||||
version = "4.15.0"
|
||||
description = "tox is a generic virtualenv management and test command line tool"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "tox-4.14.2-py3-none-any.whl", hash = "sha256:2900c4eb7b716af4a928a7fdc2ed248ad6575294ed7cfae2ea41203937422847"},
|
||||
{file = "tox-4.14.2.tar.gz", hash = "sha256:0defb44f6dafd911b61788325741cc6b2e12ea71f987ac025ad4d649f1f1a104"},
|
||||
{file = "tox-4.15.0-py3-none-any.whl", hash = "sha256:300055f335d855b2ab1b12c5802de7f62a36d4fd53f30bd2835f6a201dda46ea"},
|
||||
{file = "tox-4.15.0.tar.gz", hash = "sha256:7a0beeef166fbe566f54f795b4906c31b428eddafc0102ac00d20998dd1933f6"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -3971,13 +3974,13 @@ testing = ["build[virtualenv] (>=1.0.3)", "covdefaults (>=2.3)", "detect-test-po
|
||||
|
||||
[[package]]
|
||||
name = "tqdm"
|
||||
version = "4.66.2"
|
||||
version = "4.66.4"
|
||||
description = "Fast, Extensible Progress Meter"
|
||||
optional = true
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "tqdm-4.66.2-py3-none-any.whl", hash = "sha256:1ee4f8a893eb9bef51c6e35730cebf234d5d0b6bd112b0271e10ed7c24a02bd9"},
|
||||
{file = "tqdm-4.66.2.tar.gz", hash = "sha256:6cd52cdf0fef0e0f543299cfc96fec90d7b8a7e88745f411ec33eb44d5ed3531"},
|
||||
{file = "tqdm-4.66.4-py3-none-any.whl", hash = "sha256:b75ca56b413b030bc3f00af51fd2c1a1a5eac6a0c1cca83cbb37a5c52abce644"},
|
||||
{file = "tqdm-4.66.4.tar.gz", hash = "sha256:e4d936c9de8727928f3be6079590e97d9abfe8d39a590be678eb5919ffc186bb"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -4254,4 +4257,4 @@ desktop = ["opencv-python"]
|
||||
[metadata]
|
||||
lock-version = "2.0"
|
||||
python-versions = "^3.8"
|
||||
content-hash = "56ddae6824a9f28c9954badd4c642c57f687b099c6169f97fa0372e294500c17"
|
||||
content-hash = "29af5aa06f97e77a2dba94c5a6d77d7d1903448724df07416026a378d3c6a64d"
|
||||
+3
-3
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.20.0rc2"
|
||||
version = "0.21.0rc3"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -43,7 +43,7 @@ defusedxml = "^0.7.1"
|
||||
opencv-python = { version = ">=4.5.5.64", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64"
|
||||
requests = { version = ">=2.26.0,<=2.31.0", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.2", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.4", optional = true }
|
||||
pillow = ">=9.4"
|
||||
|
||||
[tool.poetry.extras]
|
||||
@@ -67,7 +67,7 @@ nbconvert = "^7.14.2"
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
mkdocs-material = {extras = ["imaging"], version = "^9.5.5"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.25"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.26"}
|
||||
mike = "^2.0.0"
|
||||
# For Documentation Development use Python 3.10 or above
|
||||
# Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support
|
||||
|
||||
@@ -69,17 +69,20 @@ from supervision.draw.utils import (
|
||||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotators import EdgeAnnotator, VertexAnnotator
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
place_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
|
||||
@@ -13,7 +13,7 @@ from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.image import crop_image, place_image, resize_image
|
||||
from supervision.utils.image import crop_image, overlay_image, scale_image
|
||||
|
||||
|
||||
class BoundingBoxAnnotator(BaseAnnotator):
|
||||
@@ -1965,7 +1965,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
crop_image(image=scene, xyxy=xyxy) for xyxy in detections.xyxy.astype(int)
|
||||
]
|
||||
resized_crops = [
|
||||
resize_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
scale_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
]
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
@@ -1974,7 +1974,9 @@ class CropAnnotator(BaseAnnotator):
|
||||
(x1, y1), (x2, y2) = self.calculate_crop_coordinates(
|
||||
anchor=anchor, crop_wh=crop_wh, position=self.position
|
||||
)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=(x1, y1))
|
||||
scene = overlay_image(
|
||||
scene=scene, inserted_image=resized_crop, anchor=(x1, y1)
|
||||
)
|
||||
color = resolve_color(
|
||||
color=self.border_color,
|
||||
detections=detections,
|
||||
|
||||
@@ -18,6 +18,8 @@ class VideoAssets(Enum):
|
||||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
| `BEACH` | `beach-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/beach-1.mp4) |
|
||||
| `BASKETBALL` | `basketball-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/basketball-1.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
@@ -27,6 +29,8 @@ class VideoAssets(Enum):
|
||||
SUBWAY = "subway.mp4"
|
||||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
BEACH = "beach-1.mp4"
|
||||
BASKETBALL = "basketball-1.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
@@ -62,4 +66,12 @@ VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.PEOPLE_WALKING.value}",
|
||||
"0574c053c8686c3f1dc0aa3743e45cb9",
|
||||
),
|
||||
VideoAssets.BEACH.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BEACH.value}",
|
||||
"4175d42fec4d450ed081523fd39e0cf8",
|
||||
),
|
||||
VideoAssets.BASKETBALL.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BASKETBALL.value}",
|
||||
"60d94a3c7c47d16f09d342b088012ecc",
|
||||
),
|
||||
}
|
||||
@@ -9,10 +9,6 @@ from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
class BoxAnnotator:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
@@ -46,6 +42,10 @@ class BoxAnnotator:
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
|
||||
@@ -20,11 +20,11 @@ from supervision.detection.utils import (
|
||||
merge_data,
|
||||
non_max_merge,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.validators import validate_detections_fields
|
||||
|
||||
|
||||
def _merge_object_detection_pair(det1: Detections, det2: Detections) -> Detections:
|
||||
@@ -92,34 +92,71 @@ def _merge_object_detection_pair(det1: Detections, det2: Detections) -> Detectio
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
The `sv.Detections` allows you to convert results from a variety of object detection
|
||||
and segmentation models into a single, unified format. The `sv.Detections` class
|
||||
enables easy data manipulation and filtering, and provides a consistent API for
|
||||
Supervision's tools like trackers, annotators, and zones.
|
||||
The `sv.Detections` class in the Supervision library standardizes results from
|
||||
various object detection and segmentation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision [trackers](/trackers/), [annotators](/detection/annotators/), and [tools](/detection/tools/line_zone/).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Inference"
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
Use [`sv.Detections.from_inference`](/detection/core/#supervision.detection.core.Detections.from_inference)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
annotated_image = annotator.annotate(image, detections)
|
||||
```
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
=== "Ultralytics"
|
||||
|
||||
In `sv.Detections`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xyxy`, `mask`, `confidence`,
|
||||
`class_id`, and `tracker_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `detections[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
Use [`sv.Detections.from_ultralytics`](/detection/core/#supervision.detection.core.Detections.from_ultralytics)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
Use [`sv.Detections.from_transformers`](/detection/core/#supervision.detection.core.Detections.from_transformers)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
@@ -135,15 +172,7 @@ class Detections:
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xyxy: np.ndarray
|
||||
mask: Optional[np.ndarray] = None
|
||||
@@ -242,8 +271,8 @@ class Detections:
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
Creates a `sv.Detections` instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
!!! Note
|
||||
|
||||
@@ -267,10 +296,13 @@ class Detections:
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if "obb" in ultralytics_results and ultralytics_results.obb is not None:
|
||||
@@ -461,11 +493,6 @@ class Detections:
|
||||
Creates a Detections instance from object detection or segmentation
|
||||
[Transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key `class_name` in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
transformers_results (dict): The output of Transformers model inference. A
|
||||
dictionary containing the `scores`, `labels`, `boxes` and `masks` keys.
|
||||
@@ -502,6 +529,10 @@ class Detections:
|
||||
id2label=model.config.id2label
|
||||
)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
class_ids = transformers_results["labels"].cpu().detach().numpy().astype(int)
|
||||
@@ -575,17 +606,12 @@ class Detections:
|
||||
@classmethod
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key `class_name` in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
@@ -598,14 +624,18 @@ class Detections:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
@@ -655,10 +685,10 @@ class Detections:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_roboflow(result)
|
||||
|
||||
@@ -1,3 +1,4 @@
|
||||
import warnings
|
||||
from dataclasses import replace
|
||||
from typing import Iterable, Optional, Tuple
|
||||
|
||||
@@ -11,7 +12,7 @@ from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.utils.internal import deprecated_parameter
|
||||
from supervision.utils.internal import SupervisionWarnings, deprecated_parameter
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
@@ -21,7 +22,6 @@ class PolygonZone:
|
||||
Attributes:
|
||||
polygon (np.ndarray): A polygon represented by a numpy array of shape
|
||||
`(N, 2)`, containing the `x`, `y` coordinates of the points.
|
||||
frame_resolution_wh (Tuple[int, int]): The frame resolution (width, height)
|
||||
triggering_anchors (Iterable[sv.Position]): A list of positions specifying
|
||||
which anchors of the detections bounding box to consider when deciding on
|
||||
whether the detection fits within the PolygonZone
|
||||
@@ -41,18 +41,26 @@ class PolygonZone:
|
||||
def __init__(
|
||||
self,
|
||||
polygon: npt.NDArray[np.int64],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
frame_resolution_wh: Optional[Tuple[int, int]] = None,
|
||||
triggering_anchors: Iterable[Position] = (Position.BOTTOM_CENTER,),
|
||||
):
|
||||
if frame_resolution_wh is not None:
|
||||
warnings.warn(
|
||||
"The `frame_resolution_wh` parameter is no longer required and will be "
|
||||
"dropped in version supervision-0.24.0. The mask resolution is now "
|
||||
"calculated automatically based on the polygon coordinates.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
|
||||
self.polygon = polygon.astype(int)
|
||||
self.frame_resolution_wh = frame_resolution_wh
|
||||
self.triggering_anchors = triggering_anchors
|
||||
|
||||
self.current_count = 0
|
||||
|
||||
width, height = frame_resolution_wh
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
self.frame_resolution_wh = (x_max + 1, y_max + 1)
|
||||
self.mask = polygon_to_mask(
|
||||
polygon=polygon, resolution_wh=(width + 1, height + 1)
|
||||
polygon=polygon, resolution_wh=(x_max + 2, y_max + 2)
|
||||
)
|
||||
|
||||
def trigger(self, detections: Detections) -> npt.NDArray[np.bool_]:
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from itertools import chain
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
from typing import Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -787,102 +787,6 @@ def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
||||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple
|
||||
from typing import List, Tuple, Union
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
@@ -448,3 +448,19 @@ class ColorPalette:
|
||||
raise ValueError("idx argument should not be negative")
|
||||
idx = idx % len(self.colors)
|
||||
return self.colors[idx]
|
||||
|
||||
|
||||
def unify_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
"""
|
||||
Converts a color input in multiple formats to a standardized BGR format.
|
||||
|
||||
Args:
|
||||
color (Union[Tuple[int, int, int], Color]): The color input to be converted,
|
||||
which can be either a tuple of RGB values or an instance of a Color class.
|
||||
|
||||
Returns:
|
||||
Tuple[int, int, int]: The color in BGR format as a tuple of three integers.
|
||||
"""
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
@@ -5,12 +5,7 @@ from supervision.geometry.core import Point
|
||||
|
||||
def get_polygon_center(polygon: np.ndarray) -> Point:
|
||||
"""
|
||||
Calculate the center of a polygon.
|
||||
|
||||
This function takes in a polygon as a 2-dimensional numpy ndarray and
|
||||
returns the center of the polygon as a Point object.
|
||||
|
||||
The center is calculated as the center
|
||||
Calculate the center of a polygon. The center is calculated as the center
|
||||
of the solid figure formed by the points of the polygon
|
||||
|
||||
Parameters:
|
||||
@@ -23,12 +18,12 @@ def get_polygon_center(polygon: np.ndarray) -> Point:
|
||||
|
||||
Examples:
|
||||
```python
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
vertices = np.array([[0, 0], [0, 2], [2, 2], [2, 0]])
|
||||
get_polygon_center(vertices)
|
||||
Point(x=1, y=1)
|
||||
polygon = np.array([[0, 0], [0, 2], [2, 2], [2, 0]])
|
||||
sv.get_polygon_center(polygon=polygon)
|
||||
# Point(x=1, y=1)
|
||||
```
|
||||
"""
|
||||
|
||||
|
||||
Whitespace-only changes.
@@ -0,0 +1,177 @@
|
||||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
|
||||
|
||||
class BaseKeyPointAnnotator(ABC):
|
||||
@abstractmethod
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
pass
|
||||
|
||||
|
||||
class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton vertices on images. It uses
|
||||
specified key points to determine the locations where the vertices should be
|
||||
drawn.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
radius: int = 4,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for annotating key points.
|
||||
radius (int, optional): The radius of the circles used to represent the key
|
||||
points.
|
||||
"""
|
||||
self.color = color
|
||||
self.radius = radius
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with skeleton vertices based on the provided key
|
||||
points. It draws circles at each key point location.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
for x, y in xy:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=(int(x), int(y)),
|
||||
radius=self.radius,
|
||||
color=self.color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton edges on images using specified key
|
||||
points. It connects key points with lines to form the skeleton structure.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Optional[List[Tuple[int, int]]] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for the edges.
|
||||
thickness (int, optional): The thickness of the edges.
|
||||
edges (Optional[List[Tuple[int, int]]]): The edges to draw.
|
||||
If set to `None`, will attempt to select automatically.
|
||||
"""
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.edges = edges
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene by drawing lines between specified key points to form
|
||||
edges.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
edges = self.edges
|
||||
if not edges:
|
||||
edges = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not edges:
|
||||
warn(f"No skeleton found with {len(xy)} vertices")
|
||||
return scene
|
||||
|
||||
for class_a, class_b in edges:
|
||||
xy_a = xy[class_a - 1]
|
||||
xy_b = xy[class_b - 1]
|
||||
missing_a = np.allclose(xy_a, 0)
|
||||
missing_b = np.allclose(xy_b, 0)
|
||||
if missing_a or missing_b:
|
||||
continue
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
pt1=(int(xy_a[0]), int(xy_a[1])),
|
||||
pt2=(int(xy_b[0]), int(xy_b[1])),
|
||||
color=self.color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
@@ -0,0 +1,375 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import suppress
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_keypoints_fields
|
||||
|
||||
|
||||
@dataclass
|
||||
class KeyPoints:
|
||||
"""
|
||||
The `sv.KeyPoints` class in the Supervision library standardizes results from
|
||||
various keypoint detection and pose estimation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision annotators.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_ultralytics)
|
||||
method, which accepts model results.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, 2)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1]`
|
||||
confidence (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the confidence scores of the keypoint keypoints.
|
||||
class_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the class ids of the keypoint keypoints.
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xy: npt.NDArray[np.float32]
|
||||
class_id: Optional[npt.NDArray[np.int_]] = None
|
||||
confidence: Optional[npt.NDArray[np.float32]] = None
|
||||
data: Dict[str, Union[npt.NDArray[Any], List]] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
validate_keypoints_fields(
|
||||
xy=self.xy,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
data=self.data,
|
||||
)
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Returns the number of keypoints in the keypoints object.
|
||||
"""
|
||||
return len(self.xy)
|
||||
|
||||
def __iter__(
|
||||
self,
|
||||
) -> Iterator[
|
||||
Tuple[
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
Dict[str, Union[np.ndarray, List]],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
Iterates over the Keypoint object and yield a tuple of
|
||||
`(xy, confidence, class_id, data)` for each keypoint detection.
|
||||
"""
|
||||
for i in range(len(self.xy)):
|
||||
yield (
|
||||
self.xy[i],
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
get_data_item(self.data, i),
|
||||
)
|
||||
|
||||
def __eq__(self, other: KeyPoints) -> bool:
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xy, other.xy),
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
is_data_equal(self.data, other.data),
|
||||
]
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_inference(cls, inference_result: Union[dict, Any]) -> KeyPoints:
|
||||
"""
|
||||
Create a `sv.KeyPoints` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. When a keypoint detection model is used, this method
|
||||
extracts the keypoint coordinates, class IDs, confidences, and class names.
|
||||
|
||||
Args:
|
||||
inference_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions with keypoints.
|
||||
|
||||
Returns:
|
||||
(KeyPoints): A KeyPoints object containing the keypoint coordinates,
|
||||
class IDs, and confidences of each keypoint.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id=<POSE_MODEL_ID>, api_key=<ROBOFLOW_API_KEY>)
|
||||
|
||||
result = model.infer(image)[0]
|
||||
key_points = sv.KeyPoints.from_inference(result)
|
||||
```
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference_sdk import InferenceHTTPClient
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
client = InferenceHTTPClient(
|
||||
api_url="https://detect.roboflow.com",
|
||||
api_key=<ROBOFLOW_API_KEY>
|
||||
)
|
||||
|
||||
result = client.infer(image, model_id=<POSE_MODEL_ID>)
|
||||
key_points = sv.KeyPoints.from_inference(result)
|
||||
```
|
||||
"""
|
||||
if isinstance(inference_result, list):
|
||||
raise ValueError(
|
||||
"from_inference() operates on a single result at a time."
|
||||
"You can retrieve it like so: inference_result = model.infer(image)[0]"
|
||||
)
|
||||
|
||||
# Unpack the result if received from inference.get_model,
|
||||
# rather than inference_sdk.InferenceHTTPClient
|
||||
with suppress(AttributeError):
|
||||
inference_result = inference_result.dict(exclude_none=True, by_alias=True)
|
||||
|
||||
if not inference_result.get("predictions"):
|
||||
return cls.empty()
|
||||
|
||||
xy = []
|
||||
confidence = []
|
||||
class_id = []
|
||||
class_names = []
|
||||
|
||||
for prediction in inference_result["predictions"]:
|
||||
prediction_xy = []
|
||||
prediction_confidence = []
|
||||
for keypoint in prediction["keypoints"]:
|
||||
prediction_xy.append([keypoint["x"], keypoint["y"]])
|
||||
prediction_confidence.append(keypoint["confidence"])
|
||||
xy.append(prediction_xy)
|
||||
confidence.append(prediction_confidence)
|
||||
|
||||
class_id.append(prediction["class_id"])
|
||||
class_names.append(prediction["class"])
|
||||
|
||||
data = {CLASS_NAME_DATA_FIELD: np.array(class_names)}
|
||||
|
||||
return cls(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=np.array(confidence, dtype=np.float32),
|
||||
class_id=np.array(class_id, dtype=int),
|
||||
data=data,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> KeyPoints:
|
||||
"""
|
||||
Creates a KeyPoints instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.engine.results.Keypoints):
|
||||
The output Results instance from YOLOv8
|
||||
|
||||
Returns:
|
||||
KeyPoints: A new KeyPoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
"""
|
||||
if ultralytics_results.keypoints.xy.numel() == 0:
|
||||
return cls.empty()
|
||||
|
||||
xy = ultralytics_results.keypoints.xy.cpu().numpy()
|
||||
class_id = ultralytics_results.boxes.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
|
||||
confidence = ultralytics_results.keypoints.conf.cpu().numpy()
|
||||
data = {CLASS_NAME_DATA_FIELD: class_names}
|
||||
return cls(xy, class_id, confidence, data)
|
||||
|
||||
@classmethod
|
||||
def from_yolo_nas(cls, yolo_nas_results) -> KeyPoints:
|
||||
"""
|
||||
Create a KeyPoints instance from a YOLO NAS results.
|
||||
|
||||
Args:
|
||||
yolo_nas_results (ImagePoseEstimationPrediction):
|
||||
The output object from YOLO NAS.
|
||||
|
||||
Returns:
|
||||
KeyPoints: A new KeyPoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import torch
|
||||
import supervision as sv
|
||||
import super_gradients
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
yolo_nas = super_gradients.training.models.get(
|
||||
"yolo_nas_pose_s", pretrained_weights="coco_pose").to(device)
|
||||
|
||||
results = yolo_nas.predict(image, conf=0.1)
|
||||
keypoints = sv.KeyPoints.from_yolo_nas(results)
|
||||
```
|
||||
"""
|
||||
if len(yolo_nas_results.prediction.poses) == 0:
|
||||
return cls.empty()
|
||||
|
||||
xy = yolo_nas_results.prediction.poses[:, :, :2]
|
||||
confidence = yolo_nas_results.prediction.poses[:, :, 2]
|
||||
|
||||
# yolo_nas_results treats params differently.
|
||||
# prediction.labels may not exist, whereas class_names might be None
|
||||
if hasattr(yolo_nas_results.prediction, "labels"):
|
||||
class_id = yolo_nas_results.prediction.labels # np.array[int]
|
||||
else:
|
||||
class_id = None
|
||||
|
||||
data = {}
|
||||
if class_id is not None and yolo_nas_results.class_names is not None:
|
||||
class_names = []
|
||||
for c_id in class_id:
|
||||
name = yolo_nas_results.class_names[c_id] # tuple[str]
|
||||
class_names.append(name)
|
||||
data[CLASS_NAME_DATA_FIELD] = class_names
|
||||
|
||||
return cls(
|
||||
xy=xy,
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
data=data,
|
||||
)
|
||||
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union[KeyPoints, List, np.ndarray, None]:
|
||||
"""
|
||||
Get a subset of the KeyPoints object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new KeyPoints object that represents a subset of the original
|
||||
keypoints. When provided with a string, it accesses the corresponding item in
|
||||
the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the KeyPoints or an item from the data.
|
||||
|
||||
Returns:
|
||||
Union[KeyPoints, Any]: A subset of the KeyPoints object or an item from
|
||||
the data field.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
keypoints = sv.KeyPoints()
|
||||
|
||||
first_detection = keypoints[0]
|
||||
first_10_keypoints = keypoints[0:10]
|
||||
some_keypoints = keypoints[[0, 2, 4]]
|
||||
class_0_keypoints = keypoints[keypoints.class_id == 0]
|
||||
high_confidence_keypoints = keypoints[keypoints.confidence > 0.5]
|
||||
|
||||
feature_vector = keypoints['feature_vector']
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return KeyPoints(
|
||||
xy=self.xy[index],
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
data=get_data_item(self.data, index),
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
"""
|
||||
Set a value in the data dictionary of the KeyPoints object.
|
||||
|
||||
Args:
|
||||
key (str): The key in the data dictionary to set.
|
||||
value (Union[np.ndarray, List]): The value to set for the key.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
keypoints['names'] = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in keypoints.class_id
|
||||
]
|
||||
```
|
||||
"""
|
||||
if not isinstance(value, (np.ndarray, list)):
|
||||
raise TypeError("Value must be a np.ndarray or a list")
|
||||
|
||||
if isinstance(value, list):
|
||||
value = np.array(value)
|
||||
|
||||
self.data[key] = value
|
||||
|
||||
@classmethod
|
||||
def empty(cls) -> KeyPoints:
|
||||
"""
|
||||
Create an empty Keypoints object with no keypoints.
|
||||
|
||||
Returns:
|
||||
(KeyPoints): An empty Keypoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
from supervision import Keypoints
|
||||
empty_keypoints = Keypoints.empty()
|
||||
```
|
||||
"""
|
||||
return cls(xy=np.empty((0, 0, 2), dtype=np.float32))
|
||||
@@ -0,0 +1,36 @@
|
||||
from enum import Enum
|
||||
from typing import Dict, List, Tuple
|
||||
|
||||
Edges = List[Tuple[int, int]]
|
||||
|
||||
|
||||
class Skeleton(Enum):
|
||||
COCO = [
|
||||
(1, 2),
|
||||
(1, 3),
|
||||
(2, 3),
|
||||
(2, 4),
|
||||
(3, 5),
|
||||
(6, 12),
|
||||
(6, 7),
|
||||
(6, 8),
|
||||
(7, 13),
|
||||
(7, 9),
|
||||
(8, 10),
|
||||
(9, 11),
|
||||
(12, 13),
|
||||
(14, 12),
|
||||
(15, 13),
|
||||
(16, 14),
|
||||
(17, 15),
|
||||
]
|
||||
|
||||
|
||||
SKELETONS_BY_EDGE_COUNT: Dict[int, Edges] = {}
|
||||
SKELETONS_BY_VERTEX_COUNT: Dict[int, Edges] = {}
|
||||
|
||||
for skeleton in Skeleton:
|
||||
SKELETONS_BY_EDGE_COUNT[len(skeleton.value)] = skeleton.value
|
||||
|
||||
unique_vertices = set(vertex for edge in skeleton.value for vertex in edge)
|
||||
SKELETONS_BY_VERTEX_COUNT[len(unique_vertices)] = skeleton.value
|
||||
@@ -12,8 +12,9 @@ from supervision.utils.internal import deprecated_parameter
|
||||
|
||||
class STrack(BaseTrack):
|
||||
shared_kalman = KalmanFilter()
|
||||
_external_count = 0
|
||||
|
||||
def __init__(self, tlwh, score, class_ids):
|
||||
def __init__(self, tlwh, score, class_ids, minimum_consecutive_frames):
|
||||
# wait activate
|
||||
self._tlwh = np.asarray(tlwh, dtype=np.float32)
|
||||
self.kalman_filter = None
|
||||
@@ -24,6 +25,10 @@ class STrack(BaseTrack):
|
||||
self.class_ids = class_ids
|
||||
self.tracklet_len = 0
|
||||
|
||||
self.external_track_id = -1
|
||||
|
||||
self.minimum_consecutive_frames = minimum_consecutive_frames
|
||||
|
||||
def predict(self):
|
||||
mean_state = self.mean.copy()
|
||||
if self.state != TrackState.Tracked:
|
||||
@@ -53,7 +58,7 @@ class STrack(BaseTrack):
|
||||
def activate(self, kalman_filter, frame_id):
|
||||
"""Start a new tracklet"""
|
||||
self.kalman_filter = kalman_filter
|
||||
self.track_id = self.next_id()
|
||||
self.internal_track_id = self.next_id()
|
||||
self.mean, self.covariance = self.kalman_filter.initiate(
|
||||
self.tlwh_to_xyah(self._tlwh)
|
||||
)
|
||||
@@ -62,6 +67,10 @@ class STrack(BaseTrack):
|
||||
self.state = TrackState.Tracked
|
||||
if frame_id == 1:
|
||||
self.is_activated = True
|
||||
|
||||
if self.minimum_consecutive_frames == 1:
|
||||
self.external_track_id = self.next_external_id()
|
||||
|
||||
self.frame_id = frame_id
|
||||
self.start_frame = frame_id
|
||||
|
||||
@@ -71,10 +80,10 @@ class STrack(BaseTrack):
|
||||
)
|
||||
self.tracklet_len = 0
|
||||
self.state = TrackState.Tracked
|
||||
self.is_activated = True
|
||||
|
||||
self.frame_id = frame_id
|
||||
if new_id:
|
||||
self.track_id = self.next_id()
|
||||
self.internal_track_id = self.next_id()
|
||||
self.score = new_track.score
|
||||
|
||||
def update(self, new_track, frame_id):
|
||||
@@ -93,7 +102,10 @@ class STrack(BaseTrack):
|
||||
self.mean, self.covariance, self.tlwh_to_xyah(new_tlwh)
|
||||
)
|
||||
self.state = TrackState.Tracked
|
||||
self.is_activated = True
|
||||
if self.tracklet_len == self.minimum_consecutive_frames:
|
||||
self.is_activated = True
|
||||
if self.external_track_id == -1:
|
||||
self.external_track_id = self.next_external_id()
|
||||
|
||||
self.score = new_track.score
|
||||
|
||||
@@ -131,6 +143,15 @@ class STrack(BaseTrack):
|
||||
def to_xyah(self):
|
||||
return self.tlwh_to_xyah(self.tlwh)
|
||||
|
||||
@staticmethod
|
||||
def next_external_id():
|
||||
STrack._external_count += 1
|
||||
return STrack._external_count
|
||||
|
||||
@staticmethod
|
||||
def reset_external_counter():
|
||||
STrack._external_count = 0
|
||||
|
||||
@staticmethod
|
||||
def tlbr_to_tlwh(tlbr):
|
||||
ret = np.asarray(tlbr).copy()
|
||||
@@ -144,7 +165,9 @@ class STrack(BaseTrack):
|
||||
return ret
|
||||
|
||||
def __repr__(self):
|
||||
return "OT_{}_({}-{})".format(self.track_id, self.start_frame, self.end_frame)
|
||||
return "OT_{}_({}-{})".format(
|
||||
self.internal_track_id, self.start_frame, self.end_frame
|
||||
)
|
||||
|
||||
|
||||
def detections2boxes(detections: Detections) -> np.ndarray:
|
||||
@@ -186,6 +209,10 @@ class ByteTrack:
|
||||
Increasing minimum_matching_threshold improves accuracy but risks fragmentation.
|
||||
Decreasing it improves completeness but risks false positives and drift.
|
||||
frame_rate (int, optional): The frame rate of the video.
|
||||
minimum_consecutive_frames (int, optional): Number of consecutive frames that an object must
|
||||
be tracked before it is considered a 'valid' track.
|
||||
Increasing minimum_consecutive_frames prevents the creation of accidental tracks from
|
||||
false detection or double detection, but risks missing shorter tracks.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
@deprecated_parameter(
|
||||
@@ -218,6 +245,7 @@ class ByteTrack:
|
||||
lost_track_buffer: int = 30,
|
||||
minimum_matching_threshold: float = 0.8,
|
||||
frame_rate: int = 30,
|
||||
minimum_consecutive_frames: int = 1,
|
||||
):
|
||||
self.track_activation_threshold = track_activation_threshold
|
||||
self.minimum_matching_threshold = minimum_matching_threshold
|
||||
@@ -225,6 +253,7 @@ class ByteTrack:
|
||||
self.frame_id = 0
|
||||
self.det_thresh = self.track_activation_threshold + 0.1
|
||||
self.max_time_lost = int(frame_rate / 30.0 * lost_track_buffer)
|
||||
self.minimum_consecutive_frames = minimum_consecutive_frames
|
||||
self.kalman_filter = KalmanFilter()
|
||||
|
||||
self.tracked_tracks: List[STrack] = []
|
||||
@@ -285,11 +314,14 @@ class ByteTrack:
|
||||
matches, _, _ = matching.linear_assignment(iou_costs, 0.5)
|
||||
detections.tracker_id = np.full(len(detections), -1, dtype=int)
|
||||
for i_detection, i_track in matches:
|
||||
detections.tracker_id[i_detection] = int(tracks[i_track].track_id)
|
||||
detections.tracker_id[i_detection] = int(
|
||||
tracks[i_track].external_track_id
|
||||
)
|
||||
|
||||
return detections[detections.tracker_id != -1]
|
||||
|
||||
else:
|
||||
detections = Detections.empty()
|
||||
detections.tracker_id = np.array([], dtype=int)
|
||||
|
||||
return detections
|
||||
@@ -308,6 +340,7 @@ class ByteTrack:
|
||||
self.lost_tracks: List[STrack] = []
|
||||
self.removed_tracks: List[STrack] = []
|
||||
BaseTrack.reset_counter()
|
||||
STrack.reset_external_counter()
|
||||
|
||||
def update_with_tensors(self, tensors: np.ndarray) -> List[STrack]:
|
||||
"""
|
||||
@@ -345,7 +378,7 @@ class ByteTrack:
|
||||
if len(dets) > 0:
|
||||
"""Detections"""
|
||||
detections = [
|
||||
STrack(STrack.tlbr_to_tlwh(tlbr), s, c)
|
||||
STrack(STrack.tlbr_to_tlwh(tlbr), s, c, self.minimum_consecutive_frames)
|
||||
for (tlbr, s, c) in zip(dets, scores_keep, class_ids_keep)
|
||||
]
|
||||
else:
|
||||
@@ -387,7 +420,7 @@ class ByteTrack:
|
||||
if len(dets_second) > 0:
|
||||
"""Detections"""
|
||||
detections_second = [
|
||||
STrack(STrack.tlbr_to_tlwh(tlbr), s, c)
|
||||
STrack(STrack.tlbr_to_tlwh(tlbr), s, c, self.minimum_consecutive_frames)
|
||||
for (tlbr, s, c) in zip(dets_second, scores_second, class_ids_second)
|
||||
]
|
||||
else:
|
||||
@@ -468,22 +501,22 @@ def joint_tracks(
|
||||
) -> List[STrack]:
|
||||
"""
|
||||
Joins two lists of tracks, ensuring that the resulting list does not
|
||||
contain tracks with duplicate track_id values.
|
||||
contain tracks with duplicate internal_track_id values.
|
||||
|
||||
Parameters:
|
||||
track_list_a: First list of tracks (with track_id attribute).
|
||||
track_list_b: Second list of tracks (with track_id attribute).
|
||||
track_list_a: First list of tracks (with internal_track_id attribute).
|
||||
track_list_b: Second list of tracks (with internal_track_id attribute).
|
||||
|
||||
Returns:
|
||||
Combined list of tracks from track_list_a and track_list_b
|
||||
without duplicate track_id values.
|
||||
without duplicate internal_track_id values.
|
||||
"""
|
||||
seen_track_ids = set()
|
||||
result = []
|
||||
|
||||
for track in track_list_a + track_list_b:
|
||||
if track.track_id not in seen_track_ids:
|
||||
seen_track_ids.add(track.track_id)
|
||||
if track.internal_track_id not in seen_track_ids:
|
||||
seen_track_ids.add(track.internal_track_id)
|
||||
result.append(track)
|
||||
|
||||
return result
|
||||
@@ -492,17 +525,17 @@ def joint_tracks(
|
||||
def sub_tracks(track_list_a: List, track_list_b: List) -> List[int]:
|
||||
"""
|
||||
Returns a list of tracks from track_list_a after removing any tracks
|
||||
that share the same track_id with tracks in track_list_b.
|
||||
that share the same internal_track_id with tracks in track_list_b.
|
||||
|
||||
Parameters:
|
||||
track_list_a: List of tracks (with track_id attribute).
|
||||
track_list_b: List of tracks (with track_id attribute) to
|
||||
track_list_a: List of tracks (with internal_track_id attribute).
|
||||
track_list_b: List of tracks (with internal_track_id attribute) to
|
||||
be subtracted from track_list_a.
|
||||
Returns:
|
||||
List of remaining tracks from track_list_a after subtraction.
|
||||
"""
|
||||
tracks = {track.track_id: track for track in track_list_a}
|
||||
track_ids_b = {track.track_id for track in track_list_b}
|
||||
tracks = {track.internal_track_id: track for track in track_list_a}
|
||||
track_ids_b = {track.internal_track_id for track in track_list_b}
|
||||
|
||||
for track_id in track_ids_b:
|
||||
tracks.pop(track_id, None)
|
||||
|
||||
@@ -81,7 +81,7 @@ def pillow_to_cv2(image: Image.Image) -> np.ndarray:
|
||||
image (Image.Image): Pillow image (in RGB format).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Input image converted to OpenCV format.
|
||||
(np.ndarray): Input image converted to OpenCV format.
|
||||
"""
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
@@ -97,7 +97,7 @@ def cv2_to_pillow(image: np.ndarray) -> Image.Image:
|
||||
image (np.ndarray): OpenCV image (in BGR format).
|
||||
|
||||
Returns:
|
||||
Image.Image: Input image converted to Pillow format.
|
||||
(Image.Image): Input image converted to Pillow format.
|
||||
"""
|
||||
image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)
|
||||
return Image.fromarray(image)
|
||||
+283
-148
@@ -7,9 +7,10 @@ from typing import Callable, List, Literal, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.color import Color, unify_to_bgr
|
||||
from supervision.draw.utils import calculate_optimal_text_scale, draw_text
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.utils.conversion import (
|
||||
@@ -25,103 +26,326 @@ MAX_COLUMNS_FOR_SINGLE_ROW_GRID = 3
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def crop_image(image: np.ndarray, xyxy: np.ndarray) -> np.ndarray:
|
||||
def crop_image(
|
||||
image: ImageType,
|
||||
xyxy: Union[npt.NDArray[int], List[int], Tuple[int, int, int, int]],
|
||||
) -> ImageType:
|
||||
"""
|
||||
Crops the given image based on the given bounding box.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be cropped, represented as a numpy array.
|
||||
xyxy (np.ndarray): A numpy array containing the bounding box coordinates
|
||||
in the format (x1, y1, x2, y2).
|
||||
image (ImageType): The image to be cropped. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
xyxy (Union[np.ndarray, List[int], Tuple[int, int, int, int]]): A bounding box
|
||||
coordinates in the format `(x_min, y_min, x_max, y_max)`, accepted as either
|
||||
a `numpy.ndarray`, a `list`, or a `tuple`.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The cropped image as a numpy array.
|
||||
(ImageType): The cropped image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
detection = sv.Detections(...)
|
||||
with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
for xyxy in detection.xyxy:
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
sink.save_image(image=cropped_image)
|
||||
```
|
||||
"""
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.shape
|
||||
# (400, 400, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.size
|
||||
# (400, 400)
|
||||
```
|
||||
|
||||
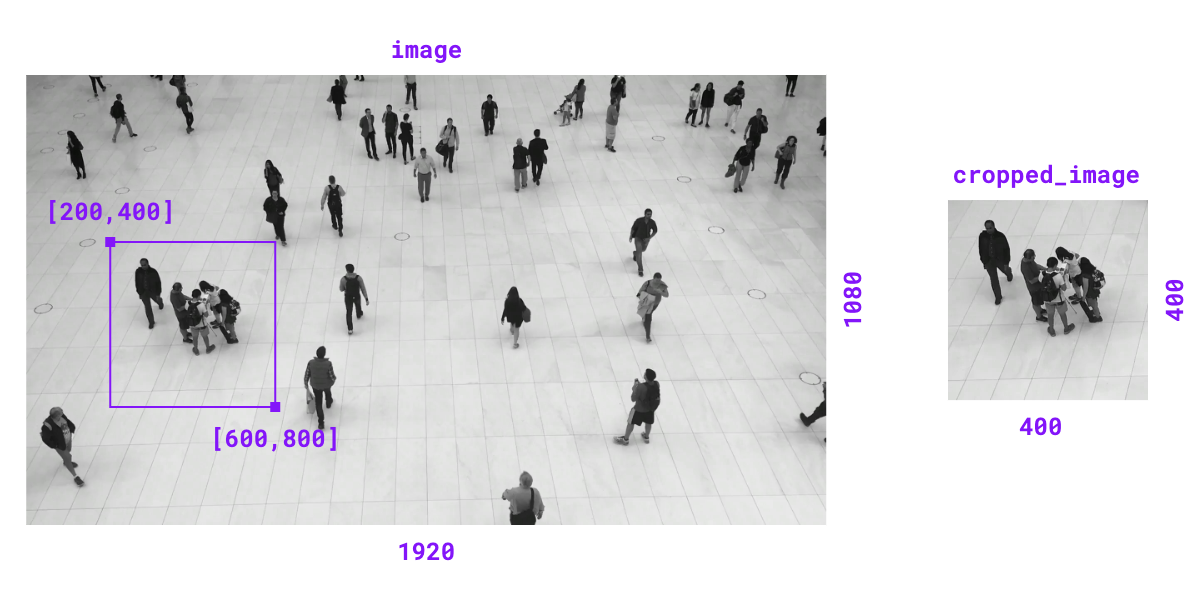{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if isinstance(xyxy, (list, tuple)):
|
||||
xyxy = np.array(xyxy)
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return image[y1:y2, x1:x2]
|
||||
x_min, y_min, x_max, y_max = xyxy.flatten()
|
||||
return image[y_min:y_max, x_min:x_max]
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image(image: np.ndarray, scale_factor: float) -> np.ndarray:
|
||||
def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
"""
|
||||
Resizes an image by a given scale factor using cv2.INTER_LINEAR interpolation.
|
||||
Scales the given image based on the given scale factor.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The input image to be resized.
|
||||
image (ImageType): The image to be scaled. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale
|
||||
factor > 1.0 zooms in, < 1.0 zooms out.
|
||||
factor > `1.0` zooms in, < `1.0` zooms out.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The resized image.
|
||||
(ImageType): The scaled image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Raises:
|
||||
ValueError: If the scale factor is non-positive.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.shape
|
||||
# (540, 960, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.size
|
||||
# (960, 540)
|
||||
```
|
||||
"""
|
||||
if scale_factor <= 0:
|
||||
raise ValueError("Scale factor must be positive.")
|
||||
|
||||
old_width, old_height = image.shape[1], image.shape[0]
|
||||
nwe_width = int(old_width * scale_factor)
|
||||
new_height = int(old_height * scale_factor)
|
||||
|
||||
return cv2.resize(image, (nwe_width, new_height), interpolation=cv2.INTER_LINEAR)
|
||||
width_old, height_old = image.shape[1], image.shape[0]
|
||||
width_new = int(width_old * scale_factor)
|
||||
height_new = int(height_old * scale_factor)
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
def place_image(
|
||||
scene: np.ndarray, image: np.ndarray, anchor: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def resize_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
keep_aspect_ratio: bool = False,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes the given image to a specified resolution. Can maintain the original aspect
|
||||
ratio or resize directly to the desired dimensions.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool, optional): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.shape
|
||||
# (562, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.size
|
||||
# (1000, 562)
|
||||
```
|
||||
|
||||
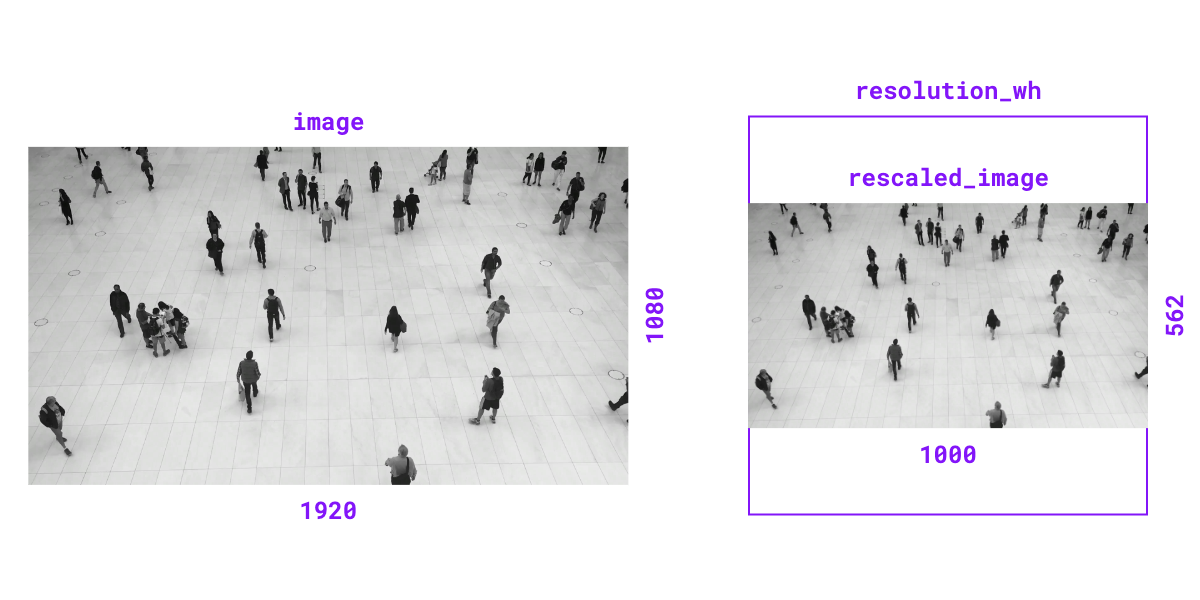{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if keep_aspect_ratio:
|
||||
image_ratio = image.shape[1] / image.shape[0]
|
||||
target_ratio = resolution_wh[0] / resolution_wh[1]
|
||||
if image_ratio >= target_ratio:
|
||||
width_new = resolution_wh[0]
|
||||
height_new = int(resolution_wh[0] / image_ratio)
|
||||
else:
|
||||
height_new = resolution_wh[1]
|
||||
width_new = int(resolution_wh[1] * image_ratio)
|
||||
else:
|
||||
width_new, height_new = resolution_wh
|
||||
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = Color.BLACK,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes and pads an image to a specified resolution with a given color, maintaining
|
||||
the original aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
color (Union[Tuple[int, int, int], Color]): The color to pad with. If tuple
|
||||
provided it should be in BGR format.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.shape
|
||||
# (1000, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.size
|
||||
# (1000, 1000)
|
||||
```
|
||||
|
||||
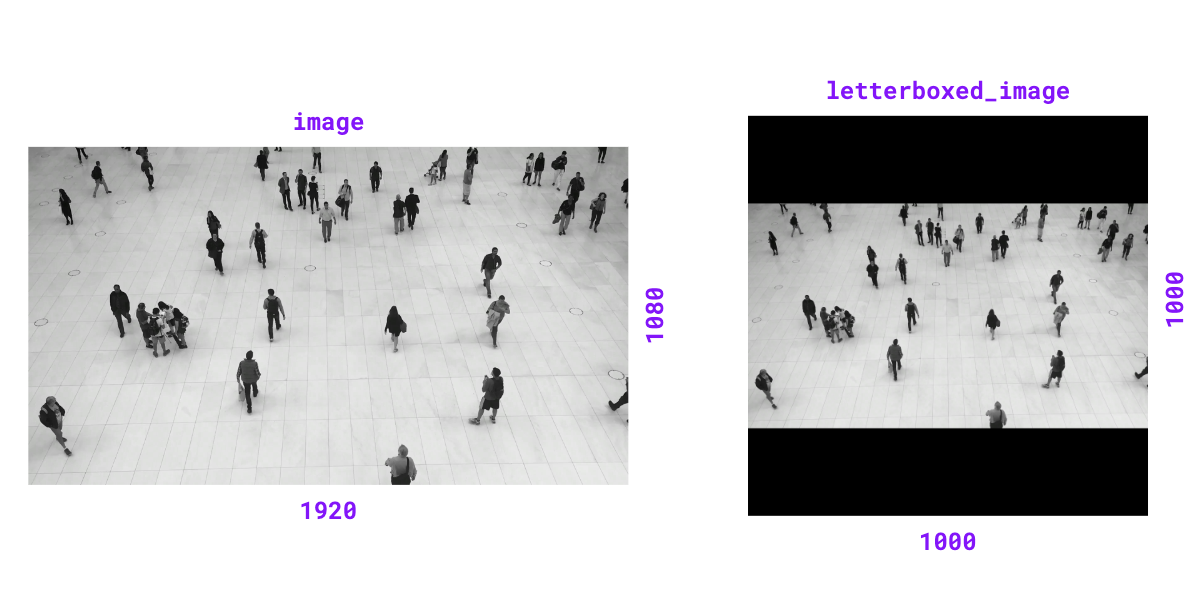{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
color = unify_to_bgr(color=color)
|
||||
resized_image = resize_image(
|
||||
image=image, resolution_wh=resolution_wh, keep_aspect_ratio=True
|
||||
)
|
||||
height_new, width_new = resized_image.shape[:2]
|
||||
padding_top = (resolution_wh[1] - height_new) // 2
|
||||
padding_bottom = resolution_wh[1] - height_new - padding_top
|
||||
padding_left = (resolution_wh[0] - width_new) // 2
|
||||
padding_right = resolution_wh[0] - width_new - padding_left
|
||||
return cv2.copyMakeBorder(
|
||||
resized_image,
|
||||
padding_top,
|
||||
padding_bottom,
|
||||
padding_left,
|
||||
padding_right,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
overlay: npt.NDArray[np.uint8],
|
||||
anchor: Tuple[int, int],
|
||||
) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
Places an image onto a scene at a given anchor point, handling cases where
|
||||
the image's position is partially or completely outside the scene's bounds.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The background scene onto which the image is placed.
|
||||
image (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The (x, y) coordinates in the scene where the
|
||||
image (np.ndarray): The background scene onto which the image is placed.
|
||||
overlay (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The `(x, y)` coordinates in the scene where the
|
||||
top-left corner of the image will be placed.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The modified scene with the image placed at the anchor point,
|
||||
or unchanged if the image placement is completely outside the scene.
|
||||
"""
|
||||
scene_height, scene_width = scene.shape[:2]
|
||||
image_height, image_width = image.shape[:2]
|
||||
(np.ndarray): The result image with overlay.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
overlay = np.zeros((400, 400, 3), dtype=np.uint8)
|
||||
result_image = sv.overlay_image(image=image, overlay=overlay, anchor=(200, 400))
|
||||
```
|
||||
|
||||
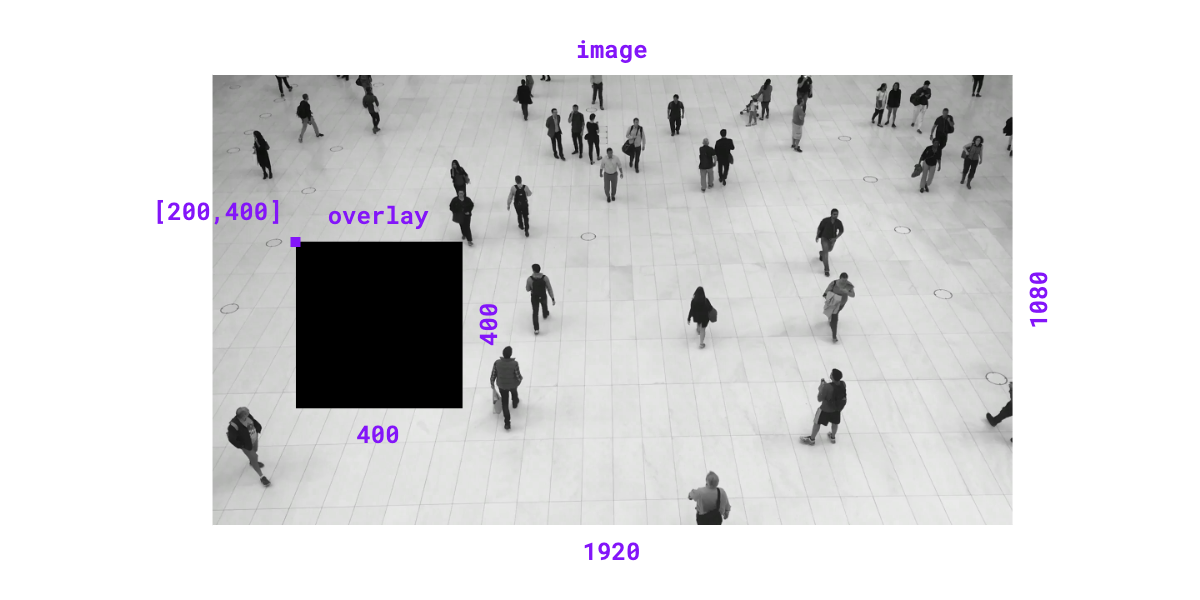{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
scene_height, scene_width = image.shape[:2]
|
||||
image_height, image_width = overlay.shape[:2]
|
||||
anchor_x, anchor_y = anchor
|
||||
|
||||
is_out_horizontally = anchor_x + image_width <= 0 or anchor_x >= scene_width
|
||||
is_out_vertically = anchor_y + image_height <= 0 or anchor_y >= scene_height
|
||||
|
||||
if is_out_horizontally or is_out_vertically:
|
||||
return scene
|
||||
return image
|
||||
|
||||
start_y = max(anchor_y, 0)
|
||||
start_x = max(anchor_x, 0)
|
||||
end_y = min(scene_height, anchor_y + image_height)
|
||||
end_x = min(scene_width, anchor_x + image_width)
|
||||
x_min = max(anchor_x, 0)
|
||||
y_min = max(anchor_y, 0)
|
||||
x_max = min(scene_width, anchor_x + image_width)
|
||||
y_max = min(scene_height, anchor_y + image_height)
|
||||
|
||||
crop_start_y = max(-anchor_y, 0)
|
||||
crop_start_x = max(-anchor_x, 0)
|
||||
crop_end_y = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
crop_end_x = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_x_min = max(-anchor_x, 0)
|
||||
crop_y_min = max(-anchor_y, 0)
|
||||
crop_x_max = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_y_max = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
|
||||
scene[start_y:end_y, start_x:end_x] = image[
|
||||
crop_start_y:crop_end_y, crop_start_x:crop_end_x
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
|
||||
return scene
|
||||
return image
|
||||
|
||||
|
||||
class ImageSink:
|
||||
@@ -145,13 +369,13 @@ class ImageSink:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
with sv.ImageSink(target_dir_path='target/directory/path',
|
||||
overwrite=True) as sink:
|
||||
for image in sv.get_video_frames_generator(
|
||||
source_path='source_video.mp4', stride=2):
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>, stride=2)
|
||||
|
||||
with sv.ImageSink(target_dir_path=<TARGET_CROPS_DIRECTORY>) as sink:
|
||||
for image in frames_generator:
|
||||
sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
""" # noqa E501 // docs
|
||||
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
@@ -285,14 +509,14 @@ def create_tiles(
|
||||
raise ValueError("Could not create image tiles from empty list of images.")
|
||||
if return_type == "auto":
|
||||
return_type = _negotiate_tiles_format(images=images)
|
||||
tile_padding_color = _color_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = _color_to_bgr(color=tile_margin_color)
|
||||
tile_padding_color = unify_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = unify_to_bgr(color=tile_margin_color)
|
||||
images = images_to_cv2(images=images)
|
||||
if single_tile_size is None:
|
||||
single_tile_size = _aggregate_images_shape(images=images, mode=tile_scaling)
|
||||
resized_images = [
|
||||
letterbox_image(
|
||||
image=i, desired_size=single_tile_size, color=tile_padding_color
|
||||
image=i, resolution_wh=single_tile_size, color=tile_padding_color
|
||||
)
|
||||
for i in images
|
||||
]
|
||||
@@ -311,8 +535,8 @@ def create_tiles(
|
||||
titles_anchors = fill(
|
||||
sequence=titles_anchors, desired_size=len(images), content=None
|
||||
)
|
||||
titles_color = _color_to_bgr(color=titles_color)
|
||||
titles_background_color = _color_to_bgr(color=titles_background_color)
|
||||
titles_color = unify_to_bgr(color=titles_color)
|
||||
titles_background_color = unify_to_bgr(color=titles_background_color)
|
||||
tiles = _generate_tiles(
|
||||
images=resized_images,
|
||||
grid_size=grid_size,
|
||||
@@ -542,92 +766,3 @@ def _generate_color_image(
|
||||
shape: Tuple[int, int], color: Tuple[int, int, int]
|
||||
) -> np.ndarray:
|
||||
return np.ones(shape[::-1] + (3,), dtype=np.uint8) * color
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = (0, 0, 0),
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image to fit the desired size, preserving its aspect
|
||||
ratio, adding padding of given color if needed to maintain aspect ratio.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
desired_size (Tuple[int, int]): image size (width, height) representing
|
||||
the target dimensions.
|
||||
color (Union[Tuple[int, int, int], Color]): the color to pad with - If
|
||||
tuple provided - should be BGR.
|
||||
|
||||
Returns:
|
||||
np.ndarray: letterboxed image (type may be adjusted to PIL.Image by
|
||||
decorator if function was called with PIL.Image)
|
||||
"""
|
||||
color = _color_to_bgr(color=color)
|
||||
resized_img = resize_image_keeping_aspect_ratio(
|
||||
image=image,
|
||||
desired_size=desired_size,
|
||||
)
|
||||
new_height, new_width = resized_img.shape[:2]
|
||||
top_padding = (desired_size[1] - new_height) // 2
|
||||
bottom_padding = desired_size[1] - new_height - top_padding
|
||||
left_padding = (desired_size[0] - new_width) // 2
|
||||
right_padding = desired_size[0] - new_width - left_padding
|
||||
return cv2.copyMakeBorder(
|
||||
resized_img,
|
||||
top_padding,
|
||||
bottom_padding,
|
||||
left_padding,
|
||||
right_padding,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image_keeping_aspect_ratio(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image preserving its aspect ratio.
|
||||
|
||||
For example: input image is (640, 480) and we want to resize into
|
||||
(1024, 1024). If this rectangular image is just resized naively
|
||||
to square-shape output - aspect ratio would be altered. If we do not
|
||||
want this to happen - we may resize bigger dimension (640) to 1024.
|
||||
Ratio of change is 1.6. This ratio is later on used to calculate scaling
|
||||
in the other dimension. As a result we have (1024, 768) image.
|
||||
|
||||
Parameters:
|
||||
- image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
- desired_size (Tuple[int, int]): image size (width, height) representing the
|
||||
target dimensions. Parameter will be used to dictate maximum size of
|
||||
output image. Output size may be smaller - to preserve aspect ratio of original
|
||||
image.
|
||||
|
||||
Returns:
|
||||
np.ndarray: resized image (type may be adjusted to PIL.Image by decorator
|
||||
if function was called with PIL.Image)
|
||||
"""
|
||||
if image.shape[:2] == desired_size[::-1]:
|
||||
return image
|
||||
img_ratio = image.shape[1] / image.shape[0]
|
||||
desired_ratio = desired_size[0] / desired_size[1]
|
||||
if img_ratio >= desired_ratio:
|
||||
new_width = desired_size[0]
|
||||
new_height = int(desired_size[0] / img_ratio)
|
||||
else:
|
||||
new_height = desired_size[1]
|
||||
new_width = int(desired_size[1] * img_ratio)
|
||||
return cv2.resize(image, (new_width, new_height))
|
||||
|
||||
|
||||
def _color_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
@@ -16,7 +16,7 @@ def create_batches(
|
||||
batch_size (int): The expected size of a batch.
|
||||
|
||||
Returns:
|
||||
Generator[List[V], None, None]: A generator that yields chunks
|
||||
(Generator[List[V], None, None]): A generator that yields chunks
|
||||
of `sequence` of size `batch_size`, up to the length of
|
||||
the input `sequence`.
|
||||
|
||||
@@ -54,7 +54,7 @@ def fill(sequence: List[V], desired_size: int, content: V) -> List[V]:
|
||||
`sequence` as padding.
|
||||
|
||||
Returns:
|
||||
List[V]: A padded version of the input `sequence` (if needed).
|
||||
(List[V]): A padded version of the input `sequence` (if needed).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
|
||||
@@ -0,0 +1,141 @@
|
||||
from typing import Any, Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_keypoint_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n,m})"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
|
||||
if confidence is not None:
|
||||
is_valid = isinstance(confidence, np.ndarray) and confidence.shape == (n, m)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but "
|
||||
"got"
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_xy(xy: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n, m},)"
|
||||
actual_shape = str(getattr(xy, "shape", None))
|
||||
|
||||
is_valid = isinstance(xy, np.ndarray) and (
|
||||
xy.shape == (n, m, 2) or xy.shape == (n, m, 3)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def validate_keypoints_fields(
|
||||
xy: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
n = len(xy)
|
||||
m = len(xy[0]) if len(xy) > 0 else 0
|
||||
validate_xy(xy, n, m)
|
||||
validate_class_id(class_id, n)
|
||||
validate_keypoint_confidence(confidence, n, m)
|
||||
validate_data(data, n)
|
||||
@@ -3,6 +3,7 @@ from typing import Any, Dict, List, Optional
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
|
||||
|
||||
def mock_detections(
|
||||
@@ -30,5 +31,24 @@ def mock_detections(
|
||||
)
|
||||
|
||||
|
||||
def mock_keypoints(
|
||||
xy: List[List[float]],
|
||||
confidence: Optional[List[float]] = None,
|
||||
class_id: Optional[List[int]] = None,
|
||||
data: Optional[Dict[str, List[Any]]] = None,
|
||||
) -> KeyPoints:
|
||||
def convert_data(data: Dict[str, List[Any]]):
|
||||
return {k: np.array(v) for k, v in data.items()}
|
||||
|
||||
return KeyPoints(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=(
|
||||
confidence if confidence is None else np.array(confidence, dtype=np.float32)
|
||||
),
|
||||
class_id=(class_id if class_id is None else np.array(class_id, dtype=int)),
|
||||
data=convert_data(data) if data else {},
|
||||
)
|
||||
|
||||
|
||||
def assert_almost_equal(actual, expected, tolerance=1e-5):
|
||||
assert abs(actual - expected) < tolerance, f"Expected {expected}, but got {actual}."
|
||||
+11
-13
@@ -5,22 +5,19 @@ import pytest
|
||||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision import Color, Point
|
||||
from supervision.utils.image import (
|
||||
create_tiles,
|
||||
letterbox_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
)
|
||||
from supervision.utils.image import create_tiles, letterbox_image, resize_image
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
||||
def test_resize_image_for_opencv_image() -> None:
|
||||
# given
|
||||
image = np.zeros((480, 640, 3), dtype=np.uint8)
|
||||
expected_result = np.zeros((768, 1024, 3), dtype=np.uint8)
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -29,15 +26,16 @@ def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
||||
), "Expected output shape to be (w, h): (1024, 768)"
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_pillow_image() -> None:
|
||||
def test_resize_image_for_pillow_image() -> None:
|
||||
# given
|
||||
image = Image.new(mode="RGB", size=(640, 480), color=(0, 0, 0))
|
||||
expected_result = Image.new(mode="RGB", size=(1024, 768), color=(0, 0, 0))
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -62,7 +60,7 @@ def test_letterbox_image_for_opencv_image() -> None:
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
@@ -88,7 +86,7 @@ def test_letterbox_image_for_pillow_image() -> None:
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
|
||||
Reference in new issue
Block a user